Getting Started With Control Systems Technology
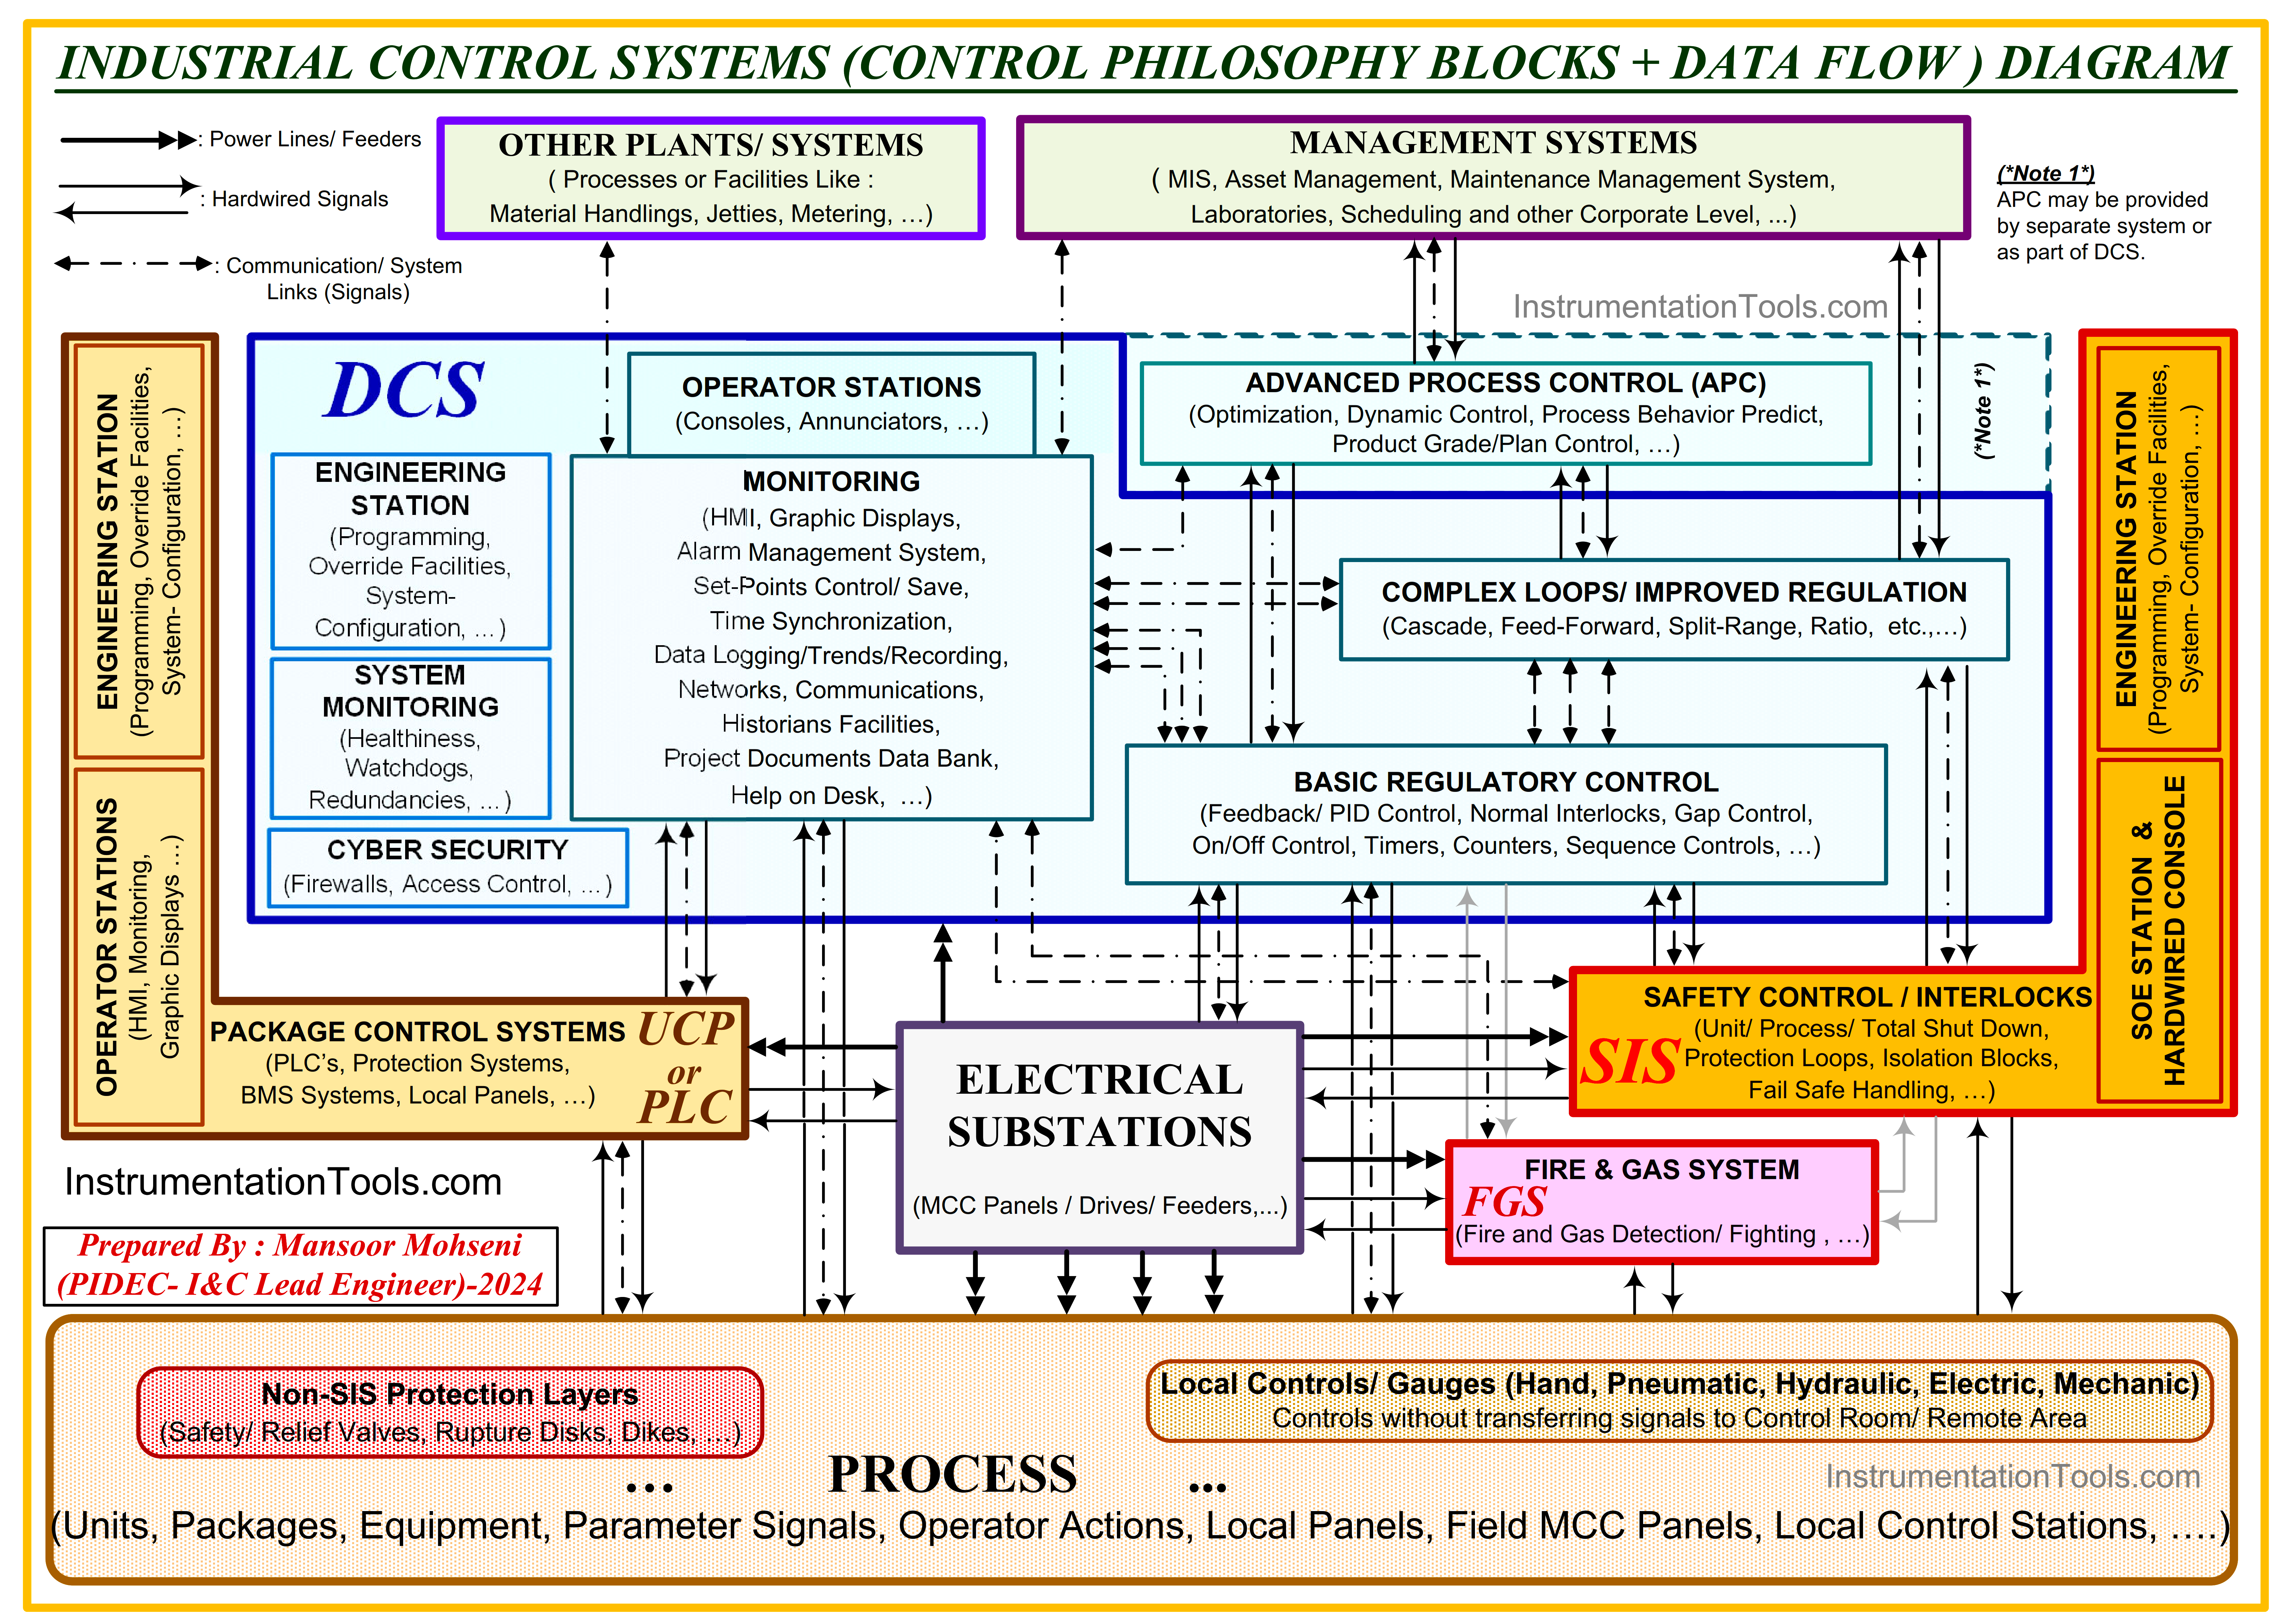
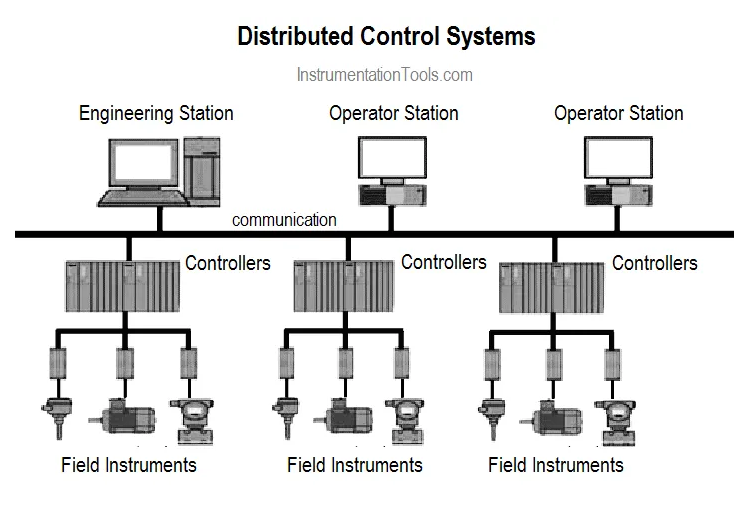
Control Systems Technology covers everything from basic PID loops to full PLC networks and distributed control architectures. It is not as clean on paper as it sounds in practice. Sensors drift, actuators stall, and every "well-tuned" controller falls apart when the environment changes by five percent. That is the reality you deal with when you are actually running these systems. At its core, it is the study and application of feedback mechanisms that keep physical processes where they need to be. Temperature, pressure, flow rate, position. You measure something, compare it to a setpoint, and adjust an output accordingly. The math behind this is well established and taught in every engineering curriculum. The hard part is getting it to work when the process variable is noisy, the plant is nonlinear, and your tuning gains are sitting at the edge of instability because the load profile changed overnight. I once spent three days chasing a hunting oscillation in a water level control loop. The system had a large dead tank with a slow-response valve. Every textbook said the integral time should be set to one-quarter of the dominant time constant. That did not work. The real problem was the pressure upstream of the valve fluctuating with other lines in the facility, which the controller could not see. I solved it by adding a feedforward term based on the upstream pressure measurement rather than trying to retune the feedback loop. Feedforward compensation for known disturbances is something most introductory courses gloss over, but in the field it makes the difference between a controller that tracks and one that simply chases.
The Practical Breakdown of Control Loops
Most industrial applications still rely on PID control. It is not because it is optimal. It is because it is robust, well-understood, and does not require a detailed process model to get usable results. The three terms are proportional, integral, and derivative action applied to the error signal. Proportional gain determines how aggressively the controller responds to the current error. Integral action eliminates steady-state offset by accumulating error over time. Derivative action anticipates future error based on the rate of change. Getting the balance right is the entire discipline of loop tuning. Here is a counter-intuitive point that beginners consistently miss: derivative action is often more useful for filtering noise than for improving response. A noisy sensor with high derivative gain will make your controller scream and waste actuator life. In practice, I almost always apply a low-pass filter to the derivative term and leave the proportional and integral terms doing the heavy lifting. The derivative term on its own without conditioning is more liability than asset in most real-world installations.
Another overlooked detail is anti-windup. When the actuator hits its physical limit, the integral term keeps accumulating error and the controller builds up a huge internal state. Once the error reverses, the actuator stays saturated for an unacceptably long time before the integral term unwinds. Most modern controllers have built-in anti-windup, but if you are working with legacy equipment or writing your own implementation, you need to handle this explicitly. Clamping, back-calculation, or conditional integration are the standard approaches. Pick one and implement it correctly, or your startup transients will be unpleasant.
Get the Full Details

Working With Programmable Logic Controllers
PLCs are the workhorse of industrial control. They execute logic-based and sequential control programs in real time. Ladder logic remains the dominant programming language in many facilities, though structured text and function block diagrams are gaining ground, especially in new designs. The practical challenge with PLCs is not the programming itself. It is the integration. Every sensor, every actuator, every safety interlock needs to be wired, addressed, and validated. I have seen projects where the control logic was fine but the input filtering was wrong, causing random faults from dirty power lines and induction from nearby VFDs. Proper grounding, shielded cabling, and isolating analog inputs with signal conditioners are the kinds of details that separate a stable system from one that randomly fails at 2 AM on a Saturday. Scan time is another practical concern. Simple logic-based programs scan in milliseconds. But when you mix ladder logic with continuous PID loops, motion control blocks, and communication overhead, scan times can stretch and introduce timing uncertainty. For most applications this is acceptable, but if you are running high-speed packaging lines or synchronized motion systems, scan time variation becomes a real constraint and you may need to dedicate separate processors or use a real-time operating system approach.
Tuning Methods That Actually Work
There are plenty of tuning methods in the literature. Ziegler-Nichols is the most famous and the least reliable for anything beyond simple first-order processes. Open-loop step response methods like Cohen-Coon have better theoretical grounding but assume you can safely perturb the process. Closed-loop methods like relay feedback are faster and safer but still require the process to behave reasonably during the test. In practice, I start with a rough model of the process. A first-order plus dead time approximation is sufficient for most initial tuning. I determine the process gain, time constant, and dead time from historical data or a controlled step test, then use that model to calculate initial PID parameters. From there I refine by trial, observing closed-loop response to setpoint changes and load disturbances. The whole process for a typical temperature or flow loop takes maybe 30 to 45 minutes if the hardware is already commissioned. A poorly instrumented loop on an old process can take a full day or more. Model predictive control is superior when you have multivariable interactions, significant constraints, or processes with long dead times. But it requires a good process model and more development time. If your process is a single loop with modest dynamics, a properly tuned PID will outperform a poorly implemented MPC every time. The maturity of PID tuning techniques and the availability of auto-tuning features in modern controllers make them the default choice for roughly 80 percent of industrial applications.
When Control Systems Technology Fails Completely
It does fail. Here are the scenarios where your best controller design cannot save you: Non-minimum phase systems. If your process has a right-half-plane zero, increasing gain to improve response will always worsen stability. The inverse response behavior means the process initially moves in the wrong direction before correcting. No amount of PID tuning fixes this. You need to account for the RHP zero in your controller design or accept that performance will be fundamentally limited. Extreme time delays. When dead time exceeds roughly 20 to 30 percent of the dominant time constant, PID control degrades rapidly. Smith predictors and MPC can help, but they are sensitive to model mismatch. If your delay varies with operating conditions, which is common in chemical processes, even those methods struggle.
Actuator saturation and stiction. A controller can be perfectly tuned on paper and still perform poorly because the final control element is worn, sticky, or undersized. I replaced a control valve that was causing persistent oscillation and found the actuator had lost 40 percent of its force due to packing friction. The valve positioner was compensating within its range but the underlying actuator was marginal. Recalculating gains would have been a waste of time. The fix was mechanical, not computational. Sensor failure or severe noise. A bad temperature transmitter reading will cause your controller to drive the process into dangerous territory with no warning unless you have fault detection and fail-safe logic. Simple sanity checks like rate-of-change limits, sensor cross-validation, and outlier filtering can catch most common failures. More sophisticated approaches use residual-based fault detection, but those require accurate models and are not worth the effort for simple loops.
Implementation Checklist for New Projects
Before you write any control logic, verify these fundamentals: Instrumentation is calibrated and specified correctly for the application. A flow transmitter with the wrong range or a pressure sensor that cannot handle the media will undermine any controller you design. Match the instrument to the process conditions, not the other way around. Power and signal integrity are addressed. Ground loops, EMI from variable frequency drives, and poor cable routing are sources of intermittent faults that consume more engineering time than any control design task.
Fail-safe states are defined and implemented. What happens to the process if the controller loses power, if communication fails, or if a sensor disconnects? The default behavior should be safe, not maximal output. I have seen systems where a failed sensor caused the controller to drive a valve fully open because the fail-degraded mode was incorrectly configured. Documentation is kept current. Control system documentation degrades faster than anything else on a project. As logic is modified and instruments are replaced, the drawings and descriptions become inaccurate. A version-controlled library of control narratives, P&IDs with instrument tags, and tuning reports pays for itself the next time someone needs to troubleshoot or modify the system. The gap between textbook control theory and field-deployed systems is wide and filled with practical details that are not covered in any course. Understanding the theory is necessary but not sufficient. The systems that perform reliably are the ones where someone thought through the sensor selection, the actuator capabilities, the failure modes, and the maintenance accessibility before writing a single line of control code.