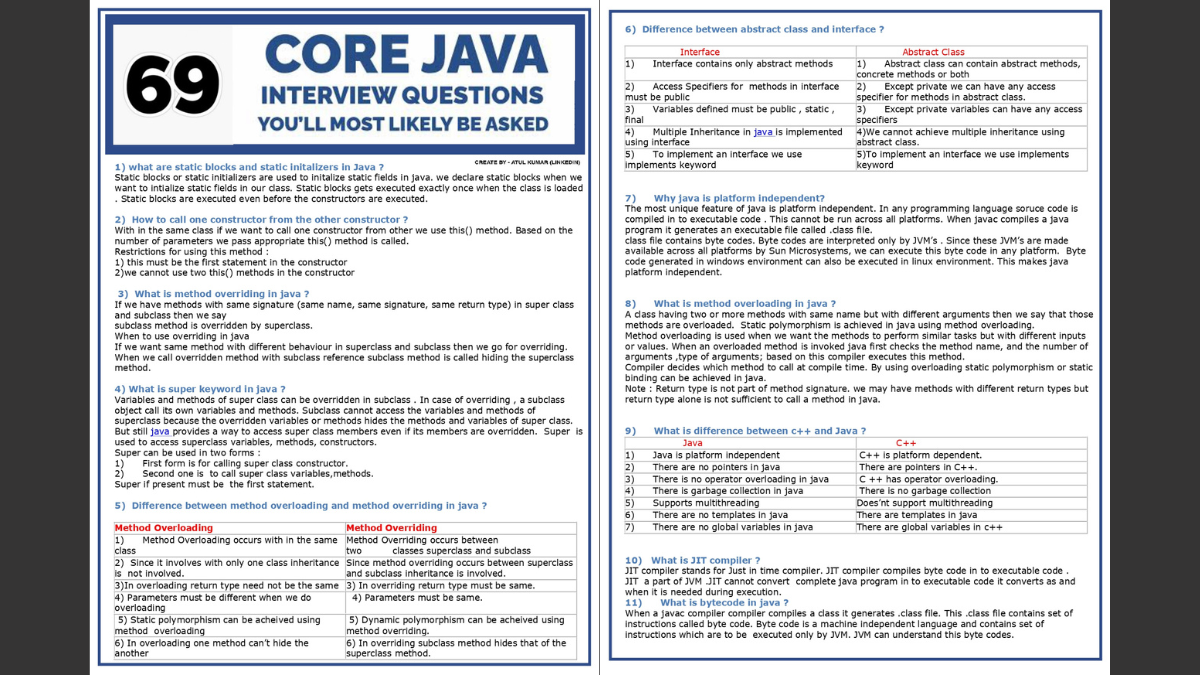
What Actually Comes Up When They Test Your Java Knowledge
Most senior Java roles don't care that you can explain the four pillars of OOP. They need to know whether you understand what happens when two threads touch the same data structure, why your garbage collector started STW every 30 seconds, or whether that HashMap you built will actually survive a serialization round-trip across classloaders. I've sat on both sides of these interviews for years. Here is what separates people who write Java from people who write correct Java. Start with memory model and concurrency. A lot of candidates can quote the happens-before relationship rules but freeze when you ask them why volatile doesn't make a long calculation atomic. I once interviewed someone who spent ten minutes trying to defend synchronized on a method that was already inside a block locked on the same monitor. The answer was simple: reentrant lock acquisition, not deadlock. But the real test comes when you push into double-checked locking. People know the pattern. Fewer people remember why it fails before Java 5 without a volatile on the reference field. I had a production bug once where a singleton factory appeared to work because HotSpot happened to serialize the writes in order on that particular CPU. It broke on ARM. That is the kind of thing I want to hear about when I ask you to implement DCL. Volatile, synchronization, and the java.util.concurrent package belong in one conversation. Understand the difference between a volatile read and a lock acquire. A volatile gives you visibility and ordering. It does not give you atomicity for compound operations. I have seen teams put AtomicInteger everywhere and then wonder why their counters were off by one during rollback. The fix was not more atomics. It was putting the increment inside the same transaction boundary as the state change. Locks are not the enemy. Blindly adding fine-grained locking without thinking about contention is.
Garbage collection gets asked a lot at the senior level. Not because they expect you to tune CMS flags by hand, but because they want to see whether you understand why your young generation is filling up faster than expected. I remember a service where we got full GCs every few minutes under light load. Turns out we were creating thousands of short-lived objects inside a loop that processed incoming messages. The objects themselves were small. The problem was that the allocation rate exceeded the young gen size. Moving the loop body to reuse a single buffer cut the GC pause time from 200 milliseconds to under 10. That is not a G1 trick. That is basic allocation-awareness.
Streams, Lambdas, and the Things You Should Avoid
Java 8 streams changed how we write code. They did not fix bad algorithmic thinking. A lot of people write streams that are slower than an equivalent loop because they create intermediate objects on every map or filter operation. I reviewed code once where a stream pipeline building a lookup table was doing a sorted call for no reason. The sort created a temporary array. The whole thing took 300 milliseconds instead of 15. Changing to a plain HashMap builder got it back to acceptable numbers without losing readability. Method references versus lambda expressions is another common question. People pick lambdas because they feel more explicit. Method references are usually cleaner and slightly faster because the compiler generates a synthetic handle rather than creating an anonymous class. I do not recommend switching for performance. I recommend switching because the code is easier to read when someone else maintains it. Default methods on interfaces are fine. Static interface methods are also fine. What causes problems is when people create deep hierarchies of interfaces with default methods that call each other. You lose the ability to predict which implementation runs. I have seen three levels of interface inheritance where a default method in the base interface called a default in the middle layer, which relied on a concrete implementation of a leaf interface. Changing the leaf implementation broke behavior in the base. Keep interface hierarchies flat. Use composition instead of deep default method chains.
Get the Full Details
Serialization, Reflection, and Edge Cases That Trip People Up
Serialization is rarely the right answer anymore. Still, you need to understand why serialVersionUID matters and what happens when you remove a field. I had a system where we serialized session objects and upgraded the class by adding a new field without changing the serialVersionUID. Deserialization on the older JVM succeeded because Java uses default values for missing fields. But the reverse failed. Reading an older serialized form on a newer class version worked. Writing a newer form and reading it on an older JVM threw InvalidClassException. The fix was adding a writeReplace method to control what actually gets serialized instead of relying on the automatic field mapping. Reflection gives you access to private fields and methods. It also bypasses encapsulation in ways that make debugging nearly impossible. I used reflection once to patch a third-party library where a private field was not exposed through any setter. The patch worked in testing. It broke in production when the library vendor updated the internal field name. Using a supported API or a fork is always better. If you must use reflection, at least wrap it in a utility method that throws a clear exception when the expected field is missing. Generics and type erasure cause confusion because the runtime does not know the actual type parameter. You cannot create an array of a generic type. You cannot check an instanceof against a parameterized type. People try to work around this with Class literals and reflection. The cleaner approach is to pass the Class object as a parameter and use it for all runtime type operations. I prefer this because it makes the type information explicit rather than hiding it behind unchecked casts.
Concurrency Patterns and Where They Fail
ThreadLocal is useful for storing request-scoped data without passing it through every method call. It is also a source of memory leaks if you do not clean it up. I once had a pool of worker threads where ThreadLocal variables accumulated across requests because a finally block was missing the remove call. The heap grew until we hit OOM. Adding the remove in a finally block fixed it. Always pair ThreadLocal set with a guaranteed remove. CompletableFuture is powerful but easy to misuse. Chaining ten async operations in sequence looks parallel but executes serially. People write pipelines like this assuming they gain concurrency. The fix is using supplyAsync or runAsync with an explicit executor for each independent step, then combining the results with allOf or thenCombine. I prefer allOf when I need to wait for everything. I prefer thenCombine when I need to process pairs of results. Virtual threads are available since Java 21. They reduce the overhead of thread creation and context switching. They do not eliminate the need for proper synchronization. Sharing mutable state between virtual threads still requires locks or immutable data structures. I tested a service migrating from platform threads to virtual threads. The throughput improved by roughly three times for I/O-bound work. CPU-bound work saw no improvement. The code changes were minimal. The lesson is that virtual threads solve one class of problem. They do not replace careful design.
What I Actually Listen For During the Interview
I do not care that you memorized the equals contract. I care that you understand why two objects that compare equal must have the same hash code, and what happens when they do not. I do not care that you can implement a binary search. I care that you explain why Integer.parseInt throws NumberFormatException for null instead of returning a special value. I care that you talk about edge cases without being prompted. The best candidates admit what they do not know. They say they would check the JavaDoc or read the source. They have opinions but they are willing to revise them when presented with evidence. I respect that more than someone who recites answers from a blog post without understanding the underlying mechanics. Practical experience beats textbook knowledge every time. If you have dealt with production memory leaks, concurrent modification exceptions, or classloader issues, bring those stories up. They show you have actually maintained Java systems beyond a tutorial project. The theoretical questions are there to verify your foundation. The discussion is where you demonstrate you can apply it.

A Few Specific Scenarios I Have Seen
One candidate implemented a cache using a HashMap and never considered what happens when the cache grows without bound. I asked about eviction. They said they would add a maximum size check. That is not enough. Without an eviction policy, the cache either grows until it causes GC pressure or it silently drops entries without warning. The fix is using a bounded structure like Caffeine or implementing a simple LRU with a LinkedHashMap. I accepted the Caffeine answer immediately because it shows familiarity with production-grade tooling rather than reinventing a broken wheel. Another candidate struggled with the difference between fail-fast and fail-safe iterators. They knew ConcurrentHashMap was safe for concurrent modification. They did not know why. The answer is that it uses per-segment locking rather than a single lock over the entire table. Iterators on ConcurrentHashMap do not throw ConcurrentModificationException because they capture a snapshot of the iterator state rather than relying on a modification count. This is a detail that matters when you choose an implementation for a high-throughput scenario. Finally, people often ask about the performance of ArrayList versus LinkedList. The answer depends on access pattern. Random access favors ArrayList because LinkedList requires traversal. Sequential access can favor LinkedList in theory, but in practice the cache misses and node allocation overhead usually make ArrayList faster. I have seen people switch to LinkedList to optimize remove operations in the middle of a list, only to discover that the overall throughput dropped because the random access pattern dominated the workload. Profile before you optimize. A benchmark running for a few minutes will tell you more than a theoretical analysis.
These are the kinds of conversations that matter in a senior interview. Not because they prove you can pass a multiple choice test, but because they reveal whether you have actually built and maintained systems at scale. The questions are a means to that end. How you answer them is what counts.