What These Assessments Actually Look Like in Practice
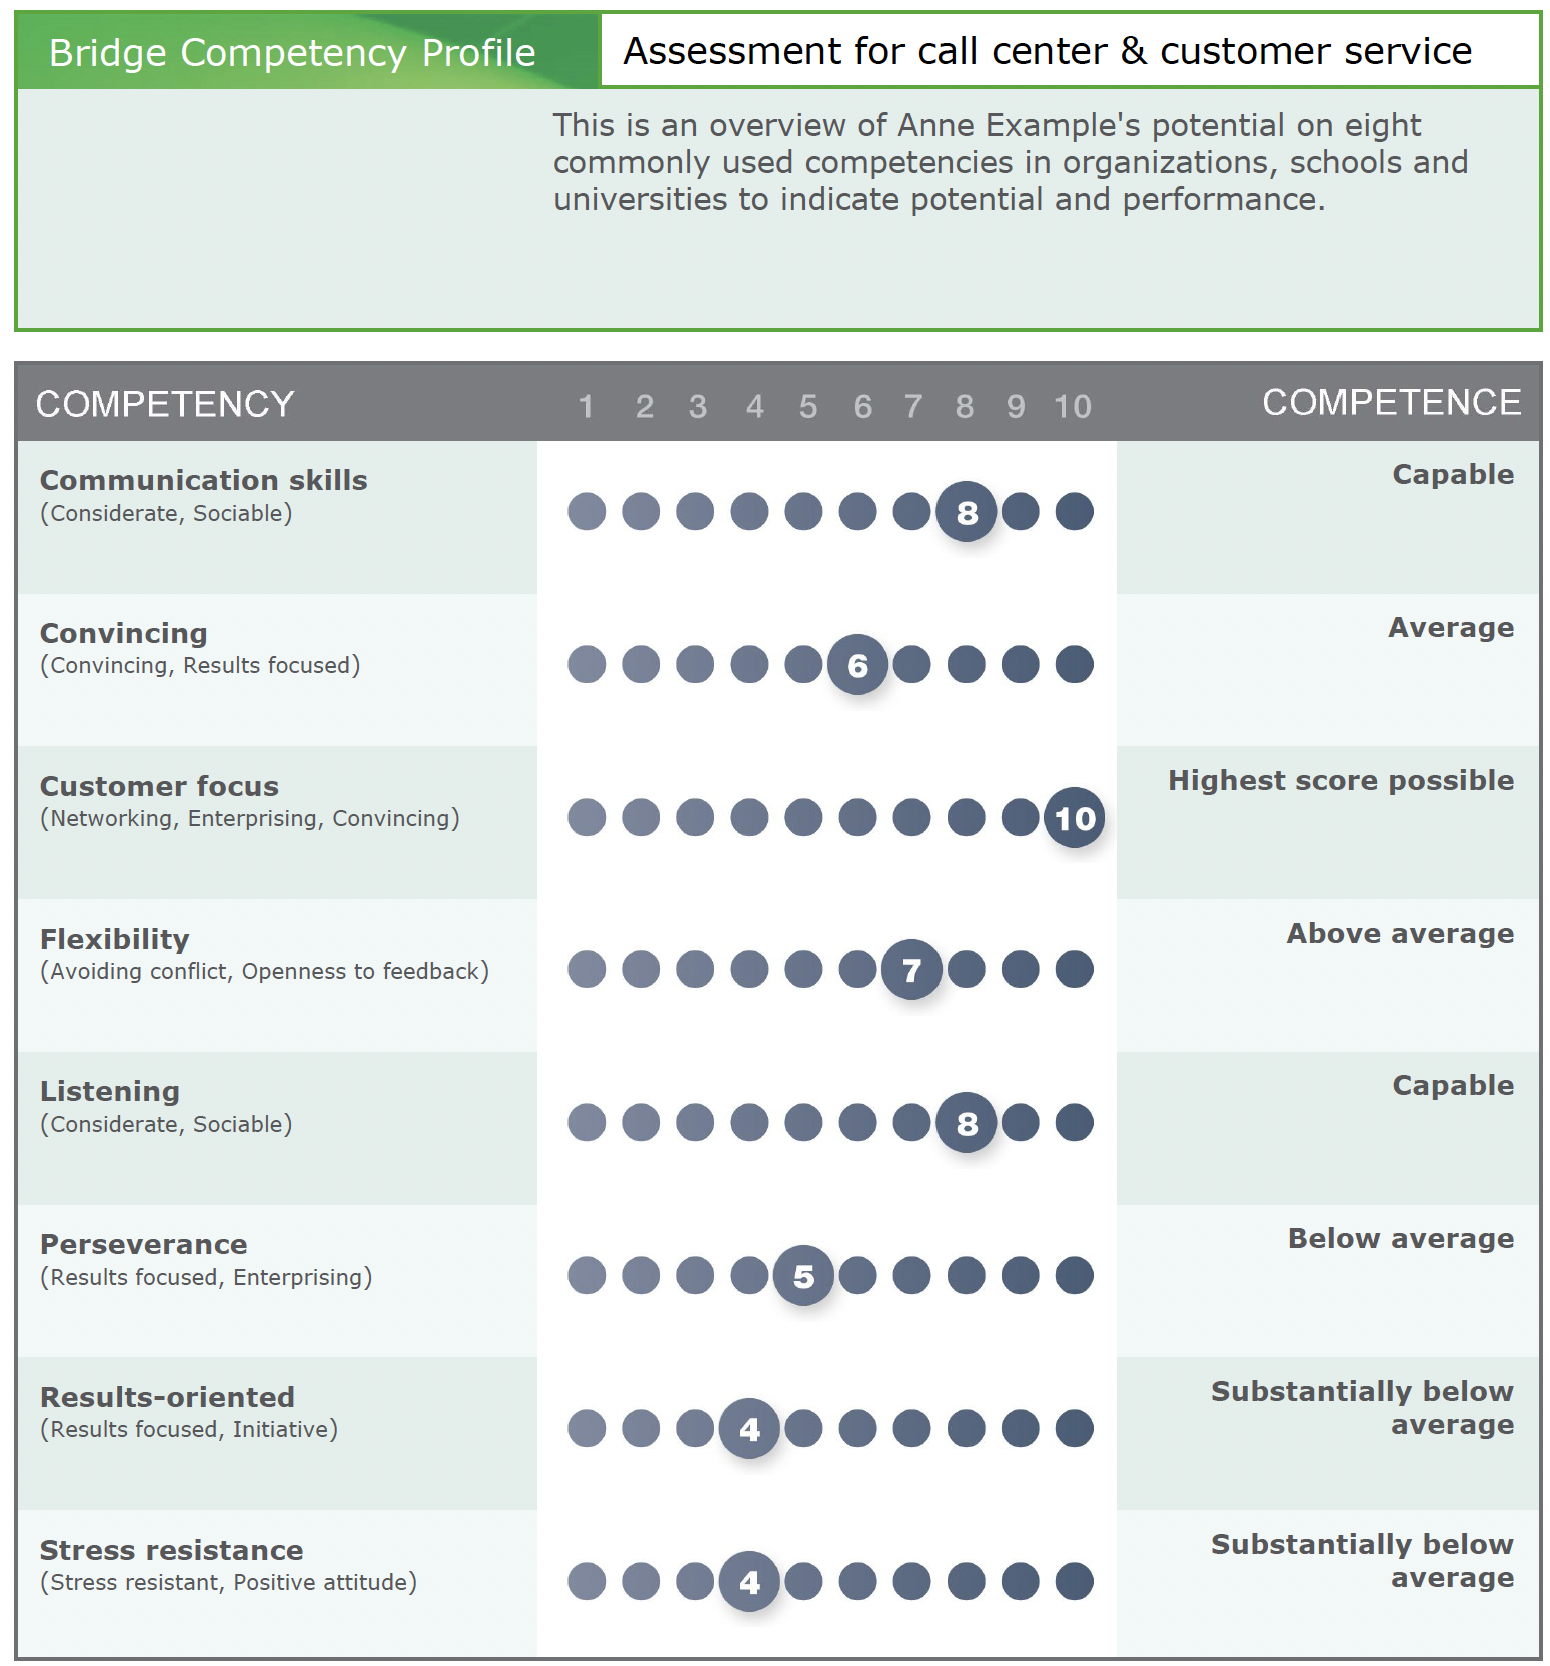
A customer service assessment is just a structured evaluation of how well your agents handle real interactions. The assessment part is where people mess up because they treat it like a compliance checklist instead of a diagnostic tool. I spent years watching companies run these assessments and then do absolutely nothing with the data. That's the real problem. Most organizations collect scores and file them away. That's not an assessment program. That's paperwork. The core idea is straightforward. You take recorded calls, chats, or tickets and score them against a rubric. The rubric should cover things like resolution time, tone, accuracy of information, and whether the agent followed your process. Some teams also factor in customer satisfaction scores from post-interaction surveys. The combination of objective metrics and subjective quality scoring tends to give you the clearest picture.
Customer Service Assessment Examples
Here are the types you'll actually see in the wild. First, there's the call-based quality audit where an evaluator listens to a full interaction and rates it on criteria like greeting, active listening, problem resolution, and closing. Then there's the chat transcript review, which is different because chat moves faster and you need to judge responsiveness and conciseness rather than conversational flow. Ticket-based assessments look at written support cases and evaluate clarity, completeness, and follow-up accuracy. I also ran live ride-along evaluations where an observer sat with an agent during actual calls and marked down real-time behaviors. This method catches things recordings miss. Agents perform differently when they know they're being watched, which is a flaw, but it also reveals how they handle pressure. You just have to account for that distortion when you're interpreting the results. The most useful examples aren't the generic ones you find on a templates site. They're the ones tied to your actual business metrics. If your average handle time is too high, your assessment criteria should weight efficiency more heavily. If your first contact resolution rate is trash, the rubric needs to reward agents who solve problems without transfers. Match the scoring to what's actually broken.
I ran into a specific edge case that taught me this the hard way. We were assessing a team that handled enterprise technical escalations. Standard quality scores looked great. These agents were polite, thorough, and followed every step. But our mean time to resolution was 72 hours because they were escalating everything to Tier 2 instead of working through the decision tree. No amount of tone scoring caught that. I reworked the assessment to include a weighted escalation audit. Agents lost points for unnecessary escalations and gained points when they resolved issues within their lane. That single change dropped our escalation rate by 40 percent in three months. The original rubric was measuring the wrong thing.
Get the Full Details
How to Build an Assessment That Doesn't Suck
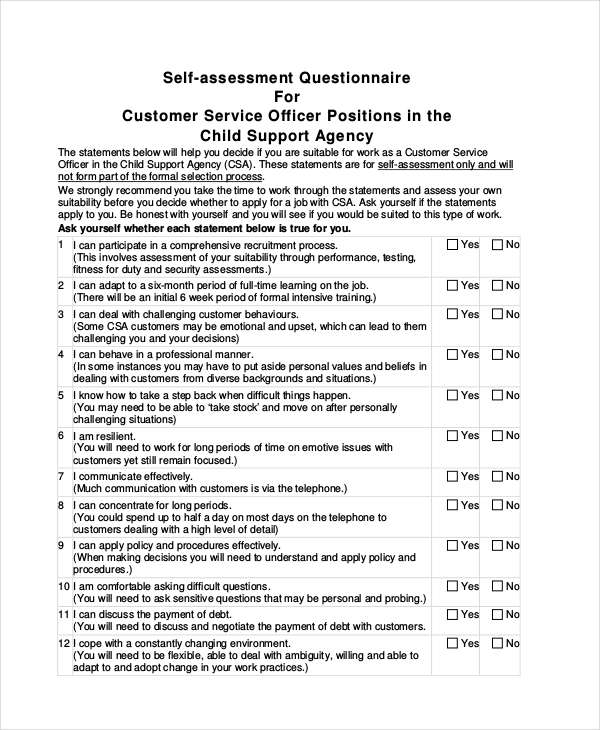
Start by defining what good looks like for your specific operation. Write down the behaviors and outcomes you actually want. Then turn those into a scoring grid. A 1 to 5 scale works fine. One means the agent completely failed that criterion. Five means they exceeded expectations. Keep it simple. Overcomplicating the scale just makes calibration harder without adding useful detail. Calibration is where most programs fall apart. Two evaluators looking at the same interaction should arrive at the same score within a point or two. If they don't, your criteria are too vague or your evaluators haven't been aligned. I've seen teams spend weeks on calibration sessions just to get inter-rater reliability into an acceptable range. Don't skip this step. Bad calibration turns your assessment into a popularity contest where scores reflect the evaluator's mood instead of the agent's performance. Sampling matters too. You can't evaluate every interaction. Pick a statistically meaningful sample based on volume. For high-volume teams handling thousands of tickets a month, assessing five to ten percent of interactions per agent per month gives you enough data to spot patterns without burning through evaluator capacity. For smaller teams, even three interactions per month is useful if you're looking at the right ones. Random sampling works for detecting overall trends. Targeted sampling catches specific issues. Use both.
The feedback loop is the part people ignore. An assessment without feedback is just surveillance. Agents need to see their scores, understand why they got them, and know what to improve. Schedule quarterly review conversations at minimum. Biweekly is better if you have the bandwidth. The review should reference specific moments from the recorded interactions, not general comments like "work on your tone." Pinpoint the exact call, the exact moment, and the exact alternative approach.
Common Pitfalls That Wreck Your Data
First, don't let managers score their own direct reports. It creates a conflict of interest that skews results toward leniency. Independent evaluators or a rotation system where evaluators swap teams periodically keeps the scores honest. I once worked with a company where team leads scored their own people and the quality scores were uniformly in the high nineties. Meanwhile, customer satisfaction was tanking. The disconnect was immediately obvious once an external team came in and started auditing. Second, stop using assessment scores as the sole basis for performance reviews and compensation decisions. When money is on the line, evaluators become afraid to give low scores and agents become paranoid about being audited. The data degrades. Use assessments for development purposes and layer in other performance indicators for evaluation decisions. Third, be aware that your assessment criteria will drift over time. What mattered in 2019 doesn't necessarily matter now. Customer expectations shift. Products change. Your process gets updated. Review and revise your rubric at least twice a year. I've seen companies run the same assessment framework for four years straight while their product lineup doubled and their support channels expanded from phone to chat to social media to video. The old rubric was evaluating behaviors that no longer existed.

Where This Approach Falls Short
Assessments measure what happened after the fact. They don't predict future performance. An agent can have a strong quarter on paper and still burn out or leave. They also struggle to capture context. A difficult customer, a broken tool, or a missing piece of information can make even a skilled agent look bad on an evaluation. No scoring rubric fully accounts for situational variables. If you're dealing with very small teams under twenty agents, formal assessments might be overkill. Direct observation and regular one-on-ones often produce better results with less overhead. For large contact centers with complex operations, you'll likely need dedicated QA staff and a scoring platform to keep things manageable. Spreadsheets break down somewhere around fifty evaluators trying to track thousands of interactions per month. The alternative to a full assessment program is a lightweight feedback model based on customer-driven signals. Pull CSAT scores, Net Promoter Score data, and complaint frequency, then use those as proxies for service quality. It's faster and cheaper but less granular. You won't know why an agent is struggling, only that they are. Combine both approaches if you can. Let the assessments explain the patterns the metrics reveal.