Why your ML project never ships
Most people learning machine learning quit because they spend three weeks watching Andrew Ng lectures and still can't load a CSV without it exploding. I watched a friend do exactly this last winter. He knew gradient descent by heart but treated a pandas merge like it was black magic. The gap between understanding a concept and actually running code is where people get stuck, and it's not something any tutorial explains properly. The fix isn't more content. It's a structured daily habit that forces you to write code every single session, no matter how small. This is what I call Daily Machine Learning For Beginners, and it's the only reason I've actually shipped projects instead of collecting bookmarked courses.
How Daily Machine Learning For Beginners actually works
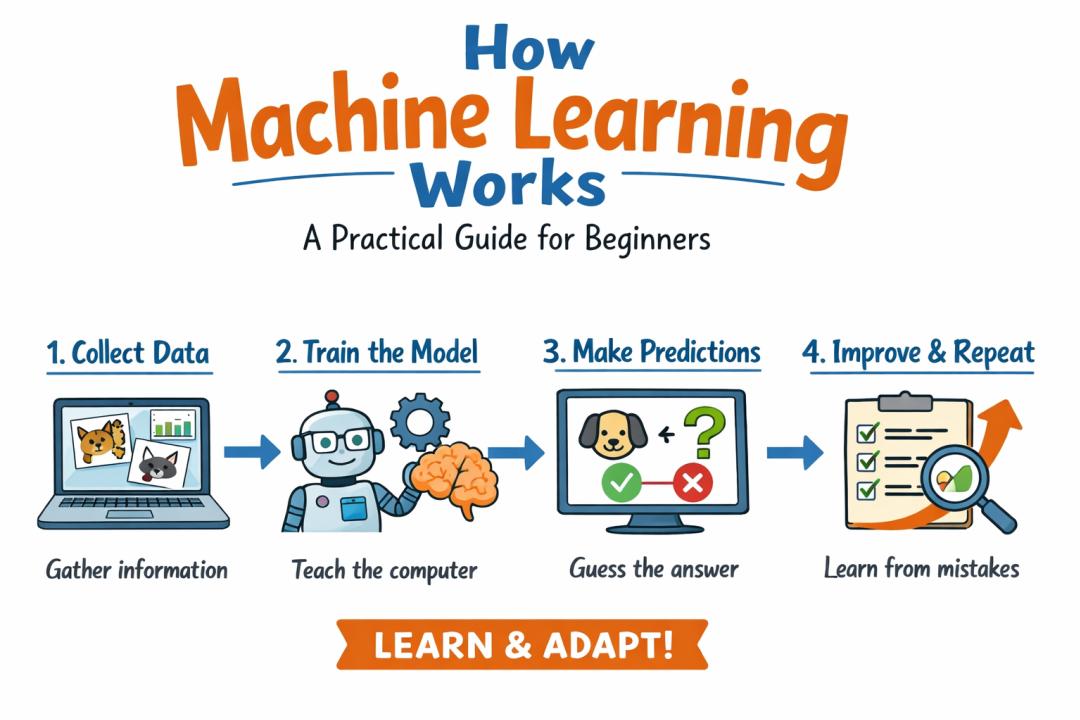
The method is brutally simple. Each day you pick one concrete task and finish it. Not study. Finish. It could be loading a dataset and printing the first five rows with their datatypes. It could be training a logistic regression on the breast cancer dataset and saving the accuracy to a text file. That's it. The constraint is the point. You're not trying to build a production model; you're training yourself to move from zero to done in under forty-five minutes. I keep a notebook on my desk with a checklist of tasks. Most days I complete two or three items in about thirty minutes. The days I don't finish anything are rare, and when they happen, I notice my confidence drops by evening. There's a psychological feedback loop here that most guides ignore entirely.
The task list most beginners miss
Here's the actual sequence I go through with new people. It took me about two years to figure out the right order, and I've seen people waste six months going backwards. Week one is entirely data handling. Load CSVs with different delimiters. Handle missing values using forward fill versus mean imputation and observe how the model output changes. Encode a single categorical variable with one-hot and another with label encoding. This seems boring but it's where 80% of beginners drown. I once had someone try to train a random forest on a dataset with 40,000 unique city names and no encoding at all. The model threw a memory error and he blamed scikit-learn. It wasn't the model's fault. Week two introduces modeling, but only the simplest ones. Linear regression, logistic regression, a single decision tree. You train them, you evaluate them, you save the results. Do not jump to XGBoost yet. Do not touch neural networks. The reason is that you need to understand what a baseline looks like before you can tell when a complex model is actually helping. I learned this the hard way when I deployed an LSTM on a tabular dataset and got worse accuracy than a logistic regression. The LSTM was overfitting badly and I had no way to notice because I never established the baseline first.
Get the Full Details
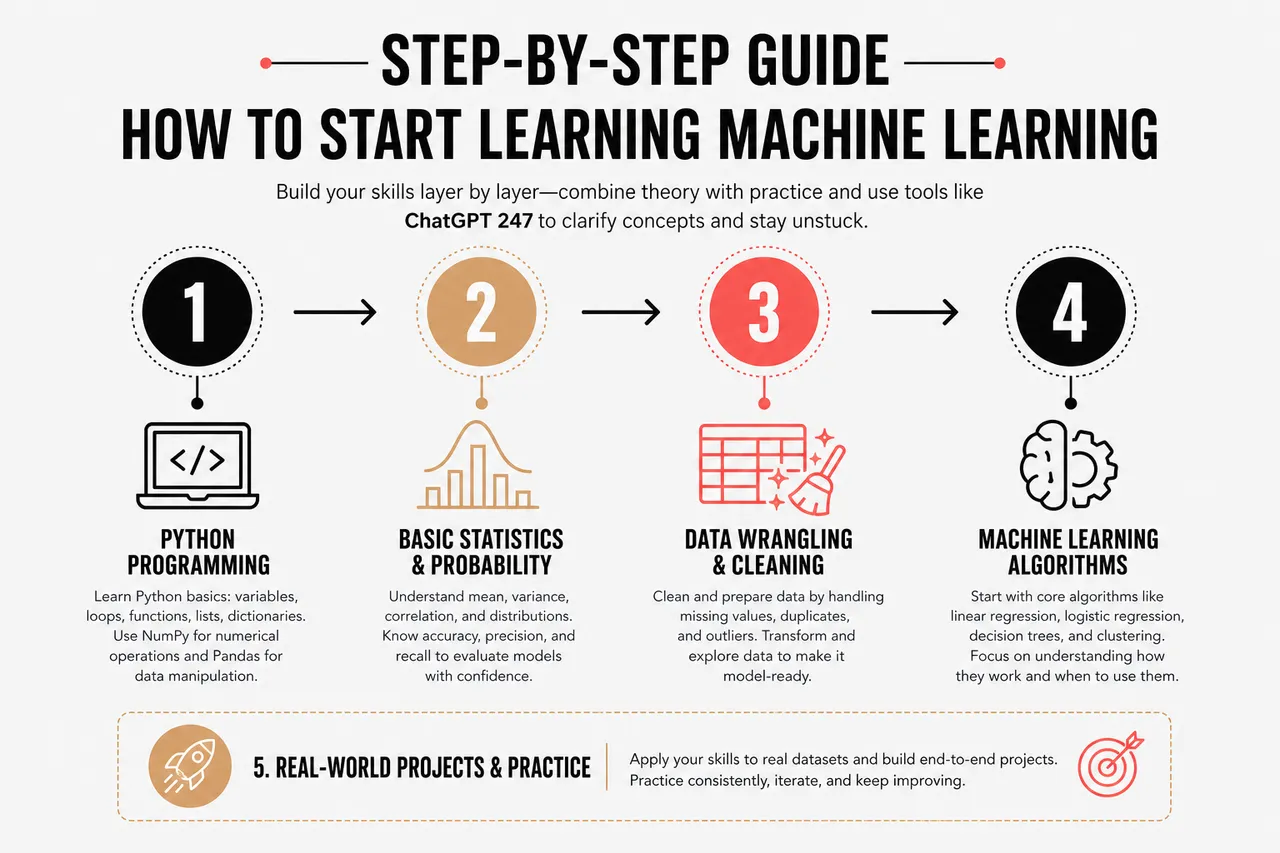
Week three is evaluation and validation. Train-test split with stratification. Cross-validation with five folds. Understanding why accuracy lies to you on imbalanced datasets. I built a fraud detection model once where the accuracy was 99.3 percent and the recall was 4.1 percent. Nine out of ten frauds went undetected and nobody noticed because everyone was looking at accuracy. This is the single most important lesson in this entire guide and almost nobody teaches it early enough. Week four combines everything. Take a real dataset from Kaggle, clean it, encode it, train a baseline, add one feature engineering step, retrain, compare. The dataset doesn't need to be interesting. It just needs to be real. I use the California Housing dataset for this because it has missing values, mixed scales, and a continuous target that teaches you about regression metrics without overwhelming you.
Daily Machine Learning For Beginners gets real results when you stick to the sequence
The reason this approach works is that it matches how skill actually accumulates. You're not consuming information passively. You're performing tasks that compound. Day one's skill doesn't vanish by day two. It builds on top of it. After thirty days of this pattern, most beginners can load a dataset, preprocess it, train a model, and interpret the results without googling every single step. That's a real baseline competence that most advanced courses assume you already have. What I don't include on purpose is hyperparameter tuning in the first month. Grid search is useful later, but it's a distraction now. You'll waste three hours on a random forest's max_depth while the actual problem is that your target variable has a leak from the training set into the features. I've seen this happen dozens of times. Data leakage is the silent killer of beginner projects, and it doesn't show up in any accuracy metric until you deploy and the model performs identically to a random guess on new data. There's also a limit to what this method can do. If you're trying to learn deep reinforcement learning or large language model fine-tuning, a daily forty-five-minute habit won't bridge the mathematical gap. You still need linear algebra, probability, and calculus at that level. Daily Machine Learning For Beginners is designed for the applied practitioner who wants to build useful models on tabular and text classification data, not for someone preparing for a research career. Be honest about which category you're in.
The other limitation is motivation decay around day twenty-two. This is not theoretical. I track my own streaks and the average drop happens between three weeks and a month in. The solution I use is switching the dataset every Tuesday, even if it's the same type of problem. A new dataset resets the novelty and makes the repetition feel less stale. It's a small hack but it keeps people going past the point where most quit. Some people ask whether they should use Python or R for this. I use Python exclusively because the ecosystem is larger and the documentation is easier to search when you're stuck at 11pm. R is fine if you already know it, but switching languages mid-habit introduces unnecessary friction. Pick one and commit for at least sixty days.
The checklist I actually use
Here's the running list. Each item is designed to take between fifteen and forty minutes. If you can't finish it in an hour, you're overcomplicating it. Day 1-3: Install Python, pandas, numpy, scikit-learn, and matplotlib. Load three different CSV files. Print their shapes and dtypes. Save the output to a log file. This sounds trivial and it is. Getting comfortable with the toolchain removes the biggest barrier in the first week. Day 4-6: Handle missing values on a single dataset using three methods: drop rows, fill with mean, fill with median. Compare the resulting column statistics. Observe how each choice shifts the distribution.
Day 7-9: Encode one categorical feature with sklearn's LabelEncoder. Encode another with OneHotEncoder. Fit only on the training split, not the full dataset. This second point is non-negotiable and most beginners get it wrong on their first try. If you fit the encoder on all data, you're leaking information from the test set into your preprocessing pipeline. Day 10-12: Train a logistic regression on a binary classification dataset. Print the classification report, not just accuracy. Look at precision, recall, and F1. The discrepancy between accuracy and recall on imbalanced data is the insight you're looking for here. Day 13-15: Build a decision tree classifier with max_depth set to 3. Plot it using graphviz or sklearn's plot_tree. Read the splits and explain each one in plain language. If you can't explain a split, you don't understand the model.
Day 16-18: Implement a k-fold cross-validation loop from scratch using numpy before using sklearn's cross_val_score. This exercise takes longer but it forces you to understand what cross-validation actually does under the hood. I've had people use cross_val_score for months and still not understand why the fold sizes matter when the dataset is imbalanced. Day 19-21: Train a random forest. Compare its accuracy to the logistic regression baseline. Note whether it actually improves or just memorizes the training data. Check for overfitting by comparing train score to test score. Day 22-24: Engineer one new feature from existing columns. For a housing dataset, create a room-per-person ratio from total rooms and population. Retrain the model. Measure the change in R-squared or accuracy.
Day 25-27: Write a simple prediction pipeline function that takes raw input and returns a prediction. Input goes in as a dictionary, the function handles missing values, encoding, and scaling, and outputs a class label. This is the closest thing to production code a beginner can write, and it changes how you think about models. Day 28: Review everything you've built. Pick the worst-performing model from the month and identify why. Was it data quality? Leakage? A bad baseline? Write down one sentence explaining the problem and one sentence explaining the fix. This reflection step is where the habit becomes a real skill. The whole sequence is forty-five minutes a day. Some days take longer. That's acceptable. Missing a day is acceptable too, but missing two days in a row tends to break the streak for most people. I don't judge the inconsistency. It's just data.
If you want to go further after this foundation, the next natural step is learning scikit-learn's Pipeline object properly, then moving into feature selection with mutual information or recursive feature elimination. Don't rush there. The value of Daily Machine Learning For Beginners is in the repetition, not the speed. Forty-five focused minutes a day will outperform a six-hour weekend tutorial every single time, and I've watched enough people try the weekend approach to know that for certain.