Getting Started Without Wasting Three Weeks
I have watched people burn months trying to learn data analysis through expensive bootcamps and sprawling online courses that assume you already know what you are doing. The reality is that data analysis at its core is a small set of repeatable skills, and most beginners trip over the same things within the first month. You do not need a statistics degree. You need to understand how to get data into a tool, clean it without accidentally deleting half your rows, run basic aggregations, and then figure out why your visualization looks wrong. This guide cuts through the noise and gives you the path that actually works, the kind of path I would have appreciated when I was starting out and still had the energy to research things properly. The phrase itself usually points to one of two things. Most people mean the actual book published by Wiley, which has gone through multiple editions and covers everything from spreadsheet basics to introductory Python pandas workflows. Some people mean the broader category of beginner-friendly tutorials and resources that exist in abundance online. Neither is inherently bad. The book by Wiley is decent as a reference text if you want something structured, but it will not make you competent by itself. Reading about groupby operations in pandas is not the same as breaking a dataset and fixing it at 11pm on a Tuesday. Here is how this actually works in practice. Pick one tool and commit to it for at least six weeks before jumping to another one. The biggest mistake I see is people learning Excel pivots for two weeks, then watching a YouTube tutorial on Tableau, then switching to Python because someone on Reddit said R is better for stats. You end up with surface-level familiarity in three tools and no real ability to solve a problem in any of them. If you are working with financial data, spreadsheets are fine for small datasets. If you are handling anything above roughly fifty thousand rows, you will hit performance walls and need to move to pandas or a database. I learned this the hard way when a client sent me a forty-two thousand row invoice dataset in Excel format. I tried building pivot tables and conditional formatting, and Excel started freezing after twenty minutes. Moving that same dataset into pandas and running the aggregations took about four seconds.
What You Actually Need to Know First
Data analysis is not about memorizing functions. It is about understanding data structure. Before you open any software, spend time looking at your raw data and answering three questions: what are the columns, what types of values live in each column, and what is the unit of observation. The third question is the one most beginners miss. A row should represent one thing, whether that is one customer, one transaction, one product listing, or one day of sensor readings. When your data violates this principle, everything downstream becomes painful. I once spent three hours debugging a revenue calculation because a single order had been split across multiple rows in ways that weren't obvious from the column headers. The dataset looked clean until I summed revenue by order ID and got numbers that were roughly four times higher than the invoice total. Cross-referencing the order IDs against the line items revealed that some orders had been duplicated with slightly different timestamps due to a sync error between two systems. The fix was a simple deduplication step, but it cost me half a day to find. Learn the basic data types properly. Strings, integers, floats, booleans, dates, and categorical variables behave differently in every tool you will encounter. Mixing up integer division and float division in Python will silently give you wrong averages. Treating a date column as a string will break sorting and filtering. These are not edge cases. They happen constantly in real work.
The Tool Decision
You have three realistic options for getting started, and none of them require buying anything. Excel or Google Sheets. Good for small datasets, quick lookups, and people who need to share results with non-technical stakeholders. Pivot tables, VLOOKUP, and basic charting cover a surprising amount of everyday work. The ceiling is low, though. Anything beyond fifty thousand rows gets slow, and reproducibility is terrible because formulas live inside cells where they can be accidentally overwritten or broken when columns shift. Python with pandas. This is the default for a reason. It handles messy data well, scales to millions of rows on a laptop, and produces reproducible code instead of fragile spreadsheets. The learning curve is steeper than Excel but gentler than SQL for exploratory work. Install Anaconda or use a free Jupyter environment, learn the DataFrame object, and focus on read_csv, groupby, merge, and basic plotting. That is roughly eighty percent of what you will do in the first year.
Get the Full Details

SQL. If your data lives in a database, which it almost certainly does in any professional setting, SQL is non-negotiable. SELECT, WHERE, GROUP BY, JOIN, and subqueries handle most analytical queries. Start with SQLite since it requires no installation, then move to PostgreSQL if you want something closer to production. You do not need to learn advanced query optimization early on. You need to learn not to write queries that scan entire tables when a simple index would help.
Cleaning Data Without Crying
Data cleaning is where most beginners quit or develop bad habits. The wrong approach is to manually fix rows in a spreadsheet and save a new file. The right approach is to write code that does the cleaning so you can rerun it when the data changes. This is not a luxury. It is the difference between having a process and having a temporary patch. Start by checking for missing values in every column. Pandas has isna().sum() which returns the count of missing entries per column in under a second. Excel has ISBLANK but it does not give you a summary view across an entire dataset without building a pivot table. Decide what to do with missing values based on the column, not arbitrarily. Removing rows with any missing value might destroy your sample. Filling with zero is almost always wrong unless zero is a meaningful value. Filling with the median of the column is usually safer than the mean because outliers distort averages. I had a dataset of customer satisfaction scores where roughly fifteen percent of entries were missing for one particular region. The initial instinct was to drop those rows, but that region represented twelve percent of total transactions. Dropping them skewed the overall average upward by almost two points. I filled the missing values with the regional median instead and noted the assumption in a comment so anyone reviewing the work could see what happened. Watch out for invisible whitespace and inconsistent casing. A column that contains "NY", "ny", " ny ", and "N.Y." is five categories to most aggregation functions, not one. Strip whitespace and lowercase everything before grouping. Duplicate detection is another common trap. Two rows might look identical to the human eye but contain different timestamps or internal IDs. Use subset parameters in pandas drop_duplicates or EXCEPT in SQL to find true duplicates based on the business keys that matter.
Common Pitfalls That Look Fine Until They Don't
Averaging percentages is dangerous. If you have a 90 percent conversion rate on 100 visitors and a 10 percent conversion rate on 1,000 visitors, the simple average is 50 percent. The correct weighted average is about 18 percent. This mistake shows up in dashboards constantly because tools like Excel will happily average a selected range without warning you. Correlation is not causation, but more importantly, correlation does not imply a linear relationship. Two variables might be strongly related in a U-shaped pattern, and a Pearson correlation coefficient would report near zero. Always plot your data before running statistical tests. Scatter plots catch things that summary statistics hide. I found this out when analyzing the relationship between response time and error rate in a logging system. The correlation coefficient was negligible, which initially suggested no relationship. Then I plotted the data and saw a clear threshold effect. Below five hundred milliseconds, errors were rare. Above five hundred milliseconds, error rates spiked dramatically. The relationship was nonlinear, and a simple correlation test missed it entirely. Silent data type conversions are another source of headaches. Pandas might convert a column of zip codes from integers to strings automatically, then your numeric aggregation functions fail later. SQL might silently truncate decimal precision when you insert into an integer column. Always check the data type after importing or joining datasets.
Building Something Real
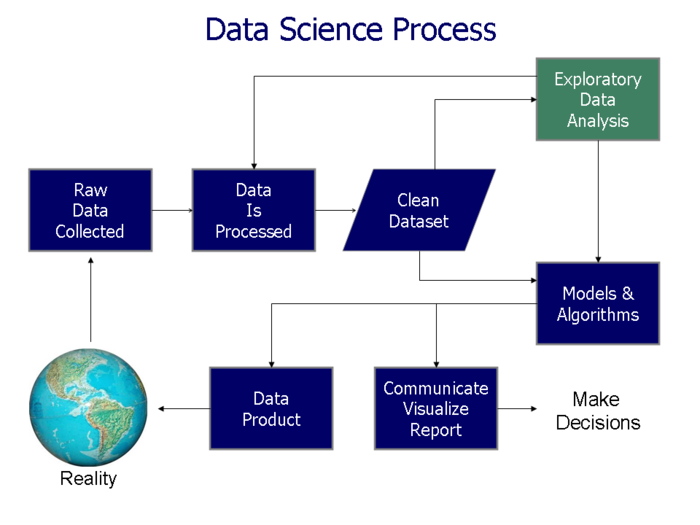
The fastest way to learn is to work with a dataset that has actual messiness in it. Clean, textbook datasets do not prepare you for real work. Download a public dataset from Kaggle or a government open data portal, import it into your chosen tool, and try to answer a specific question. Something like "what is the average transaction value by product category for the last six months, excluding cancelled orders?" forces you to handle date filtering, joins, grouping, and outlier removal in a single workflow. When you hit a problem, look it up. Stack Overflow and the official documentation are better teachers than any structured course at this stage. Keep a notebook of the problems you encounter and how you solved them. I still refer back to notes I wrote two years ago about merging datasets on date ranges instead of exact matches. The solution involved using pandas merge_asof, and I would have wasted hours rediscovering it without the note. This practice compounds over time.
What This Approach Does Not Do
It will not teach you machine learning. It will not prepare you for big data infrastructure or distributed computing. It will not make you proficient in advanced statistical inference. Data Analysis For Dummies resources are designed to get you to a competent beginner level, and that is their actual purpose. If you need to build predictive models or work with petabyte-scale datasets, you will need additional study after you have the fundamentals locked down. Spreadsheets will also fail you once your dataset grows beyond what your computer can hold in memory. Pandas loads everything into RAM, which works fine until your dataset exceeds available memory. At that point you need to consider chunked processing, Dask, or moving the computation to a database. Acknowledging these limits upfront prevents frustration later.