Building Histograms in Excel Without Losing Your Mind
Data Analysis Histogram Excel
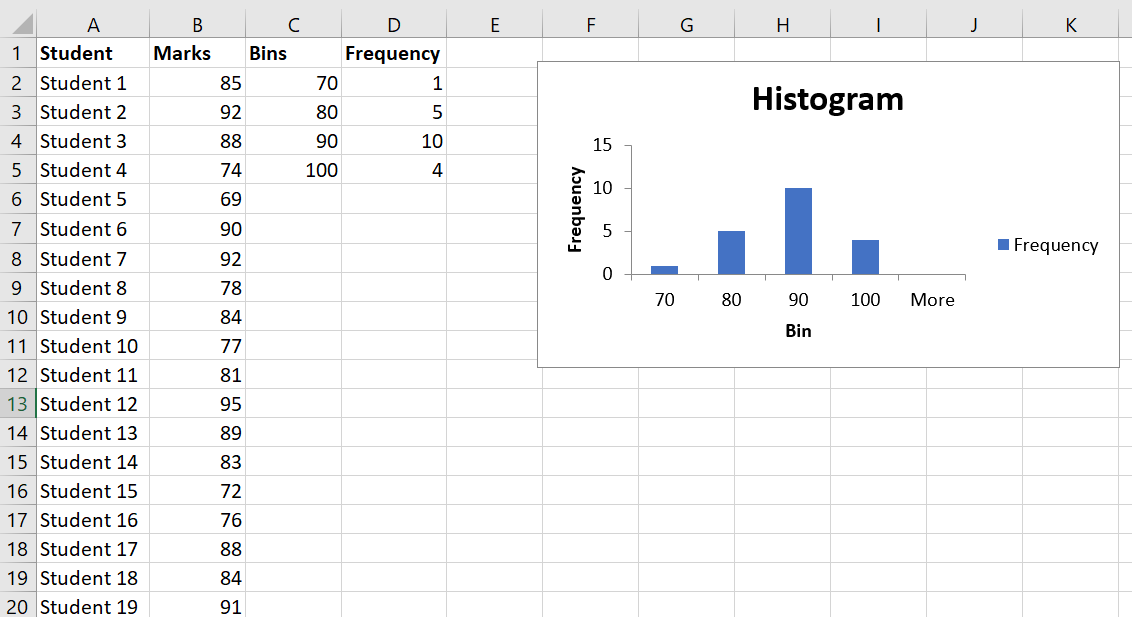
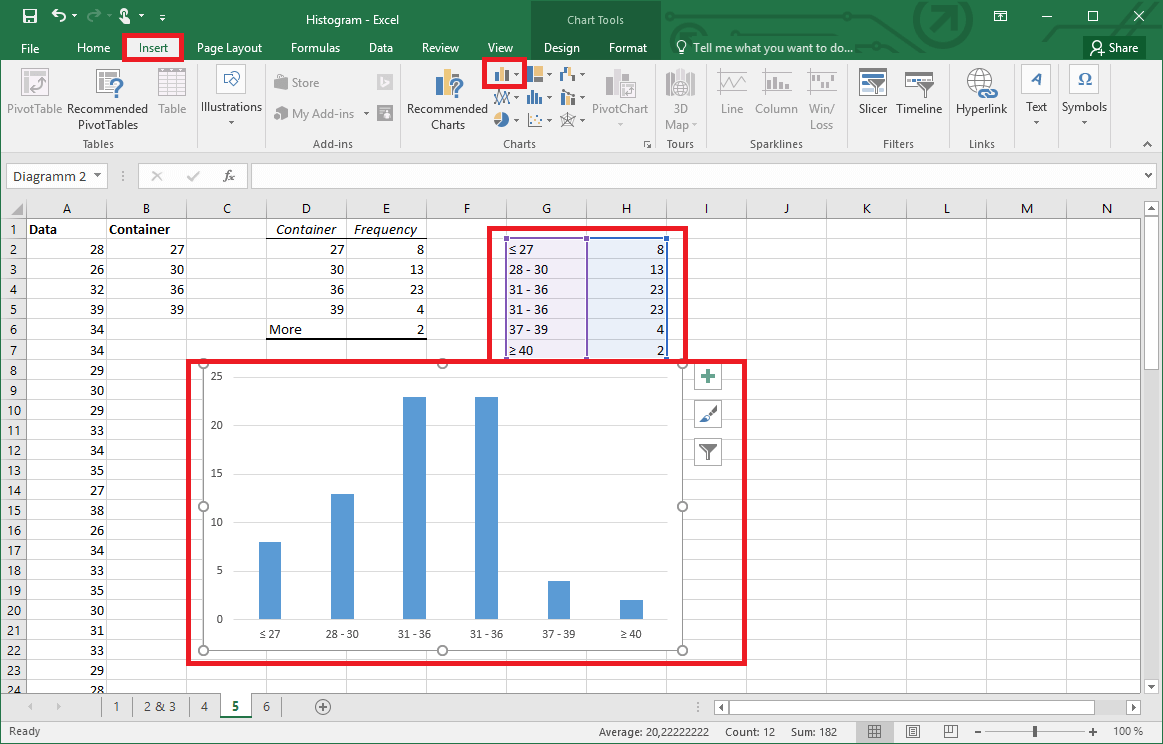
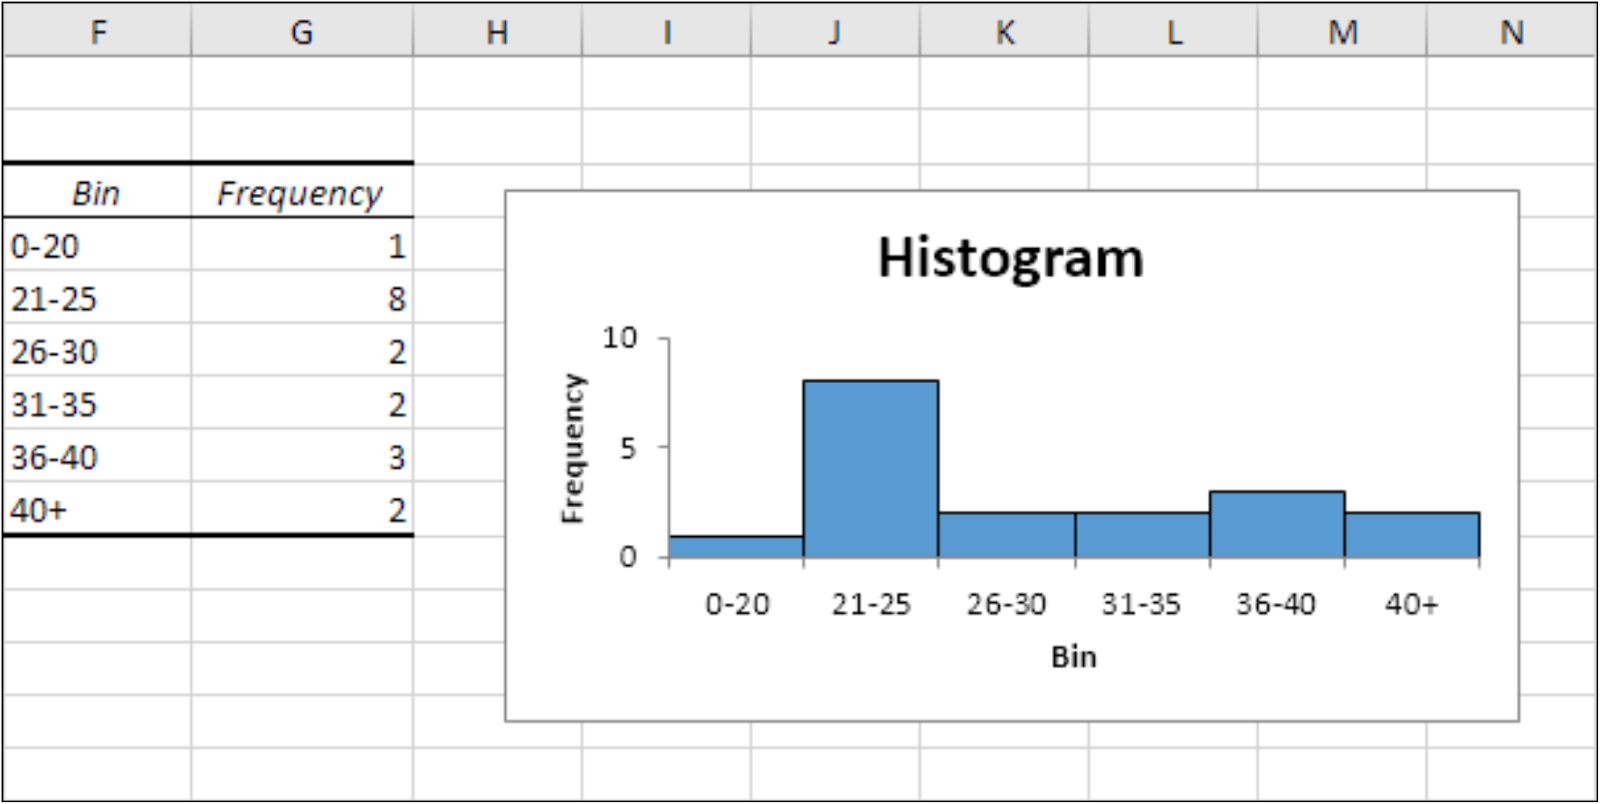
Excel doesn't make it obvious where the histogram tool lives. If you're opening a fresh workbook and just trying to get a frequency distribution out of a column of numbers, you'll poke around the Insert tab for a while before giving up. The real path goes through the Data tab, then Data Analysis in the Analysis group. If that button isn't there, you need to load the Analysis ToolPak from File > Options > Add-ins first. It's been buried there since 2003, which means anyone who learned Excel on anything older will tell you it's a mystery they've solved through pain. I once spent forty-five minutes trying to force a histogram out of a dataset because I had accidentally filtered the view before running the tool. The Analysis ToolPak doesn't respect Excel's visible filter. It reads the raw range. So my histogram showed frequencies for the entire unfiltered dataset while the chart area looked like garbage because the bins didn't align with what I was actually looking at. The fix was brutal: delete the filter, run the analysis on a clean copy, then rebuild whatever pivot or dashboard you were working from. I stopped making that mistake after the third time, but I still lose fifteen minutes occasionally when I'm switching between filtered and unfiltered sheets on instinct. The core mechanic is simpler than most people make it. You feed it a single column of raw values as the Input Range, optionally specify where Bin Ranges live if you want control over bucket boundaries, and tell it where to dump the output. Excel spits back two columns: the bin edges and the frequency counts. Then you select those two columns, go to Insert > Charts > Histogram. The result looks nothing like the Analysis ToolPak output by default, which confuses people who don't expect the wizard to generate a separate table before the chart even appears.
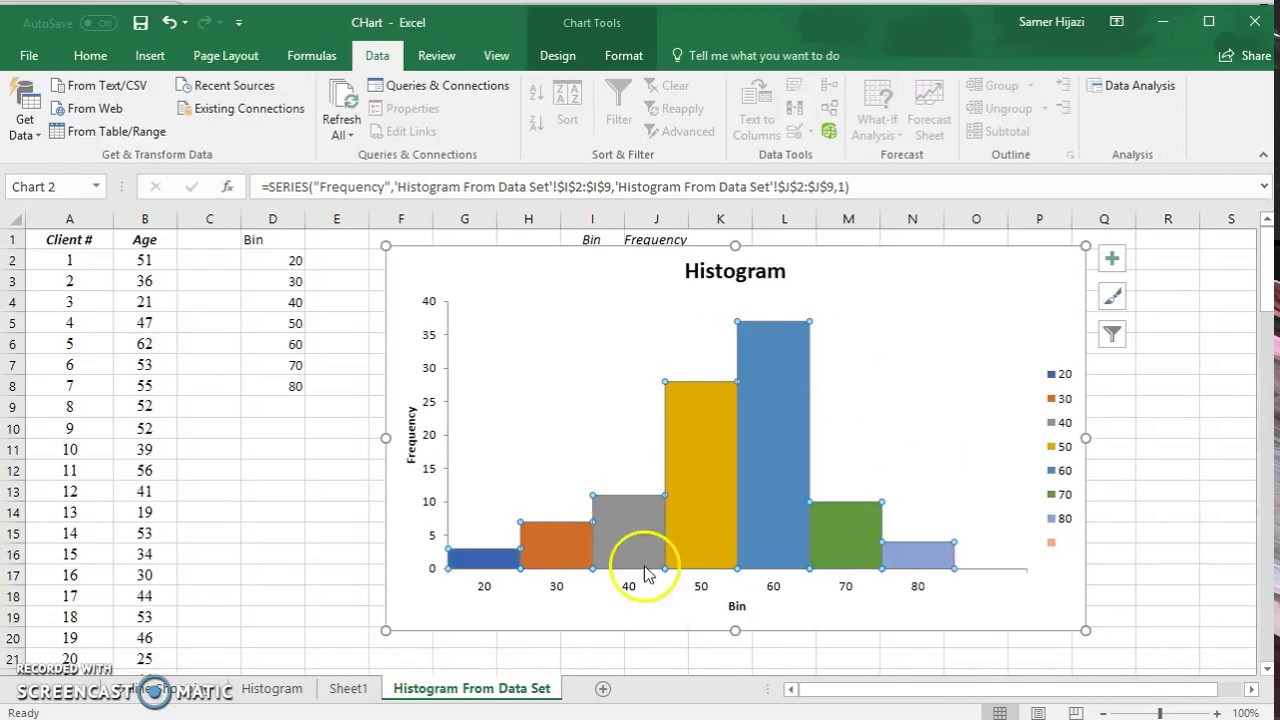
Here's what nobody tells beginners about bin sizing. Excel automatically calculates bin widths based on your data range and sample size using what it calls a "automatic" bin algorithm. That usually means the Sturges or Freedman-Diaconis rule, though Excel doesn't name either of them. The bins it generates will look reasonable on a normal distribution. They look terrible on anything skewed, bimodal, or heavily clustered. I've seen analysts ship histograms with thirty bins on a dataset of twelve hundred points because they trusted the default, and the resulting chart made every minor fluctuation look like a signal. It was noise. You can override the bin width manually by right-clicking the horizontal axis, choosing Format Axis, and setting Bin width to a fixed number instead of letting Excel choose. Another thing that catches people off guard: the Analysis ToolPak histogram output includes a cumulative percentage column if you check that box. It also includes a chart if you tell it to create one. Some versions of Excel will create both in the same output and you'll end up with a worksheet that has the frequency table, the cumulative table, and an embedded chart all overlapping. I usually uncheck "Chart Output" when running the tool and build the chart separately. That way I have full control over the axis scaling, bin labeling, and formatting without fighting a pre-rendered chart object that refuses to resize cleanly. The real bottleneck most people hit is when they need to recalculate bins after the fact. Say you run a histogram, look at the chart, and realize your bins are too wide. You change the bin width in the Format Axis dialog and the chart updates. But the underlying frequency table from the Analysis ToolPak is now wrong. It's still counting against the original bins. You have to rerun the entire analysis if you want a new table to match. There's no live link between the chart formatting and the source data. I wrote a small VBA macro that grabs the current bin width from the axis, regenerates the bin edges as a helper column, and then runs FREQUENCY against it. It saves me about ten minutes per rebuild, which sounds trivial until you're producing twenty histograms a week for a client report.
If you're working with large datasets, above fifty thousand rows, the Analysis ToolPak gets slow. Not unusable, but noticeable. It processes everything in memory during the calculation phase. I switched to a dynamic approach using LET and SEQUENCE functions for those cases, which cut processing time from roughly forty seconds down to under three seconds on a standard laptop. The formula creates bin edges,FREQUENCY counts them, and spill arrays handle the rest. It also means you can build a self-updating dashboard where changing the source data automatically refreshes the bins without re-running any tool. The biggest limitation of Excel's histogram tools is that they don't handle missing values gracefully. If your input range contains blanks, Excel treats them as zeros in the Analysis ToolPak version. In a FREQUENCY formula, blanks get ignored entirely, which is more correct but still worth knowing about. I learned this the hard way on a customer satisfaction dataset where roughly eight percent of responses were blank because the survey logic skipped certain questions. The histogram showed a massive spike at zero that looked like a real cluster. It was just missing data being treated as a value. My workaround was always to add a COUNTBLANK check before running any analysis, and to filter or replace blanks explicitly rather than hoping the tool would understand them. For people who need this regularly, the Analysis ToolPak is adequate but archaic. It hasn't changed meaningfully in over a decade. The formula-based approach is faster for large data and fully dynamic. For one-off charts on small datasets, the wizard is fine if you remember to check your bins afterward and rerun the analysis when they change.
Get the Full Details