The gap between what people expect and what actually works
Most beginners assume you just upload a spreadsheet and get back polished charts. It doesn't work like that. You have to think about what the model can actually do with your data, what it will do wrong, and where the process usually breaks down. I learned this the hard way on a project where I needed a client to review quarterly figures without sending them the raw file. I used Data Analysis With Chat Gpt for the first time on a real deliverable. The output looked clean until someone noticed a few line items were shifted by one row. That was my first lesson.Data Analysis With Chat Gpt
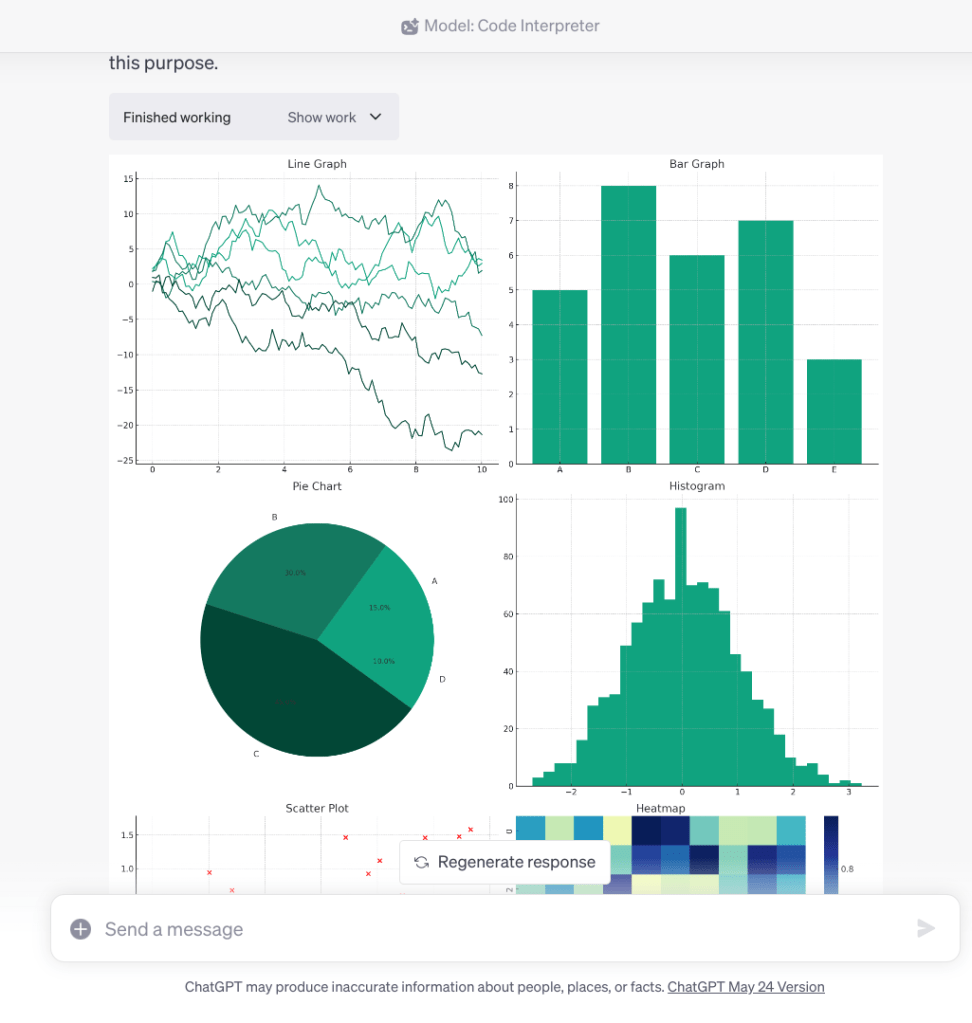
The tool is straightforward once you understand the workflow. You provide a dataset, describe what you want, and the model writes Python code to run against your file. It can handle pandas, matplotlib, seaborn, scipy, and a few other standard libraries. The Python engine executes in a sandboxed environment and returns results, tables, or images. That's the basic shape of it. The details are where people trip up.Start by preparing your data in a way that doesn't fight the model. CSV, XLSX, and JSON are the standard formats. Clean headers help. If your columns have missing values or inconsistent naming, the model will guess, and guessing is where errors appear. I once had a column labeled "Net Rev (tmb)" in one file and "Net Revenue" in another. The model tried to merge them and produced a NaN-filled column that looked fine at a glance. I caught it because I kept the raw file open side by side. When you prompt the model, be specific about the calculation, not just the outcome. Saying "show me revenue trends" is vague. Saying "compute rolling 30-day average of column A, exclude rows where column B is null, and plot with error bars from standard deviation" gives the model a clear path. The more precise your instructions, the fewer iterations you need. On average, a well-written first prompt gets you closer to a working result than two rounds of revision. I usually spend about five minutes refining the prompt before I even paste the file.
Code generation and the hidden failure points
The model writes Python, but it doesn't always read your mind about column names, dates, or categorization. Here is a practical example. I asked it to group sales data by region and month and calculate a percentage change. It produced code that ran without errors, but the percentage change was based on the wrong baseline. The model treated the first row as the anchor instead of the first month of each region. I had to add a groupby().shift() step and specify the sorting order explicitly. After that, the numbers matched what I expected. This is a common pattern. The model will produce syntactically correct code that is logically wrong. You always need to verify the output against a known sample.I also learned that date parsing is a frequent source of problems. If your dates are in mixed formats, the model may parse them as strings instead of datetime objects. This makes grouping by month impossible. The fix is simple: tell the model the date format in the prompt and have it convert the column with pd.to_datetime() before any other operation. I include the format string in the first message every time. It saves at least one round of debugging.
Output quality and verification
Charts look good. Tables look clean. Verification is the step most people skip. You should check at least three things before you consider the analysis complete.- Shape of the data: Confirm the row count matches expectations. If your input has 12,000 rows, the output should not have 11,500 unless you filtered intentionally.
- Basic statistics: Compare the mean, median, and standard deviation from the model against a quick manual calculation or a separate tool.
- Edge cases: Look for zero division, empty groups, or unexpected NaN propagation. These usually surface in the final chart or summary table.
I keep a small notebook of common failure modes. It includes issues like datetime alignment across timezones, duplicate column names after merge, and integer overflow in large aggregations. Each of these can produce results that look normal but are technically incorrect. The notebook helps me catch them faster.
Get the Full Details
When the tool does and does not work
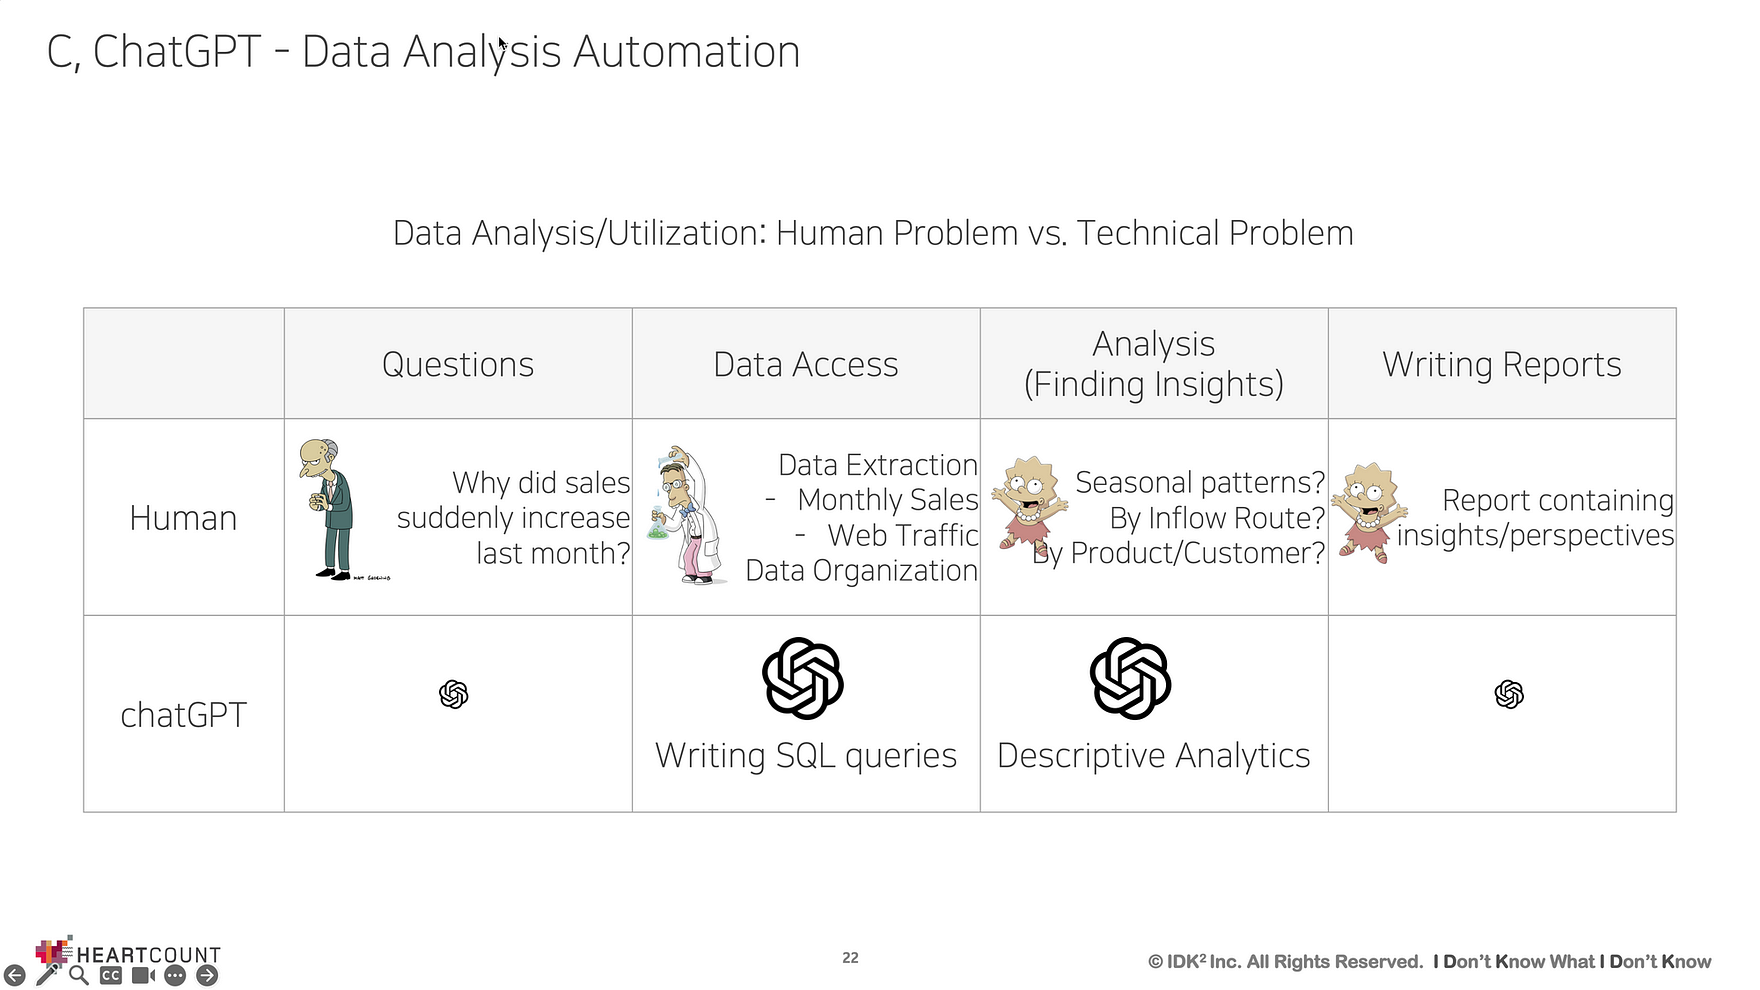
The tool excels at routine transformations, standard visualizations, and straightforward statistical summaries. It struggles with domain-specific logic, custom business rules, and data that requires subjective judgment. If your analysis depends on a company policy that is not documented in the dataset, the model cannot infer it. It will make something up. I found this out when a client asked for a churn score based on an internal heuristic. The model produced a reasonable-looking formula, but it did not match the documented approach. I had to rewrite the scoring logic myself and use the model only to implement it.Another limitation is context length. Large files can exceed the model's window, which forces you to split the data or summarize before analysis. I typically cap my uploads at around 50 MB. Anything larger requires preprocessing. The workaround is to aggregate the data at the source or use sampling for exploratory work, then run the full calculation on the aggregated subset.
Practical workflow that actually saves time
I use a consistent sequence. First, I clean the data outside the model. I remove obvious duplicates, standardize column names, and check for missing values. This step usually takes five to ten minutes for a typical file. Second, I write the prompt with explicit column names, date formats, and the desired output structure. Third, I run the model and inspect the code before executing it. Fourth, I compare the output against a hand-calculated sample. Fifth, I iterate only if something is wrong. This sequence reduces the chance of hidden errors and keeps the process fast.The total time savings depend on the task. For a standard pivot table with a bar chart, I usually cut the process down from about forty minutes to fifteen. For a more complex analysis involving multiple joins and custom aggregations, the reduction is smaller, maybe from two hours to forty-five minutes. The value is not in magic. It is in removing the boilerplate and letting the model handle the tedious coding while you focus on correctness.