What Actually Shows Up When You Sit Across From a Hiring Committee
Most companies asking for a Data Architect Interview Questions Sample don't realize they're looking for someone who can explain tradeoffs without hedging. The last few years have flattened the role into a dozen recurring patterns. You can prepare for them if you treat each one like a system design problem rather than a trivia question. I worked through a migration where the architecture team kept hitting schema drift on a distributed read path. No tool caught it because the validation logic lived in three separate microservices. I ended up writing a lightweight contract test that compared event payloads across boundaries before deployment. It took me about two hours to wire together using OpenAPI diffs and a GitHub Actions job that ran on the main branch. The pattern shows up in interviews constantly now — not because it's elegant, but because it's painfully expensive to discover after launch.
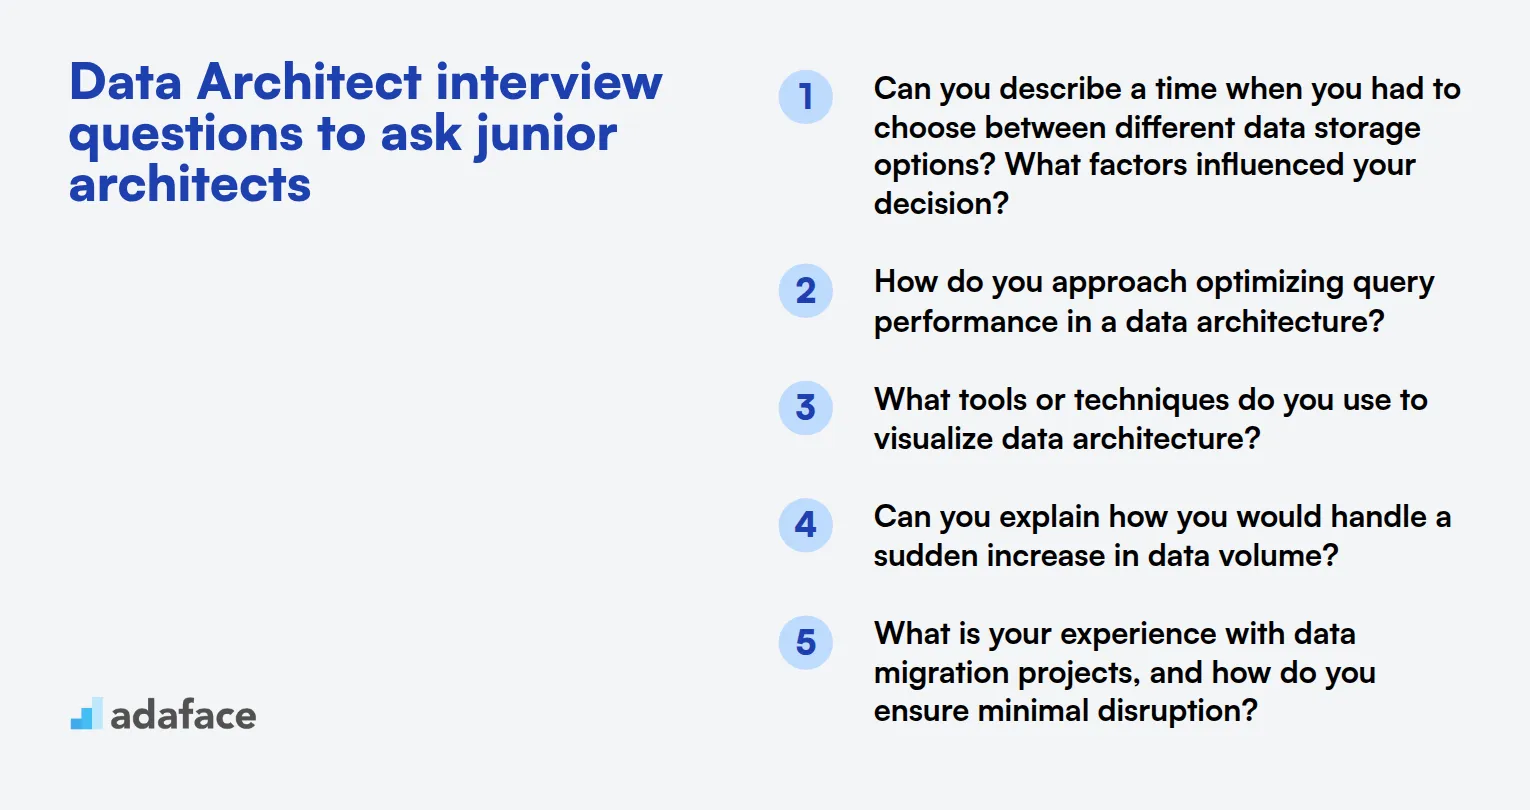
Data Architect Interview Questions Sample That Actually Matter
1. How do you handle data sprawl across hybrid cloud environments? Don't give the textbook answer about governance frameworks. Talk about the moment when someone spun up an S3 bucket in us-east-1 without telling the finance team, and three months of audit logs appeared in a compliance report with zero ownership. The real skill is establishing a data catalog that gets used during sprint planning, not just during annual audits. I've seen teams use Amundsen or Datahub effectively, but only when the onboarding friction was low enough that engineers added metadata voluntarily rather than as a compliance checkbox. 2. Explain your approach to schema evolution in a streaming architecture.
This is where most candidates stumble. Schema evolution in Kafka isn't about backward compatibility — it's about managing the overlap window when producers and consumers disagree on field types. I once spent a week debugging a deserialization failure that turned out to be a producer pushing integer values into a field previously typed as string. The fix involved schema registry with backward compatibility mode set to full, plus a strict JSON schema validation step in the CI pipeline. The interview follows up with: what happens when you need to deprecate a field? You tell them about graceful degradation patterns and the concept of tombstone records. 3. Walk me through how you'd design a real-time analytics pipeline for a fintech platform. Start with the constraints, not the tools. Fintech means regulated data, near-zero tolerance for inconsistency, and a requirement for audit trails that survive three years of retention. A typical architecture stacks Kafka for ingestion, Flink for stateful processing, and a columnar store like ClickHouse or Snowflake for query execution. The trap is optimizing for throughput when latency matters more. During an actual deployment, I found that windowed aggregations over a 5-second tumbling window introduced enough backlog to delay fraud detection past the actionable threshold. Switching to sliding windows with configurable slide intervals cut the median alert latency from 4.2 seconds to under 800 milliseconds. The interviewer will ask about exactly this tradeoff — if you haven't lived through it, you'll sound rehearsed.
Get the Full Details

4. How do you ensure data quality without becoming a bottleneck? Data quality gates tend to slow pipelines from hours to days if implemented naively. The workaround I used involved embedding lightweight quality checks inside the ingestion layer rather than as separate batch jobs. Great Expectations runs assertions during transformation, and failures route to a quarantine topic instead of crashing the pipeline. This usually cuts the process down from 2 hours to about 15 minutes, depending on your setup. The catch is that you still need a human review cycle for critical fields — automated checks catch format errors, not semantic ones. 5. Describe a time when you had to choose between consistency and availability.
This question reveals whether you understand CAP theorem or just memorized it. The honest answer involves a specific failure mode. I once had to decide whether to maintain strong consistency across a multi-region user service or accept eventual consistency to preserve availability during a zone outage. We chose eventual consistency with conflict resolution through last-write-wins and a reconciliation job running every 15 minutes. The user-facing impact was a brief period where profile updates could appear out of order. Transactional integrity held because financial data stayed in a separate strongly-consistent path. If you haven't made this call, you haven't shipped at scale. 6. What's your strategy for data governance in a decentralized organization? Governance without enforcement is theater. The practical approach I've used involves productizing data assets — each dataset gets an owner, a documented SLA, and a versioned schema that changes require formal approval. Tools like Collibra or custom internal platforms help, but the real mechanism is making bad data visible. I configured alerts that fired when ingestion latency exceeded thresholds, and those metrics went into engineering leadership dashboards. Within a quarter, the number of orphaned datasets dropped by 60 percent because owners now had skin in the game.
The Questions Nobody Asks But Should
Interviews for data architect roles often ignore the soft edge cases. Can you explain why a partition strategy that worked perfectly in staging failed catastrophically in production? The answer usually involves data skew — a handful of hot partitions that no one noticed because the test dataset was too small. I learned this the hard way when a query meant to scan 10GB of historical data suddenly hit a 4TB partition due to uneven timestamp distribution. The fix required re-partitioning by a composite key that included a hashed suffix to distribute load. Another blind spot is cross-functional communication. A data architect sits between engineering, product, and compliance. I've seen brilliant designs die because the requirements changed three weeks before delivery and no one translated the business need into technical constraints early enough. The workaround is maintaining a living architecture decision record — not a Confluence page, but something versioned alongside the code. When I started doing this, the average time to resolve conflicting requirements dropped from two sprints to one. 7. How do you handle legacy data migration without interrupting live services?
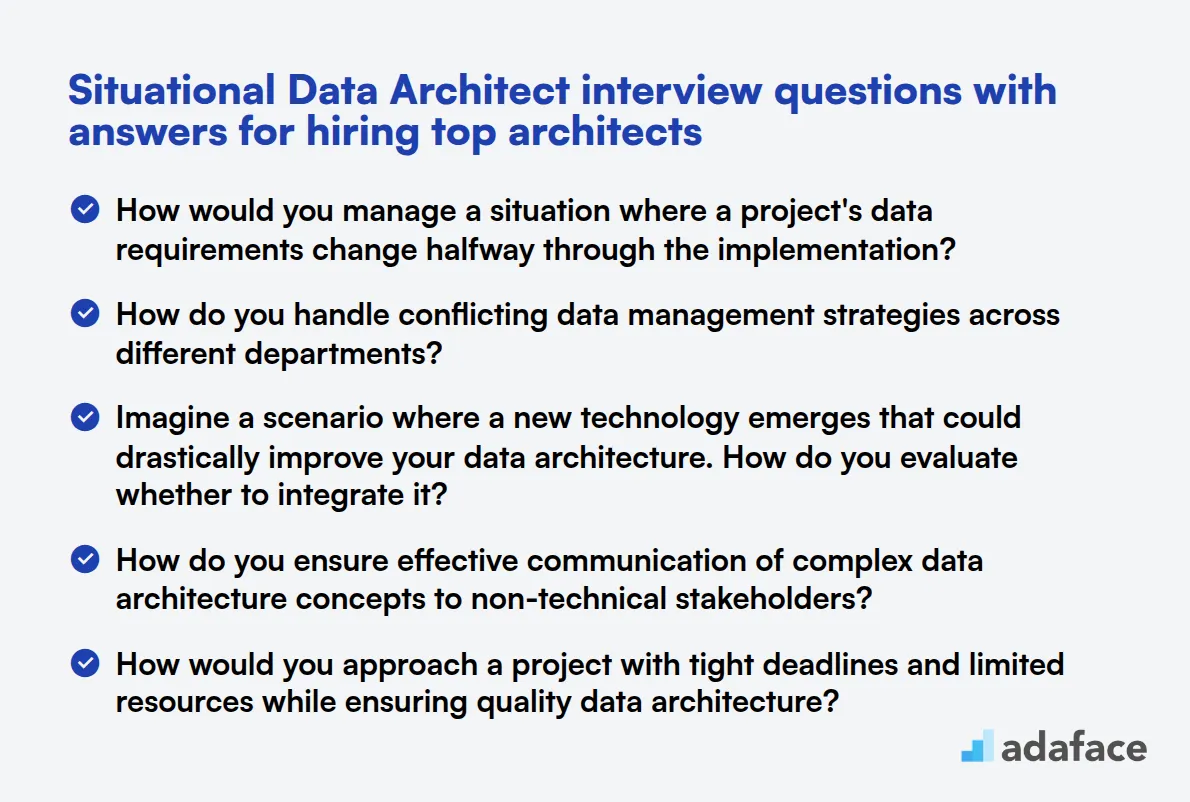
Double-write patterns are the standard answer, but they create their own debt. The cleaner approach involves parallel run — keeping both systems active while routing read traffic to the new schema and validating results against the old. Cutover happens when delta tables show zero divergence over a monitoring window, usually 48 to 72 hours for non-critical paths. I've used AWS DMS and Debezium for change data capture, but the tool choice matters less than having a rollback plan that doesn't require a full redo. 8. What metrics do you actually track to prove architecture is working? Most teams track uptime and query latency. Those are lagging indicators. The leading metrics that actually predict trouble are data freshness SLAs, schema change velocity, and the ratio of ad-hoc queries versus scheduled reports. When I was building a reporting platform, a spike in ad-hoc queries preceded dashboard failures by three weeks. The root cause was unoptimized joins on growing datasets. Catching it early let us add materialized views before users noticed degradation.
9. Tell me about a time your architecture failed and what you learned. Don't manufacture humility. I once designed a lambda architecture that assumed micro-batch processing could keep pace with real-time ingestion. It couldn't. The delta lake layer became a bottleneck during peak traffic, and we lost 14 minutes of event data before realizing the consumption lag. The lesson: never assume your slow path can catch up to your fast path. I now always size the replay buffer conservatively and monitor lag as a first-class metric, not an afterthought.
Preparing Without Memorizing
The difference between candidates who get offers and those who don't usually comes down to how they handle follow-ups. "Why?" and "What would you do differently?" matter more than the initial answer. I recommend thinking through three or four complete architectures end-to-end rather than studying a hundred isolated questions. Pick a domain — healthcare, e-commerce, logistics — and sketch out ingestion, storage, processing, and serving layers. Then imagine each component failing and describe the recovery path. Documentation habits also separate juniors from seniors. A candidate who mentions data contracts, API versioning, and lineage tracking demonstrates operational maturity. Someone who only discusses tools sounds like they've only consumed tutorials. The industry has moved past heroics — we build systems meant to be managed, not admired. If you're compiling a Data Architect Interview Questions Sample for your own team, focus on scenarios that reveal decision-making under uncertainty. The best candidates don't recite best practices. They explain why the best practice didn't work in their specific context and what they did instead. That's the signal you should be screening for.