Getting Data Engineering On Google Cloud Platform to actually work
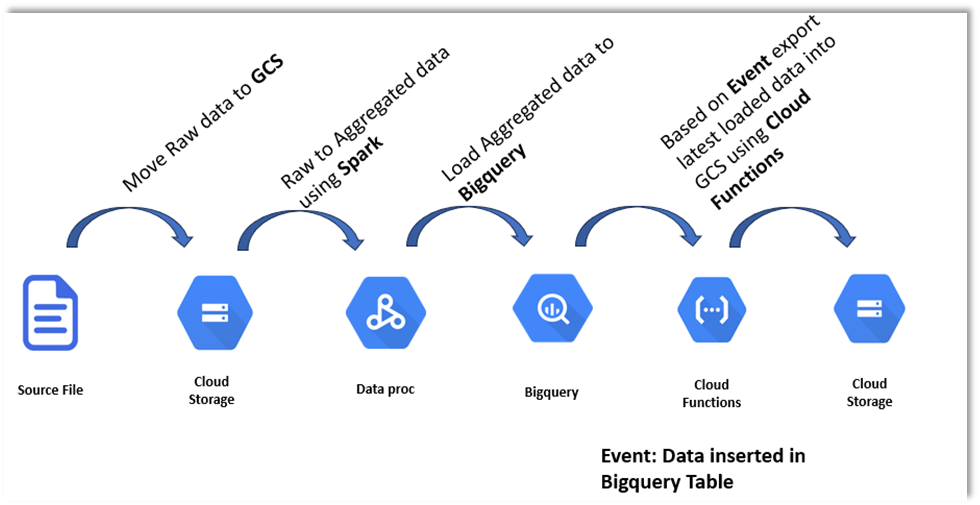
The first thing you need to understand is that BigQuery isn't a database and it isn't a data warehouse in the traditional sense. It's a columnar analytics engine running on Google's infrastructure. You don't put transactional data in it and expect good performance. I've seen teams try to use BigQuery as a replacement for PostgreSQL on their application layer and then wonder why queries are costing them thousands of dollars instead of returning in milliseconds. Here's how I actually set up a data engineering pipeline on GCP. Start with Cloud Storage as your landing zone. Raw files come in, get validated, and then move to a processed bucket. The validation step is where most people skip and immediately regret it later. I use a Cloud Run service that checks file schemas, verifies partitioning keys match what the downstream tables expect, and rejects anything malformed before it ever touches BigQuery. This usually saves me from having to debug why a 4AM job failed because some upstream service sent a date string in MM/DD/YYYY format instead of YYYY-MM-DD.
Data Engineering On Google Cloud Platform for batch pipelines
For batch processing, Dataflow is the default choice and it's fine until it isn't. I use it when the pipeline involves complex transformations, multiple sinks, or when you need exactly-once processing semantics across write targets. The catch is that setting up a Dataflow job properly takes time. You need to think about your beam pipeline runner, choose between the DirectRunner for local testing and the DataflowRunner for production, and understand how windowing works if you're doing any aggregation. There's a specific edge case that tripped me up for weeks. When you write to BigQuery from Dataflow using the WriteToBigQuery transform without specifying a table schema explicitly, Dataflow tries to infer it from your PCollection. This works until your data has null values in certain columns, which causes BigQuery to default those columns to STRING type instead of what you actually wanted. The fix is to define your table schema in code before writing and pass it to the transform. Here's roughly what that looks like:
table_schema = bigquery.TableSchema({
    'fields': [
        bigquery.TableFieldSchema(name='user_id', type='INTEGER'),
        bigquery.TableFieldSchema(name='event_type', type='STRING'),
        bigquery.TableFieldSchema(name='timestamp', type='TIMESTAMP'),
    ]
})
pcollection | beam.io.WriteToBigQuery(
    table='dataset.events',
    schema=table_schema,
    write_disposition=beam.io.BigQueryDisposition.WRITE_APPEND
)
Without that explicit schema, the first few records with null user_id would make BigQuery create the column as STRING, and then you'd spend the next day rerunning backfills with ALTER TABLE statements. Airflow on Cloud Composer is the standard answer and it's the right one for most cases. But here's something nobody tells you: Composer environments have a hard limit on the number of DAGs you can run concurrently, and that limit is tied to your Airflow scheduler workers. I once had a pipeline that worked fine with twelve DAGs and then broke when we added a thirteenth because the scheduler started skipping task heartbeats. The resolution was upgrading the Composer environment to use at least two scheduler instances and tuning the scheduler heartbeat interval. For simpler use cases where you just need cron-style execution, Cloud Scheduler paired with Cloud Functions or Cloud Run works well enough. A Cloud Scheduler job triggers a Cloud Run endpoint every hour, and that endpoint kicks off a BigQuery query or a Dataflow job. This setup avoids the overhead of Composer entirely and is perfectly adequate if your dependencies are shallow. The tradeoff is that you lose visibility into execution history and dependency management, which matters when your pipeline has five or more stages.
Get the Full Details

Streaming data and Pub/Sub
When you need real-time ingestion, Pub/Sub is your messaging layer. Events from applications or IoT devices go into topics, and subscribers consume them. The typical pattern is Pub/Sub to Cloud Pub/Sub subscriber to Dataflow to BigQuery or Cloud Storage. This works, but there's a latency trap. Dataflow batches messages internally by default, which means you might see a delay of thirty to sixty seconds between when a message hits Pub/Sub and when it appears in your sink. If you need sub-second latency, you have to tune Dataflow's streaming buffer settings and accept higher costs from more frequent commits. I encountered a problem where messages were arriving out of order because multiple producers were writing to the same Pub/Sub topic without assigning ordering keys. Dataflow's watermark tracking got confused, and my event-time windows were producing incorrect aggregates. The workaround was to enable message ordering on the topic and ensure every producer included a consistent ordering key in each message. It added some operational complexity but fixed the data quality issue completely.
Cost management that doesn't hurt
BigQuery pricing has two components: slot-based querying and storage. Storage is cheap, roughly five dollars per terabyte per month. Querying is where people get burned. A single poorly written query against a ten-terabyte table without proper filtering can cost over a hundred dollars in on-demand pricing. I learned this the hard way when a developer ran a SELECT * across a fact table to debug an issue and racked up a bill that took three weeks to explain to finance. The solution is partitioned and clustered tables. Partition by ingestion date or event date, and cluster by the most commonly filtered columns. This can reduce query costs by eighty to ninety percent compared to an unpartitioned table. I also recommend setting up query quotas and budget alerts in Cloud Billing. A query budget alert at ninety percent of your monthly allowance gives you warning before things spiral out of control. For recurring reports, use BigQuery cached results strategically. If two queries against the same table with the same parameters run within four hours of each other, the second one hits the cache and costs nothing. This is especially useful for dashboards that refresh every fifteen minutes and query the same dataset repeatedly.
Security and access control
IAM on GCP is powerful and deeply nested. Service accounts are the primary identity for automated processes, not humans. I've seen teams create service accounts with the BigQuery Admin role attached because it was easier than figuring out the correct combination of roles. This is wrong and it creates security liability. The principle of least privilege means giving each service account only the roles it actually needs. For Data Engineering On Google Cloud Platform, the typical minimum roles are:

- Cloud Storage Admin on the buckets the pipeline reads from and writes to
- BigQuery Data Editor on the specific datasets, not project-level access
- Dataflow Worker if you're using custom service accounts instead of the default
Row-level security in BigQuery is handled through row-level access policies, which are straightforward to set up but easy to misconfigure. I once granted a dataset viewer role to a service account and assumed they could only see public tables. They couldn't, because the dataset itself was private and the viewer role didn't override that. The fix was adding the BigQuery Data Viewer role at the dataset level explicitly. Cloud Monitoring works with GCP services out of the box. Dataflow jobs expose metrics you can visualize, BigQuery queries show slot utilization and bytes processed, and Pub/Sub topics report publish and pull rates. The problem is that most of this monitoring is passive. You get charts and you get alerts, but you don't get automatic recovery when something breaks. I built a simple error handling pattern using Cloud Logging and Cloud Workflows. When a Dataflow job fails, the error log entry contains the job ID, the failed stage, and the exception message. A Workflows orchestration picks up that log entry, retries the job with adjusted parameters if it's a transient error, or sends a Slack notification with the full stack trace if it's a schema mismatch. This cut my on-call response time from about twenty minutes to roughly two minutes for the common failure modes.
One thing that caught me off guard: BigQuery has a per-query slot limit that defaults to 500 slots in most projects. If your complex joins or aggregations exceed that, the query fails with a resource exceeded error. The fix is either to simplify the query, split it into smaller steps, or request a slot limit increase through the Google Cloud console. I've had to request increases up to 2000 slots for our largest ETL jobs during monthly close periods.
Alternatives worth considering
Not every data engineering problem belongs on GCP. If your team is already deep in the AWS ecosystem, moving to GCP just for data engineering creates unnecessary context switching. Similarly, if you need tight integration with Kafka and your organization already runs Confluent Cloud, that might be a better fit than Pub/Sub depending on your latency requirements and operational expertise. For smaller teams without dedicated data engineering staff, lookat Managed Service for Apache Spark on Dataproc. It removes a lot of the operational overhead of managing your own cluster, and the pricing is more predictable than raw Compute Engine instances. The tradeoff is that you have less control over node configuration and autoscaling behavior compared to running Spark on your own VMs. The biggest mistake I see people make is trying to replicate on-premise architectures on GCP without adjusting for the cloud-native constraints. Hadoop-style distributed processing doesn't map cleanly to BigQuery's columnar model. Spark on Dataproc is closer to a direct replacement, but even then, the cost profile is different enough that you need to rethink your partitioning strategy and data layout. Data Engineering On Google Cloud Platform works best when you design around what GCP does well rather than forcing your existing patterns into it.
Getting Data Engineering On Google Cloud Platform to actually work
The first thing you need to understand is that BigQuery isn't a database and it isn't a data warehouse in the traditional sense. It's a columnar analytics engine running on Google's infrastructure. You don't put transactional data in it and expect good performance. I've seen teams try to use BigQuery as a replacement for PostgreSQL on their application layer and then wonder why queries are costing them thousands of dollars instead of returning in milliseconds. Here's how I actually set up a data engineering pipeline on GCP. Start with Cloud Storage as your landing zone. Raw files come in, get validated, and then move to a processed bucket. The validation step is where most people skip and immediately regret it later. I use a Cloud Run service that checks file schemas, verifies partitioning keys match what the downstream tables expect, and rejects anything malformed before it ever touches BigQuery. This usually saves me from having to debug why a 4AM job failed because some upstream service sent a date string in MM/DD/YYYY format instead of YYYY-MM-DD.
Data Engineering On Google Cloud Platform for batch pipelines
For batch processing, Dataflow is the default choice and it's fine until it isn't. I use it when the pipeline involves complex transformations, multiple sinks, or when you need exactly-once processing semantics across write targets. The catch is that setting up a Dataflow job properly takes time. You need to think about your beam pipeline runner, choose between the DirectRunner for local testing and the DataflowRunner for production, and understand how windowing works if you're doing any aggregation. There's a specific edge case that tripped me up for weeks. When you write to BigQuery from Dataflow using the WriteToBigQuery transform without specifying a table schema explicitly, Dataflow tries to infer it from your PCollection. This works until your data has null values in certain columns, which causes BigQuery to default those columns to STRING type instead of what you actually wanted. The fix is to define your table schema in code before writing and pass it to the transform. Here's roughly what that looks like:
table_schema = bigquery.TableSchema({
    'fields': [
        bigquery.TableFieldSchema(name='user_id', type='INTEGER'),
        bigquery.TableFieldSchema(name='event_type', type='STRING'),
        bigquery.TableFieldSchema(name='timestamp', type='TIMESTAMP'),
    ]
})
pcollection | beam.io.WriteToBigQuery(
    table='dataset.events',
    schema=table_schema,
    write_disposition=beam.io.BigQueryDisposition.WRITE_APPEND
)
Without that explicit schema, the first few records with null user_id would make BigQuery create the column as STRING, and then you'd spend the next day rerunning backfills with ALTER TABLE statements. Airflow on Cloud Composer is the standard answer and it's the right one for most cases. But here's something nobody tells you: Composer environments have a hard limit on the number of DAGs you can run concurrently, and that limit is tied to your Airflow scheduler workers. I once had a pipeline that worked fine with twelve DAGs and then broke when we added a thirteenth because the scheduler started skipping task heartbeats. The resolution was upgrading the Composer environment to use at least two scheduler instances and tuning the scheduler heartbeat interval. For simpler use cases where you just need cron-style execution, Cloud Scheduler paired with Cloud Functions or Cloud Run works well enough. A Cloud Scheduler job triggers a Cloud Run endpoint every hour, and that endpoint kicks off a BigQuery query or a Dataflow job. This setup avoids the overhead of Composer entirely and is perfectly adequate if your dependencies are shallow. The tradeoff is that you lose visibility into execution history and dependency management, which matters when your pipeline has five or more stages.
Streaming data and Pub/Sub
When you need real-time ingestion, Pub/Sub is your messaging layer. Events from applications or IoT devices go into topics, and subscribers consume them. The typical pattern is Pub/Sub to Cloud Pub/Sub subscriber to Dataflow to BigQuery or Cloud Storage. This works, but there's a latency trap. Dataflow batches messages internally by default, which means you might see a delay of thirty to sixty seconds between when a message hits Pub/Sub and when it appears in your sink. If you need sub-second latency, you have to tune Dataflow's streaming buffer settings and accept higher costs from more frequent commits. I encountered a problem where messages were arriving out of order because multiple producers were writing to the same Pub/Sub topic without assigning ordering keys. Dataflow's watermark tracking got confused, and my event-time windows were producing incorrect aggregates. The workaround was to enable message ordering on the topic and ensure every producer included a consistent ordering key in each message. It added some operational complexity but fixed the data quality issue completely.
Cost management that doesn't hurt
BigQuery pricing has two components: slot-based querying and storage. Storage is cheap, roughly five dollars per terabyte per month. Querying is where people get burned. A single poorly written query against a ten-terabyte table without proper filtering can cost over a hundred dollars in on-demand pricing. I learned this the hard way when a developer ran a SELECT * across a fact table to debug an issue and racked up a bill that took three weeks to explain to finance. The solution is partitioned and clustered tables. Partition by ingestion date or event date, and cluster by the most commonly filtered columns. This can reduce query costs by eighty to ninety percent compared to an unpartitioned table. I also recommend setting up query quotas and budget alerts in Cloud Billing. A query budget alert at ninety percent of your monthly allowance gives you warning before things spiral out of control. For recurring reports, use BigQuery cached results strategically. If two queries against the same table with the same parameters run within four hours of each other, the second one hits the cache and costs nothing. This is especially useful for dashboards that refresh every fifteen minutes and query the same dataset repeatedly.
Security and access control
IAM on GCP is powerful and deeply nested. Service accounts are the primary identity for automated processes, not humans. I've seen teams create service accounts with the BigQuery Admin role attached because it was easier than figuring out the correct combination of roles. This is wrong and it creates security liability. The principle of least privilege means giving each service account only the roles it actually needs. For Data Engineering On Google Cloud Platform, the typical minimum roles are:
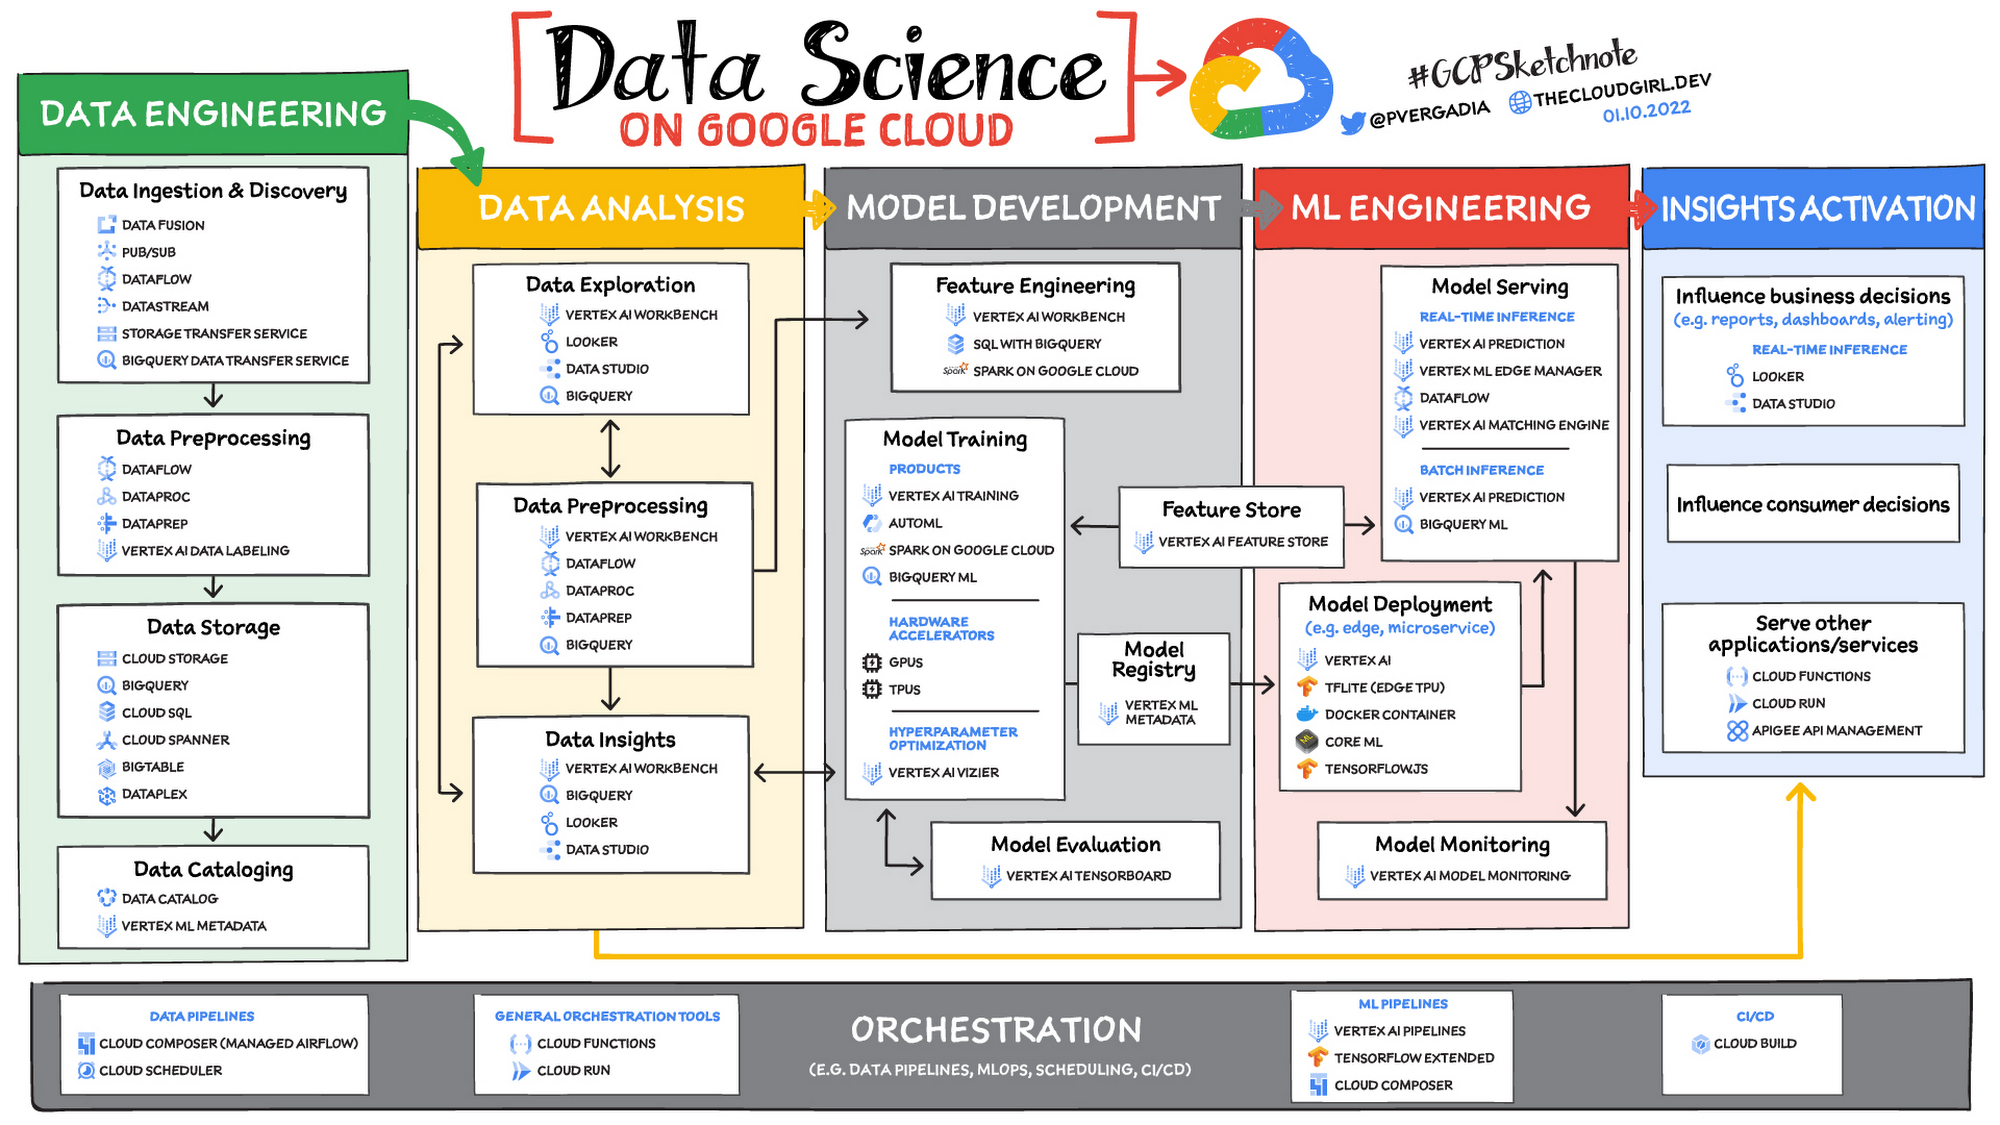
- Cloud Storage Admin on the buckets the pipeline reads from and writes to
- BigQuery Data Editor on the specific datasets, not project-level access
- Dataflow Worker if you're using custom service accounts instead of the default
Row-level security in BigQuery is handled through row-level access policies, which are straightforward to set up but easy to misconfigure. I once granted a dataset viewer role to a service account and assumed they could only see public tables. They couldn't, because the dataset itself was private and the viewer role didn't override that. The fix was adding the BigQuery Data Viewer role at the dataset level explicitly. Cloud Monitoring works with GCP services out of the box. Dataflow jobs expose metrics you can visualize, BigQuery queries show slot utilization and bytes processed, and Pub/Sub topics report publish and pull rates. The problem is that most of this monitoring is passive. You get charts and you get alerts, but you don't get automatic recovery when something breaks. I built a simple error handling pattern using Cloud Logging and Cloud Workflows. When a Dataflow job fails, the error log entry contains the job ID, the failed stage, and the exception message. A Workflows orchestration picks up that log entry, retries the job with adjusted parameters if it's a transient error, or sends a Slack notification with the full stack trace if it's a schema mismatch. This cut my on-call response time from about twenty minutes to roughly two minutes for the common failure modes.
One thing that caught me off guard: BigQuery has a per-query slot limit that defaults to 500 slots in most projects. If your complex joins or aggregations exceed that, the query fails with a resource exceeded error. The fix is either to simplify the query, split it into smaller steps, or request a slot limit increase through the Google Cloud console. I've had to request increases up to 2000 slots for our largest ETL jobs during monthly close periods.
Alternatives worth considering
Not every data engineering problem belongs on GCP. If your team is already deep in the AWS ecosystem, moving to GCP just for data engineering creates unnecessary context switching. Similarly, if you need tight integration with Kafka and your organization already runs Confluent Cloud, that might be a better fit than Pub/Sub depending on your latency requirements and operational expertise. For smaller teams without dedicated data engineering staff, look at Managed Service for Apache Spark on Dataproc. It removes a lot of the operational overhead of managing your own cluster, and the pricing is more predictable than raw Compute Engine instances. The tradeoff is that you have less control over node configuration and autoscaling behavior compared to running Spark on your own VMs. The biggest mistake I see people make is trying to replicate on-premise architectures on GCP without adjusting for the cloud-native constraints. Hadoop-style distributed processing doesn't map cleanly to BigQuery's columnar model. Spark on Dataproc is closer to a direct replacement, but even then, the cost profile is different enough that you need to rethink your partitioning strategy and data layout. Data Engineering On Google Cloud Platform works best when you design around what GCP does well rather than forcing your existing patterns into it.
