What the Data Science Cheat Sheet Monthly Actually Is
It is a recurring collection of compact reference tables and quick-referenced code snippets covering statistics, machine learning algorithms, Python libraries, and data engineering fundamentals. The format changes slightly from issue to issue, but the core idea stays the same: give someone in the middle of an implementation a fast way to find the right function name, the default hyperparameters, or the mathematical form of a model they need to write out from scratch. I have been downloading these since the first issues circulated in 2019. They arrived as PDFs, then later as Notion pages and GitHub repos. The content itself has not really changed much. What changed is how people try to use them, and how often they fail because the sheet does not match the version of the library they are actually running.
Data Science Cheat Sheet Monthly
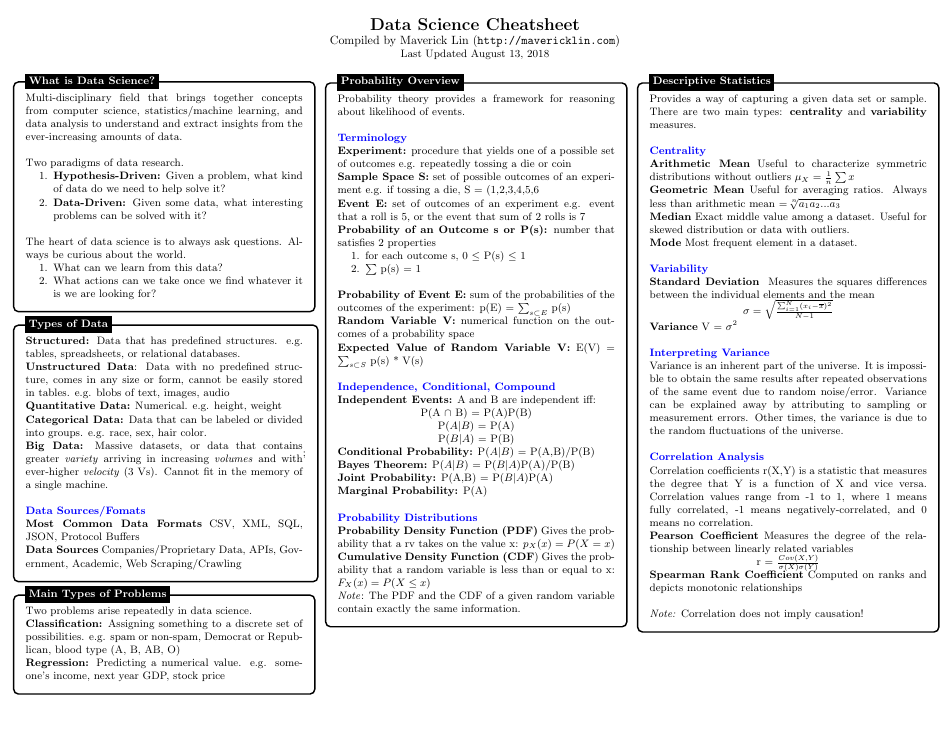
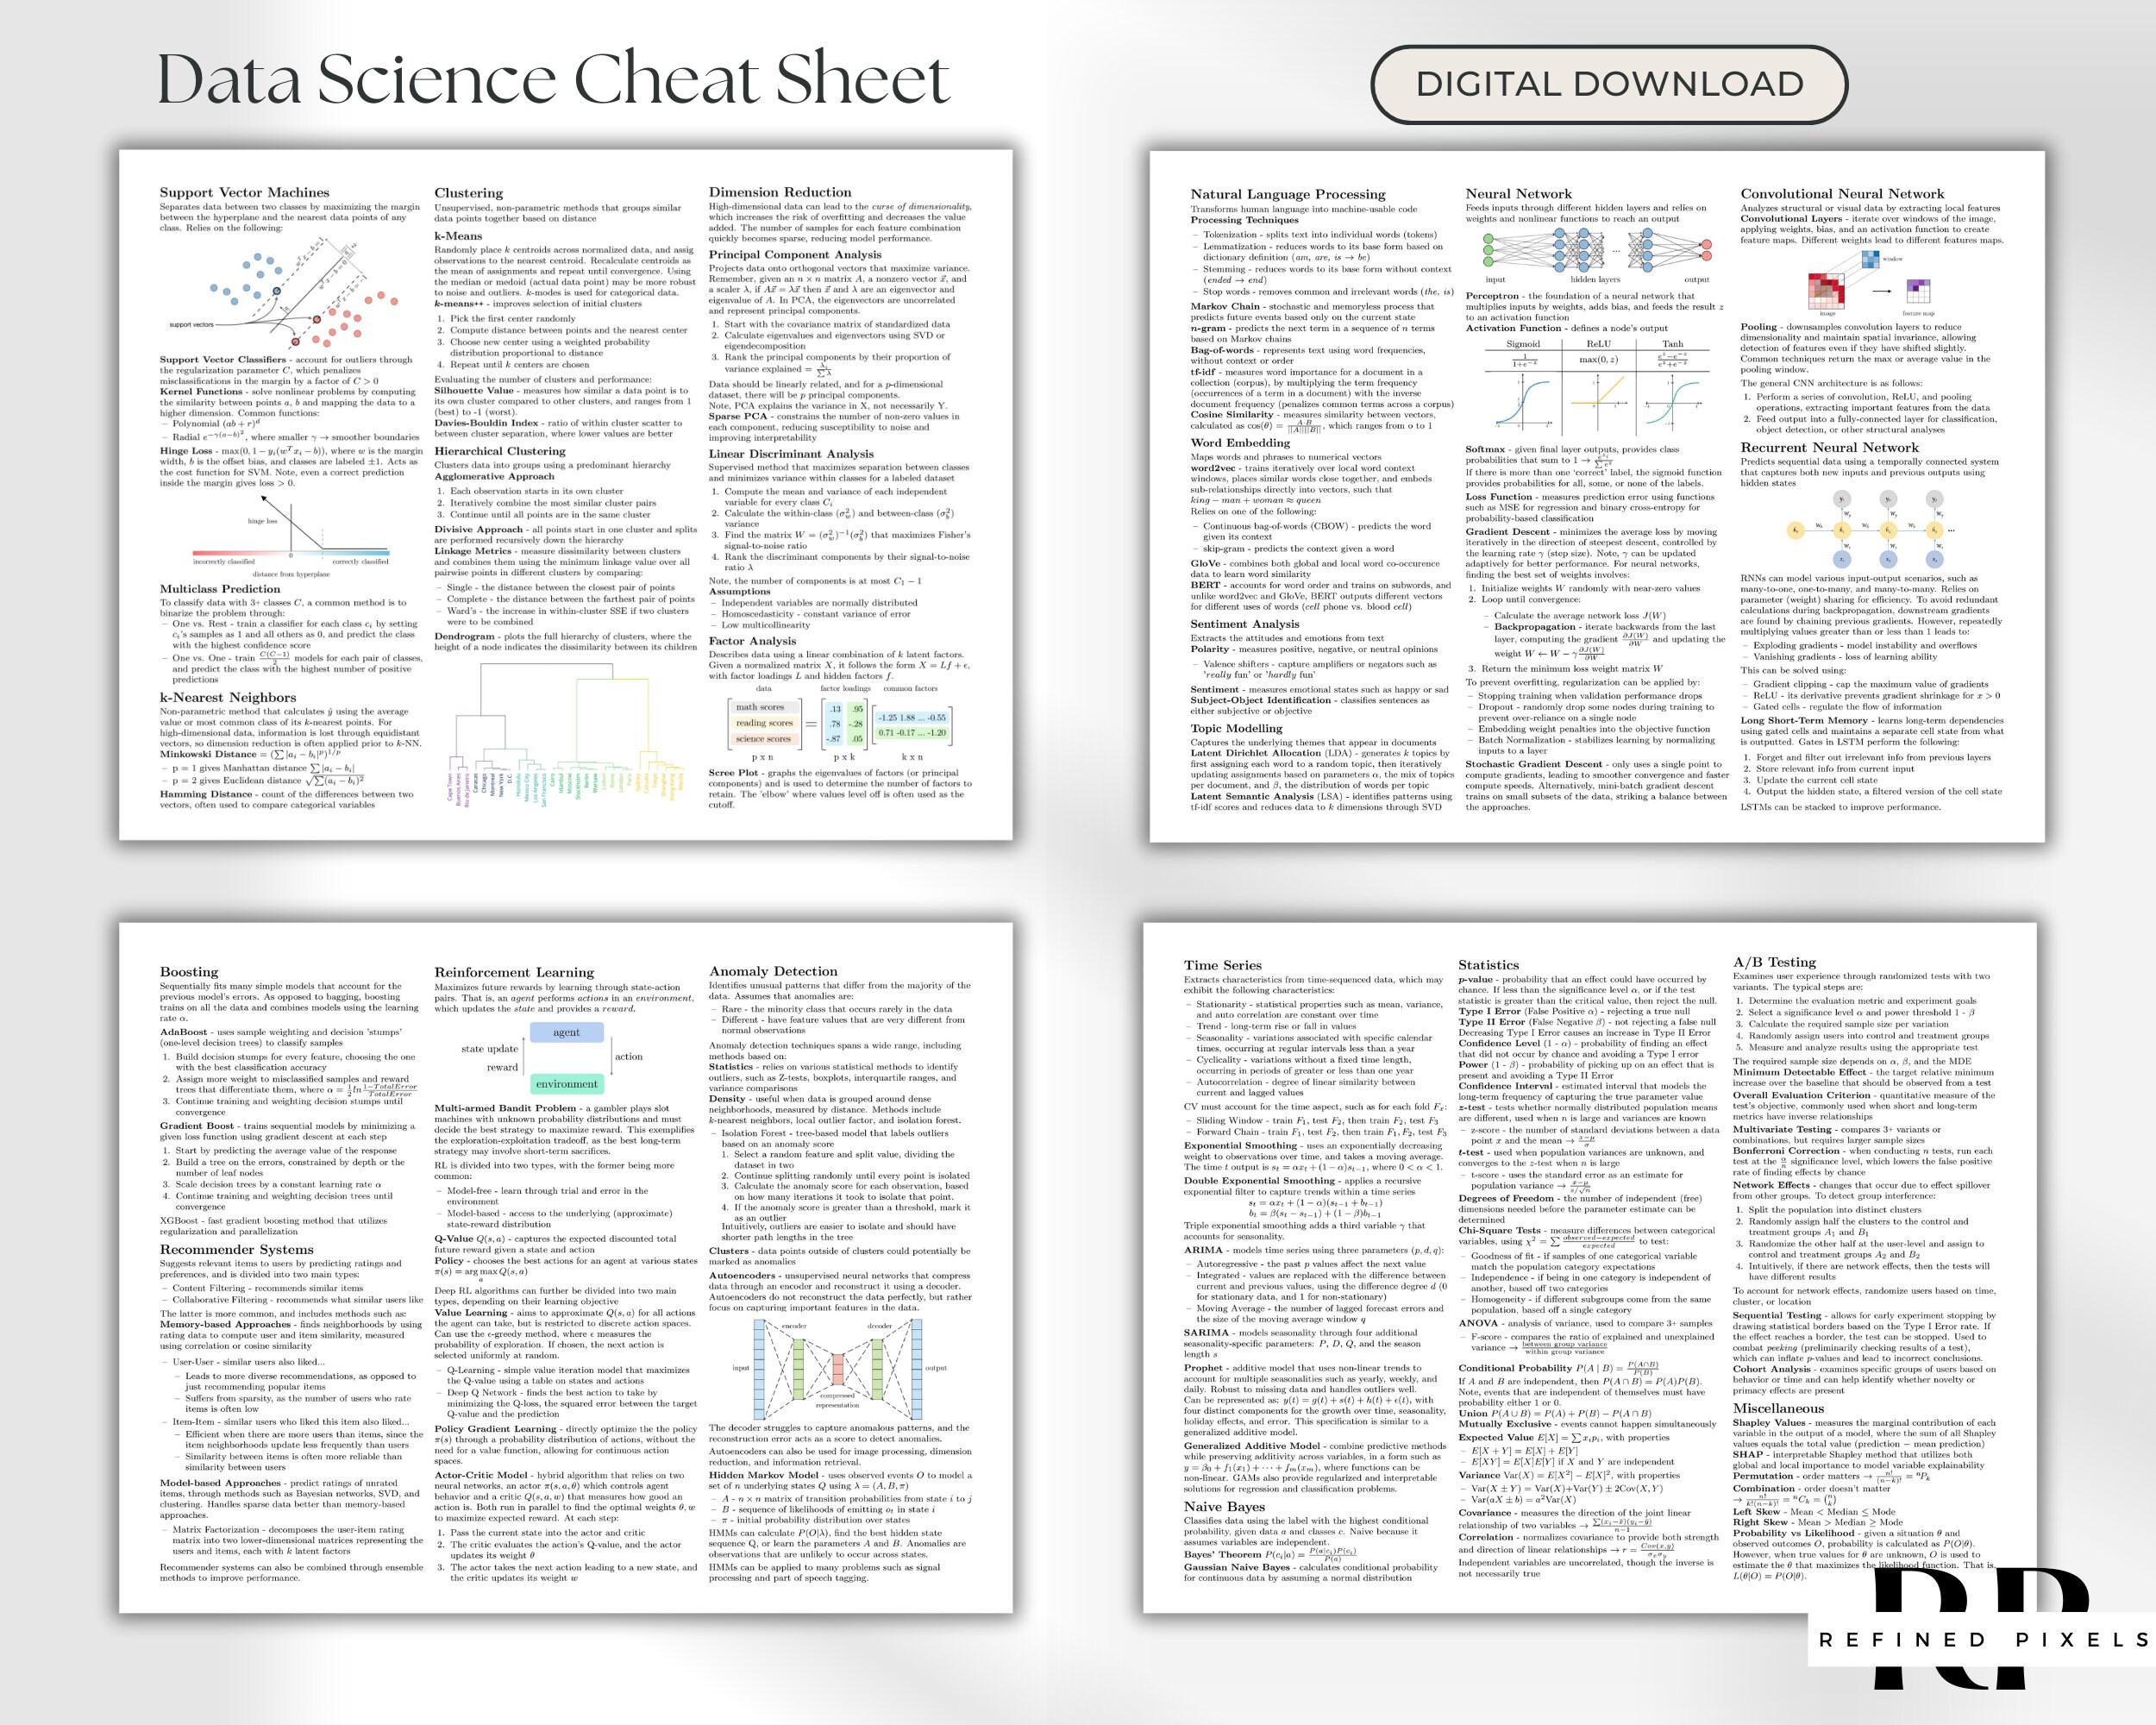
The current version organizes content into roughly eight sections: probability and distributions, hypothesis testing, data preprocessing pipelines, scikit-learn estimator signatures, model evaluation metrics, common SQL patterns for data transformation, Pandas idiom translations between versions, and a growing section on transformer architectures and their token-level behavior. Each section is dense. Some pages run into single-column reference blocks that look clean until you actually open them on a laptop screen. Here is how I use it during a real workflow. I typically open the relevant section while debugging a pipeline. I do not read it cover to cover. I go straight to the code snippet block for the function I am calling, check the default parameter list against what my environment returns, and move on. That part saves me maybe ten minutes per session. Over a week, that adds up. But the real value is in the cross-section moments where two sections overlap. For example, I was recently working on a survival analysis model using scikit-learn's proportional hazards extension alongside a custom Cox partial likelihood function. The cheat sheet had the estimator signature on one page and the math notation for the partial likelihood on another. Looking at both side by side let me catch a mismatch in how the dataset's time columns were being interpreted. My workaround was simple: I added a single Pandas dtype assertion before fitting, because the sheet does not warn you that the underlying library silently converts string dates to integers in some versions. I wrote that assertion down in my own personal notes. That has become more useful than the sheet itself.
How to Read It Without Wasting Time
Most people treat these sheets like textbooks. They should not. The content assumes you already know what you are looking for. If you are reading from page one to the end, you are using the wrong tool. The sections are arranged roughly by task difficulty, but the order does not matter. Start with the section that matches your immediate problem. If you are normalizing features, jump to the preprocessing block. If you are deciding between a random forest and a gradient boosting implementation, go straight to the model comparison table. The tables usually list the default parameters, the typical training time range for medium datasets, and the known failure modes. That last part is what most beginners skip. One thing the sheets handle well is the mapping between mathematical notation and library function calls. A formula for regularized logistic regression on one page, the corresponding LogisticRegression class call on the next. The parameter names match, mostly. The defaults sometimes do not. The sheet lists the defaults as of the release it was published under. Scikit-learn changed the regularization penalty default from L2 to L1 in a recent minor release. The sheet was not updated. If you copy the default value without checking your installed version, your model will behave differently than the example suggests. Always run a version check. Two lines of code. Takes about twelve seconds.
Get the Full Details

Another area where the sheets are genuinely useful is the SQL transformations section. I have used it to replace hours of trial-and-error when writing window functions for cohort retention queries. The cheat sheet lists the standard patterns for ROW_NUMBER, RANK, and DENSE_RANK with their behavior across PostgreSQL, BigQuery, and Snowflake. The differences matter because the output varies subtly when there are ties. I learned that the hard way during a client migration project where the query worked perfectly in PostgreSQL and failed silently in BigQuery due to a partitioning difference. The sheet flagged that difference, but only if you looked at the footnote section, which most people do not read because footnotes are small.
Where It Falls Apart
The sheets are not designed for beginners. They assume familiarity with the core concepts. If you are learning what a p-value is, the reference tables will not help you. The definitions are abbreviated, sometimes overly terse. A single line might summarize the entire derivation of the EM algorithm without any intuition about why it converges or when it does not. The library-specific sections also age quickly. A cheat sheet printed in early 2024 may reference functions that were deprecated by late 2024. The team behind the publication has been trying to shift to a living document model, but the download links still often point to static PDFs. If you download a sheet and plan to use it for production work, verify the dates on the code examples. Compare them against the changelog of the library version you are running. This usually takes about five minutes per section and prevents a lot of downstream debugging. There is also the issue of scope. The sheets cover the most common cases. They do not cover edge cases like imbalanced datasets with extreme class ratios, or multilingual text classification with very low-resource languages. If your problem falls outside the standard categories, the sheet will not save you. You will still need to read the source code, check the issue tracker, and experiment. The sheet is a starting point, not a solution.
A Practical Workflow I Use
I keep the latest PDF bookmarked in my browser. I open it in a split-screen view alongside my IDE. When I hit a wall, I search the PDF for the keyword. I read the relevant section, not the whole document. If the sheet references a function I have never seen, I open the official documentation in a new tab and compare the parameter list. This takes about three minutes. It prevents me from trusting outdated defaults. I also keep a separate note file where I record mismatches I find. Things like "this sheet lists XGBClassifier with max_depth=6 as default but my version uses 3," or "the Pandas merge documentation here uses how='inner' but the library now defaults to outer in certain contexts." That personal note file has grown to about forty entries over two years. It is more accurate than any static sheet because it reflects the environment I actually work in. If you want to start using these sheets effectively, pick one problem you are currently facing. Open the corresponding section. Verify the library versions. Write down any discrepancies. Then proceed. The sheet will get you further than trying to memorize everything. It will not get you all the way there.