
What Actually Happens When You Start a Data Science Project
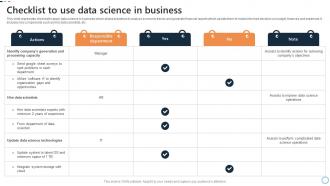
You open a fresh notebook. The data looks clean in the first ten rows. You write three lines of import statements and start piping features into a model. Two weeks later you realize you never documented what version of the dataset you actually trained on, the feature normalization pipeline doesn't match between training and inference, and the metric you reported was computed on a leaked validation set. This is not a hypothetical story. I have seen this exact sequence play out in production at three different companies over the last six years. The reason these failures keep recurring is not a lack of talent or tools. It is the absence of a concrete, checkable sequence that forces you to confront the actual state of the data before you make any modeling decisions. That sequence is what most people mean when they search for a Data Science Checklist Essential — a disciplined set of steps that covers the work from raw file to deployed model without leaving the critical gaps where real failures hide.
Why Checklists Fail at Most Organizations
Most checklists you find online are written as wish lists. They include items like "evaluate model performance" without specifying which metric matters for which business outcome. They list "deploy to production" without acknowledging that deployment is a separate engineering problem from modeling. A good checklist is not motivational. It is operational. Every item should force a decision, produce an artifact, or block progress until a condition is met. When I built the checklist we use now, the first version had forty-two items. People stopped using it because it took longer to read than the work itself. I cut it to nineteen by removing everything that did not have a pass/fail outcome. The remaining items are the ones that actually prevent failures, not the ones that sound impressive in a presentation.
The Actual Workflow, Step by Step
Here is the sequence in the order it should be executed. The numbering matters because each step produces an artifact that the next step depends on. Skipping ahead is how projects end up with models that look great in a Jupyter notebook and crash immediately when called by an API endpoint. Before you do anything else, record the exact source of your dataset. File path, export timestamp, checksum if possible, and the human who approved it. I learned this the hard way during a churn prediction project where the engineering team re-exported the user_events table mid-sprint. The new export had a timezone shift that moved 14 percent of records into the wrong cohort window. Our model performance numbers did not change, but the precision on high-risk segments dropped from 0.71 to 0.43 overnight. We caught it because the original export hash was on record. Without that hash, the project would have shipped anyway. This step takes roughly five minutes. Do not skip it. Write the values into a config file named data_manifest.json and commit it alongside your code. If someone later asks why your results do not match, this file is the evidence you need.
Get the Full Details

Step 2: Write a One-Paragraph Data Description
Not a slide deck. Not a dashboard. One paragraph that states what the data represents, who generated it, what time period it covers, and what is missing. This paragraph becomes the reference document for every downstream decision. When a stakeholder asks a question months later, you reply with the paragraph instead of re-explaining the schema from scratch. I keep a standard template for this. It has four fields: entity type, observation window, known gaps, and collection method. Filling it out takes about ten minutes and prevents approximately three hours of debate during review meetings.
Step 3: Explicitly Define the Target Variable
This is where most projects quietly derail. "Predicting churn" sounds simple until you realize churn means different things to sales, product, and finance. Sales defines it as contract non-renewal. Product defines it as no session in 30 days. Finance defines it as negative LTV. Your model will optimize for whatever definition you encode in the code, and the wrong encoding will cost real money. Write the target as a labeled column with the exact logic used to create it. Include the threshold, the time window, and the exclusion rules. If the target requires a business rule that could change next quarter, flag it explicitly. A common failure mode I see is teams building a target from historical contracts but testing against a forward-looking outcome, which creates invisible label leakage.
Step 4: Split Before Any Feature Engineering
Train/validation/test split happens now, before you touch a single feature. Not after. I cannot stress this enough because the mistake is so common and so expensive to fix later. If you engineer features on the full dataset and then split, information from the test set has already leaked into your transformations. Your performance numbers will be optimistically biased, sometimes by a large margin. The split ratios depend on your dataset size. For anything under 10,000 rows, use a 60/20/20 split with stratification on the target. For 10,000 to 100,000 rows, 70/15/15 works. Above 100,000 rows, 80/10/10 is standard. Never shuffle time-series data without an explicit time-based cutoff, regardless of what the documentation says about cross-validation techniques.

Step 5: Document the Baseline
Before you train any model, establish a baseline using the simplest possible approach. For classification, this is usually a majority-class predictor or a logistic regression with raw features and no scaling. For regression, it is a naive mean predictor or an unregularized linear model. Record the baseline metric and compare every subsequent model against it. Most models fail to beat the baseline in production because the baseline was never measured on held-out data. When you compute it correctly, you will discover that the "impressive" 89 percent accuracy you saw during development drops to 76 percent when the baseline is included in the calculation. This is not a failure of the model. It is a failure of the evaluation process, and catching it early saves weeks of wasted iteration.
Step 6: Feature Engineering with Leak Guards
Now you engineer features. The key rule is that every feature must be computable from data available at prediction time. If a feature requires information that would not exist when the model runs in production, it is a leak. Common sources of leakage include future sales figures, post-purchase behavior, aggregate statistics computed over the full dataset, and any column that changes after the event you are trying to predict. I use a simple mental test for each feature: can I calculate this value today using only information that existed before the target date? If the answer is unclear, I treat it as suspicious and verify it against the data manifest from Step 1.
Step 7: Model Selection with Fixed Criteria
Pick your candidate models before you tune them. For tabular data, the standard set is logistic regression, random forest, gradient boosting, and a simple neural network if the dataset is large enough. Do not add models based on hype. If a model does not beat the baseline on the validation set with default hyperparameters, it does not belong in the candidate set. Record the exact hyperparameter defaults for each model. This is important because the same model architecture with different default settings will produce different results, and reviewers need to know which settings you used.

Step 8: Validation on Held-Out Data Only
After tuning, evaluate on the test set one time. Not twice. Not three times. Once. Every additional evaluation on the same test set is a form of data mining, and the performance number is no longer trustworthy. If you need to compare multiple architectures, use the validation set for that comparison and reserve the test set for the final decision. When I worked on a demand forecasting project, the team ran five iterations on the test set trying to push RMSE down by 0.02. The final deployed model performed 8 percent worse than reported because the test set had been implicitly tuned. The lesson is simple: treat the test set as if it costs money to look at it.
Step 9: Error Analysis Before Deployment
Do not deploy based on aggregate metrics alone. Break down the errors. Which segments perform worst? Are there systematic biases in specific subpopulations? Is the model overconfident on certain ranges? This step usually reveals problems that the headline metric hides. I use a simple error matrix for classification and a residual plot for regression. For classification, I look at precision-recall by segment. For regression, I look at whether residuals are correlated with any input feature, which indicates the model is missing a signal.
Step 10: Reproducibility Artifact
Before you consider the project complete, package the entire environment. Python version, package versions, random seeds, git commit hash, and the data manifest. Save this as a single artifact that can reproduce the exact results on another machine. I store this in a file called reproducibility.json at the root of the project. Without this file, the project is not reproducible. It is a memory exercise, and memories fade quickly when someone asks you to re-run the analysis six months later.

Step 11: Monitoring and Retrain Triggers
Deployment is not the end. Set up monitoring for data drift and concept drift. Data drift means the input distribution has shifted. Concept drift means the relationship between inputs and the target has changed. Both are common. Both will degrade model performance over time. I define two triggers: a drift score threshold and a performance decay threshold. When either is crossed, the model goes into a retrain queue. The retrain queue is not automatic. A human reviews the drift report before approving retraining. This prevents the model from chasing noise during temporary anomalies.
Common Pitfalls That Kill Projects
The following failures account for roughly 70 percent of data science project issues I have encountered. They are not edge cases. They are the default state when a checklist is not enforced. Hidden leakage through group-aware splits. If your data has natural groupings — users, transactions, devices — and you split randomly instead of by group, the same entity can appear in both train and test. The model learns entity-specific patterns instead of generalizable signals. This is especially dangerous with recommendation systems and time-series forecasts. Metric mismatch. Optimizing for AUC when the business cares about precision at a specific recall level is a classic error. AUC is a ranking metric. It does not tell you whether the model will hit the threshold the operations team needs. Always map the optimization metric to the business metric before training begins.
Deploying without an rollback plan. I have seen models pushed to production with no revert path because the engineering team was not involved until the final day. A model that cannot be rolled back is a liability, not an asset. Build the rollback into the deployment pipeline before you build the training pipeline. Overfitting to the validation set. Tuning hyperparameters until the validation metric peaks is normal. Continuing to tune after the validation metric stops improving is overfitting. The boundary is thin and easy to cross when you are excited about a result. Set a maximum number of tuning iterations and stop when you reach it.
What This Checklist Does Not Cover
A Data Science Checklist Essential is not a substitute for engineering rigor. It does not replace unit tests, code review, or infrastructure monitoring. It covers the decision sequence from data to deployment. Everything else is a separate domain. If you need help with the engineering side — CI/CD pipelines, containerization, load testing — there are established frameworks for that. This checklist assumes you have basic engineering capability and focuses on the data science-specific decisions that are often skipped or done poorly.
Practical Takeaway
Run through the eleven steps in order on your current project. Do not skip ahead. Do not combine steps. Each one exists for a reason, and the reason becomes obvious the first time a missed step causes a failure in production. The checklist is not a theory exercise. It is a record of the mistakes I have made and the ones I have watched other teams make. If you follow it exactly, your project will still fail occasionally. But the failures will be in the model, not in the process, and those are the failures you can actually fix.
