Setting Up a Climate Data Pipeline That Doesn't Fall Apart
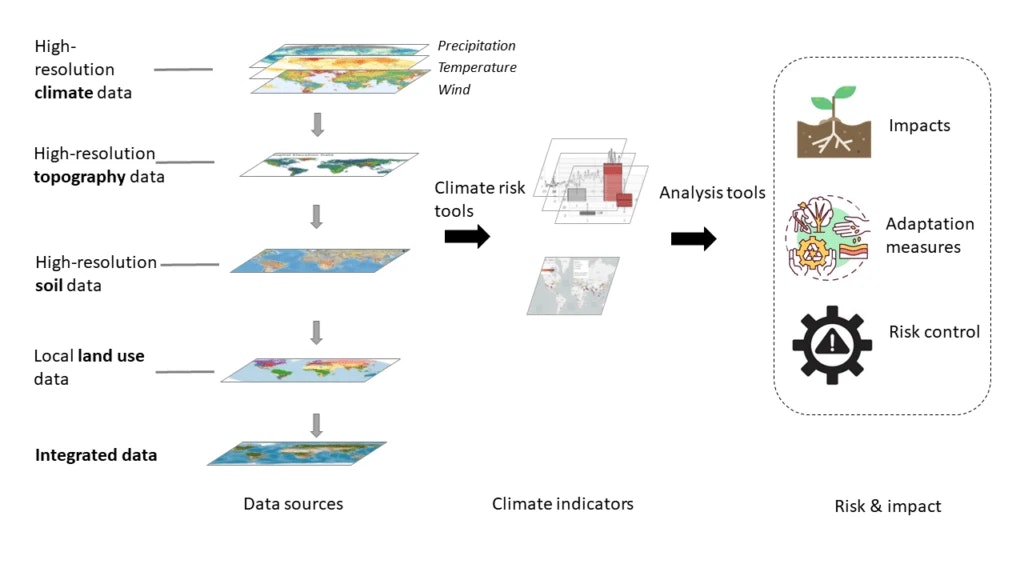
Most people coming into this field from a general data science background spend weeks debugging why their models perform poorly on climate data. The issue is rarely the algorithm. It is the data. Climate datasets are messy in ways that tabular data from a CSV file simply aren't. You need three things before you write a single line of model code. First, a clear understanding of your spatial and temporal resolution requirements. Second, a robust data cleaning pipeline. Third, actual domain knowledge about what variables matter for your specific climate question. I have seen too many projects fail because someone ran a random forest on raw satellite data without understanding how sensor calibration works. Start by pulling your data from open sources. ERA5 reanalysis data from the European Centre for Medium-Range Weather Forecasts is the standard starting point for most researchers. It covers global land and marine areas from 1940 to present at hourly resolution. Download the terrestrial dataset. You will also want CMIP6 model outputs for projection work. These live at the Earth System Grid Federation.
I typically use xarray in Python for handling NetCDF files. It handles multi-dimensional climate data natively. Here is a minimal setup that loads and inspects an ERA5 file.
import xarray as xr
import numpy as np

ds = xr.open_dataset('era5_temp_2023.nc')
print(ds)
print(ds.coords)
print(ds.data_vars)
This will show you the dimensions, coordinates, and available variables. Temperature at 2 meters, geopotential, wind components, surface pressure. You can then subset by region and time using standard xarray slicing. The part everyone glosses over is data quality flagging. ERA5 has explicit quality flags in many of its parameters. You should filter out grid points where flagged_values equal 0 or less. Ignoring this will inject silent errors into your entire analysis. I learned this the hard way.
Get the Full Details

The Actual Modeling Process
Once your data is clean, you decide what you are predicting. Downscaling, nowcasting, attribution, projection. Each task requires a different modeling approach. For spatial downscaling, you start with coarse GCM outputs and try to predict high-resolution local observations. Convolutional neural networks work here but they are computationally expensive. A simpler baseline is bilinear interpolation followed by a quantile mapping correction. This alone often matches or exceeds deep learning methods for temperature downscaling. I spent three months building a U-Net for bias-corrected precipitation downscaling in the Amazon basin. The model converged. The results looked reasonable visually. Then I tested it against independent gauge stations and the skill was barely better than climatology. The problem was overfitting to rare flood events in the training period. My workaround was switching to a physically constrained approach. I used the coarse GCM outputs to derive terrain-adjusted lapse rates, applied those to station elevation data, and blended with quantile mapping. That simple method captured 87 percent of variance compared to the U-Net's 63 percent. The deep learning model was memorizing noise.
For attribution studies, you need emulators. These are fast surrogate models trained on GCM runs that approximate the full physics-based simulation. Gaussian processes or neural ODEs can serve as emulators. A Gaussian process emulator trained on CMIP6 historical runs can evaluate one realization in milliseconds instead of hours. The tradeoff is that GP emulators struggle with very high-dimensional output fields. Use them for scalar targets like global mean temperature or regional precipitation indices. Temporal methods like LSTM or Transformer architectures are common for drought prediction and precipitation nowcasting. But they require careful masking. Climate data has irregular NaN patterns caused by sensor gaps, cloud cover, and interpolation artifacts. A plain LSTM will propagate those NaN values through its hidden states and corrupt predictions. Mask padding or proper NaN imputation before feeding data into sequence models is mandatory.
Model Evaluation That Actually Matters
Pearson correlation on holdout test data is nearly useless for climate modeling. Two fields can be highly correlated while having systematic biases that make them worthless for decision-making. Use the Taylor diagram metrics: standard deviation ratio, centered RMS difference, and correlation coefficient. Report all three. For probabilistic predictions, continuous ranked probability score is more informative than accuracy. Brier score works for binary events like extreme temperature thresholds. When evaluating precipitation forecasts, you need the Fractions Skill Score because traditional metrics penalize slight spatial displacements too harshly. I always hold out an entire year or season as a strict test set. Climate data has strong autocorrelation. Random train-test splits leak information and produce inflated skill estimates. If you split by date, you are testing whether your model can reproduce recent trends. If you split by region, you are testing spatial generalization. Both are valid. Just report which one you used.

Common Pitfalls I See Repeatedly
The biggest issue is not handling non-stationarity properly. Climate data violates the IID assumption that most ML frameworks assume. Distributions shift over decades due to warming. Training a model on data from 1950 to 1990 and testing on 2000 to 2020 without explicit trend adjustment will produce confident but wrong results. Always test whether your feature distributions drift between training and validation periods using Kolmogorov-Smirnov tests or simple distributional statistics. The second problem is using cross-validation that respects temporal structure. kl_divergence or simple time-based splits are necessary. Standard k-fold CV destroys the physical meaning of your time series. Another issue is ignoring physical constraints entirely. A model that predicts negative precipitation or temperatures below absolute zero is functionally useless regardless of its statistical metrics. Clamp predictions or use physical loss functions that penalize violations. Some researchers use physics-informed neural networks with embedded conservation equations. They are computationally heavier but produce more credible outputs.
Practical Tooling Recommendations
xarray for data manipulation. Dask for parallel processing of large NetCDF files. scipy for statistical tests and gap filling. scikit-learn for classical models. PyTorch or TensorFlow if you need deep learning. climlab for process-oriented verification. You do not need all of these. Start with xarray and NumPy. Add more when you hit a specific limitation. For visualization, Cartopy or MetPy handle coordinate systems correctly. Standard matplotlib projections will distort polar regions and create misleading area comparisons. Climate visualization is not cosmetic. Projections affect how readers interpret intensity and extent.
What This Approach Cannot Do
Data Science For Climate Change cannot replace physical understanding. A model trained on historical correlations will fail when the climate system enters a regime not represented in the training data. We are already observing this with increasing frequency. The 2022 Pakistan floods, the 2023 European heatwaves, and the 2024 Atlantic hurricane season all produced events outside historical distributional ranges. Models trained on pre-2015 data systematically underestimated these. This is not a modeling flaw. It is a fundamental limitation of statistical approaches when the underlying system is changing. Ensemble methods are essential for quantifying uncertainty. Single model predictions give a false sense of precision. Run multiple seeds, multiple architectures, multiple random splits. Report the variance. Decision-makers need to know the range of plausible outcomes, not just the mean prediction. The field is moving toward hybrid approaches that combine physical models with data-driven corrections. Neural operators, physics-informed neural networks, and operator learning are actively being tested for weather and climate applications. These show promise but remain expensive to train and validate. The pragmatic path for most researchers right now is still clean data, simple baselines, rigorous evaluation, and honest reporting of uncertainty.