The Unsexy Truth About Building Pipelines
Pipelines don't really fail at the glamorous part. They fail three days after you ship them because someone changed an API response format on the other end and your whole DAG starts producing empty rows. I learned this the hard way at a previous company. We had a clean extraction transformation load setup running overnight. Then a third-party provider updated their endpoint without documentation. Our pipeline didn't crash. It quietly produced zero records every morning for eleven days. The dashboard showed a red flag eventually, but by then the data team had lost a full quarter's worth of training data for a model we were about to ship. That's the part nobody puts in the tutorials. The pipeline works. Until it doesn't, and it doesn't crash with a visible error.
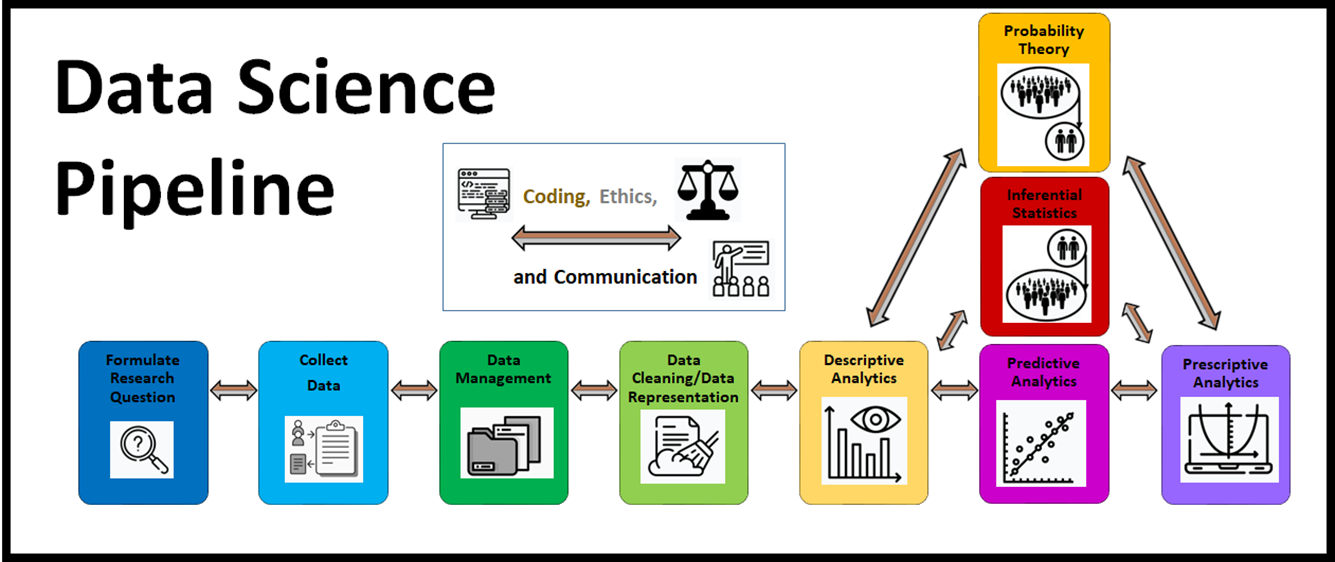
Data Science Pipeline Architecture
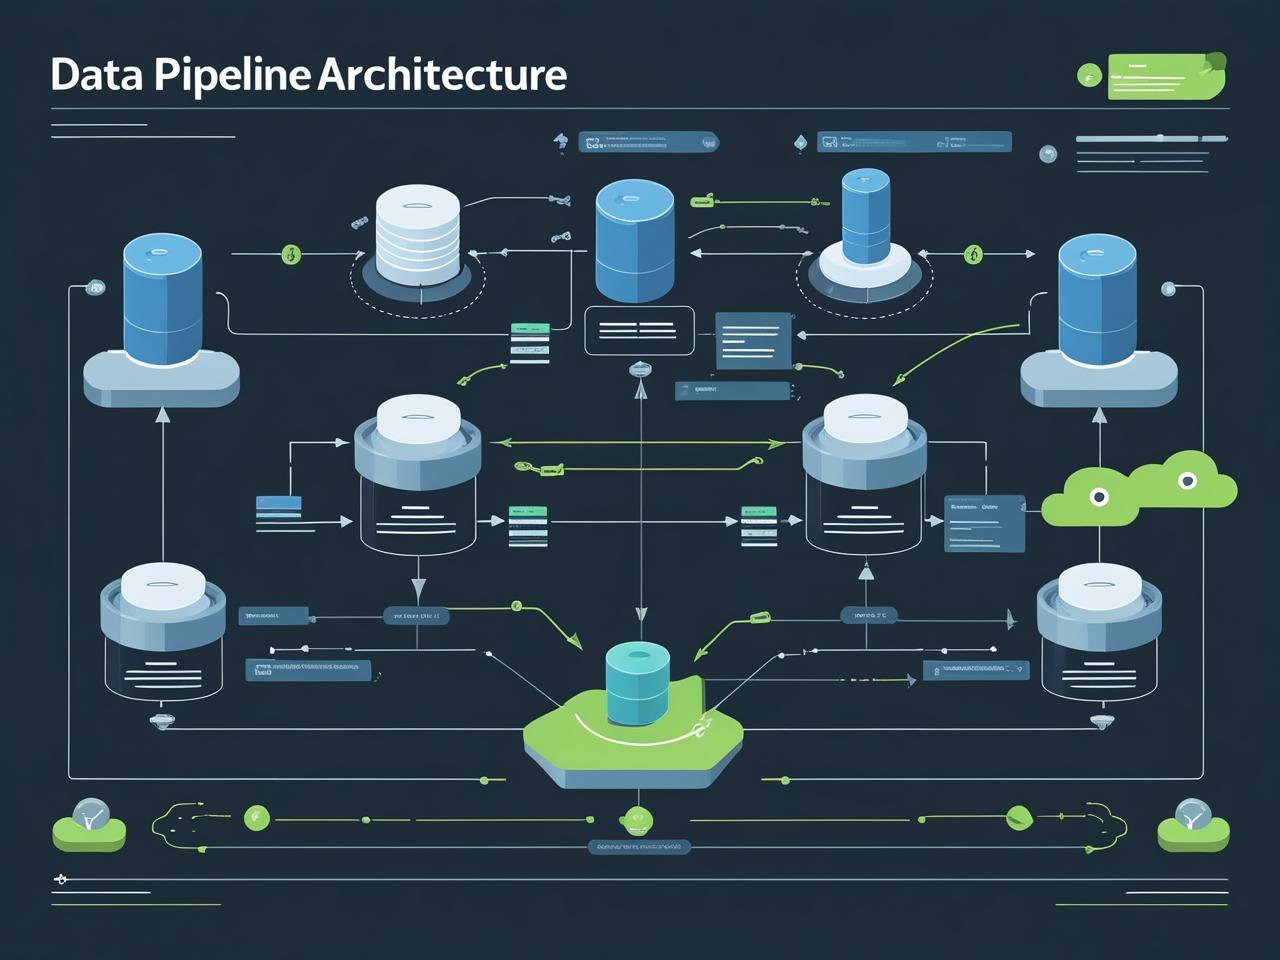
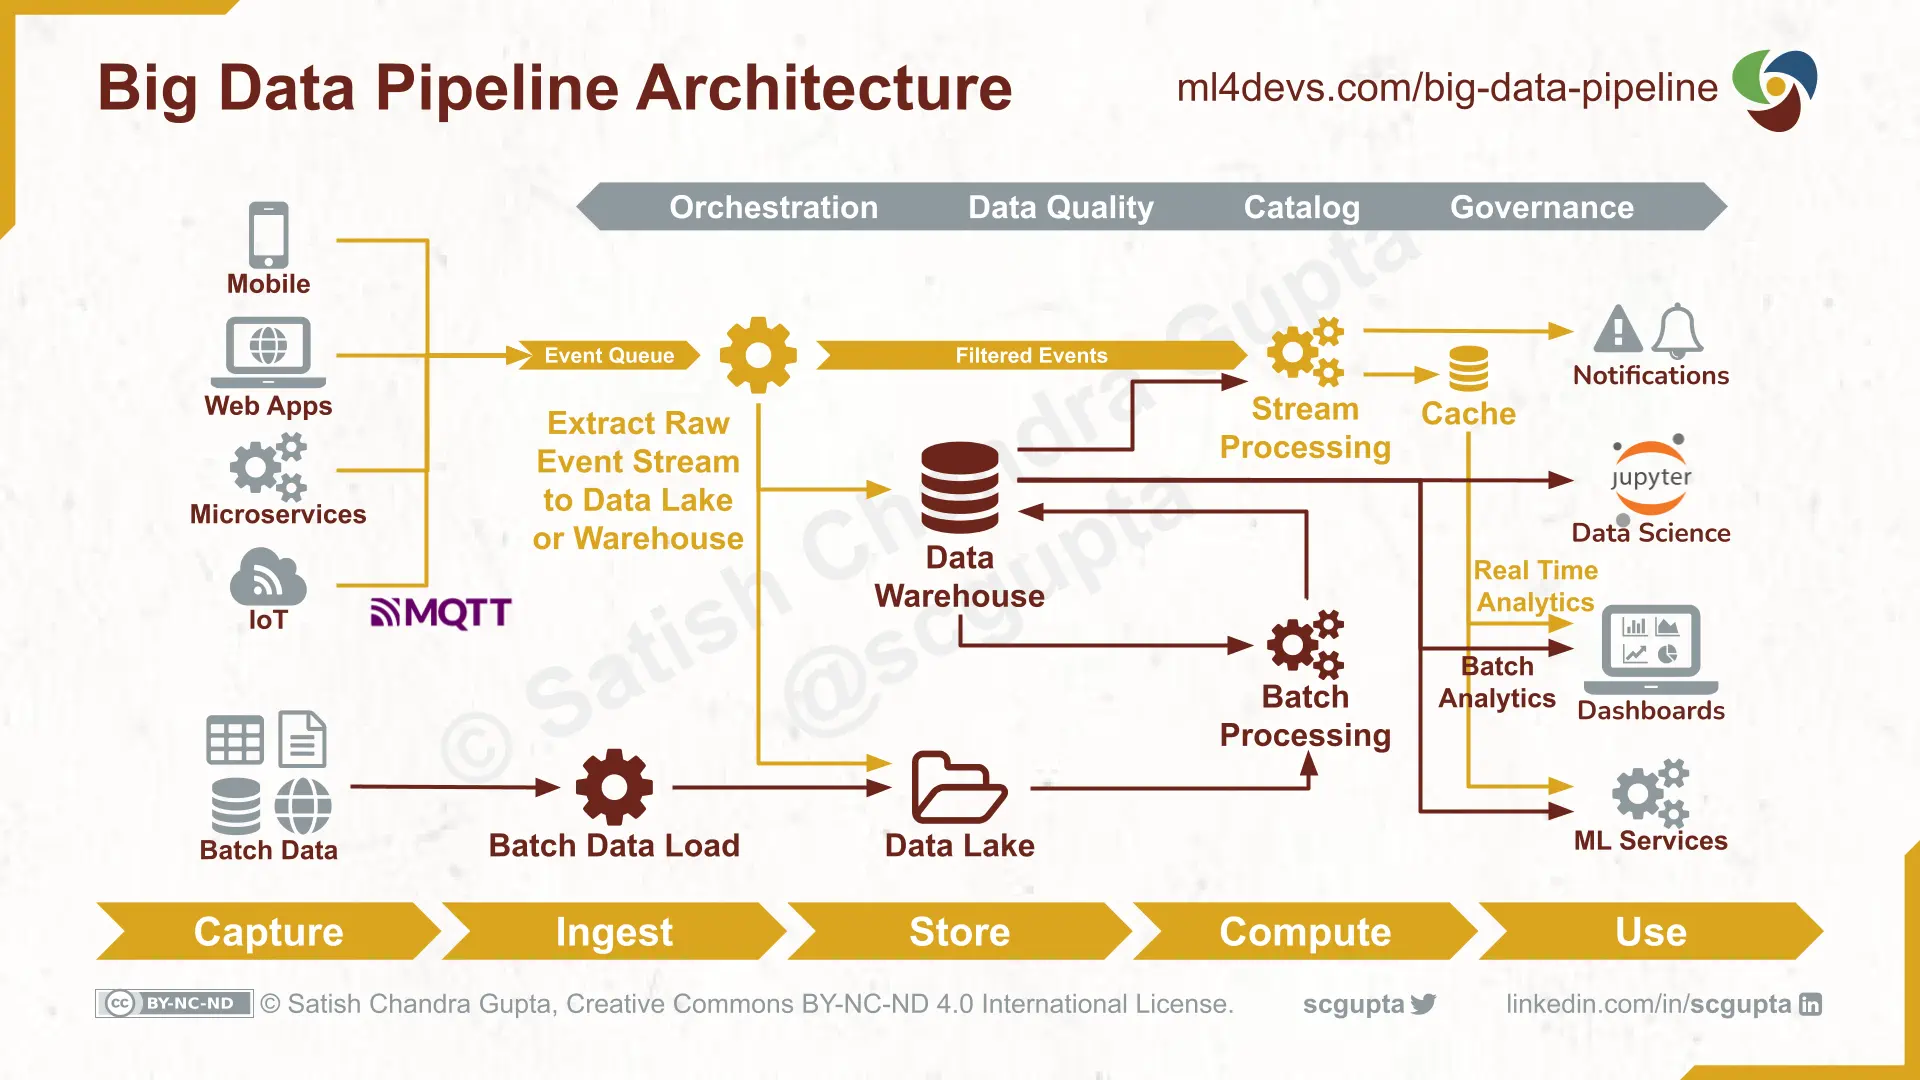
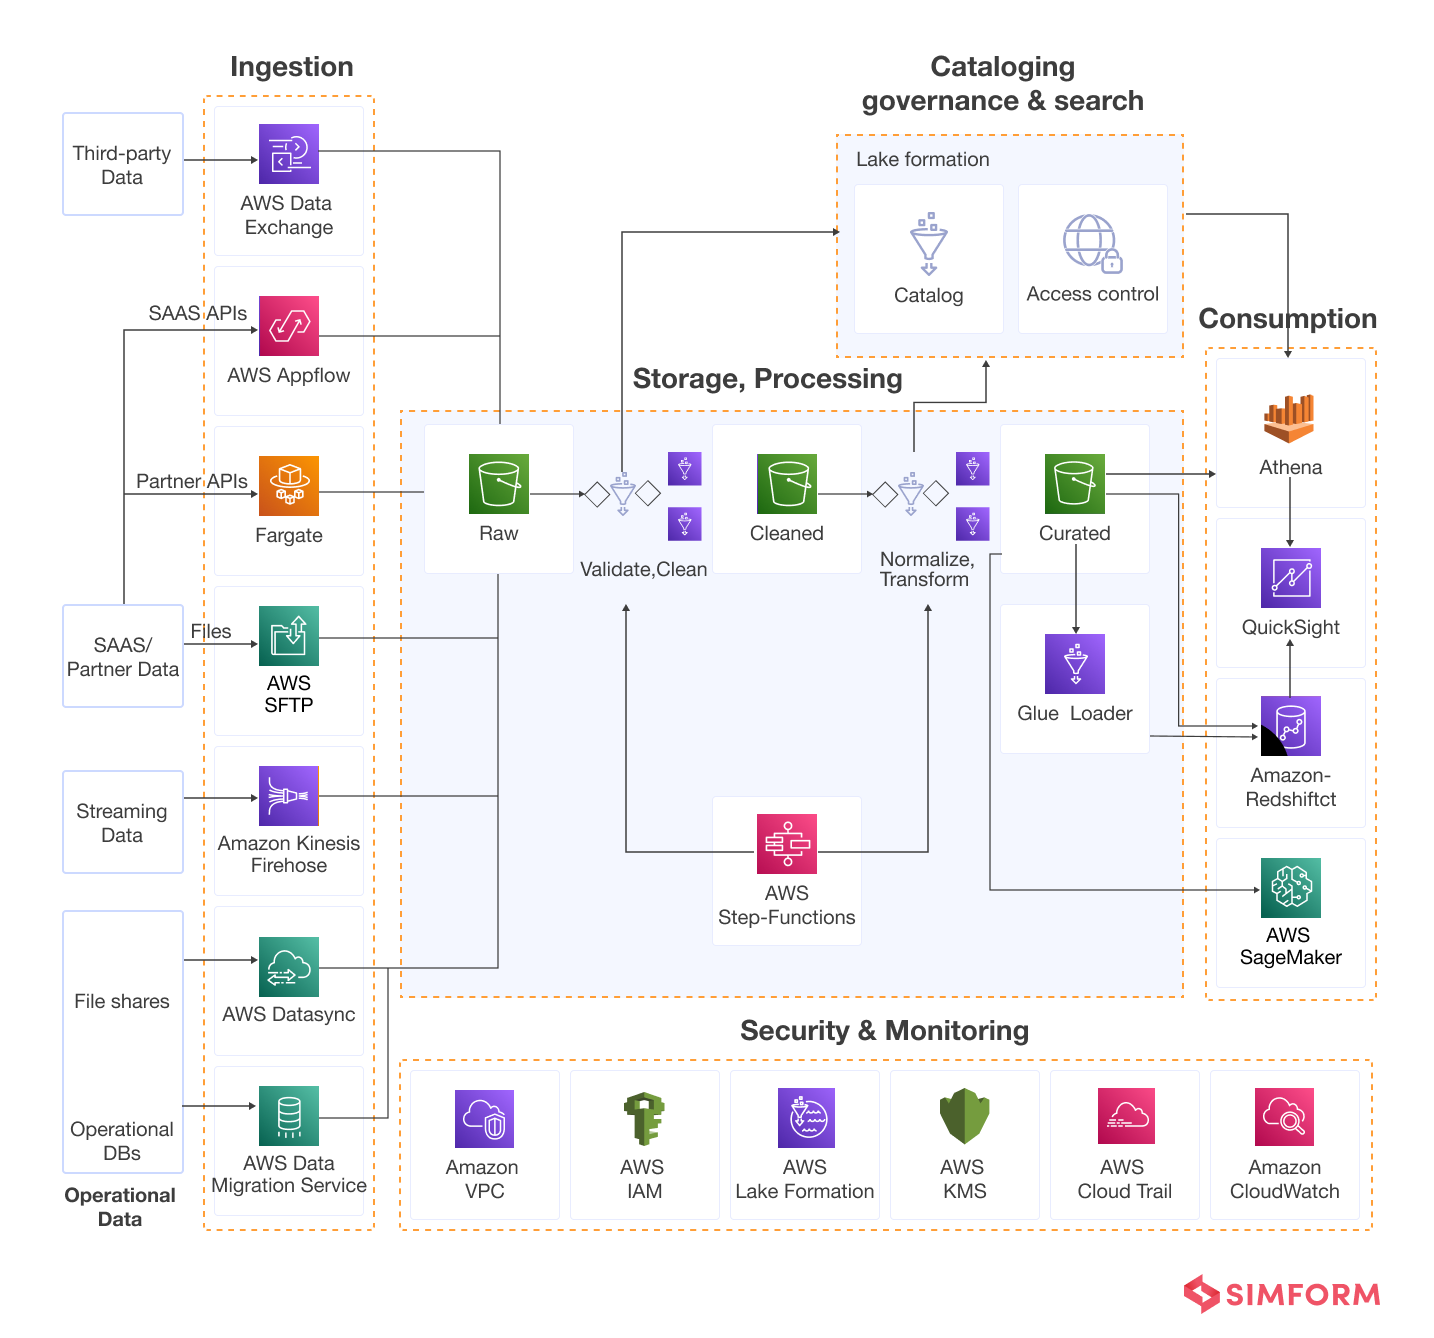
At its core, it's just a sequence of stages where data moves from raw source to something a model or analysis can actually use. The typical breakdown is extraction, transformation, loading, and then usually some kind of monitoring layer on top. But the architecture choices you make between those stages determine whether this thing survives past month two. Most teams start with a simple script that does everything in one go. Pull from the database, clean with pandas, run a model, write the output. That's not a pipeline. That's a prototype. A proper pipeline separates concerns so each stage can fail independently and be retried without restarting everything from scratch.
Orchestration Is Where You'll Lose Sleep
Airflow dominates this space for a reason, but it's not the only option. Dagster and Prefect both handle dependency management better in certain scenarios. The tradeoff is usually readability versus flexibility. Airflow DAGs are verbose but everyone knows how to read them. Dagster feels more like writing Python code and less like describing a workflow in YAML, which matters when you have twelve people touching the same pipeline. Here's what I'd actually recommend based on pipeline size rather than whatever sounds good in a conference talk: For datasets under a few gigabytes and fewer than ten stages, stick with a lightweight orchestrator or even cron with conditional scripts. The overhead of setting up Airflow for something small isn't worth it. You're spending more time debugging the orchestrator than the actual data logic.
Get the Full Details
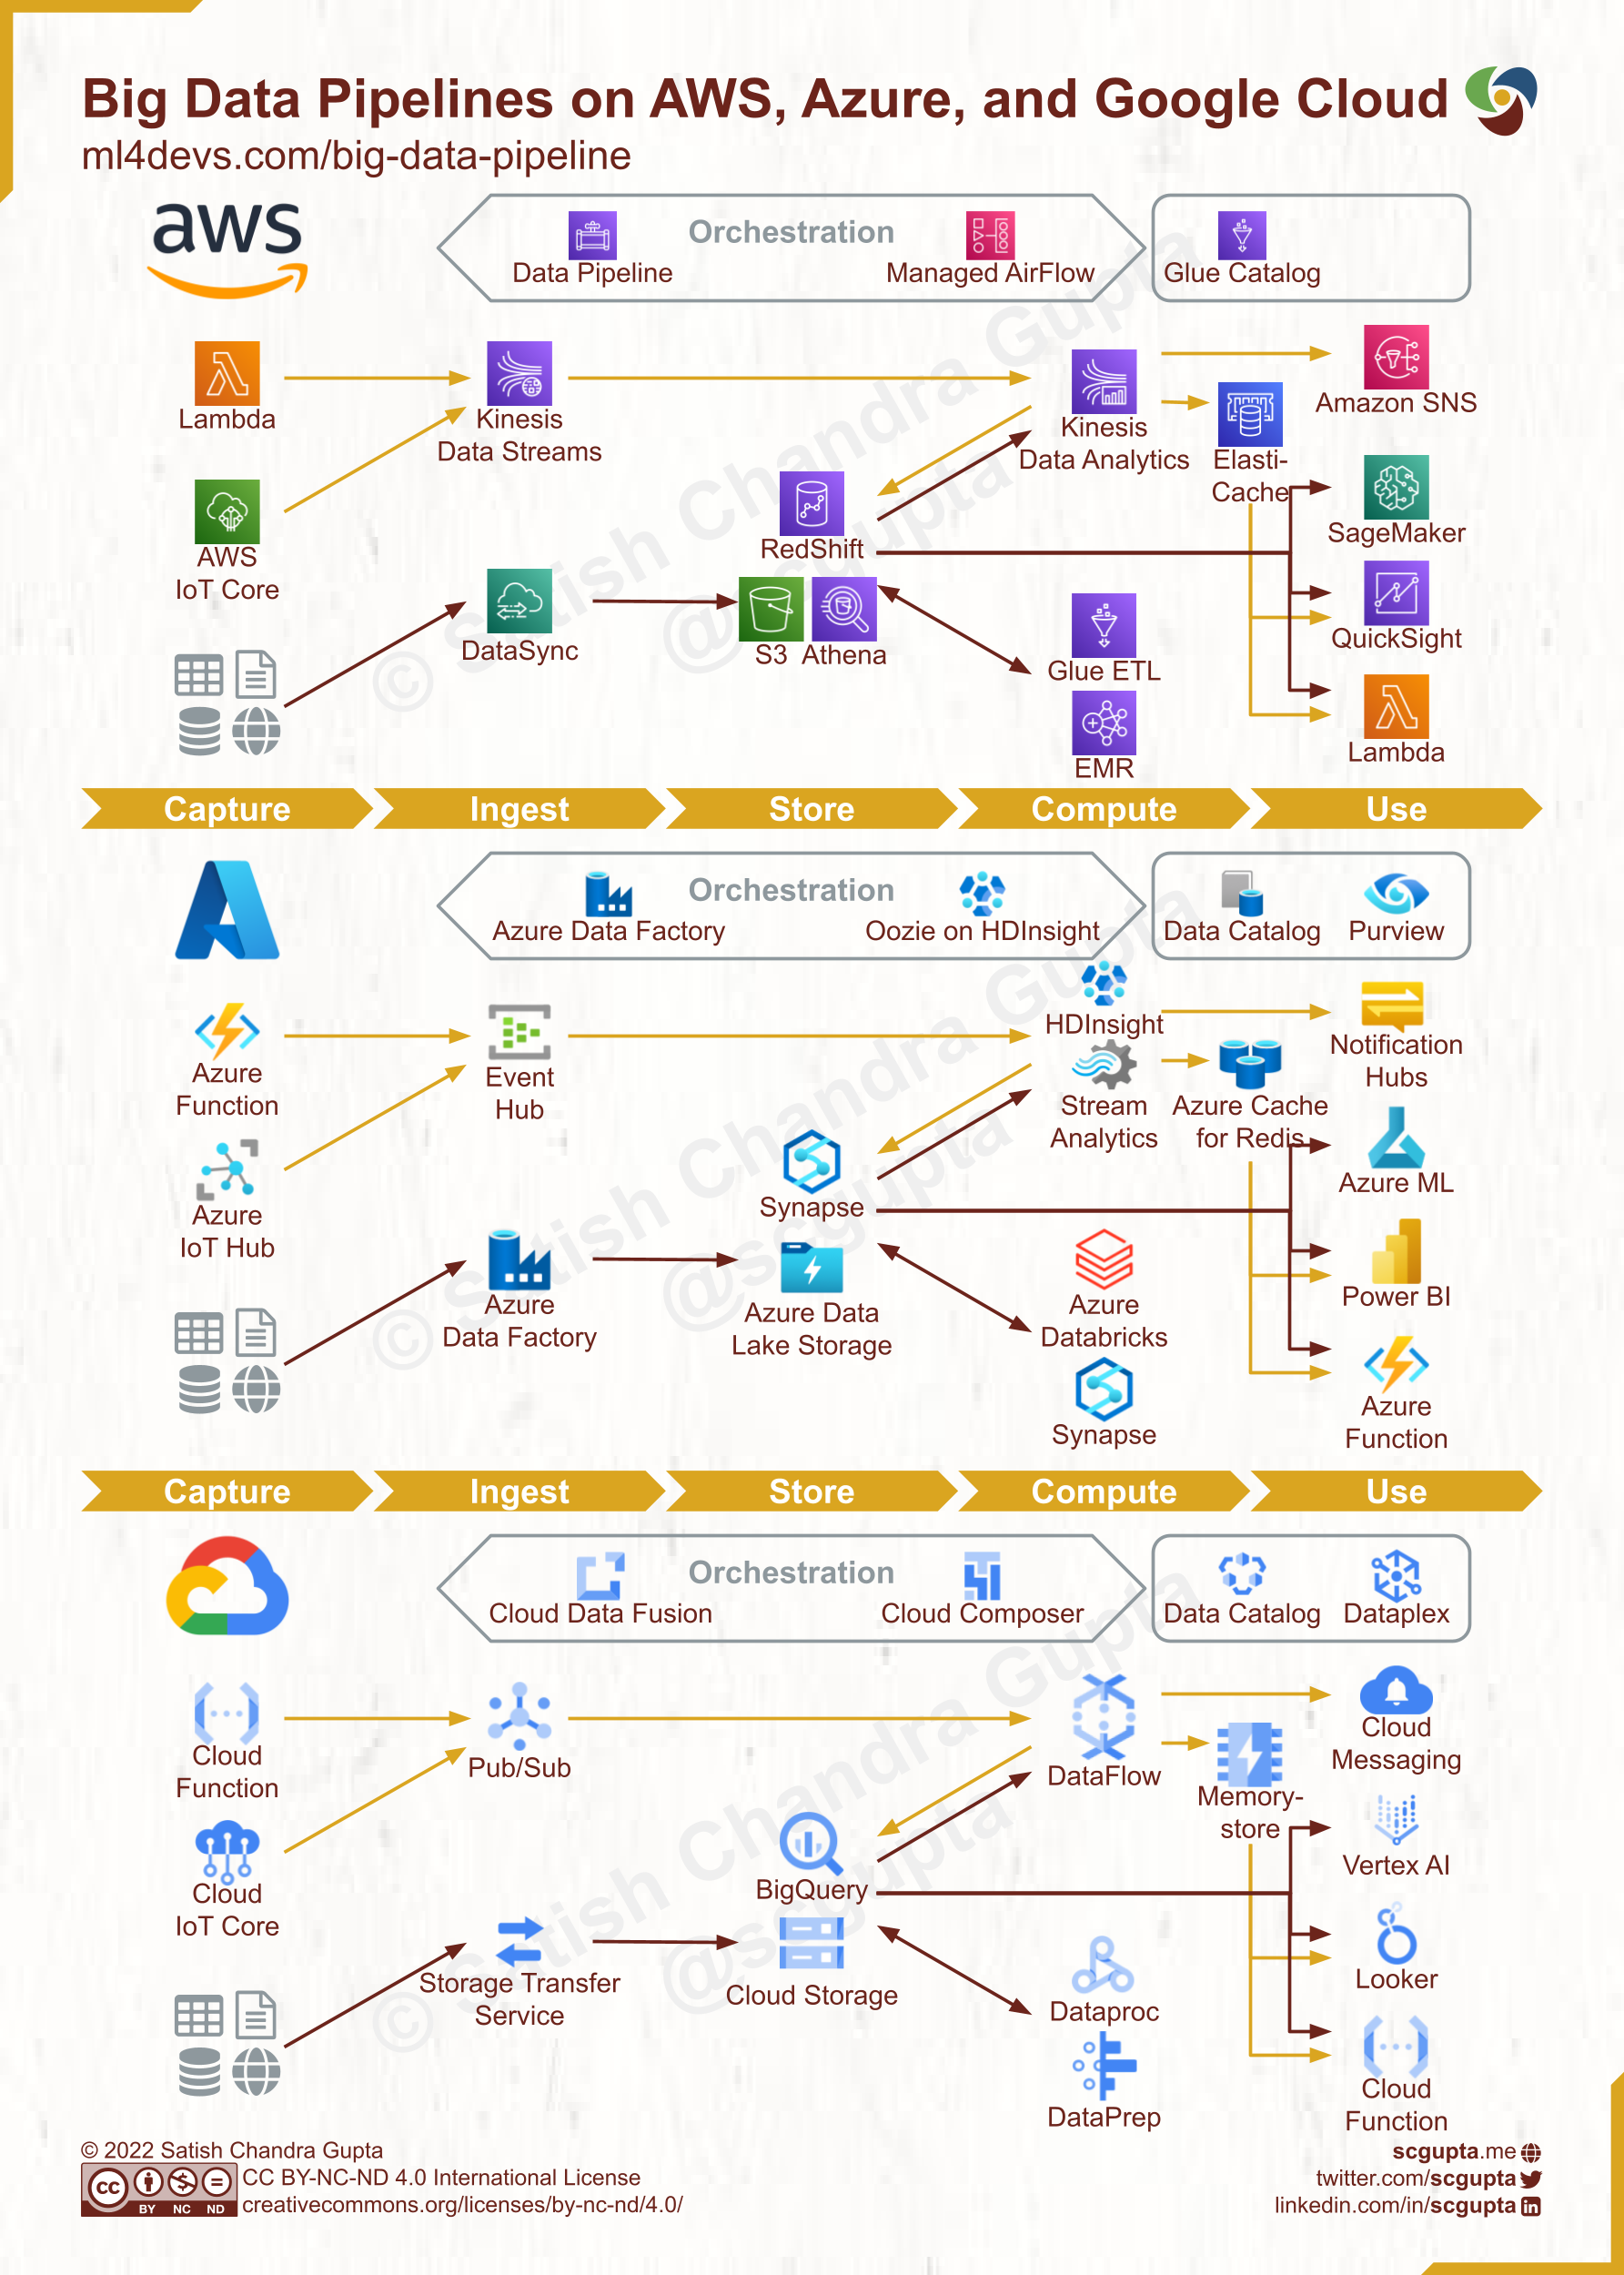
For anything larger, you need proper backfills, retry logic with exponential delay, and the ability to rerun a single failed node without re-executing upstream dependencies that already succeeded. That's what a real orchestrator gives you. The backfill alone will save you during compliance audits when someone asks where last year's data came from.
The Real Bottleneck Isn't Compute
Everyone obsesses over whether to use Spark or Dask or just a really well-tuned pandas script. The bottleneck is almost never the compute. It's the data movement between stages and the lack of caching between pipeline runs. I once had a team spend three weeks trying to optimize a transformation that read ten million rows from S3, ran a groupby, and wrote the result back. The groupby itself was fast. What took four hours was reading the raw data every single time because there was no intermediate cache between the extraction stage and the transformation stage. We added a parquet cache layer with a checksum-based invalidation policy. Same pipeline, 47 minutes instead of four hours. Parquet isn't the answer for every intermediate storage problem, but it solves the majority of them. Columnar format, compression, schema enforcement. If you're passing data between stages as CSV or JSON, you're burning unnecessary cycles on parsing and serialization.
Schema Validation That Actually Works
The eleven-day silent failure I mentioned above was preventable. The fix wasn't more monitoring on the dashboard side. It was adding schema validation at the ingestion point using something like Great Expectations or even a simple Pydantic model, depending on the complexity. Here's the counter-intuitive part: validate on ingestion, not on consumption. Most teams put validation downstream near the model or the report because that's where they see the data "in the wild." But by then you've already wasted compute on bad data and you're chasing ghosts through logs. Validate at the entry point where the failure is cheapest to catch. We set up a simple check right after extraction that compared the incoming row count and column types against a baseline from the previous successful run. If either drifted more than five percent, the pipeline flagged it and paused downstream execution. Cost us about twenty lines of code. Saved us from the kind of failure that quietly corrupts months of work.
Monitoring Without the Noise
Alerting on every pipeline failure is useless. You get desensitized within a week and start ignoring all the pings. The useful alerts are the ones that actually correlate with business impact. Track these things instead of generic success and failure: Row count variance between runs. If your extraction normally pulls fifty thousand records and suddenly pulls twelve thousand, that's a signal even if the pipeline technically succeeded.
Transformation duration trends. A job that normally takes twelve minutes and starts taking forty-five minutes isn't failing yet. It's one bad data pattern away from failing. Downstream consumer errors. If your data lake has a schema change detection mechanism, feed that back into the pipeline health score. A pipeline that produces correct output but the consumers can't read it is just as broken as one that produces incorrect output.
The Part Nobody Talks About: Testing
Unit tests for data pipelines are harder than unit tests for application code because the input space is enormous and the expected output often depends on business logic that lives in someone's head rather than in a spec document. What I've found that works is testing the transformation logic in isolation from the orchestration. Extract a small sample of real data, run just the transformation function against it, and assert on the output schema and basic statistical properties. Mean, standard deviation, null percentages. If a change makes the average age in a customer dataset jump from thirty-four to seventy-eight, something broke. You don't need to know exactly what to know that it's wrong. Integration tests that run the full pipeline on synthetic data are also worthwhile, but keep the synthetic data realistic. Uniformly distributed numbers hide edge cases that real data exposes immediately. Generate test data that matches the distribution and cardinality characteristics of your actual sources.

When Not to Build a Pipeline
Sometimes the right architecture is no architecture. If you're doing exploratory analysis on a dataset that changes weekly and the analysis itself takes less than an hour to re-run manually, don't build a pipeline. You're optimizing for a problem you don't have yet. Pipelines have maintenance costs. Every stage is a potential failure point. Every dependency is a version conflict waiting to happen. I've seen teams spend more time keeping their pipeline infrastructure healthy than the pipeline saves them in execution time. That's a losing equation. The threshold where a pipeline becomes worth the overhead is usually around three or more independent data sources, more than five transformation steps, and a consumption pattern that requires reproducibility rather than one-off analysis. If you meet those criteria, then the architectural decisions I described above actually matter.
Tools Break. Patterns Don't
Airflow versions update. cloud providers change their SDKs. pandas drops functions you depended on. The tools will let you down at some point. The patterns survive longer. Separating extraction from transformation from loading. Validating data at ingestion. Caching intermediate results. Testing transformations on sampled data. These aren't tied to any particular framework. I've rebuilt the same pipeline three times across four different toolchains in the last six years. Each time the orchestration layer changed, each time the storage backend changed, each time the deployment model changed. The structure stayed the same because the structure is what handles the failures before they become incidents at 2 AM. Build for the failure mode you haven't seen yet. That's usually the one that takes the longest to recover from.