Where the Book Actually Fits in Your Workflow
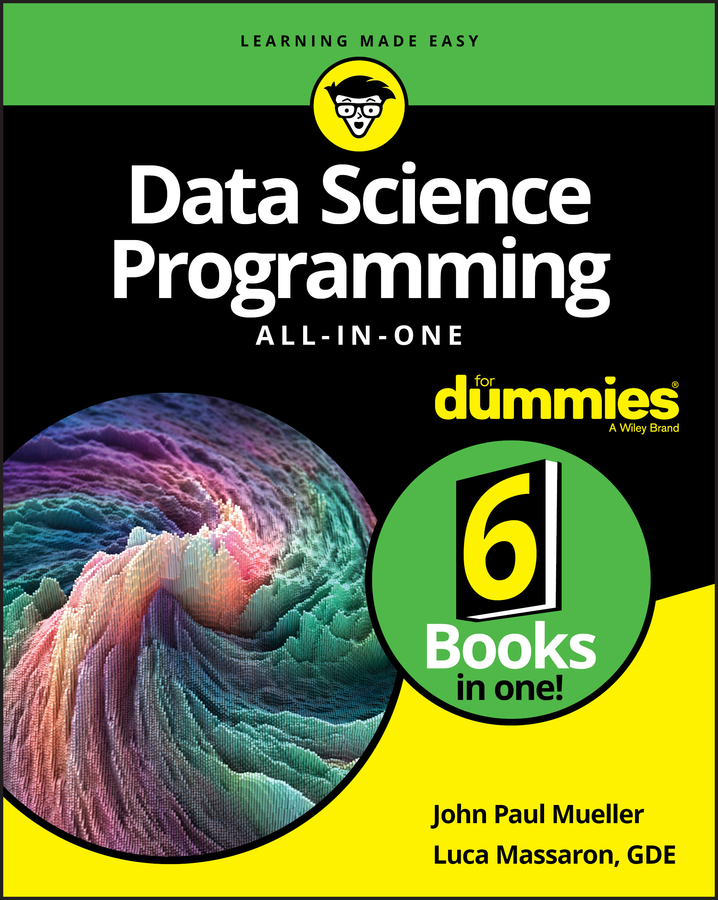
I pick up Data Science Programming All In One For Dummies when someone asks me what to read before they start a bootcamp or career switch. It covers the same ground most people expect: Python basics, NumPy, pandas, matplotlib, basic statistics, scikit-learn, a chapter on deep learning, and some business-oriented material at the end. That last part is usually what gets recommended to people who already know a bit of code and are trying to position themselves for a role. The book is not a reference. It is not deep on any single topic. It is a survey course in print. The main reason this book survives in recommendations is consistency. Most free material online is either too shallow or too advanced for the middle ground. This volume sits in the middle ground by design. The writing is plain. The exercises are structured. You can finish it in a few weeks if you actually do the coding instead of skimming. Here is the thing nobody admits: the real value is not in the theory chapters. It is in the repeated hands-on sections where you import a CSV, inspect the nulls, write a groupby, plot something, and run a train-test split. That repetition matters more than understanding every formula. If you complete every exercise yourself and commit the code to a repository, you will have enough muscle memory to handle most entry-level tasks. If you read it passively, you will forget it within a month.
The first time I tried to use this book as a self-contained curriculum, I ran into a wall around the pandas section. The book explains merge, join, and concat in separate mini-chapters, but it never shows a single realistic example where you have to decide between them while dealing with duplicate keys and mismatched index levels. I was working with a sales dataset that had transaction IDs repeated across regions, and I kept getting a Cartesian product I could not explain. The workaround was simple but tedious: I wrote a small helper that printed out the cardinality of each key column before every merge, then verified the output shape manually. That habit saved me more time than any chapter in the book. I still do that with my own pipelines now, even when I am not using this book at all. The second edition added a bit more on machine learning evaluation, which helped. The first edition was older, heavier on R, and lighter on modern scikit-learn practices. If you are picking up a used copy, check the copyright date. Anything pre-2020 is going to feel dated in the Python environment sections.
What the Book Leaves Out (And What You Should Do Instead)
This is where I stop being polite. The book will not teach you Git. It will not teach you virtual environments properly. It gives you a two-page overview of SQL that is adequate for a test but useless in practice. It barely mentions JupyterLab alternatives, version control for data, testing, or deployment. There is almost nothing about how to handle missing data beyond dropping rows or filling with a mean, which is a dangerous habit to leave with. It touches on cross-validation but does not emphasize enough that naive shuffling on time-series or grouped data leaks information and ruins your metrics. The book also assumes your data is clean. I encountered this repeatedly. In one project, I had client data where the date column was stored as text in three different formats within the same field. The book never addresses how to diagnose and fix that kind of mess. I ended up writing a small regex-based parser that identified the dominant format, converted what it could, and flagged the rest for manual review. That process took longer than any model I trained. Real work is 80 percent of that kind of tedious cleanup. The book prepares you for the 20 percent. Another gap is the lack of emphasis on reproducibility. The examples run fine on the author's machine because they pin library versions implicitly. When I copied a notebook from the book onto a fresh install, the seaborn output looked different because my Matplotlib backend had changed. The fix was not hard, but the book does not warn you about it. You learn it the hard way the first time.
Get the Full Details
How I Actually Use This Book Without Wasting Time
I do not read it cover to cover. I treat it as a map. I scan the table of contents, pick a topic I want to refresh, and read only the relevant chapters. Then I close the book and code immediately. If the examples use an outdated library call, I check the current documentation instead of arguing with the text. The book is a starting point, not the destination. For the statistics section, I supplement it with a quick review of hypothesis testing and confidence intervals from a proper source. The book gets the ideas right but skips the edge cases where the assumptions break down. For the machine learning chapters, I work through the exercises with a different dataset than the one provided. That forces you to adapt the workflow instead of memorizing the steps. I also recommend pairing the book with a practical project early. Do not wait until you finish all twelve chapters. Pick a small Kaggle dataset or your own messy data, and apply what you learn chapter by chapter. The book works best when you are solving a problem, not when you are preparing for a test.
Where to Get Data Science Programming All In One For Dummies
You can find it on Amazon, Barnes and Noble, and other major retailers. The latest edition is from Wiley. If you prefer digital, the Wiley site offers the e-book and sometimes includes access to downloadable code examples, though the code quality is inconsistent. I prefer the physical copy because it is easier to annotate, but that is a minor preference. The content is the same. There is also an online bundled version through Wiley's platform that includes some video content. It is optional. The written material stands alone. Do not pay extra for the videos unless you struggle with the text explanations. Most of the video content is redundant with the book.
Who Should Skip This Book Entirely
If you already know Python and have built two or more real projects, this book will feel slow. The pace is deliberately gentle, and that will frustrate anyone who has spent time in production code. You will spend pages on syntax you already understand. Skip it and go straight to a more advanced resource or a real project. Similarly, if you are looking for a deep dive into a single topic like NLP, computer vision, or MLOps, this book will disappoint you. It is intentionally broad. Brevity is the trade-off for accessibility. If you need depth, pick a specialized book instead. The book also struggles with the transition from tutorial to real work. The datasets are clean. The problems are well-defined. The evaluation metrics are standard. None of that reflects the ambiguity of most actual data science jobs. I learned that lesson quickly. The book gets you to the door. You have to walk through it yourself.

Practical Checklist Before You Buy
Make sure you are getting the most recent edition. The earlier ones use older library versions and miss newer scikit-learn APIs. Check the page count and the table of contents online. If the Python section is under sixty pages, it is too thin for most beginners. The book should have substantial hands-on chapters, not just concept overviews. If you are self-teaching, budget at least six to eight weeks to work through it slowly and complete every exercise. Rushing it defeats the purpose. Also keep in mind that the book is static. The field moves faster than print publishing. By the time a new edition drops, some of the code snippets may already be slightly behind. That is normal. Do not treat the book as authoritative. Treat it as structured practice with commentary. I have recommended this book to more people than I can count. Some of them used it well and built solid foundations. Others treated it as entertainment and finished it without learning anything. The difference is always the same: whether they coded along actively and filled the gaps with real projects afterward. The book does not guarantee competence. It guarantees exposure. How far you take that exposure is entirely up to you.