What Actually Separates These Two Fields
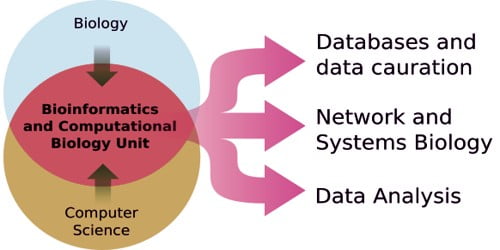
Data science and bioinformatics share a common toolkit, but they solve fundamentally different kinds of problems. Both use Python, R, statistics, and machine learning. Both deal with messy, high-dimensional data. The difference is in the structure of the data itself, the biological constraints you have to respect, and the questions you are actually trying to answer. I spent years working on both sides. A lot of people enter bioinformatics thinking it is just data science applied to biology. That is not quite right. Biology imposes constraints that most data science projects simply do not encounter. Sequencing errors follow specific patterns. Evolutionary relationships matter. You cannot treat a gene expression matrix the same way you would treat a customer churn dataset, even if both are high-dimensional tables.
Data Science Vs Bioinformatics: Where They Diverge
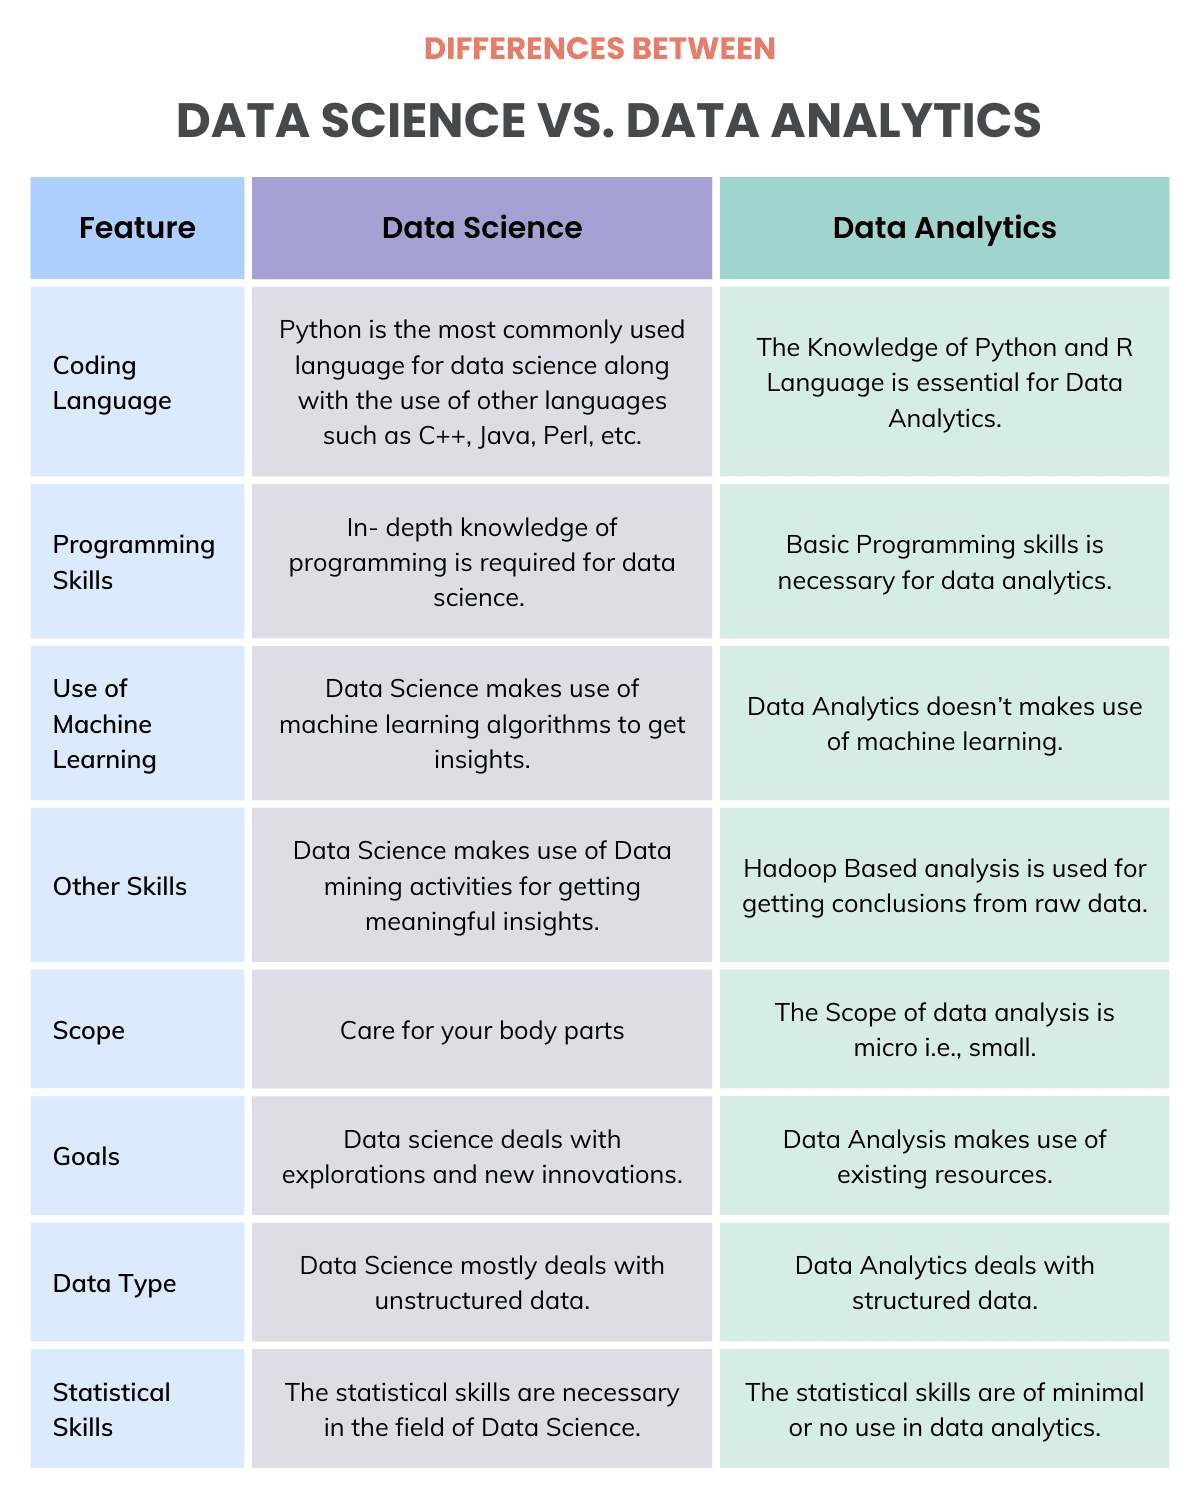
Data science typically works with structured or semi-structured data generated by human systems. Clicks, transactions, sensor readings, survey responses. The noise is usually random or at least independent between observations. The goal is prediction, classification, or causal inference within a defined business or research context. Bioinformatics works with data generated by biological systems. That means the observations are correlated through shared ancestry, the error structure is instrument-specific and non-uniform, and the data often has a hierarchical organization that mirrors evolutionary history. A single RNA-seq experiment gives you counts for roughly twenty thousand genes measured across a small number of samples. The signal-to-noise ratio is brutal. You are trying to find real biological patterns in data where the experimental design limits your statistical power by definition. The overlap is real though. A bioinformatician who cannot do data science is limited. A data scientist who wanders into genomics without understanding the domain will make expensive mistakes. I have seen it happen repeatedly. People apply standard cross-validation to genomic data and get results that look impressive until someone realizes the validation was leaky because related samples ended up in both training and test sets.
The Practical Workflow Difference
In data science, the workflow usually looks like this: define the problem, collect the data, clean it, explore it, build a model, evaluate, deploy. The bottleneck is often the model or the feature engineering. In bioinformatics, the bottleneck is almost always upstream. It is the data generation and preprocessing. Take RNA-seq analysis as a concrete example. You start with raw reads from a sequencing machine. You align them to a reference genome. You count how many reads map to each gene. Then you normalize, filter low-expression genes, handle batch effects, and finally run differential expression analysis. Each step introduces its own assumptions and potential failure modes. If your alignment parameters are off, your counts are wrong. If your normalization method does not match your experimental design, your differential expression results are garbage. The model you pick at the end does not matter much if the pipeline before it is broken. In data science, a bad model is usually correctable by trying another algorithm. In bioinformatics, a bad preprocessing choice can invalidate the entire experiment and there is no going back unless you resequence, which costs money and time.
Get the Full Details
A Specific Problem I Encountered
Here is a concrete example from my own work. We were analyzing single-cell RNA-seq data from tumor biopsies. The standard pipeline flagged a batch effect that correlated perfectly with the sequencing date. The obvious fix was to include sequencing date as a covariate in the differential expression model. But when I looked closer, I realized the batch effect was not technical. The samples sequenced on the later date happened to come from a different hospital site, and the patient populations were demographically different. Age and disease stage were confounded with the batch. I spent two days trying different correction methods. ComBat removed the batch effect but also removed real biological signal. Including site as a covariate helped but reduced the effective sample size too much. The final workaround was to use a subset of highly variable genes that were stable across sites as anchors for integration, then run the differential expression on the integrated dataset with site included as a blocking factor in the model. It was not elegant, but it preserved the biological signal while accounting for the confounding. A beginner might have just run ComBat and called it done. That would have been wrong.
What Bioinformatics Requires That General Data Science Does Not
You need to understand the biology well enough to know when the data is lying to you. Biological data has idiosyncrasies that do not appear in textbook examples. Gene length bias in RNA-seq. GC content bias in sequencing. Ambient RNA contamination in single-cell experiments. Batch effects that correlate with biological conditions. These are not edge cases. They are the normal state of affairs. You also need to be comfortable with tools and formats that are foreign to most data scientists. FASTQ, BAM, VCF, GFF, BED, HDF5 backed by HDF5. Tools like GATK, Snakemake, Nextflow, CellRanger, Seurat, Scanpy. The ecosystem is fragmented because the field moved faster than standardization efforts could keep up. You will spend time debugging why a pipeline works on Linux but fails on macOS, or why a Python package requires a specific conda environment that conflicts with everything else you have installed. On the data science side, the tooling is more mature and standardized. Pandas, scikit-learn, XGBoost, SQL databases, cloud ML platforms. The learning curve is gentler because the community is larger and the documentation is better maintained.
The Math Is Different Too
Both fields use statistics. But bioinformatics often requires specialized statistical methods that general data science courses do not cover. Negative binomial distributions for RNA-seq count data. Mixed-effects models for population genetics. Hidden Markov models for sequence alignment. Phylogenetic reconstruction methods that are computationally intensive and rely on approximations that can fail under certain conditions. A data scientist who knows generalized linear models well can pick up bioinformatics statistics relatively quickly. But the reverse is not always true. Bioinformatics statistical thinking involves dealing with thousands of simultaneous hypothesis tests, multiple testing correction, and the constant tension between statistical significance and biological relevance. A gene can be statistically significant with a tiny p-value and have a fold change so small that it is biologically meaningless. You have to learn to read both numbers and understand why they diverge.
Where Data Science Has the Edge
Data science scales better to production. A well-built model can be deployed to serve predictions to thousands of users simultaneously. The infrastructure is mature. MLOps tools, model registries, A/B testing frameworks, monitoring dashboards. Bioinformatics rarely deals with deployment in the same sense. The output is usually a paper, a clinical report, or a set of candidate genes for further experimental validation. The timeline is measured in months or years, not milliseconds. Also, data science salaries tend to be higher because the industry demand is broader. Every company needs data scientists. Only pharmaceutical companies, biotech firms, and academic labs need bioinformaticians. The job market is smaller and more specialized. That is not a value judgment. It is just a fact you should consider if career outcomes matter to you.
Where Bioinformatics Has the Edge
The intellectual challenge is deeper in many ways. You are working with data that represents the most complex system known to exist. The questions are fundamentally harder. How does a sequence of nucleotides become a living organism? How do mutations drive cancer? How do ecological communities assemble? Data science questions are often narrower: will this customer churn? Which product should we recommend? Is this transaction fraudulent? Bioinformatics also has a growing clinical impact. Precision medicine, pharmacogenomics, liquid biopsies, carrier screening. The work you do can directly affect patient outcomes. That is not true for most data science roles. It is a significant factor for people choosing between the two fields.
If You Want to Work in Either Field
Learn Python and R. They are both essential. Python for pipeline construction and machine learning. R for statistical analysis and visualization, especially in the bioinformatics space where packages like DESeq2, edgeR, and Bioconductor dominate. Learn SQL. Learn command-line tools. In bioinformatics, the command line is not optional. You will spend hours writing shell scripts to chain together tools that do not have Python wrappers. For data science, focus on statistics, machine learning, and software engineering. Build a portfolio of projects using real datasets. Kaggle is okay for practice but it does not teach you about data quality issues because the datasets are curated. For bioinformatics, you need to learn the biology. Molecular biology, genetics, and evolution are not optional background knowledge. They determine whether you can design a valid experiment and interpret the results correctly. One thing nobody tells you: bioinformatics has a replication crisis similar to psychology. Many published findings from high-throughput experiments do not replicate because the statistical methods were inappropriate for the data structure. If you care about doing rigorous work, spend time learning about experimental design and statistical power before you touch a sequencing machine or download a public dataset. The cost of a flawed analysis is much higher when you cannot go back and collect more data easily.
The Reality of Daily Work
In data science, a typical day involves meetings, code reviews, and debugging production issues. You spend a lot of time making sure your model keeps performing well after deployment. In bioinformatics, a typical day involves reading papers, troubleshooting pipelines, and waiting for jobs to finish running on a cluster. The computational tasks are often I/O-bound or memory-bound, not compute-bound. You will spend hours waiting for a genome alignment to finish because your job is swapping to disk. The communication style is different too. Data scientists present to stakeholders who care about business metrics. Bioinformaticians present to biologists and clinicians who care about mechanistic understanding. Learning to translate between these two cultures is one of the most valuable skills you can develop, regardless of which path you choose. Neither field is easier. They are just different kinds of hard. Data science hardness comes from scale and uncertainty. Bioinformatics hardness comes from complexity and the consequences of getting it wrong. If you are choosing between them, pick the kind of problem that annoys you less. That sounds crude but it is accurate. You will be doing this work for a long time, and the type of frustration you encounter daily matters more than any abstract comparison of salary or job prospects.