Decision Modeling And Analysis
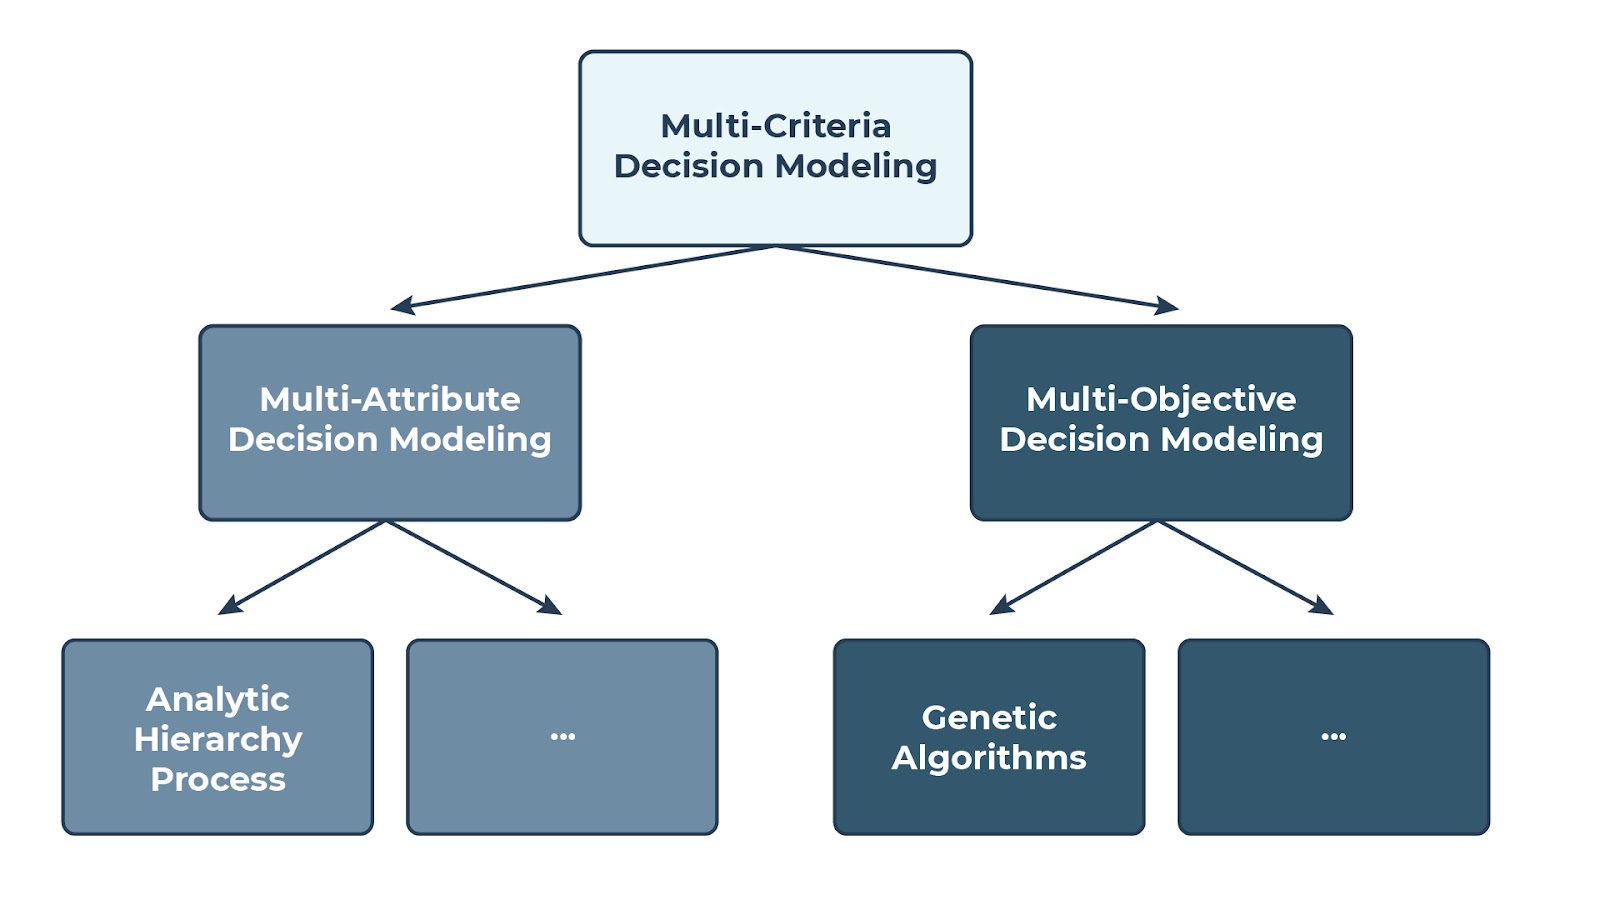
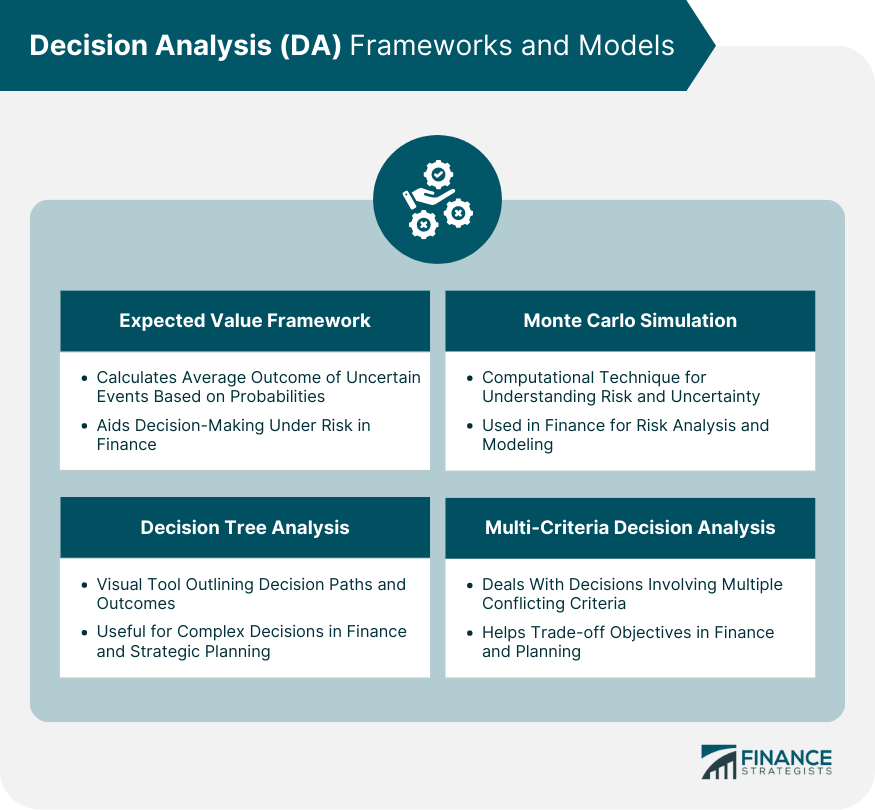
A spreadsheet with conditional formatting is not decision modeling. You have to know what the model is actually doing before you spend three weeks building it, because most of the time it will come back to bite you during implementation. At its core, decision modeling is the process of representing choices, uncertainties, constraints, and outcomes in a formal structure so you can evaluate alternatives systematically rather than arguing about them. That structure can be a decision tree, an influence diagram, a linear programming formulation, a Monte Carlo simulation, or a rule-based decision table. The tool does not matter nearly as much as the discipline of mapping every variable before you touch any software. I once spent two weeks building a perfectly elegant influence diagram for a supply chain optimization. It had four decision nodes, seven chance nodes, and a utility function that looked gorgeous on paper. Then we realized the "independent" demand nodes were actually strongly correlated across regions due to a shared regional festival calendar. The model recommended a strategy that would have left us with 40% excess inventory in three of the five regions during peak season. I rebuilt it using a copula-based correlation layer in @RISK and it took me four days. The recommendation changed completely.
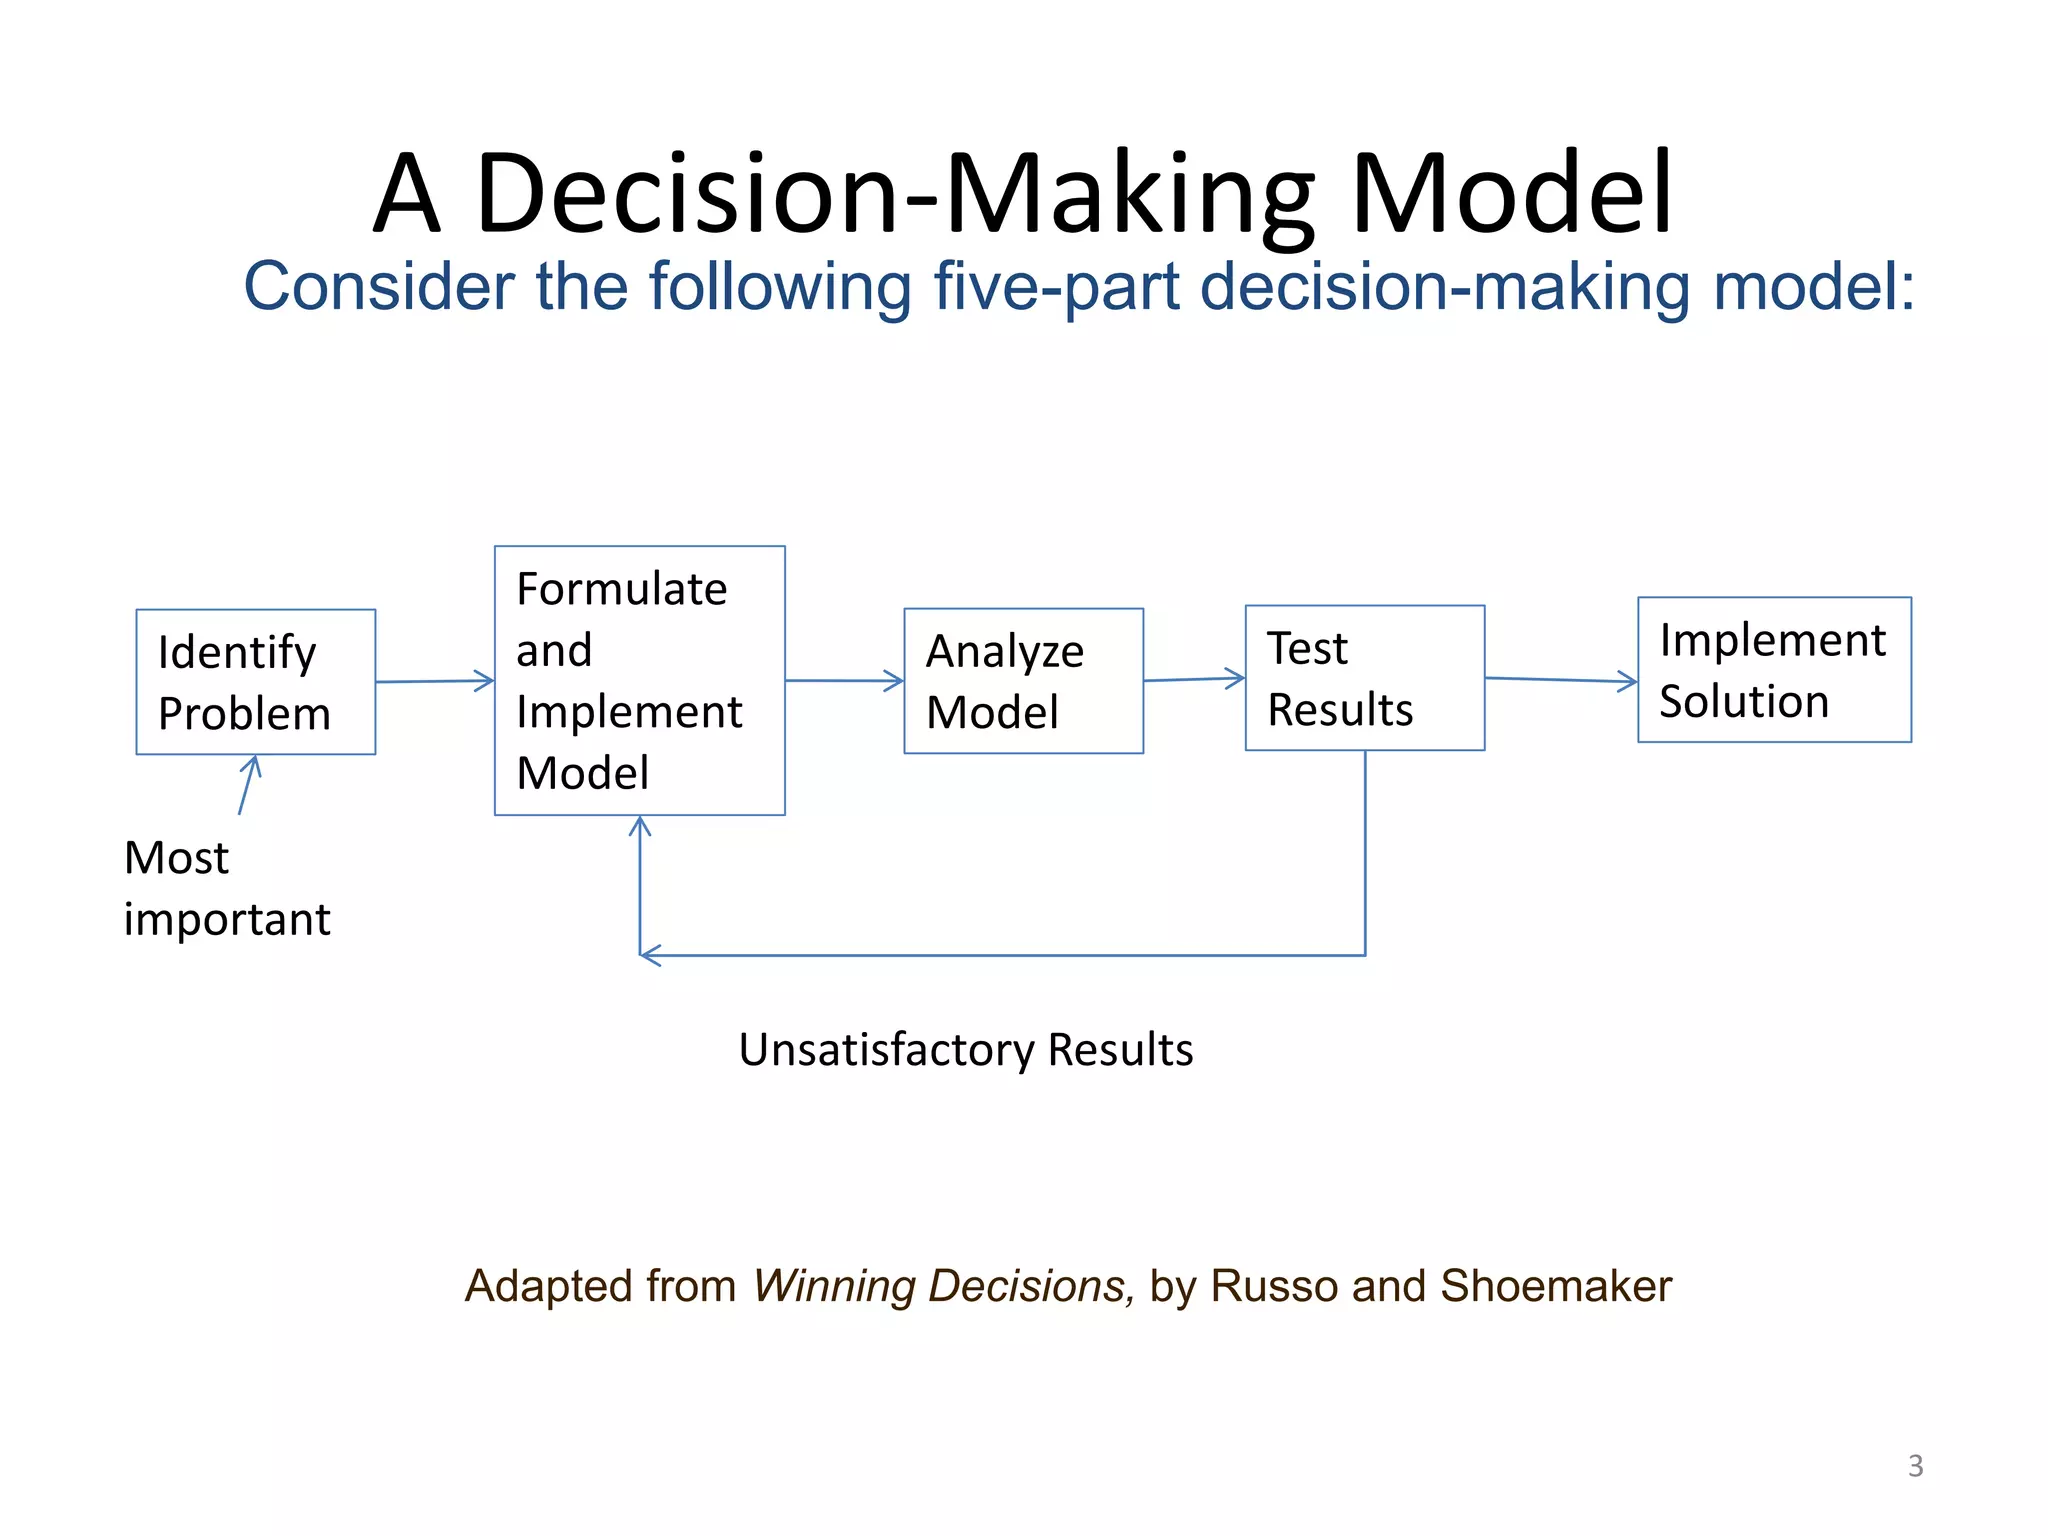
Here is how I actually approach decision modeling work now:
The Practical Method
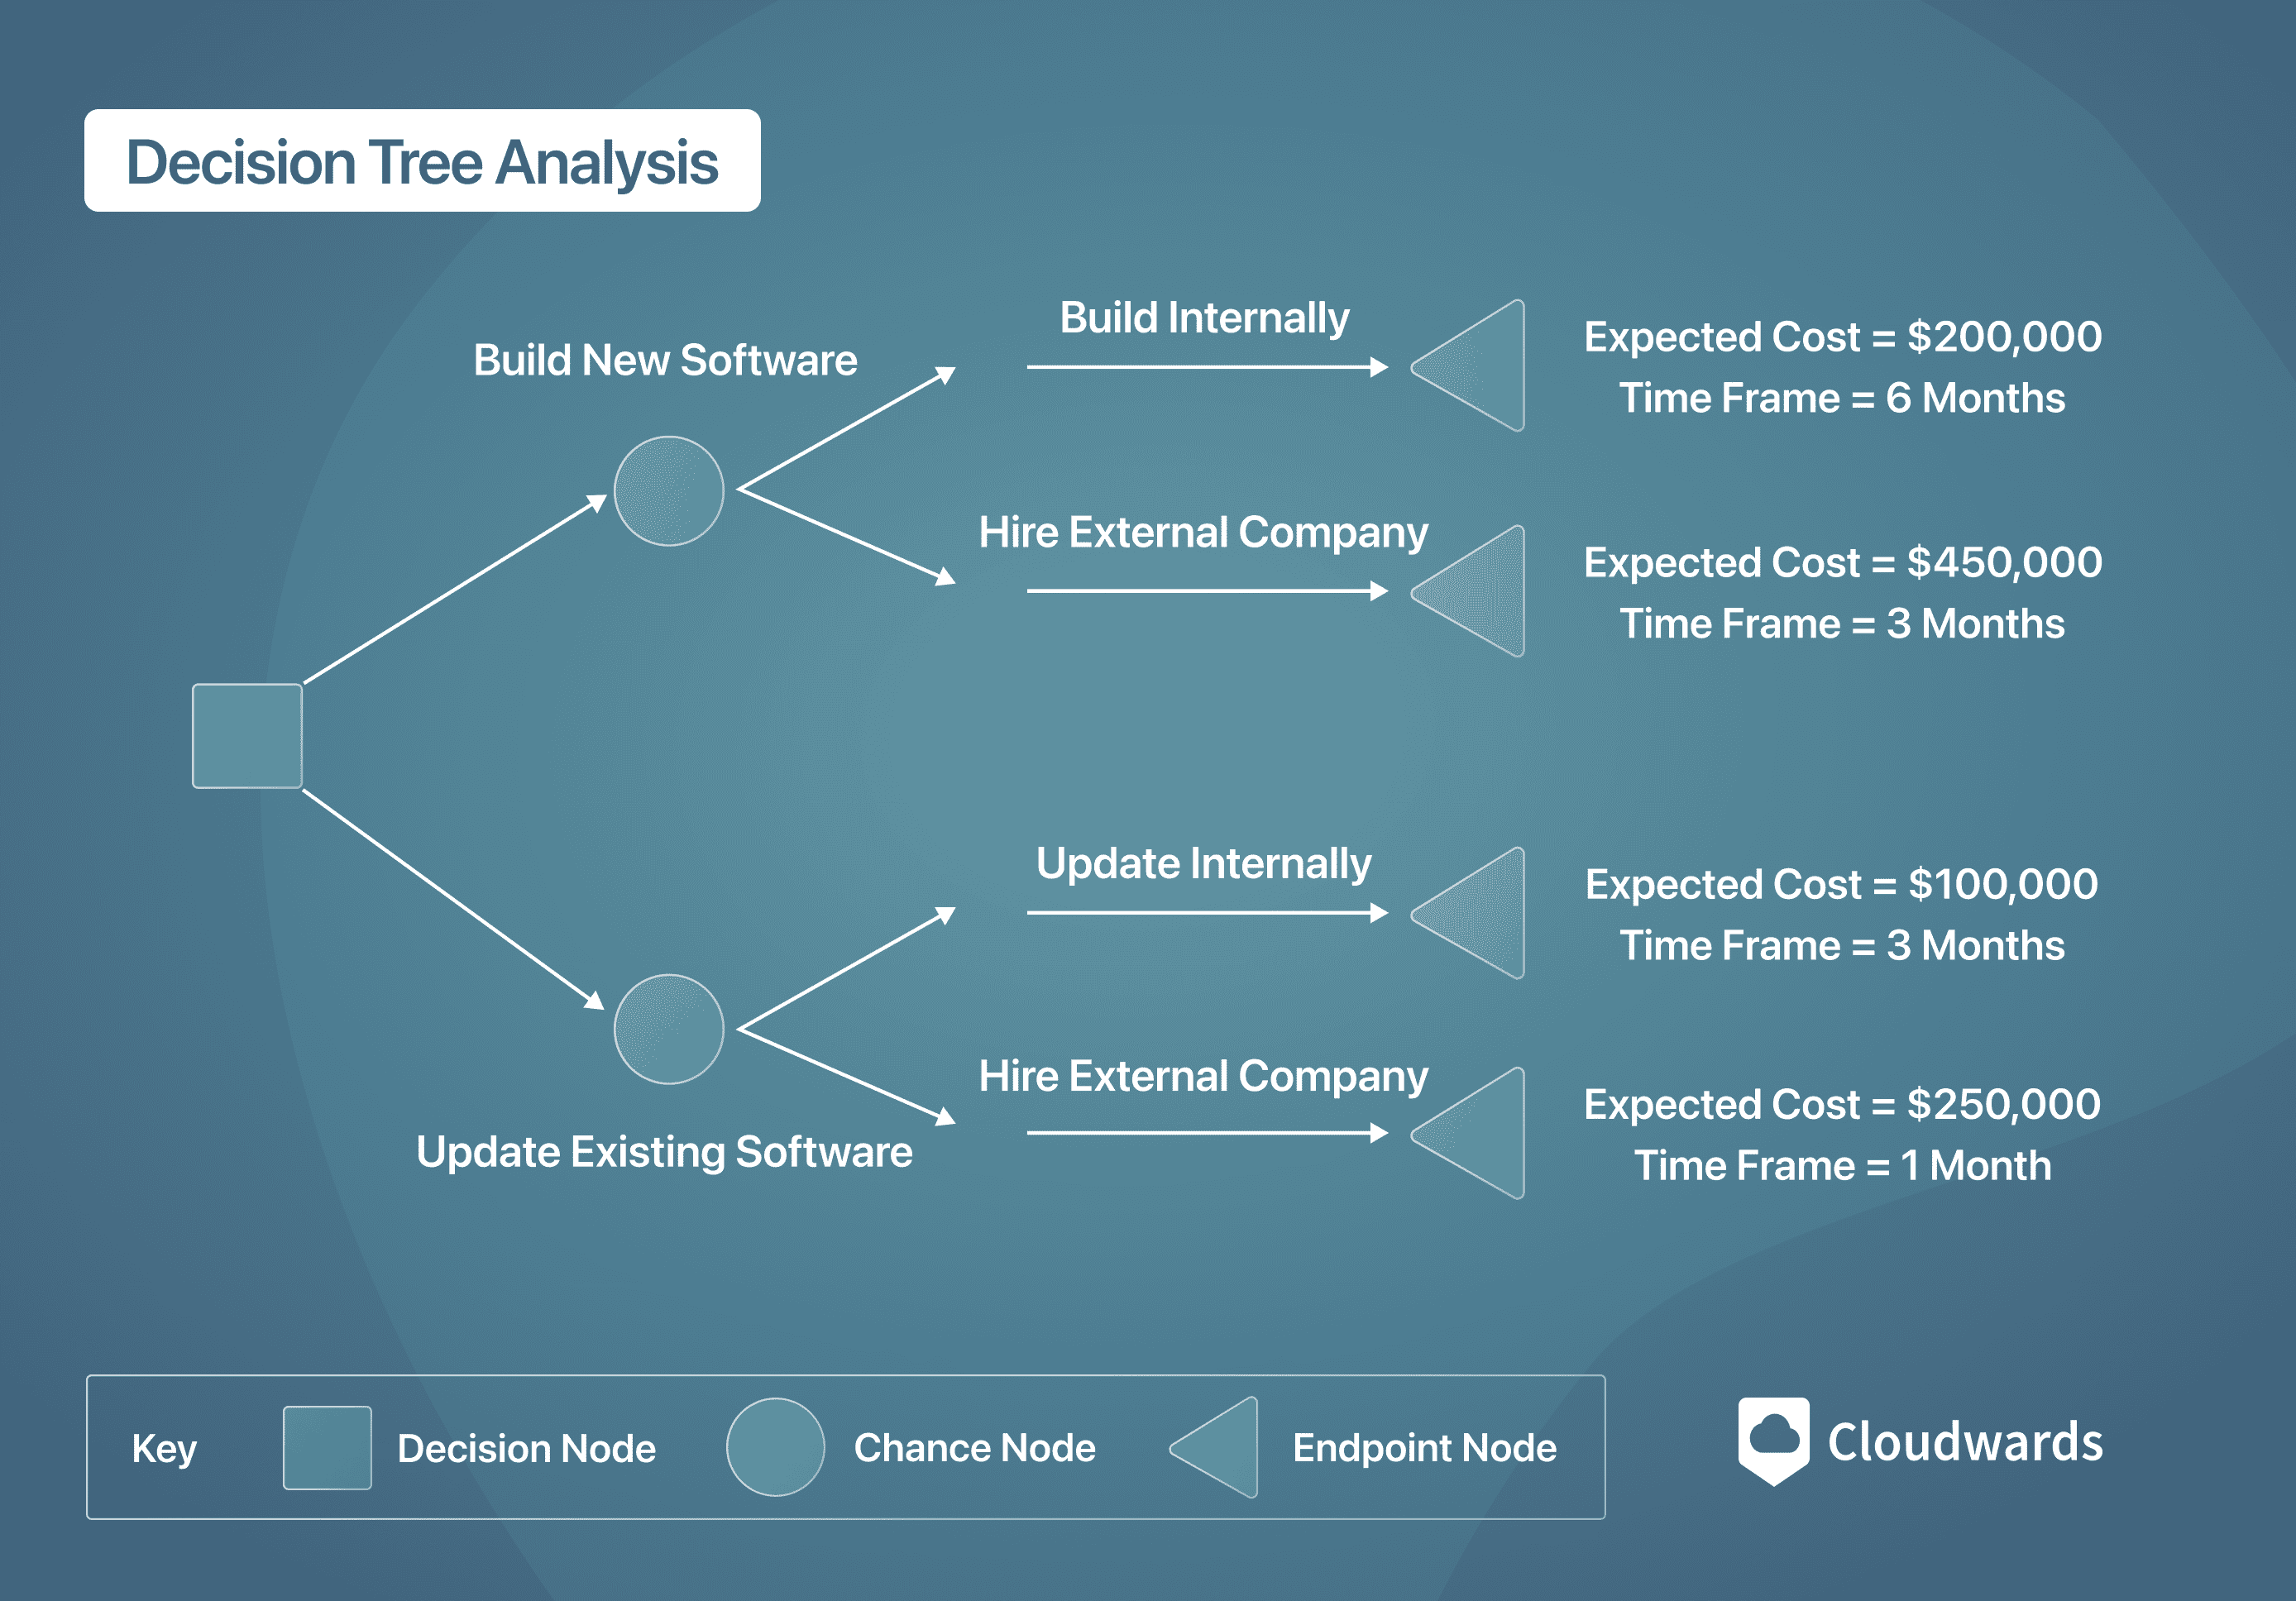
Start by writing down every variable that influences the decision. Not the important ones. Every single one. You will be surprised how many hidden variables show up when you force yourself to list them. This step usually takes longer than the modeling itself and almost always prevents a rework later. Map the dependencies between those variables before assigning any numbers. Draw arrows from cause to effect. If two variables feed into the same outcome, make sure you understand whether they interact or whether they are truly independent. Independence assumptions are the single most common source of error in decision models. I treat any assumption of statistical independence as guilty until proven otherwise. Choose the modeling form that matches the decision's structure. Sequential decisions with branching uncertainty favor decision trees. Simultaneous decisions under constraints favor optimization models. Poorly structured problems with lots of conditional rules often benefit from a decision table. Problems with high variance and multiple interacting stochastic variables need simulation. A single method does not fit all cases, and picking the wrong one early wastes more time than picking slightly the wrong one and adjusting later.
Get the Full Details
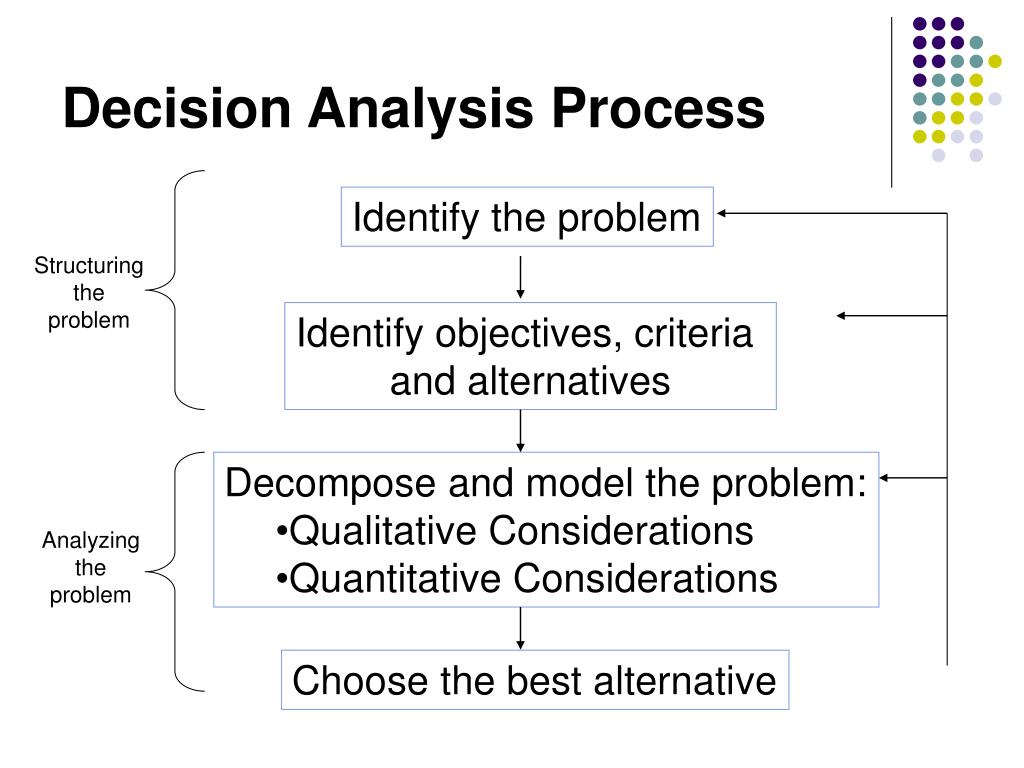
Build a skeleton model with placeholder values before you invest in data collection. A model with fake numbers lets you find structural errors quickly. A model without a skeleton makes it impossible to know whether a bad result came from bad data or bad logic. I typically build the skeleton in under an hour using rough estimates, then spend the next phase replacing placeholders with actual distributions or constraints.
Implementation Details That Matter
When building in Excel, use separate input sheets, calculation sheets, and output sheets. Never put formulas in cells that also contain manual inputs. I have seen models go wrong because someone changed an input value directly in a calculation cell and broke the entire dependency chain. Use named ranges for all key parameters. You will thank yourself when the model needs to be audited six months later by someone who did not build it. For simulation work, validate your random number generators. Standard library functions are usually fine, but if you are sampling from a custom distribution, check the histogram against the theoretical distribution after running at least 10,000 iterations. I learned this the hard way when a client's model was using a transformed uniform distribution that introduced a subtle bias toward lower values. The bias shifted the optimal decision by one full alternative, and we caught it only after comparing the simulation results against a deterministic benchmark case with known outputs. Document every assumption. Not in a separate file. In the model itself, as comments linked to the relevant cells or equations. An undocumented assumption is an assumption that will be forgotten, and a forgotten assumption is the most expensive kind of error because you do not even know where to look when the model produces a suspicious result.
Counter-Intuitive Insights
More data does not always make a better model. I have seen analysts add more variables and tighter probability distributions to a model and produce a worse decision recommendation. The reason is that additional parameters often increase model fragility rather than accuracy. A simpler model with well-justified assumptions frequently outperforms a complex model built on loosely estimated inputs. This is sometimes called the bias-variance tradeoff in a broader sense, and it applies directly to decision modeling. Another thing beginners consistently miss: the difference between a decision model and a forecasting model. A forecasting model predicts what will happen. A decision model recommends what to do. These are fundamentally different tasks. Many organizations build elaborate forecasting models and then use them directly as decision models, which produces decisions that optimize for prediction accuracy rather than actual business outcomes. The optimal action under a forecasting model is rarely the optimal action under a decision model because they minimize different things. I have corrected this mistake at two different companies by separating the teams responsible for forecasting from the teams responsible for decision analysis and making sure the decision models had their own objective functions rather than inheriting the forecasters' metrics.
Tools Available
Standard spreadsheet software with add-ons like @RISK or Crystal Ball handles most small to medium models adequately. For larger optimization problems, Gurobi, CPLEX, or the open-source HiGHS solver provide better performance. R and Python with libraries like PyMC, NumPyro, or the `decisiontheory` package are appropriate for complex probabilistic models. For purely qualitative or rule-based decision analysis, tools like FICO's Decision Management Suite or open-source rule engines exist but require significant implementation effort. There is no free download link for a complete decision modeling system because these are generally commercial products or development environments, not single utilities. What is freely available are template frameworks, reference implementations, and learning datasets. The University of Notre Dame's Management Science and Analytics group publishes several open decision modeling case studies with full model files in Excel and Python. These are useful for understanding the structure before building your own.
Where Decision Modeling Fails
Decision modeling breaks down when the problem involves genuinely unquantifiable values. If the decision depends on ethical considerations, political dynamics, or stakeholder trust that cannot be reasonably assigned a numerical weight or probability, a formal decision model will produce a false sense of precision. I have walked away from engagement contracts because the client needed a decision model for something that was fundamentally a negotiation problem. No algorithm resolves trust deficits between parties. Decision modeling also fails when the decision environment changes faster than the model can be maintained. A model that takes three months to update and a business that changes quarterly is worse than no model because the stale model creates confidence in outdated recommendations. I recommend a refresh threshold: if the underlying business logic changes significantly within two model updates, the model architecture is too rigid and needs to be redesigned with modularity in mind. Finally, decision models trained on historical data assume the future resembles the past. Structural breaks, black swan events, and regime changes violate this assumption without warning. When modeling in volatile industries, I always include a sensitivity analysis that explicitly tests decision robustness under distributional shifts, not just parameter shifts. Parameter sensitivity tells you how much the recommendation changes when inputs vary. Distributional sensitivity tells you how much the recommendation changes when the nature of uncertainty itself changes. The second type of analysis is more valuable and almost never performed.
Concrete Example Walkthrough
Consider a pharmaceutical company deciding whether to launch a new drug in one market or two. The drug has a $40 million development cost already sunk. Launching in one market requires $15 million in marketing spend. Launching in both requires $25 million total marketing spend due to some shared infrastructure. Revenue depends on regulatory approval status, competitive response, and patient adoption rate. Each of these is uncertain. The decision model here has one decision node: launch in one market or both. There are three chance nodes feeding into each market's revenue estimate: approval probability, competitive intensity, and adoption velocity. The adoption velocity is correlated across markets because the same patient advocacy groups operate in both. A naive model would treat these as independent and overstate the diversification benefit of launching in two markets. The correct approach models the correlation explicitly and recalculates the joint probability distribution. Running this model with correlated adoption shows that the expected value of launching in two markets drops by approximately 18% compared to the independent assumption. The risk-adjusted recommendation flips: under independence, both markets looks optimal. Under correlation, a single market launch becomes the preferred choice when the company's risk tolerance is moderate. This is the kind of insight that only appears when you model the structure correctly, and it is exactly the kind of mistake that happens when people skip the dependency mapping step.

The final output should not be a single expected value. It should be a decision recommendation with a range of plausible outcomes, the key drivers identified through sensitivity analysis, and a list of information items whose resolution would most reduce decision risk. If your output is just a number, you have not done the analysis correctly.