Understanding Coefficients Outside the Textbook
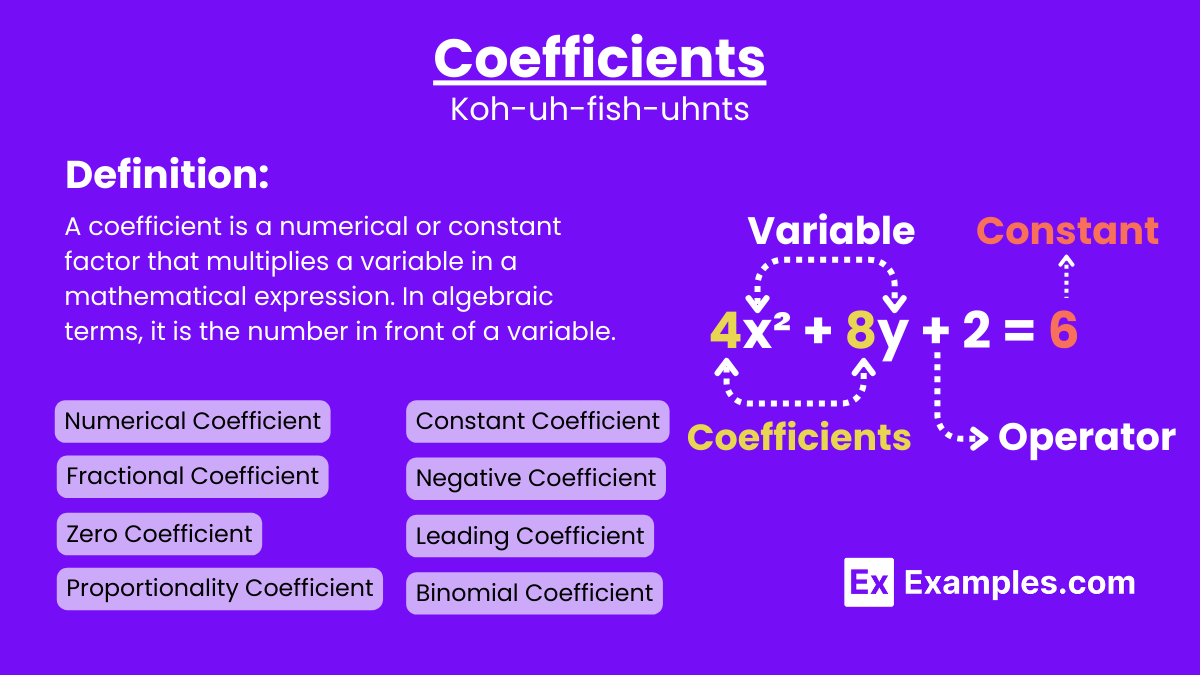
A coefficient is just a number placed in front of a variable to show how much that variable contributes to an equation or model. That's it. It's not some sacred mathematical concept that requires reverence. You see them everywhere, and most of the time people use them without really thinking about what they're actually telling you. The Definition Of Coefficient Science covers how these numbers are derived, interpreted, and applied across disciplines like statistics, physics, chemistry, and machine learning. It's not one unified field so much as a shared toolset. Different domains use the same basic idea but handle edge cases in their own ways. That's why people get confused when they try to carry understanding from one area into another. Let's say you're looking at a simple regression line: y = 0.75x + 3. The 0.75 is the coefficient for x. It means for every one-unit increase in x, y increases by 0.75 units, assuming everything else stays constant. The 3 is the intercept. People confuse coefficients with correlation all the time. They're not the same thing. Correlation measures the strength and direction of a linear relationship between two variables. A coefficient tells you the magnitude of change. You can have a strong correlation with a tiny coefficient if the scales are very different.
I run into this confusion constantly when people send me model outputs and ask whether a coefficient of 0.03 is "weak." It depends entirely on the scale of your variables. If x ranges from 0 to 100,000, then 0.03 is substantial. If x ranges from 0 to 1, it's essentially nothing. Always check the scale before making any judgment about a coefficient's importance. In machine learning, regularization directly manipulates coefficients. Ridge regression adds a penalty proportional to the square of the coefficients, which shrinks them toward zero without eliminating any. LASSO uses the absolute value of coefficients and can actually push some to exactly zero, effectively performing feature selection. Elastic net combines both approaches. The choice matters more than most practitioners realize because it changes which variables your model considers relevant. P-values attached to coefficients are another common source of error. A low p-value tells you the coefficient is likely not zero given your data and model assumptions. It does not tell you the effect is large, important, or causal. I once saw a researcher publish a finding where a coefficient was statistically significant at p
0.001 but the actual effect size was so small it had no practical meaning. The p-value was doing exactly what it was supposed to do. The interpretation was wrong.
Multicollinearity is where coefficients become unreliable. This happens when two or more predictor variables are highly correlated with each other. The model struggles to distinguish which variable is actually driving the outcome. Coefficients become unstable, their standard errors inflate, and you can get wild swings in values depending on which other variables are in the model. I dealt with this specific problem on a housing price prediction project. Square footage and number of rooms were both strong predictors, but they're inherently correlated because larger houses tend to have more rooms. When I included both, the coefficient for square footage jumped around wildly depending on whether I standardized the data or not. The model was essentially arguing with itself about which variable deserved credit for the price increase. The workaround was straightforward. I dropped the room count variable and kept square footage, since square footage already captures the size information. Alternatively, I could have created a ratio variable like rooms per square foot, which sometimes provides more meaningful signal than raw counts. The key insight is that you have to decide whether you care more about prediction accuracy or coefficient interpretability. Those two goals often conflict when multicollinearity is present.
Get the Full Details
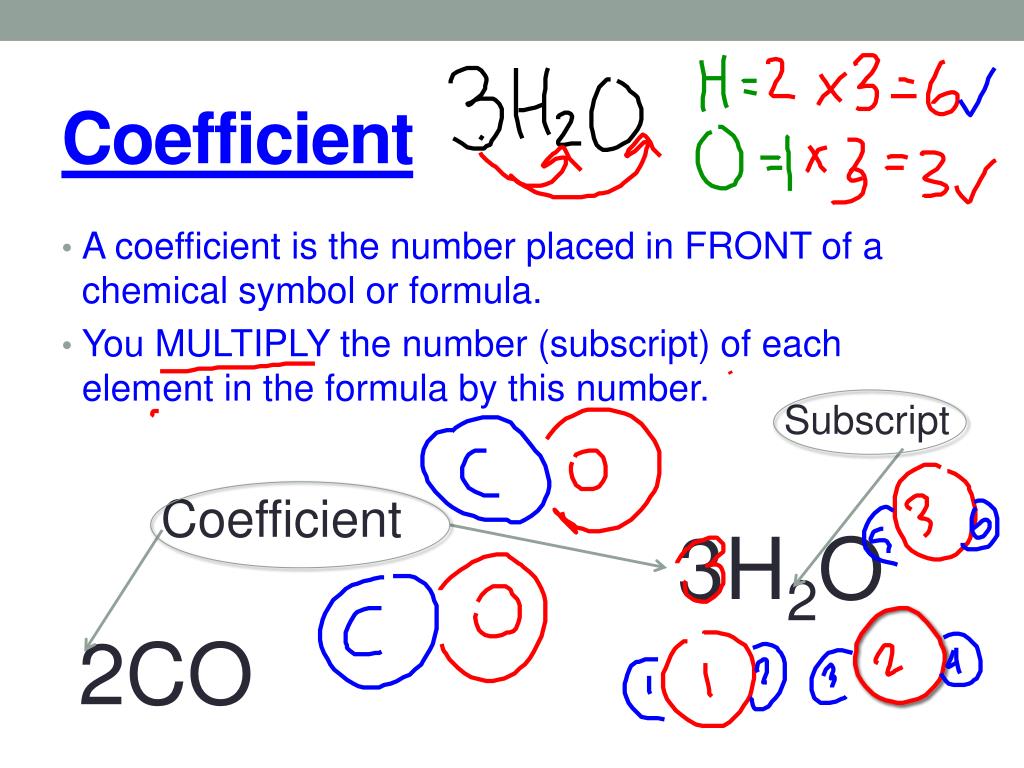
In physics, coefficients appear constantly. Thermal expansion coefficients describe how much a material expands per degree of temperature change. Friction coefficients quantify the resistance between two surfaces. Refractive indices determine how light bends when entering a material. Each one is experimentally determined and context-dependent. A steel beam's thermal expansion coefficient changes slightly with temperature, though most introductory courses treat it as a constant. Chemistry uses coefficients in rate equations and equilibrium expressions. The rate constant k in a rate law like rate = k[A]^m[B]^n isn't a coefficient in the same sense as a regression coefficient. It's an empirically determined constant that encapsulates temperature dependence and reaction mechanism. Confusing these different uses of "coefficient" leads to sloppy thinking, especially when students move from general chemistry into physical chemistry or chemical engineering. Spectrophotometry relies on molar absorptivity coefficients, which are specific to each compound at each wavelength. These values are tabulated and can be used to determine concentrations via Beer's Law. The catch is that these coefficients assume ideal conditions. High concentrations, solvent effects, and instrumental limitations can all cause deviations. I've seen people apply tabulated values to samples that were far too concentrated and then wonder why their calculated concentrations were wrong.
One thing most tutorials don't emphasize enough is that coefficients are model-dependent. Change the model specification, and your coefficients change. Adding an interaction term, transforming a variable, or including a control variable will alter the coefficients of existing predictors. This isn't a bug. It's a feature. It means coefficients describe relationships within a specific modeling framework, not absolute truths about the world. The biggest limitation of coefficient-based analysis is the assumption of linearity. Most introductory treatments present coefficients through linear models, but the real world is full of nonlinear relationships. You can force a linear coefficient onto nonlinear data, but the resulting coefficient will be a rough average at best and potentially misleading at worst. Polynomial terms, splines, and generalized additive models exist precisely because linear coefficients aren't always sufficient. The tradeoff is that they become harder to interpret, which is why many practitioners stick with linear models even when they're inappropriate. Another practical issue is that software will happily compute coefficients for data that doesn't support them. If you run a regression on time series data with autocorrelation, the coefficients will look fine but the standard errors will be wrong, making your p-values unreliable. If you run a model on data with outliers, a single influential point can dominate the coefficient estimates. Diagnostics matter more than the coefficient values themselves, yet most people look only at the numbers and stop there.
If you need to work with coefficients in practice, start by checking your variable scales, run variance inflation factor tests for multicollinearity, and always plot your residuals. These steps take about ten minutes and will save you from most of the common mistakes I've described. The alternative is publishing or presenting results that look clean but are built on unstable foundations.