What an Index Actually Is
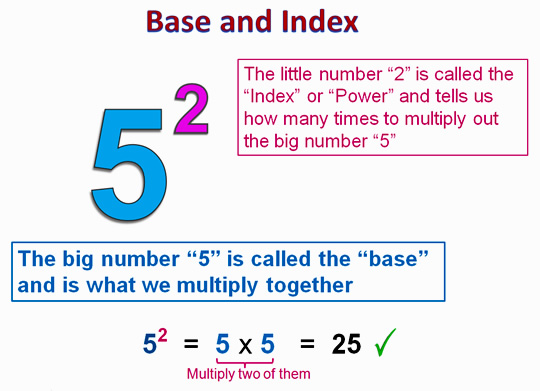
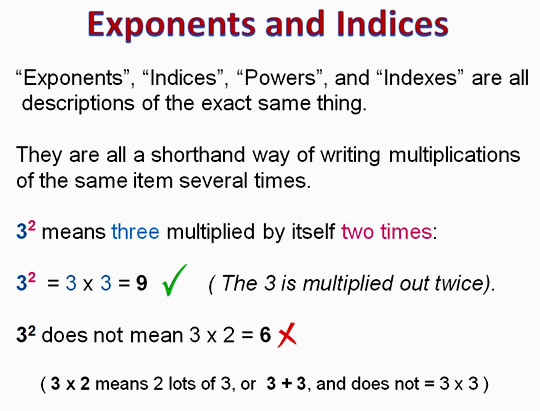
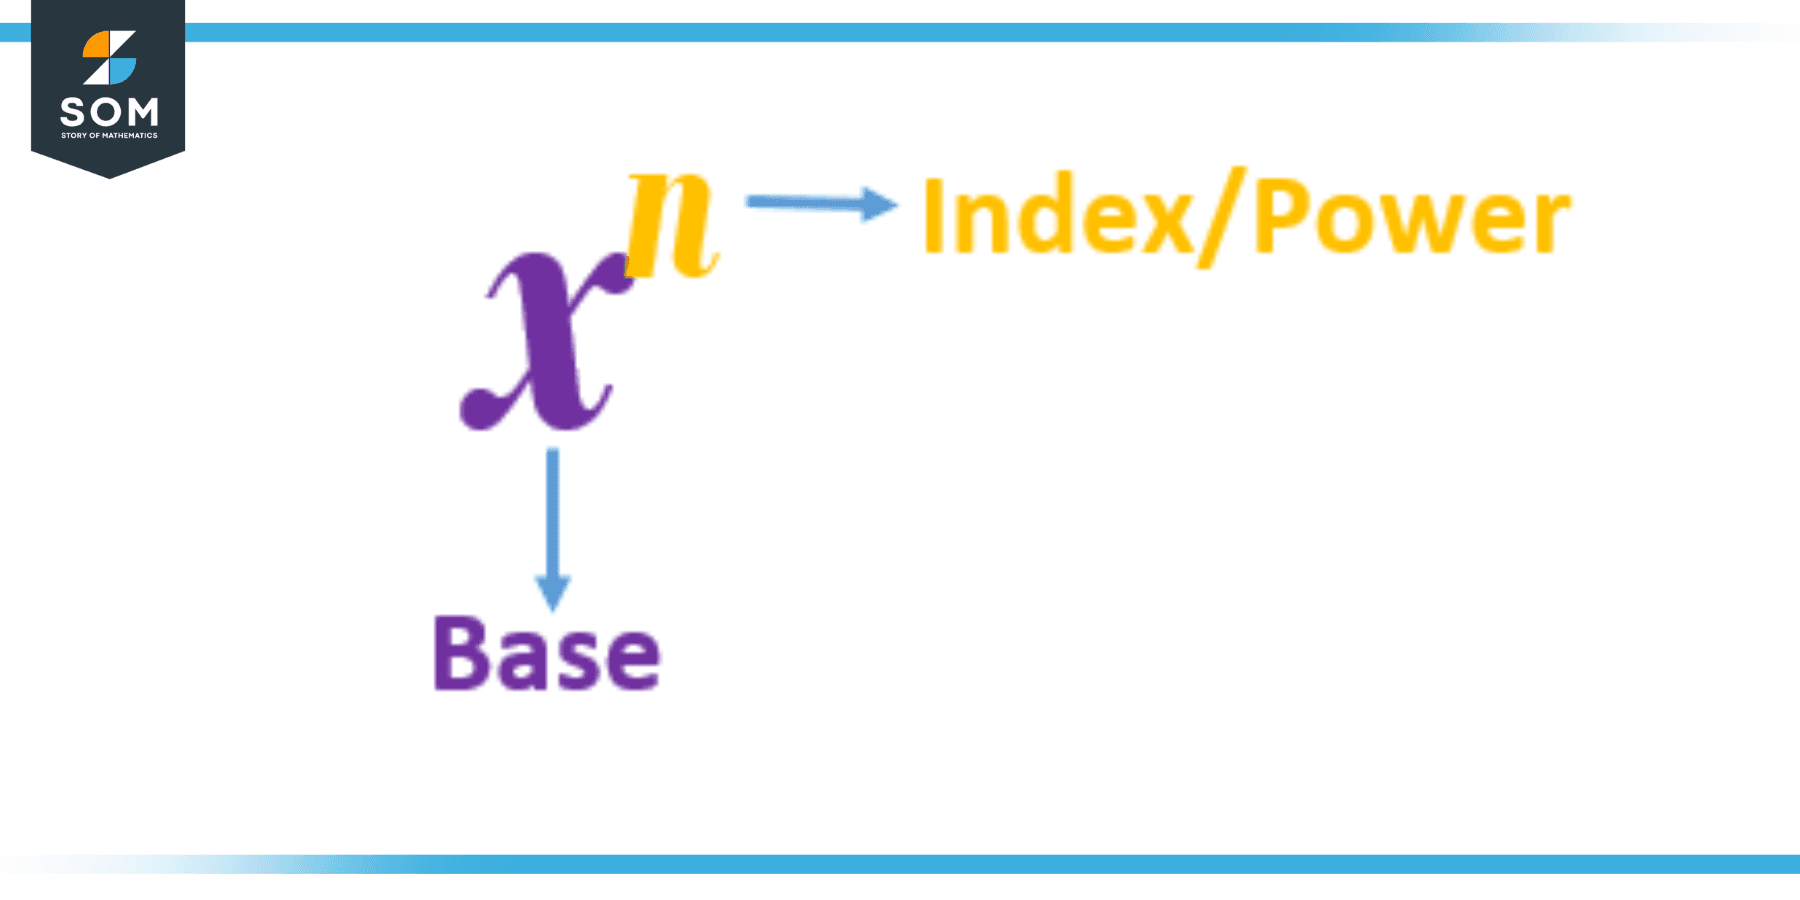
An index is just a shorthand notation for repeated multiplication. When you write a, the a is the base and the n is the index (also called the exponent). It means multiply a by itself n times. That's it. Nothing mystical about it. The notation gets old fast once you actually use it regularly, which is why people shorten it and start throwing around rules without really thinking about what they mean. You'll see textbooks present index laws as if they're discovered truth rather than convenient definitions we agreed on. They're both.
Definition Of Index In Math
In formal terms, the Definition Of Index In Math refers to the integer placed above and to the right of a base number indicating how many times that base is used as a factor in multiplication. It's a positional notation convention, not a standalone mathematical object. People sometimes confuse it with an exponent — they're the same thing in practice, though "index" is more common in British English and older texts while "exponent" dominates American usage. I ran into a real edge case once working on a signal processing problem where the index was negative and fractional simultaneously — something like 16^(-3/4). My first instinct was to just apply the laws mechanically, but that gave me garbage results because I hadn't separated the negative sign from the fraction properly. The fix was treating it as two operations in sequence: first handle the fraction by taking the fourth root and then cubing, then flip the result for the negative. So 16^(1/4) = 2, 2³ = 8, and the negative makes it 1/8. Took me about three hours of debugging a spreadsheet before I realized the issue was mine, not the calculator's. Most people would just guess and move on. That's not always the best strategy. The standard index laws are straightforward when you're dealing with positive integers. Multiply same bases? Add the indices. Divide? Subtract them. Raise a power to a power? Multiply the indices. These rules aren't arbitrary — they follow directly from what multiplication actually is. a³ × a² means (a×a×a) × (a×a), which is obviously a. The rule is just a compressed description of that fact.
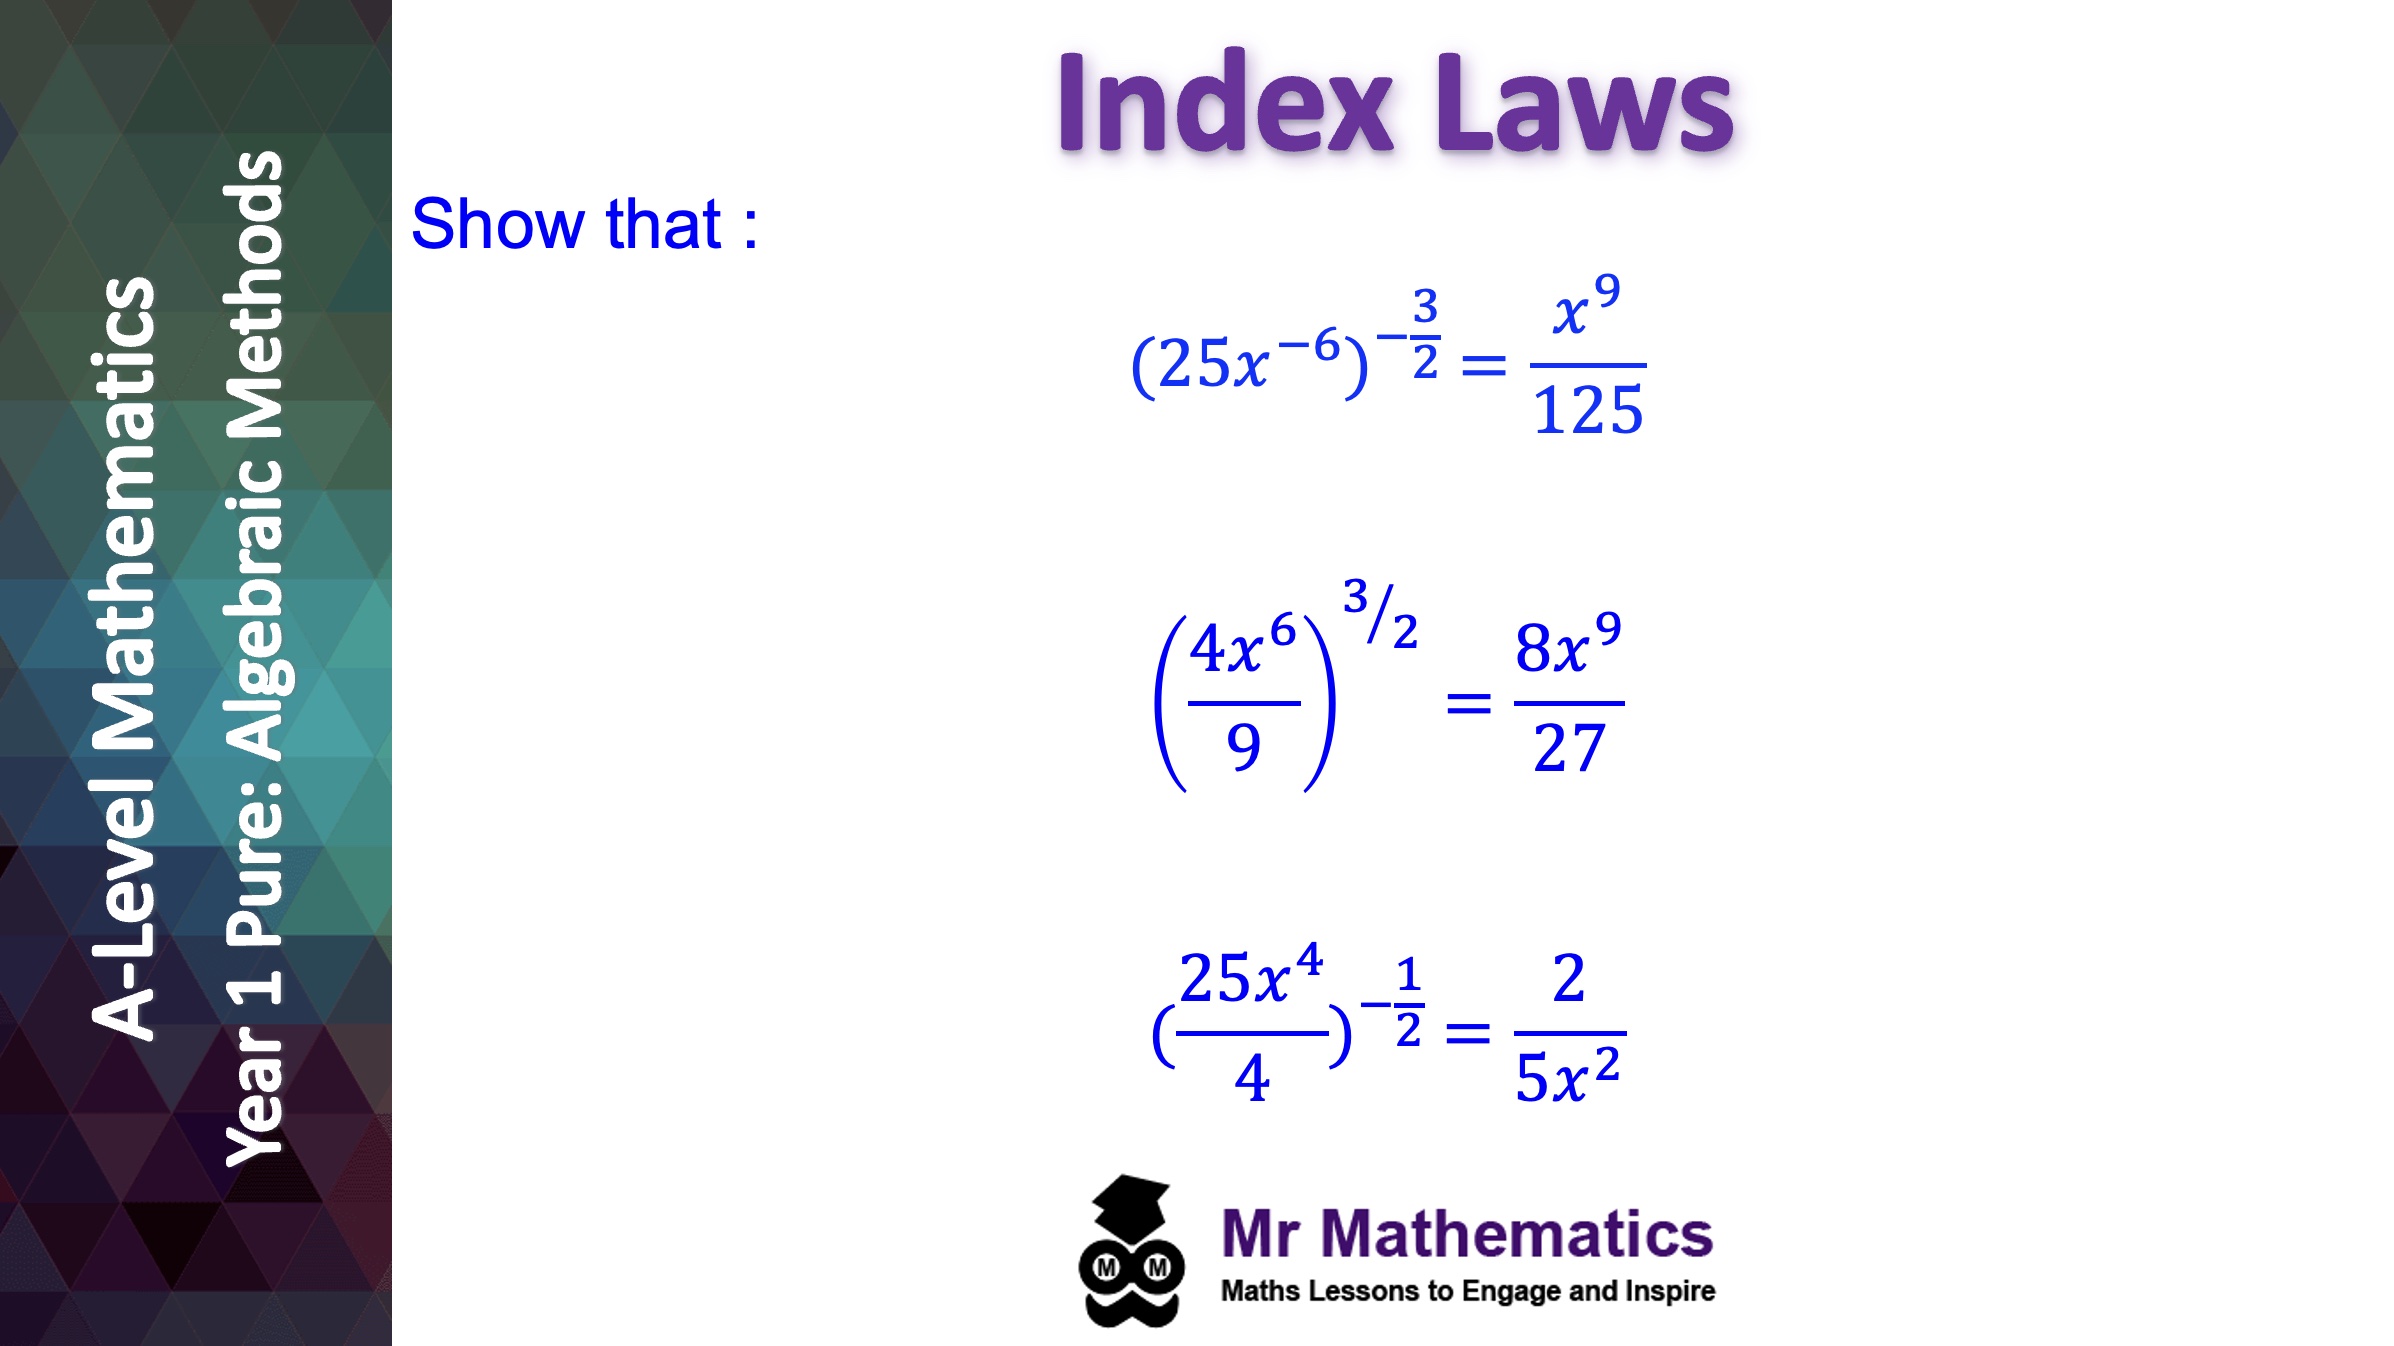
Here's where it gets messy though, and where most explanations gloss over it. The index laws break down or need careful modification when you introduce zero, negatives, fractions, or irrational numbers. And people don't always realize that. A zero index isn't a universal law — a = 1 only works when a is not zero. Zero to the zero is undefined, and calculators will often give you 1 anyway because they're following a convention, not doing actual math. I've seen this bite people in numerical analysis courses where they assumed 0 evaluated to 1 in a limit computation and got completely wrong answers because the left-hand and right-hand limits didn't match. Fractional indices are another area where beginners consistently make errors. The convention is that a^(m/n) means take the nth root of a and then raise it to the mth power. The order matters for computation but not for the final result — mathematically it's the same either way. In practice though, if you're working with large numbers by hand, it's usually easier to root first and then power, because the numbers stay smaller. Take 81^(3/4) for instance. Root first: 81^(1/4) = 3, then 3³ = 27. Power first: 81³ = 531441, then the fourth root of that. Both work, but one is considerably less painful. Negative indices flip the base to its reciprocal. a^(-n) = 1/(a). This is useful all the time in algebra and calculus, but people forget it because it's not intuitive at first glance. The reason it works is purely from the division law: a² ÷ a³ = a^(2-3) = a^(-1), and we also know a² ÷ a³ = 1/a. Therefore a^(-1) = 1/a. The negative index is just the division rule extended consistently beyond positive integers.
Get the Full Details
One counter-intuitive point that trips people up regularly: a larger index doesn't always mean a larger result. If your base is between 0 and 1, increasing the index actually makes the value smaller. 0.5¹ = 0.5, 0.5² = 0.25, 0.5³ = 0.125. The sequence converges toward zero. This seems backwards if you've only ever worked with bases greater than 1, but it's important for things like compound interest calculations with decay or probability chains where you're multiplying fractions repeatedly. Another thing that isn't obvious: indices don't distribute over addition. (a + b) is not the same as a + b. Everyone knows this at the basic level, but it becomes relevant again in more advanced work when you're estimating or approximating expressions and someone carelessly distributes the power across a sum. You need the binomial theorem for that, which expands to a + na^(n-1)b + ... and so on. For small n you can do it by hand. For large n you need a computer or a different approach entirely. Logarithms are essentially the inverse operation of indices. If y = a then x = log(y). This relationship is why index notation is so useful — it lets you convert multiplication problems into addition problems, which is exactly what logarithm tables were built for before calculators existed. The entire field of analytical chemistry and engineering calculations depended on this for decades. Slide rules were physical implementations of this principle.
The main limitation of index notation is that it doesn't handle non-integer, non-rational indices intuitively. What does 2^ actually mean? You can't multiply 2 by itself times because isn't a countable quantity. The formal definition involves infinite series or limits — specifically e^( ln 2). This is well-defined but completely invisible if you've only ever worked with integer indices. Most introductory courses never address this gap, so students end up with a model of exponents that's correct for rationals but breaks down for reals. Similarly, complex indices exist but require Euler's formula to make sense of. i^i is actually a real number, approximately 0.2079. This comes from writing i in exponential form as e^(i/2) and then using the index laws. It's a genuine curiosity that demonstrates the depth of the concept but has no practical application for most people learning the basics. If you're working with indices computationally, be aware that floating point arithmetic introduces errors. 2^(1/3)³ won't exactly equal 2 on a computer because 1/3 can't be represented exactly in binary floating point. You'll get something like 1.9999999999999998. This matters in numerical methods where small errors compound. The workaround is generally to keep expressions symbolic as long as possible and only evaluate numerically at the final step, or to use arbitrary precision libraries if your calculation demands it.
For learning purposes, the most practical approach is to internalize the five core index laws and practice applying them until they become automatic. Then learn the extensions to zero, negative, and fractional indices as unified generalizations rather than separate rules. The pattern is consistent: every extension preserves the existing laws rather than contradicting them. That's the key insight that most courses miss. Once you see that, index notation stops being a collection of memorized tricks and becomes a coherent system. A quick reference for the standard laws when a and b are non-zero and m and n are integers: a × a = a^(m+n)

a ÷ a = a^(m-n) (a) = a^(m×n) a = 1 (where a 0)
a^(-n) = 1/a a^(m/n) = (a) These hold for rational m and n as well, provided the roots exist in the real number system. Odd roots of negative numbers are fine. Even roots of negative numbers require moving into complex numbers, which is a different conversation entirely.