Plotting the Dependent Variable On Graph Without Losing Your Mind
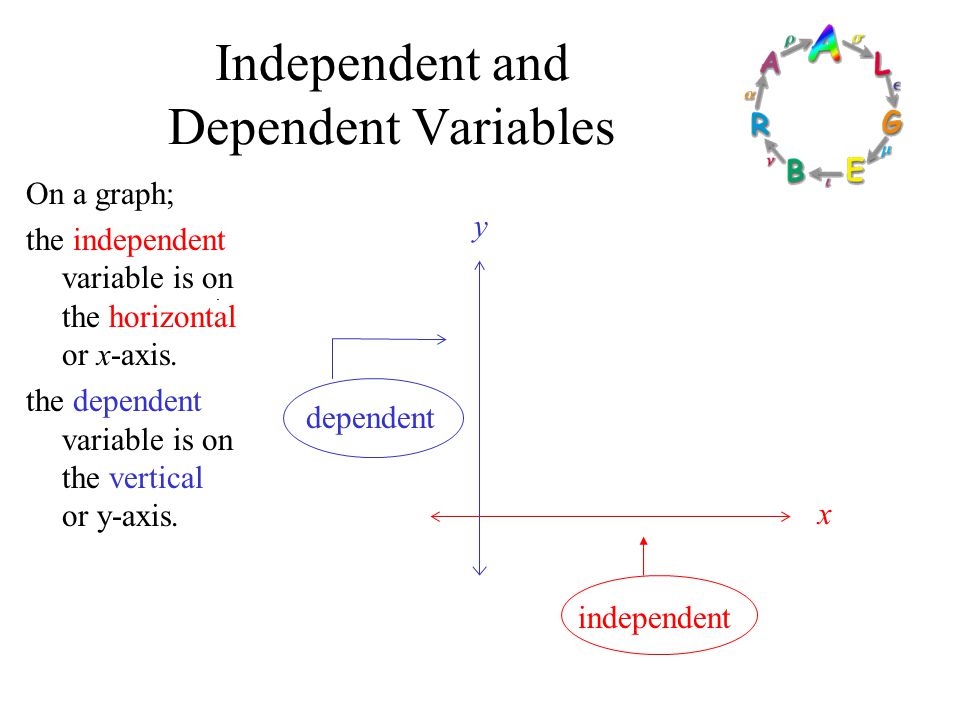
The dependent variable is the one you measure, not the one you change. That's the definition you'll find everywhere, but the real problem comes when you actually try to put it on a graph and everything starts looking wrong. I've been doing this for years and I still get tripped up by it occasionally. Here's the basic rule everyone knows: independent variable goes on the x-axis, dependent on the y-axis. The independent variable is what you control or manipulate. The dependent variable is what responds. Put them backwards and your graph becomes nearly useless for communicating anything, especially if someone else has to read it.
Setting Up a Dependant Variable On Graph Properly
Start by identifying which variable actually depends on the other one. Ask yourself: does this value change because I changed something else, or does it stand on its own? If you're measuring plant growth while varying the amount of fertilizer, growth is dependent on fertilizer amount. Growth goes on the vertical axis. Fertilizer goes on the horizontal axis. Label both axes with units. I can't stress this enough. A graph with "Time" on the x-axis and no unit specification is a guess. It could be seconds, minutes, hours. Same problem with the y-axis. When I was working on a lab report last year, my dataset had temperature in Celsius and the spreadsheet software labeled it just "Value" because I hadn't filled in the axis title properly. Took twenty minutes to trace back which column was which.
Common Mistakes That Make Graphs Misleading
The biggest issue I see is when people plot multiple dependent variables on the same graph without a clear distinction. Two y-axes look clever until someone misreads the scale and draws the wrong conclusion. If you need two dependent variables, use a secondary axis but make it visually obvious. Different color, different scale, a clear legend. Don't assume the viewer will figure it out. Another thing that causes problems is reversing the axes after you've already built the chart. The software lets you do it, but now your trend lines are calculated in the wrong direction and your correlation coefficient means something completely different. I learned this the hard way when I accidentally swapped the columns in Excel during a regression analysis. The r-squared value looked great until I realized I had flipped the variables. The relationship wasn't causal in the direction I thought it was.
Get the Full Details

Edge Case: When the Dependent Variable Doesn't Follow a Clean Pattern
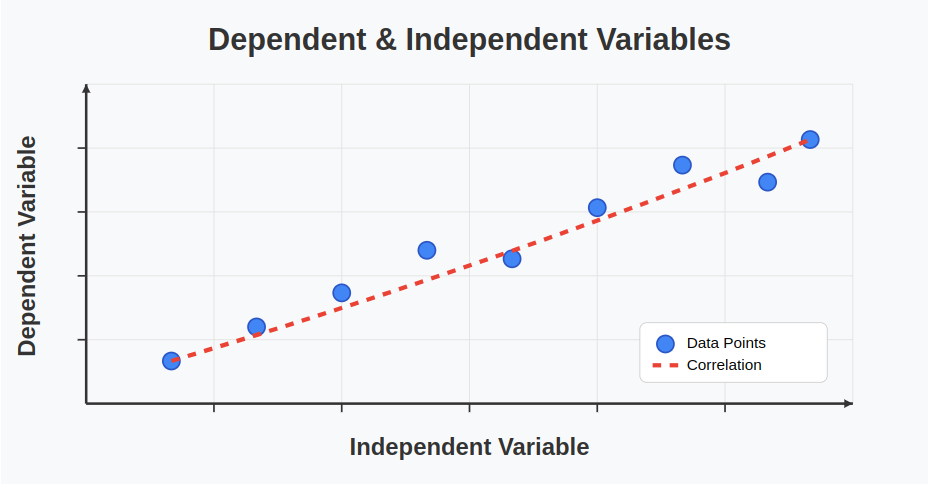
Sometimes your data points for the dependent variable scatter so much that the graph looks like noise. This happened to me with a dataset tracking reaction rates across different temperatures. The theoretical curve was smooth, but the actual measurements jumped around between 22 and 28 degrees. A standard line graph made it look like the dependent variable was completely unpredictable, which was frustrating for the report. The workaround was to plot each individual measurement as a point and then add a smoothed trend line using moving average rather than a linear regression. This showed the underlying pattern without pretending the data was cleaner than it actually was. The software does this with a right-click on the data series, but finding the right window size for the moving average took some trial and error. A window of 3 worked best for my dataset because it smoothed out the noise without hiding real variation.
Technical Details That Matter More Than People Think
The scale of your y-axis changes how the dependent variable appears. Starting the axis at zero versus starting at a nearby value can make the same data look dramatic or trivial. I always check this when reviewing graphs from other people. A graph that starts the y-axis at ninety percent of the minimum value makes tiny changes look like massive swings. This isn't always dishonest, but it's worth being aware of when you're interpreting someone else's Dependant Variable On Graph. Also consider the granularity of your dependent variable measurements. If you're measuring something that only comes in whole numbers, like counting organisms, a line graph connecting the dots implies precision that doesn't exist. A bar chart or scatter plot with no connecting line is more honest in those cases. The software defaults to line graphs for a reason, but the default isn't always the right choice.
When This Approach Breaks Down Completely
Linear graphs fail when your dependent variable spans several orders of magnitude. If your values range from 0.001 to 1000, a standard Cartesian plot will crush the small values into the x-axis and you'll see nothing. In those situations you need a logarithmic scale on the y-axis. Most graphing tools offer this as a simple setting, but not everyone knows to look for it. The tradeoff is that the axis labels become less intuitive and harder to read quickly. You gain accuracy in representation but lose immediate clarity. Another scenario where the standard approach doesn't work is when the dependent variable is categorical rather than numerical. Time series, temperature readings, weight measurements — these are all continuous. But something like customer satisfaction ratings on a scale of one to five is discrete and ordinal. Plotting this as a continuous dependent variable can imply relationships that aren't really there. A bar chart or even a heatmap works better for that kind of data. The core principle remains straightforward once you internalize it. Identify what changes in response to something else. Put that response variable on the vertical axis. Label everything. Check your scale. Don't let the software defaults make decisions for you without thinking about whether they fit your data.