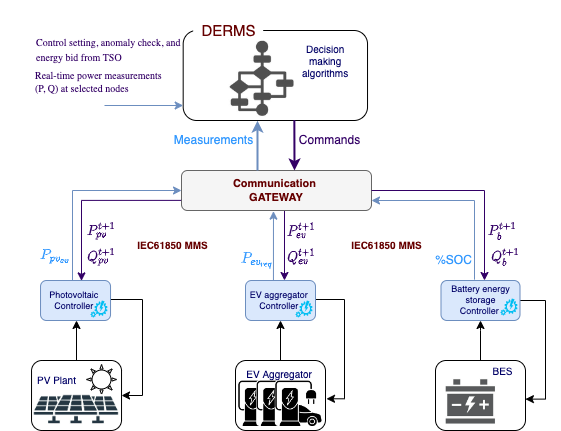
Getting Started with DERMS Architecture
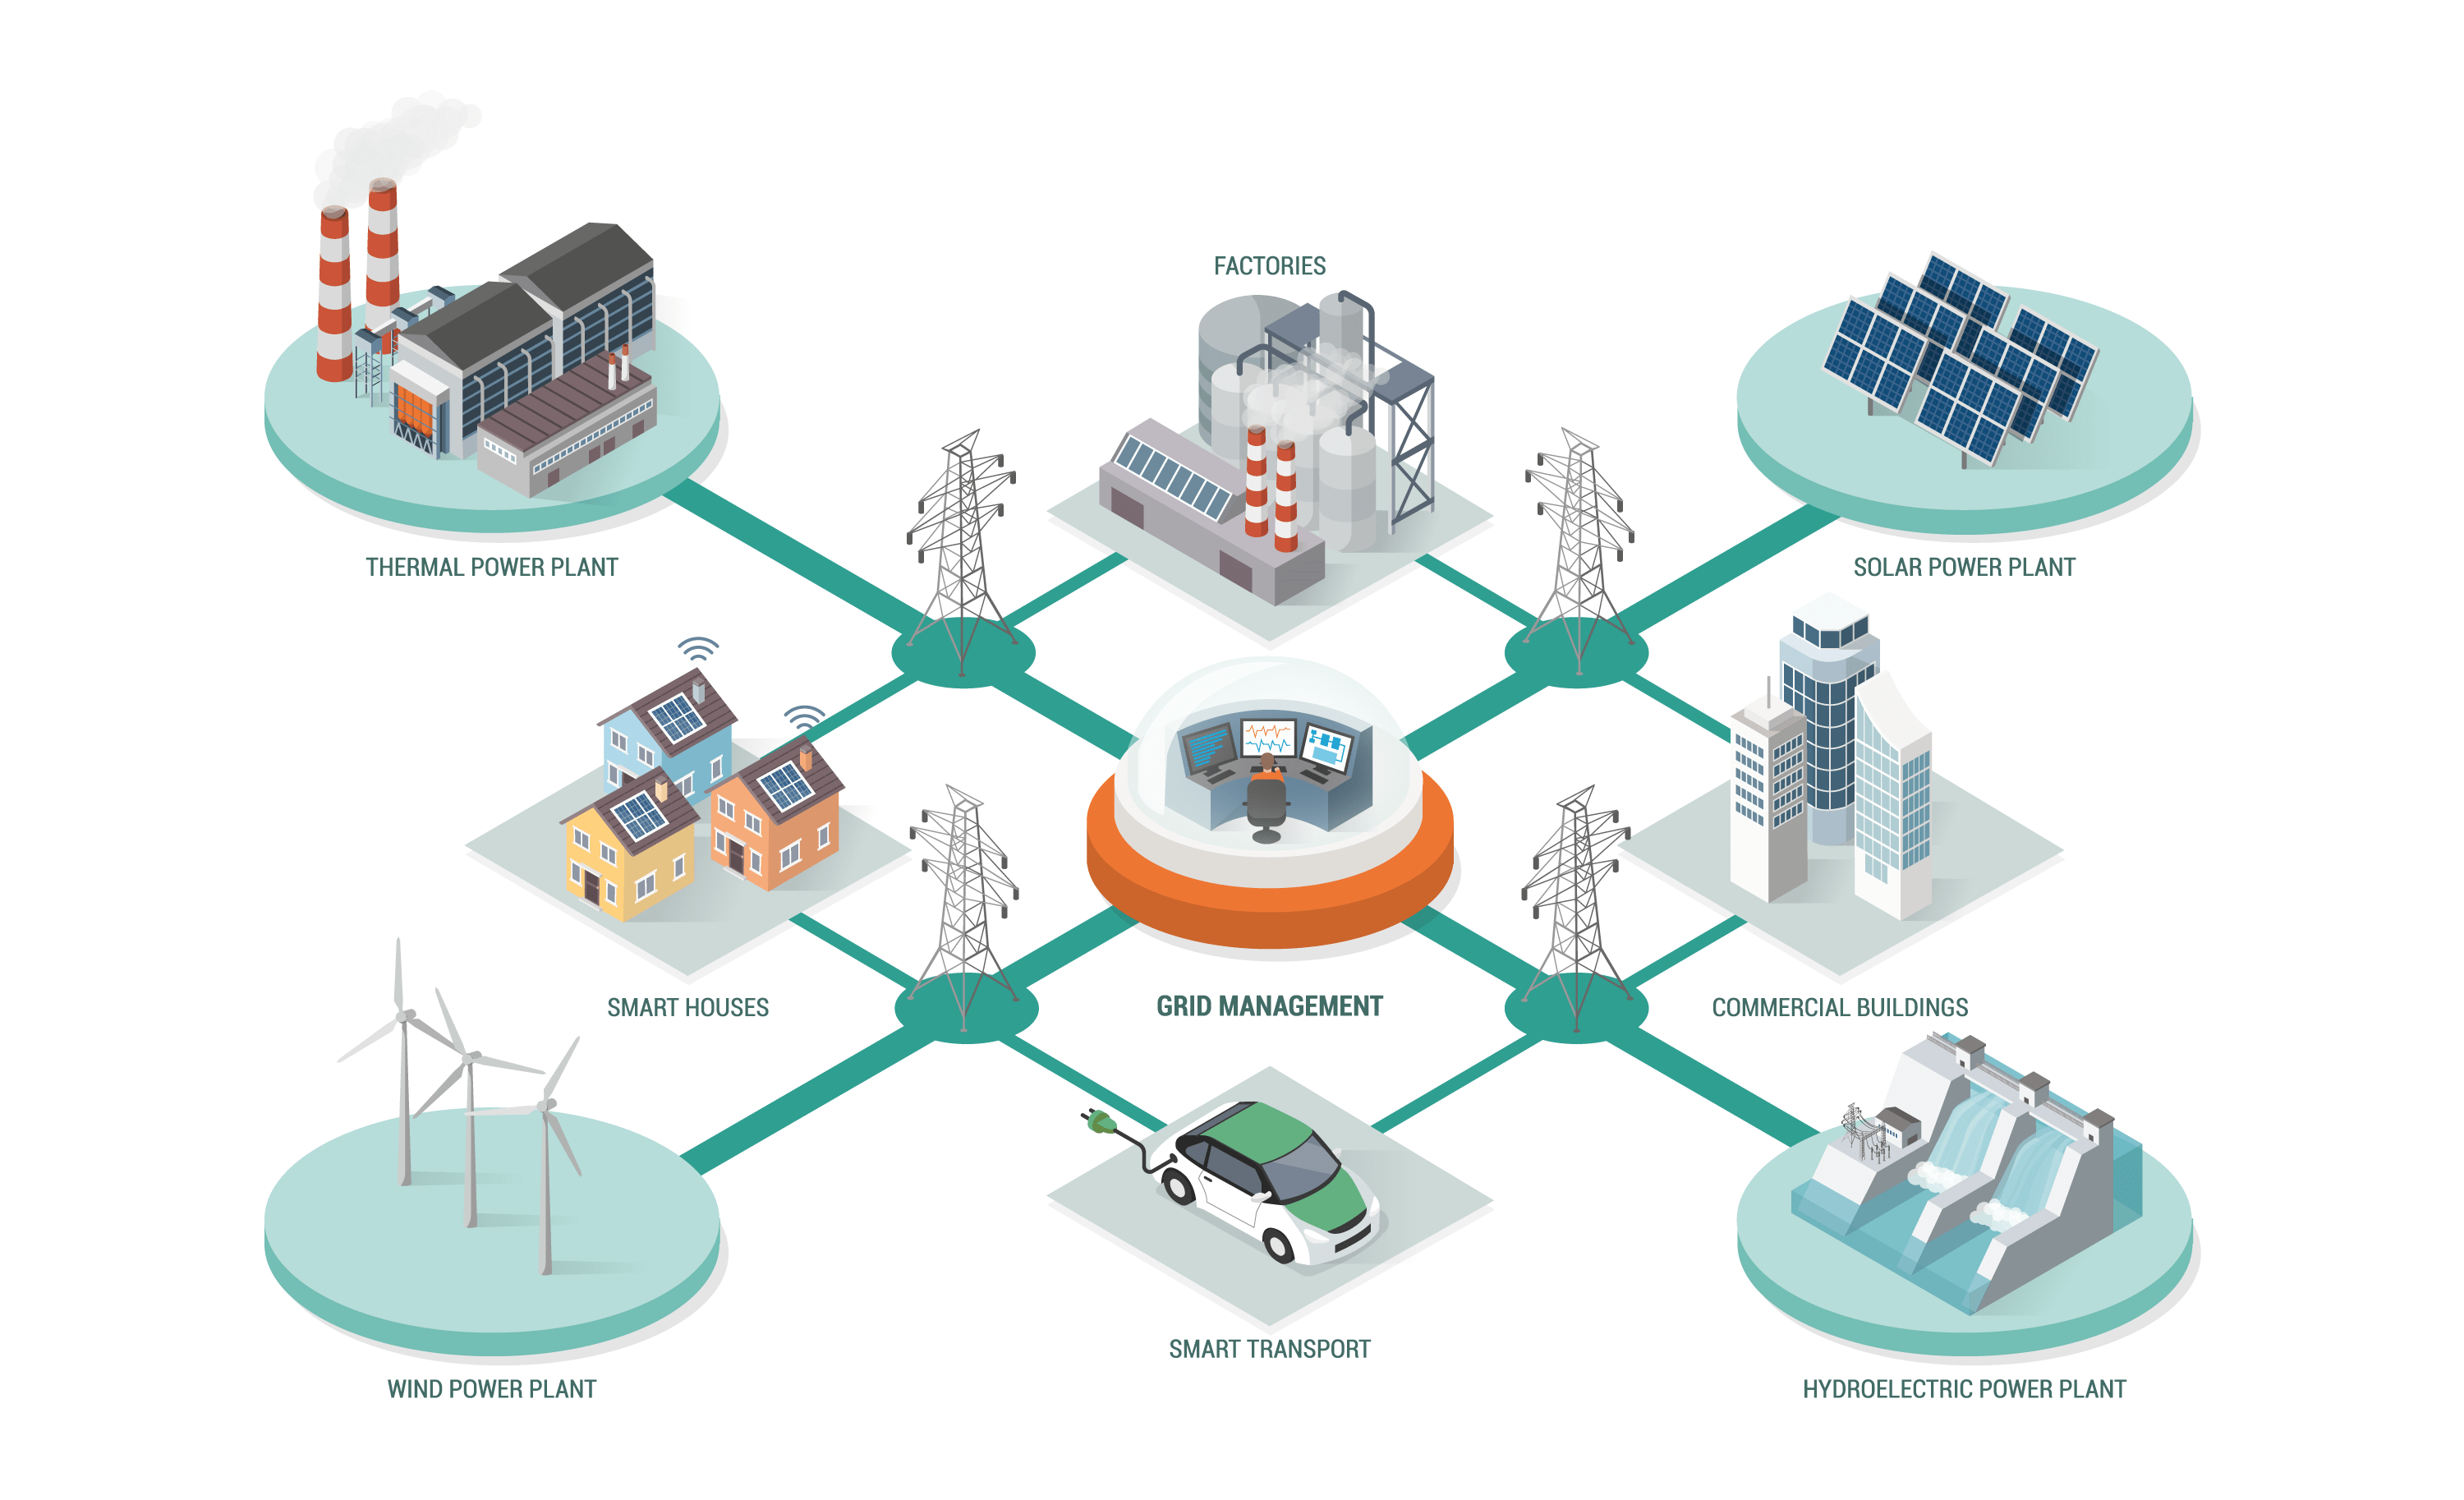
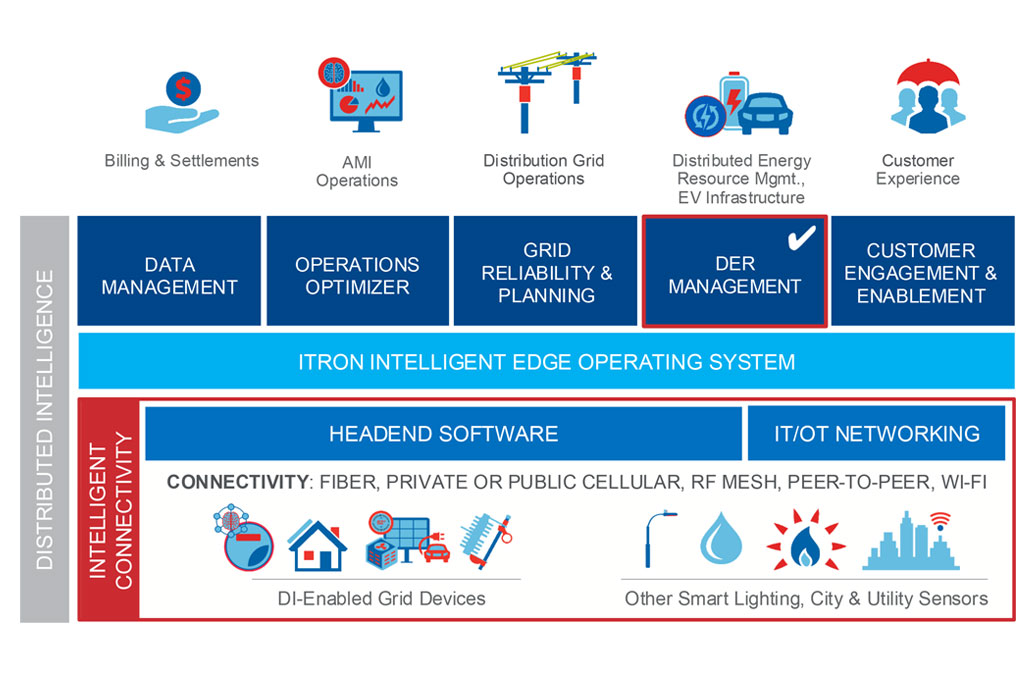
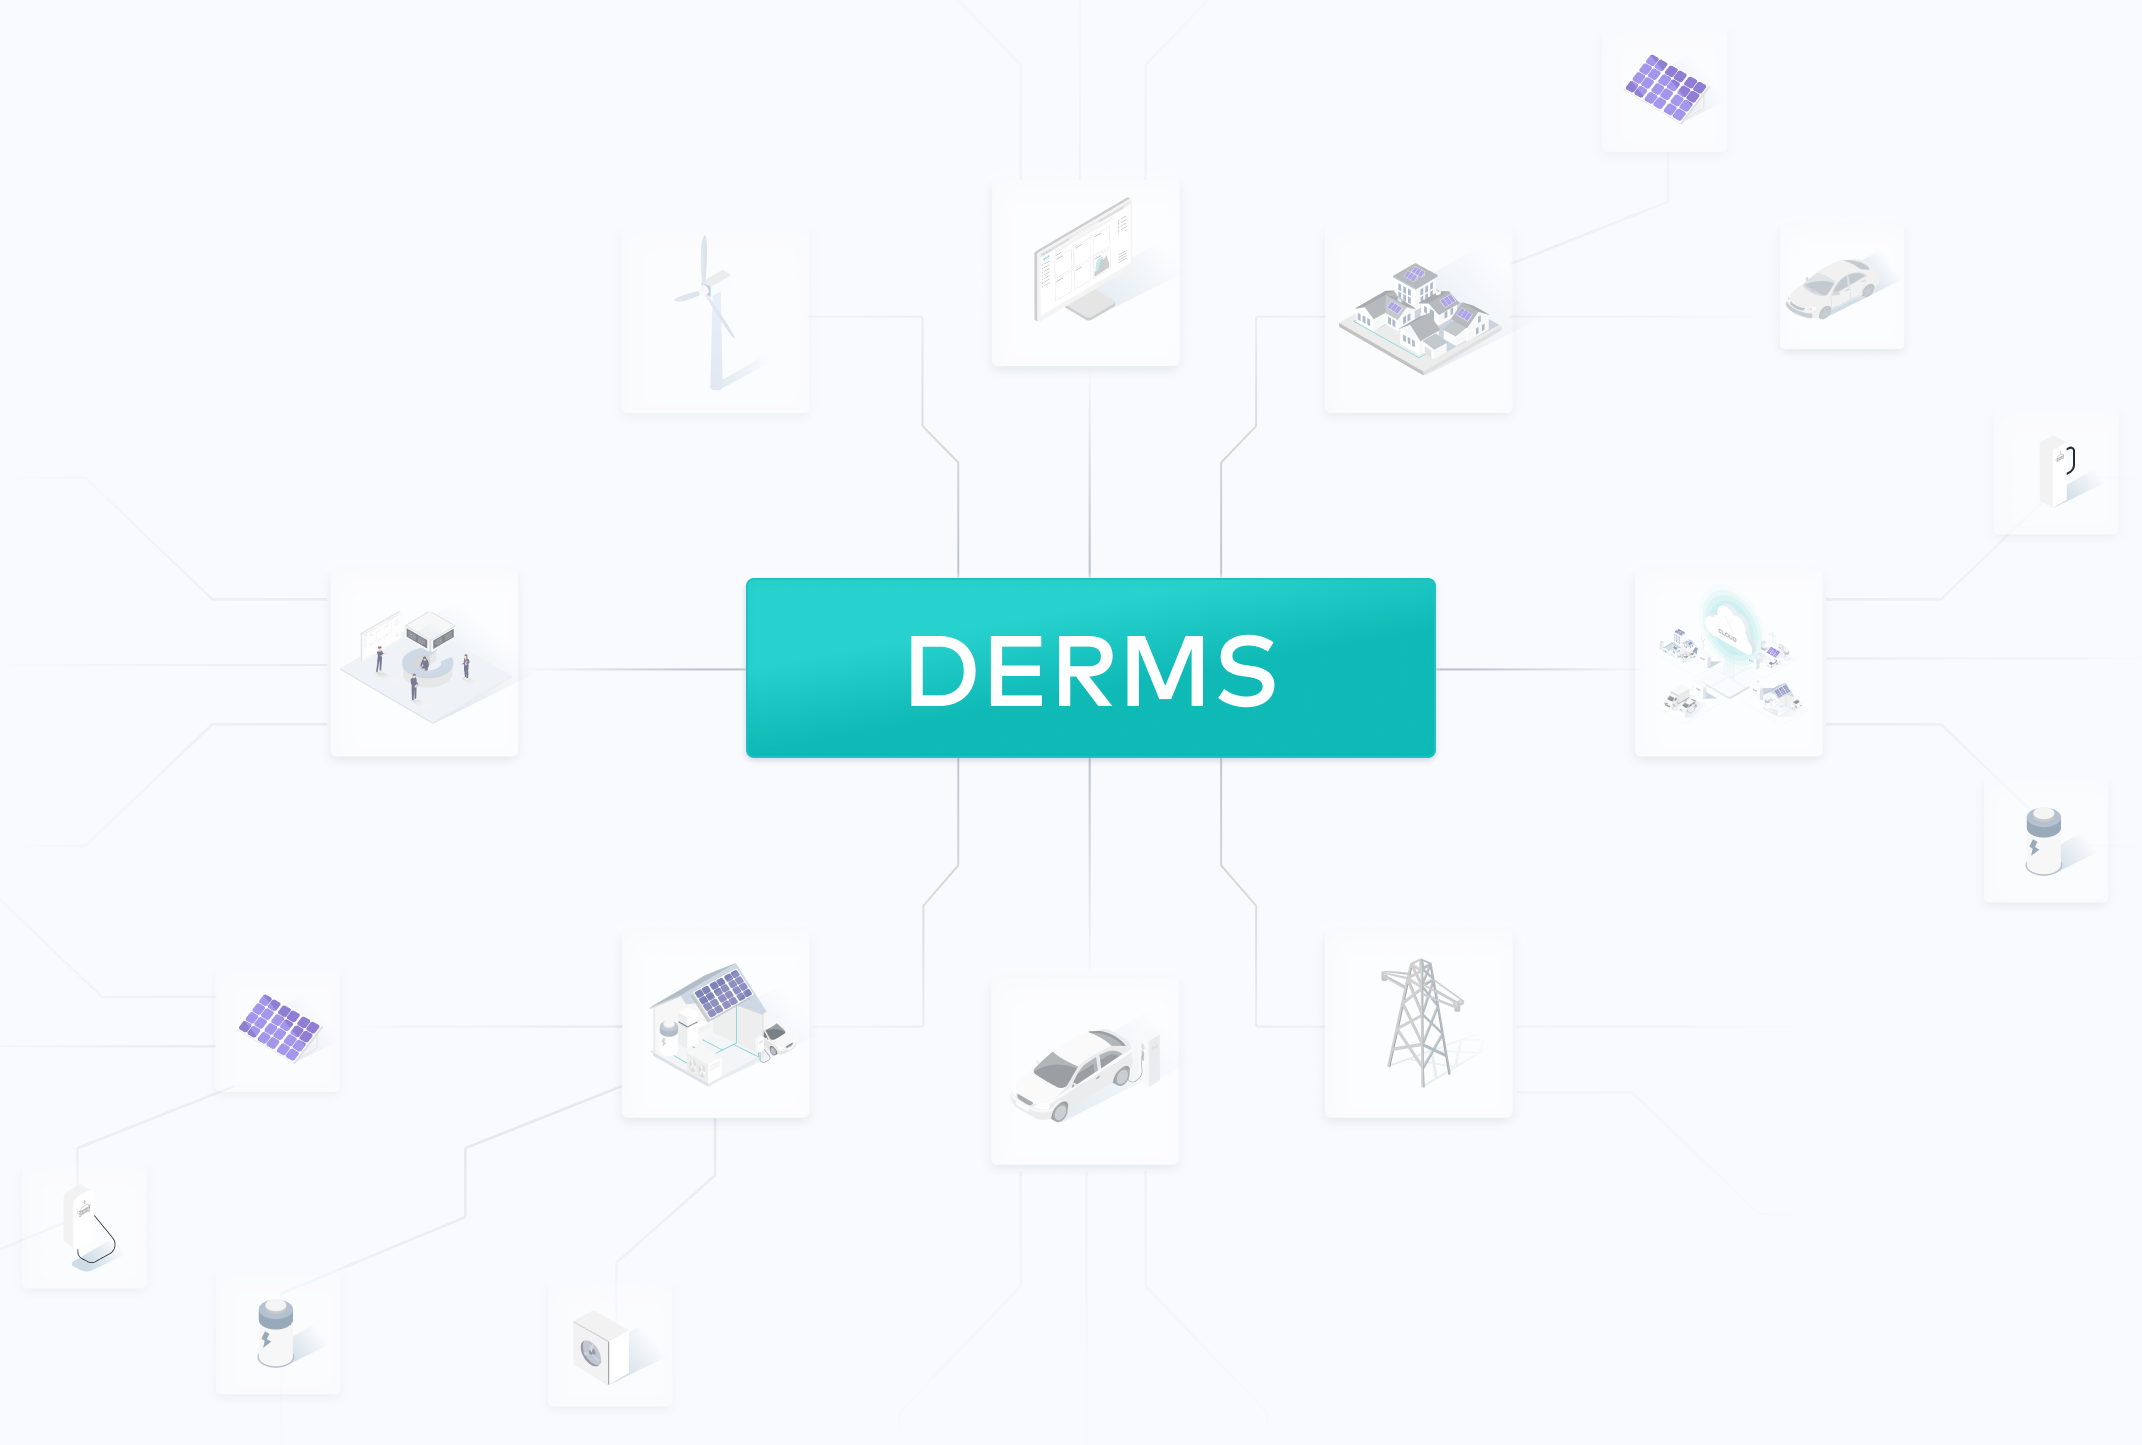
I spent about two years dealing with utility-scale distributed energy management systems before I stopped second-guessing my approach. The Derms Distributed Energy Management System is essentially a coordination layer that sits between distribution grid operators and fragmented behind-the-meter assets. It exists because you can no longer just dispatch power plants when demand spikes. The problem is the inverse — too many small resources sitting idle across a feeder, each with their own constraints, communications gaps, and willingness to participate. The basic architecture involves three components: the DERMS server that aggregates and optimizes, the communication middleware that translates between proprietary device protocols, and the endpoint devices themselves. What most people miss is that the middleware layer is where every project either succeeds or dies. I once watched a client spend 40,000 dollars licensing a commercial DERMS platform, then another 120,000 dollars in integration work because they assumed standard DNP3 support would cover everything. It did not. Their inverters spoke Modbus TCP, their battery controllers used SunSpec, and their thermostat fleet communicated over Zigbee. The middleware had to handle all three simultaneously while maintaining sub-minute telemetry refresh rates.
Derms Distributed Energy Management System Configuration
The configuration process is less intuitive than the documentation makes it sound. Here is the sequence that actually works in practice, not the one listed in the vendor manual. First, map your feeder topology. Not the GIS drawing. The actual one, with every transformer, switch, and fuse location verified on site. I learned this the hard way when a DERMS deployment in Georgia dispatched virtual power plant assets based on a feeder model that had been updated three times since the original engineering survey. The system attempted to curve-shape load on a circuit that had been reconfigured after a storm restoration. Two transformers overloaded within seven minutes. The workaround was building a real-time topology verification layer that cross-referenced SCADA state estimates against the DERMS model before any dispatch command executed. This added roughly 45 seconds to the optimization cycle but prevented another incident like that. Second, establish communication redundancy that is not purely theoretical. Most DERMS platforms advertise dual-path communication as a feature. In practice, this means having a cellular backup that fails over after three missed heartbeats from the primary fiber connection. That works until the cellular signal drops during peak demand events when every device in a five-mile radius is simultaneously trying to re-establish connections. I recommend implementing a staggered reconnection protocol with randomized backoff intervals starting at two seconds and doubling exponentially. This alone reduced communication flapping during our busiest summer events from approximately 600 disconnected-reconnect cycles per hour down to under 40.
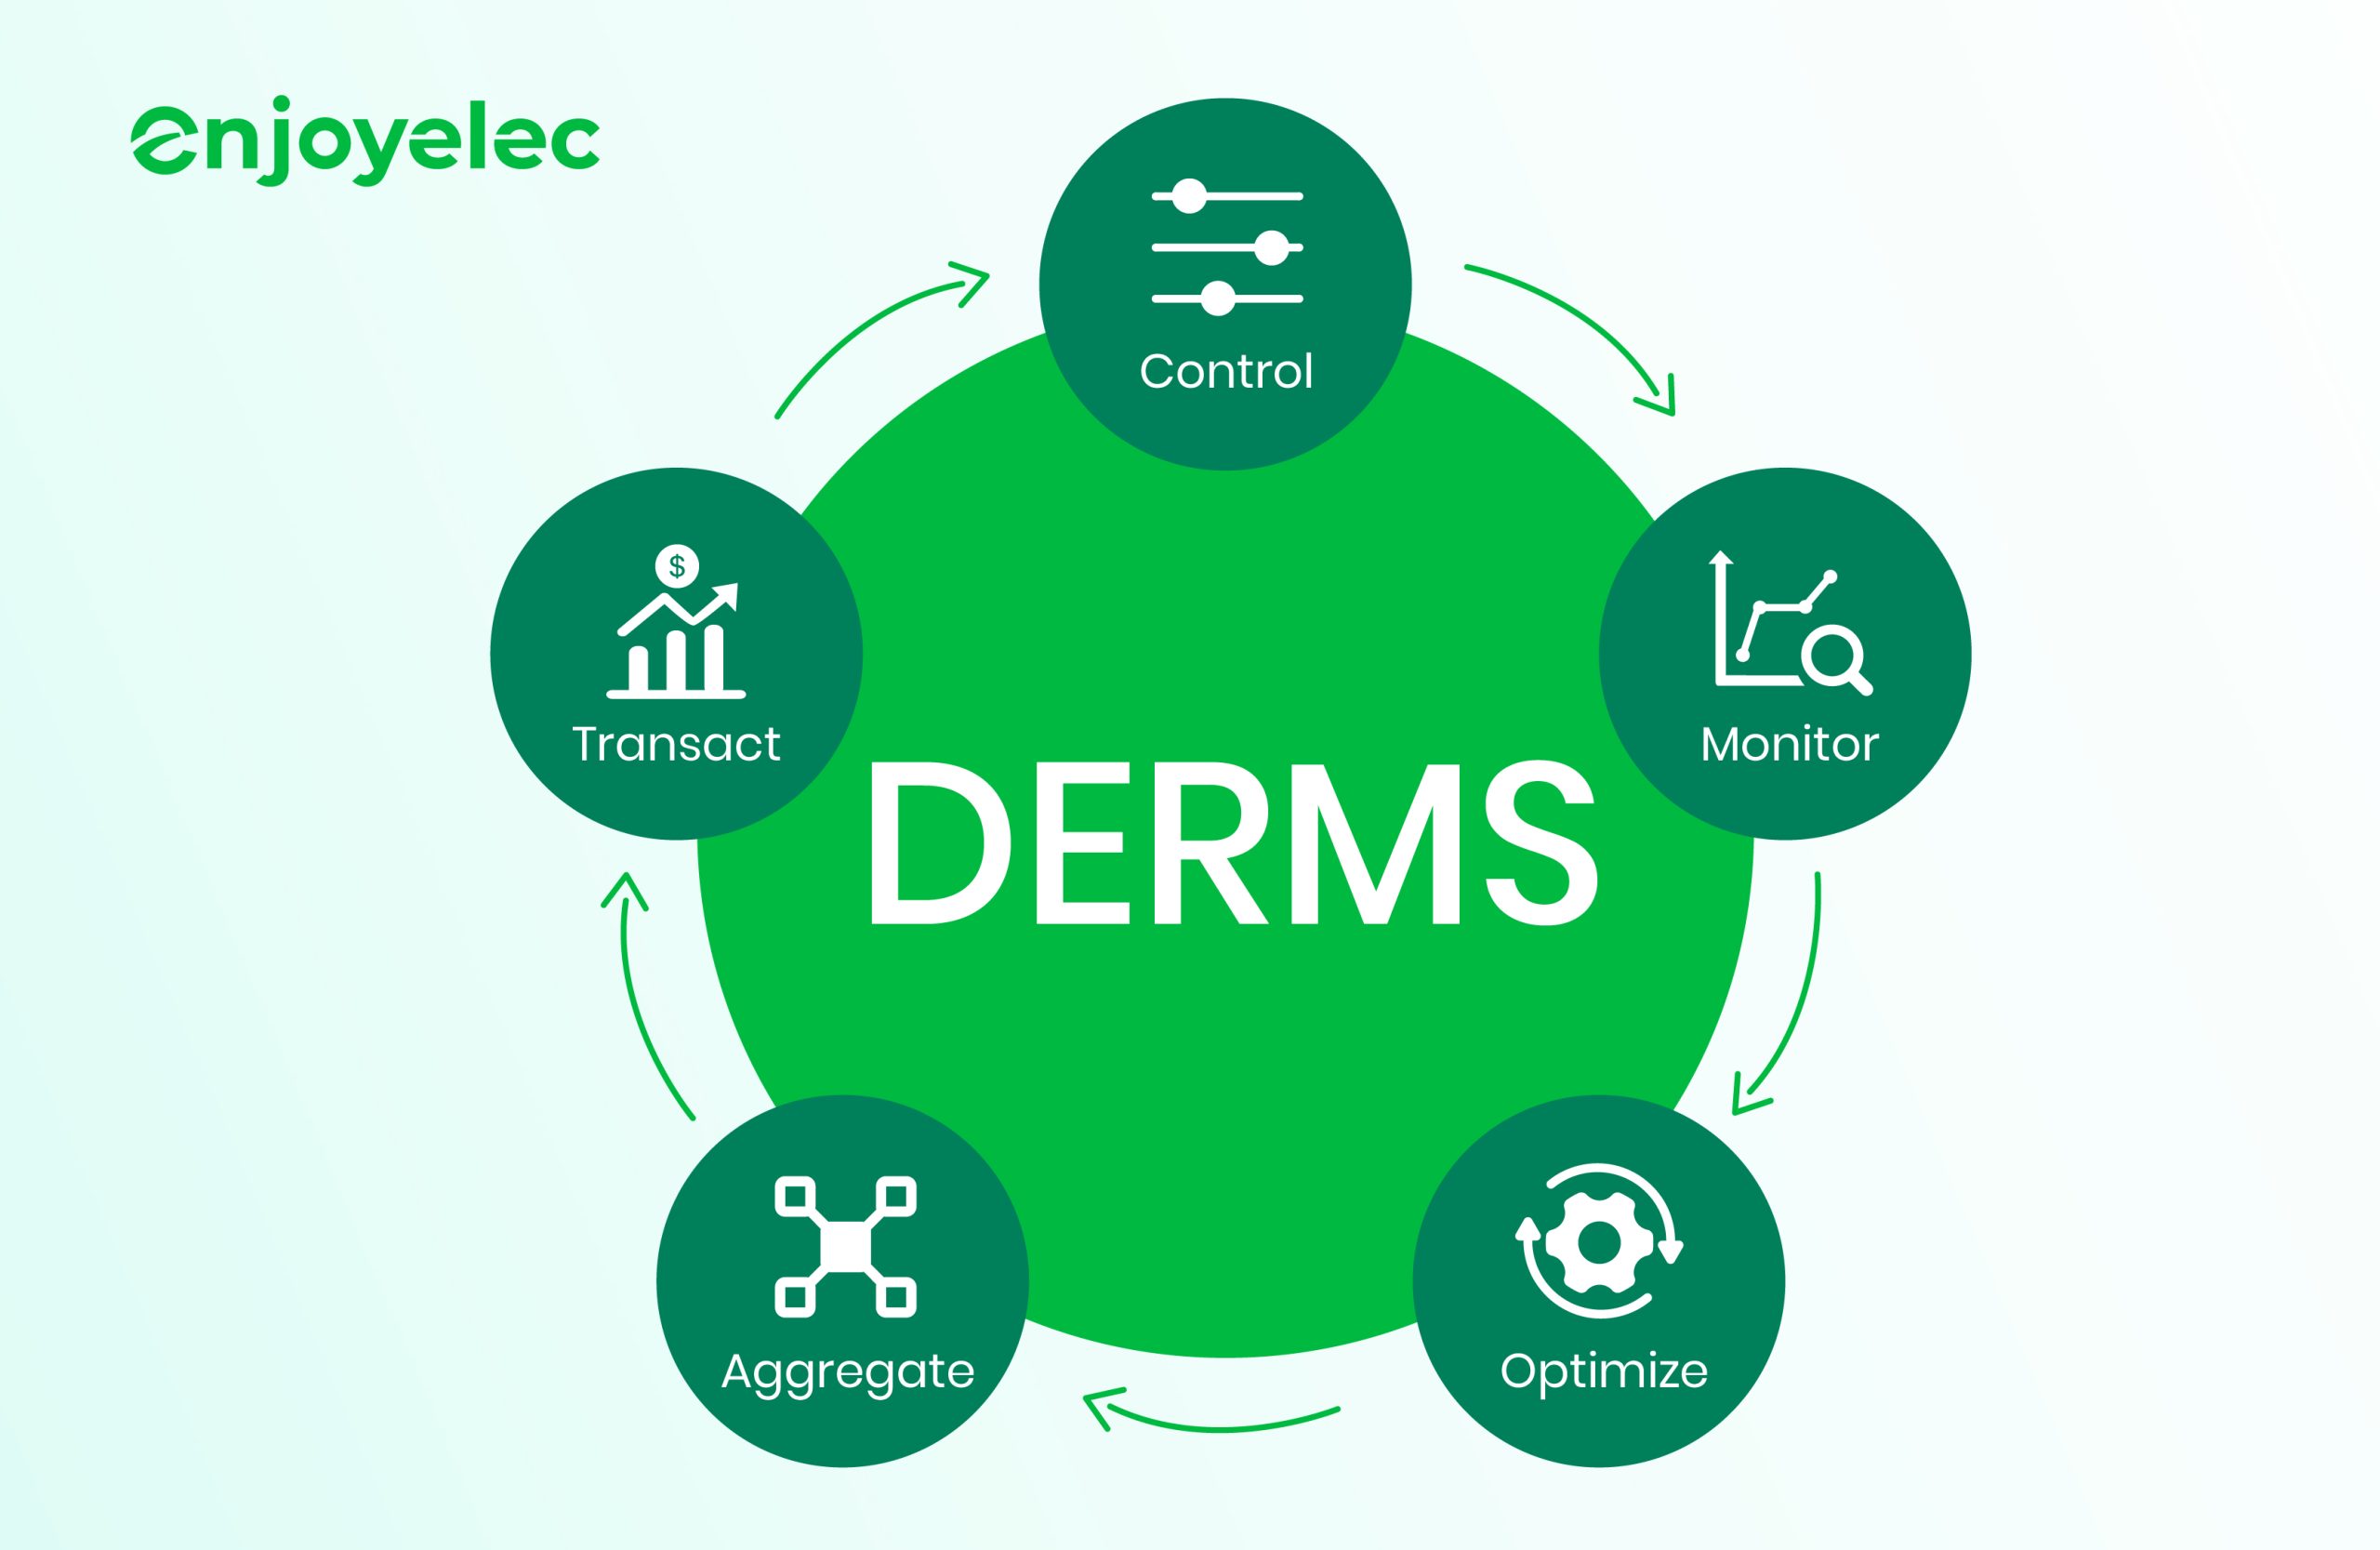
Third, define your dispatch objectives explicitly. DERMS platforms support multiple optimization strategies: peak shaving, voltage optimization, frequency regulation, and demand response. The problem is that these objectives frequently conflict. Peak shaving might require curtailing distributed generation at 2 PM, which raises voltage on the feeder and triggers your voltage optimization logic to do the opposite. The solution is creating a priority hierarchy with explicit tiebreaker rules, then documenting every exception scenario. I built a decision matrix that ran as a pre-dispatch check — it evaluated the current state of the feeder, identified which objectives were in tension, and selected the appropriate tradeoff based on preconfigured operator preferences. This reduced the number of dispatch conflicts requiring manual intervention from roughly eight per weekday to fewer than two.
Get the Full Details
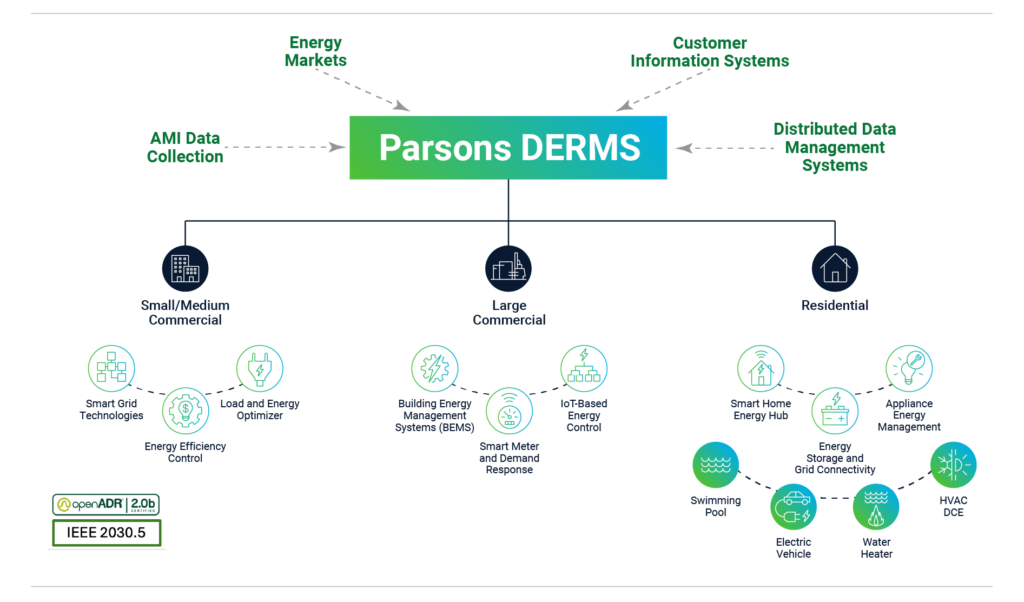
Operational Realities That Matter
DERMS platforms are not plug-and-play solutions. They require ongoing calibration, especially as the mix of connected assets changes. New solar installations shift voltage profiles on feeders that were calibrated for a different generation mix. Battery storage commissioning alters the available flexibility on circuits that were already optimized. I recommend running a full recalcibration every six months minimum, and after any feeder configuration change without exception. The data quality problem is real and underappreciated. DERMS optimization is only as good as the telemetry feeding it. I have seen platforms attempt dispatch calculations using telemetry that was 11 minutes stale because a communication gateway was misconfigured to batch-transmit data every 10 minutes instead of streaming. The optimization ran, the dispatch commands executed, and the results were essentially random relative to actual grid conditions. The fix was implementing a data freshness validation rule that flagged any optimization cycle using telemetry older than the configured freshness threshold — typically 60 seconds for real-time dispatch applications. Privacy and cybersecurity considerations are not optional. Every DERMS deployment connects to devices inside customer premises. Regulatory frameworks vary significantly by jurisdiction, and your data handling practices need to comply with whatever applies to your operating territory. I found that the most practical approach was implementing data anonymization at the endpoint level — aggregating and desensitizing customer-specific information before it left the communications gateway. This meant the DERMS platform saw feeder-level constraints and asset performance data without access to individual consumption patterns. It satisfied regulatory requirements and reduced liability exposure without meaningfully impacting optimization accuracy.
Common Failure Modes
The most common DERMS deployment failure I encountered was overestimating available participation from behind-the-meter assets. Vendors will tell you their platform can aggregate and dispatch thousands of residential inverters and smart thermostats. They can. The question is how many will actually respond consistently when called upon. In my experience, initial enrollment looks strong. Within 90 days, you typically lose 30 to 40 percent of enrolled assets due to connectivity issues, homeowner disinterest, or firmware updates that break compatibility. By day 180, the effective fleet size stabilizes at roughly 50 to 60 percent of original enrollment. Planning around the initial numbers rather than the stabilized figure is a reliable way to underperform during actual grid events. Another failure mode is treating DERMS as a standalone solution rather than a component within a broader grid modernization strategy. The system works best when integrated with existing distribution management systems, advanced metering infrastructure, and outage management platforms. Standalone DERMS deployments tend to create data silos and coordination gaps that reduce effectiveness. If you are deploying DERMS, budget for the integration work separately. It usually runs 20 to 30 percent of the total project cost and is frequently the line item that gets cut first. There are alternatives worth considering depending on your specific constraints. For smaller utilities or cooperative systems with limited distribution network complexity, a simpler load forecasting and manual dispatch approach may deliver adequate results at a fraction of the cost. For operators managing hundreds of megawatts of distributed resources across complex multi-vendor environments, DERMS becomes necessary but requires dedicated operational staffing that many organizations underestimate. The sweet spot tends to be utilities managing between 50 and 300 megawatts of potential distributed energy resources with moderate feeder complexity and existing SCADA infrastructure.
The technology has improved noticeably over the past few years. Communication reliability, optimization algorithms, and vendor support are all better than they were a decade ago. But the fundamental challenges remain the same: imperfect data, changing asset compositions, and the gap between what a platform can do in demonstration mode versus what it delivers during an actual grid stress event. Approach implementation with realistic expectations, budget appropriately for integration and ongoing calibration, and plan for the operational realities that documentation rarely mentions.