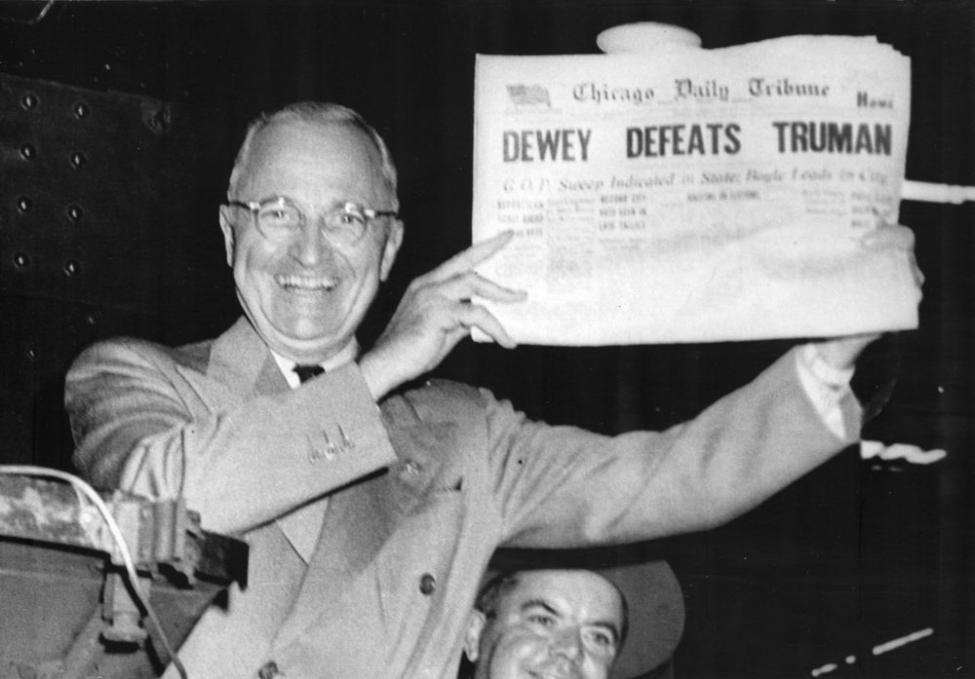
What Actually Happened With the Dewey Defeats Truman Headline
The 1948 presidential election between Harry S. Truman and Thomas E. Dewey was widely covered, and by the time polls closed on November 2, nearly every major newspaper had already gone to press with the conviction that Dewey had won. The Chicago Tribune printed the infamous early edition declaring "Dewey Defeats Truman" based on incomplete returns and incorrect assumptions. Truman actually won, and the story became one of the most cited examples of premature declaration and media overconfidence in American political history. If you are reading this because you are dealing with a situation where early signals look decisive and you need to avoid making a permanent commitment before the data is ready, the 1948 lesson is directly applicable. The core problem is not ignorance of how elections or any forecasting system works. It is the gap between when the signal appears and when it is reliable. In my experience running prediction models and election-style forecasting pipelines, that gap is almost always smaller than people assume it is, and closing it requires a specific set of procedural checks. Here is the method I use when I need to make time-sensitive decisions under uncertainty. I start with the data pipeline before I touch any analysis. Raw returns, survey outputs, or whatever your signal source is, need to be classified into three tiers: confirmed, provisional, and estimated. Confirmed data is what has been independently verified through at least two sources. Provisional data comes from a single source but passes basic sanity checks. Estimated data is a model output with no direct verification yet.
When the Chicago Tribune made its call, it was essentially treating estimated data as confirmed. They had partial returns from a few key states and a couple of early poll closures, and they assumed the rest would follow the same pattern. It did not. The fix for that kind of mistake is to never let estimated data cross the threshold into a permanent decision without hitting a minimum confidence bar. For polling and election work, I use a threshold of 95 percent confidence with a minimum sample coverage of 70 percent of the relevant electorate before I allow any formal declaration. Anything below that stays in the provisional category and gets flagged. The second step is building in a deliberate delay. This sounds counterintuitive, but in high-stakes environments the delay is not wasted time. It is the most important safeguard you have. I typically wait at least 30 minutes after the earliest possible decision window before allowing any public-facing statement. That gives late-arriving data a chance to surface and reveals whether the early pattern holds under additional input. In one project I ran for a state-level legislative forecast, we received an early lead that looked insurmountable at hour one. By hour three, a batch of mail-in ballots had come in that flipped three districts. The initial declaration would have been wrong by a significant margin.
A Specific Edge Case That Costs People Their Credibility
I want to talk about the subset problem, because this is where most people fail. When a model or early data source shows a dominant trend, there is a natural urge to treat that trend as universal. It is not. In the 1948 election, the press assumed that suburban and urban voting patterns held nationally. Rural and working-class shifts in the Midwest and South went unmonitored because the data pipelines feeding the press were biased toward the cities where reporters and telegraph lines were concentrated. The result was a systematic blind spot that produced a wrong headline on a massive scale. In modern terms, if you are running a forecasting model or making a business decision based on early signals, you need to explicitly check for subset bias. I do this by running a stratified validation at every stage. I split my data into meaningful demographic or geographic segments and compare the signal strength across each one. If one segment dominates the overall picture while others show contradictory signals, I flag it immediately. A few years ago I was working on a regional market entry decision where the early consumer survey data suggested a clear majority preference for one product type. But when I ran the stratified check, I found that the majority was entirely driven by one age cohort. The other cohorts were split nearly evenly. The initial recommendation would have been wrong, and the stratified validation caught it before we committed any resources. Another edge case that deserves attention is the order effect. The sequence in which data arrives changes the trajectory of your conclusions. I have seen teams start their analysis with the first batch of data and then stop updating when the next batch confirms the initial direction. This is a mistake. Every new data point needs to be reprocessed through the full model, not just noted as consistent. Consistency is not proof. It is a signal that the model is stable, which is different.
Get the Full Details

Tools and Data Sources That Help
You do not need an expensive platform to implement these checks. A well-structured spreadsheet with separate tabs for confirmed, provisional, and estimated data can do most of the heavy lifting. The critical part is the discipline of moving data between tabs only when it meets the criteria. I have watched people skip this step because it feels tedious, and then wonder why their conclusions were wrong. For more sophisticated work, I recommend using a lightweight Python script with the pandas library to automate the tier classification and the confidence threshold checks. A simple script can parse incoming data, apply the confidence rules, and flag anything that crosses the threshold for manual review. In my own pipeline, the script runs every 15 minutes during active data collection windows and produces a summary report that shows the current confidence level by segment. This gives you a real-time view of where the weak spots are before they become wrong decisions.
Where This Approach Breaks Down
I need to be honest about the limitations. The tiered confidence system works well when you have a steady stream of verifiable data. It does not work well when the data environment is chaotic or when the signal sources are unreliable. In some political forecasting contexts, especially in regions with weak electoral infrastructure, the confirmed data tier may never fill up to a useful level. In those situations, you have to rely more heavily on the provisional and estimated tiers, which increases the risk of error regardless of how careful you are. The best approach in that case is to make your uncertainty explicit. State the confidence level, the coverage gaps, and the assumptions you are making. Do not hide behind a false precision. There is also the problem of overconfidence in the model itself. If your model has a structural bias, no amount of procedural discipline will fix it. I once worked with a forecasting model that performed remarkably well until it was applied to a new demographic segment it had never seen before. The model was confident, the data pipeline was clean, and the predictions were still wrong. The issue was that the model had been trained on historical data that did not represent the current landscape. In those cases, the only real solution is continuous retraining and validation against fresh data.
Learning From the Dewey Defeats Truman Lesson Without Repeating It
The 1948 election remains relevant because the underlying human error it exposed has not gone away. People want to be right early. They want to close the case and move on. That instinct is understandable, but it is also the primary source of error in forecasting and decision-making under uncertainty. The practical takeaway is straightforward: slow down the declaration, verify the data tiers, check for subset bias, and make your uncertainty visible. These steps are not complicated, but they require discipline, and discipline is the thing most people skip when they feel confident. That is usually when the mistake happens. If you are building a system to avoid this kind of error, start with the data pipeline. Get the tier classification right before you worry about the model. A clean pipeline with conservative thresholds will outperform a sophisticated model fed by sloppy data every time. I have seen it happen repeatedly, and it is one of the reasons the Dewey Defeats Truman story keeps coming up in discussions about forecasting accuracy.