Testing Manual Dexterity in Engineering Environments
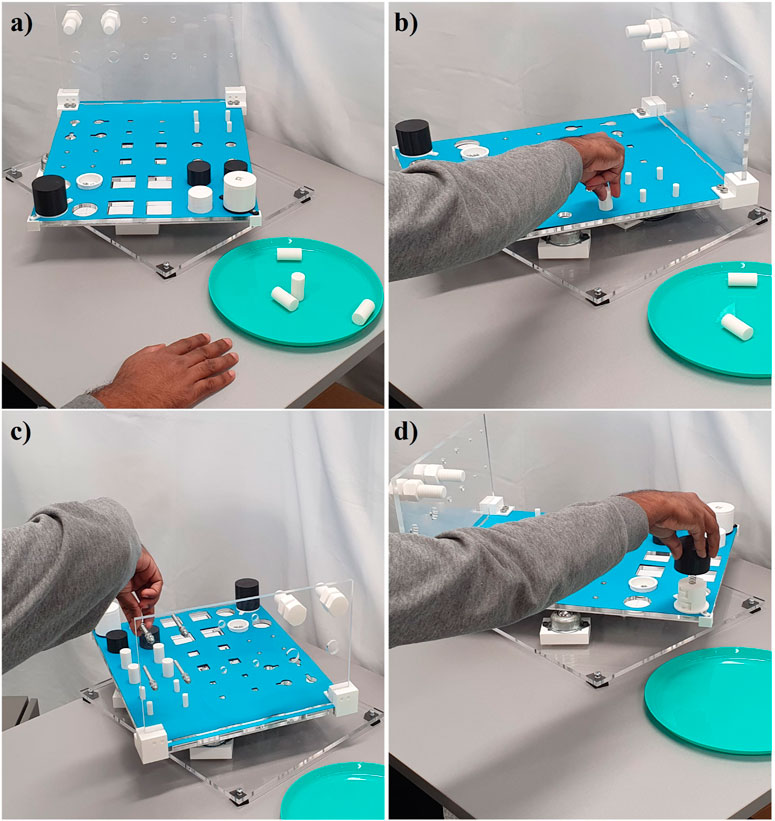
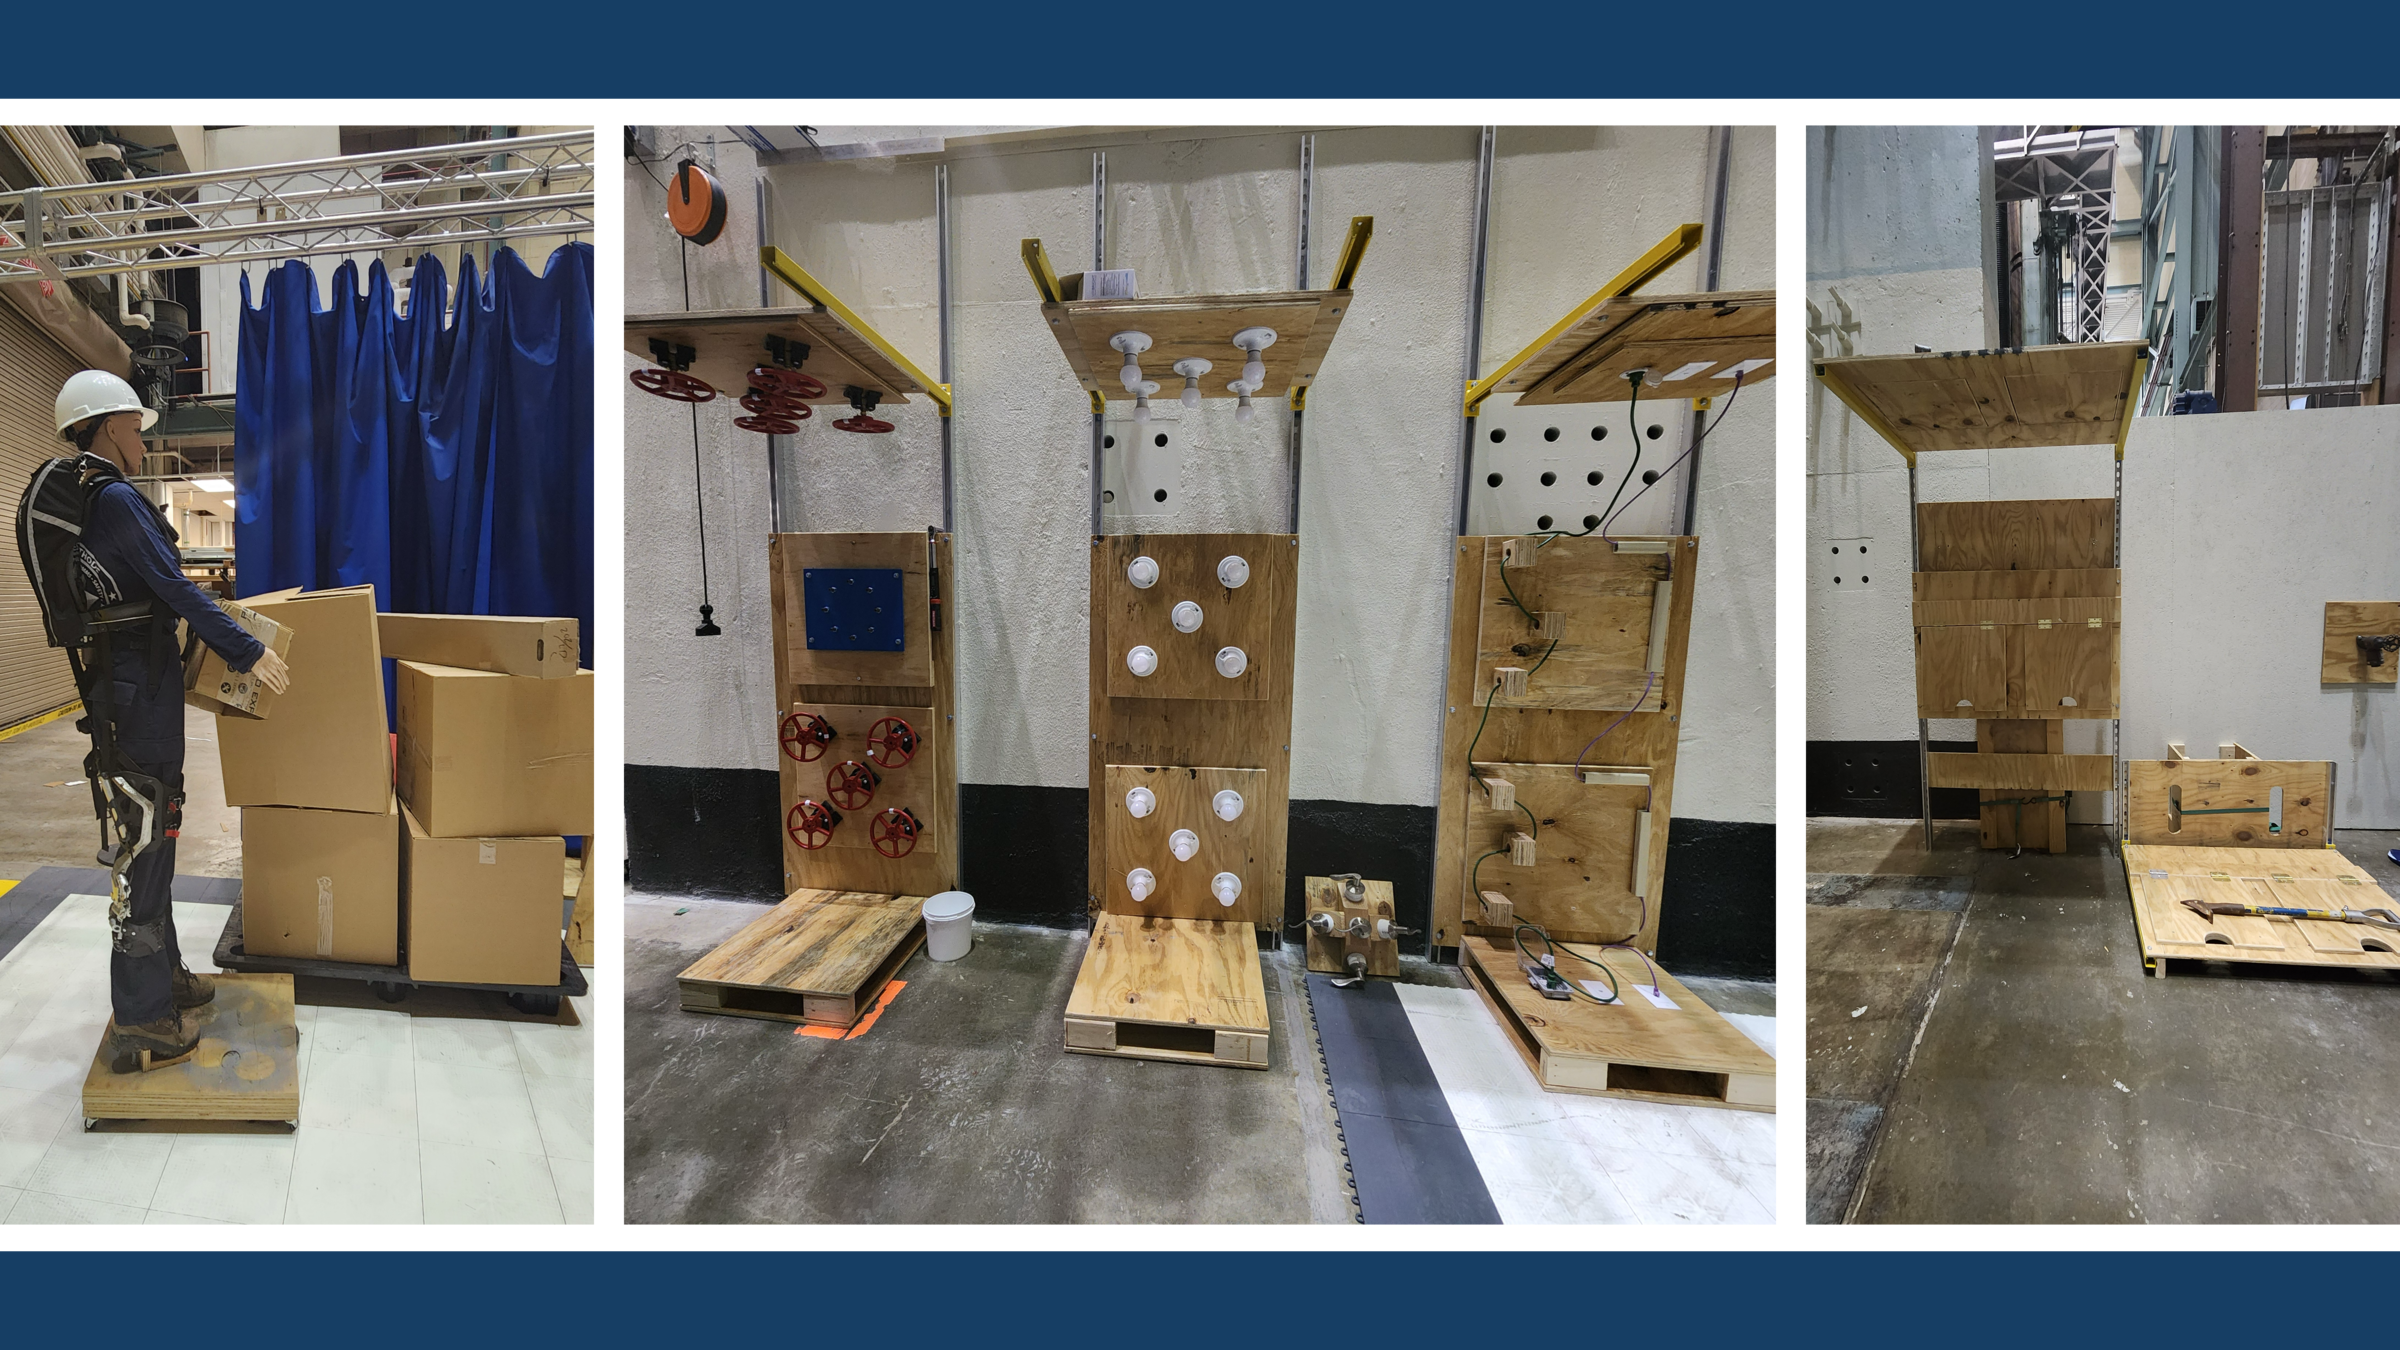
A dexterity test for engineering is basically a standardized way to measure whether a person, a process, or a component can handle fine motor tasks reliably enough for production work. It shows up most often in manufacturing quality control, ergonomics assessments, and robotics end-effector validation. If you are hiring assemblers for a precision electronics line, or if you are testing whether a pick-and-place robot can actually handle 0402 components without dropping them, you need some kind of dexterity test. There is no universal standard, which means a lot of teams just make something up, and that usually ends badly. The core variables are speed, accuracy, consistency, and fatigue resistance. Speed tells you how fast someone or something can complete a fine motor task. Accuracy measures how many errors occur per unit of work. Consistency tracks whether performance stays flat or degrades over time. Fatigue resistance is the most overlooked variable, and it is also the one that causes the most field failures. A worker or a robotic system might hit perfect numbers in a single trial, then degrade by 40 percent after three hours of repetition. That gap between lab conditions and shop floor reality is where most dexterity testing goes wrong. I have seen teams use the Purdue Pegboard as a baseline test, which is fine for general fine motor assessment, but it does not translate well to actual engineering work. A pegboard task and threading a connector pin into a cramped PCB namespace are fundamentally different physical demands. The pegboard tests bilateral coordination under low-stress conditions. Real assembly work involves awkward postures, visual occlusion, variable part tolerances, and tool resistance. I once had a contractor build an entire dexterity testing protocol around standard screwdriver insertion tasks using M3 hardware, and it worked reasonably well until we discovered that the test parts had a 0.1mm tolerance while the production parts had 0.02mm tolerance. The correlation between test scores and actual production quality was nearly zero once we switched to real parts. The workaround was to build test fixtures from production-grade components and add a deliberate torque resistance curve to the screwdriver handles. That brought the test-to-production correlation up to about 0.87, which is as good as it gets for this kind of assessment.
Building a Practical Test Protocol
Start by defining the exact task you need people or machines to perform. Write it down as a step-by-step procedure with measurable endpoints. The task should match production work as closely as possible, including tooling, workspace constraints, and part geometry. Vague tasks produce vague data. Next, establish your baseline metrics. You need a target completion time, an acceptable error rate, and a repetition count that simulates realistic workload. Three repetitions is worthless. Fifteen to thirty repetitions per trial gives you a meaningful signal. I typically run six trials with a two-minute rest between them. That takes about twenty minutes total per test subject, which is short enough to keep participants engaged and long enough to see fatigue patterns emerge. Record both aggregate and trial-by-trial data. Aggregate numbers hide degradation trends. Trial-by-trial data reveals whether someone or something is learning, plateauing, or crumbling under repetition. A participant who starts at 95 percent accuracy and drops to 78 percent by trial four is a liability regardless of what their average score looks like. Most teams miss this because they only calculate the mean.
Calibration matters more than people expect. If you are testing humans, the tools need to be properly sized and adjusted for each participant. A screwdriver that is too thick or too light changes the results entirely. If you are testing robotic systems, account for environmental variables like temperature, vibration, and lighting. I once ran a dexterity test on a pneumatic gripper system at 18 degrees Celsius and then repeated it at 28 degrees Celsius. The completion time increased by 23 percent and the error rate doubled. The vendor had only tested at room temperature and guaranteed performance based on that narrow condition. The fix was to specify an operational temperature range in the test protocol and reject any system that did not meet thresholds across the full range.
Get the Full Details
Common Pitfalls and Where This Approach Breaks Down
The biggest issue is overgeneralizing test results. A dexterity test that works for soldering small components tells you absolutely nothing about a worker or machine that will be doing heavy mechanical assembly. The motor skills involved are different. Fine grip versus power grip. Wrist flexion versus shoulder stabilization. These are not interchangeable, and treating them as such wastes time and produces false confidence. Another problem is ignoring cognitive load. Dexterity is not just physical. If your test task requires reading labels, making decisions, or adjusting to unexpected variations, you are measuring combined cognitive-motor performance, not pure dexterity. That is not necessarily bad, but you need to be honest about what you are measuring. A worker who scores poorly on a cognitively loaded task might have perfectly fine manual dexterity. They might just be slow at processing instructions under time pressure. Separate the variables if you can. If you cannot separate them, state that clearly in your report. There is also a hard limit to how much you can automate this testing for human subjects. Machines can run indefinitely with consistent parameters. Humans get distracted, injured, sick, or bored. I have found that testing more than eight subjects per day yields diminishing returns because fatigue in the tester introduces measurement drift. Rotate testers every four subjects and recalibrate equipment between rotation blocks.
If you are looking for a ready-made solution, the best freely available resources are the NIH Toolbox Cognition Battery supplementary motor tasks and the Grooved Pegboard from the NIH toolbox suite. These are not engineering-specific, but they provide validated baselines you can adapt. For production-grade testing, I usually recommend building custom jigs rather than buying off-the-shelf kits. The kits are designed for clinical populations, not for factory floor environments, and the parts and tools in those kits do not match what your actual workers or robots will handle. A custom jig costs maybe two hundred dollars in materials and a few hours of fabrication, but it produces data that actually correlates with your production outcomes. The off-the-shelf kits save you fabrication time but cost you in relevance, and relevance is the whole point of the test. The test data itself should be stored with timestamps, environmental conditions, and operator notes. Six months later when a quality incident occurs and someone asks why the hiring test did not catch a problem, you need that context available. Without it, you are just guessing about what changed.