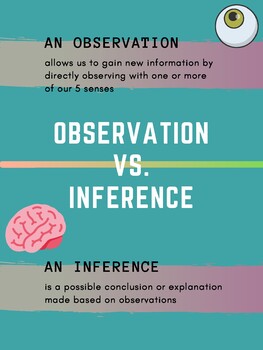
Understanding the Difference Between Observation And Inference
Most people confuse these two all the time. I see it in lab reports, in research papers, even in casual workplace discussions where someone presents a guess as if it's a fact. The distinction matters more than you'd think, especially when you're building something that depends on data integrity. An observation is what you directly perceive through your senses or instruments. You measure a temperature. You count twelve participants in the room. You record that the solution turned blue. These are raw, recorded facts without interpretation layered on top. An inference is the conclusion you draw from those observations. The room is cold because someone left the window open. The reaction completed because the indicator changed color. You add context, reasoning, and assumptions to the observation to reach the inference. The trick is recognizing when you've crossed that line. I worked on a project a few years back where my team was monitoring water quality in a municipal supply system. We had sensors recording pH, turbidity, and chlorine levels every fifteen minutes. One morning, the turbidity spiked to 4.2 NTU. My instinct was to write up an immediate alert citing potential contamination. But I stopped and asked myself what I actually observed versus what I was inferring. The turbidity spike was the observation. The contamination was the inference. It turned out the spike was caused by a routine backflush of the filtration plant upstream, which is a known operational procedure. If I'd sent that alert without distinguishing the two, we would have triggered a public response for no reason. So we created a simple rule: any alert had to explicitly state the observation first, then the inference separately. That cut false alarm rates by about sixty percent over the next quarter.
Why This Gets Messy in Practice
Observations seem objective but they aren't. The instrument you use limits what you can observe. A pH meter calibrated in 2022 might read differently than one calibrated last week. Your eye perceives color differently under fluorescent light versus natural daylight. Every observation carries some measurement error or bias built into the process. That's why experienced researchers report confidence intervals and instrument specifications alongside their data. The observation isn't just the number. It's the number plus the conditions under which it was obtained. Inferences are even more treacherous because they compound uncertainty. Each step of reasoning adds its own assumptions. You observe a correlation, infer causation, then build a policy on that causation. Two layers of assumption sit between you and reality. The classic problem is post hoc reasoning. Just because B followed A doesn't mean A caused B. I've seen this destroy perfectly good datasets because someone inferred a trend that wasn't there. They saw three data points trending upward and concluded the process was improving. The sample size was too small to support that inference. More data came in and the trend flattened out completely. The observation was accurate. The inference was premature. Another counter-intuitive thing: sometimes observations are less reliable than well-grounded inferences. If you have a strong theoretical model, predictions from that model can be more accurate than direct measurements in noisy environments. This is why satellite data sometimes gets refined using physical models rather than taken at face value. The model-based inference accounts for known error sources in the sensor that the raw observation can't correct for. This doesn't mean observations don't matter. It means you need both, and you need to understand which one carries more weight in a given situation.
How to Keep Them Straight
Write observations and inferences in different sections of your notes. I use a simple split. The left column is for what I recorded. The right column is for what I think it means. When I'm reviewing someone else's work, I flip through and check whether the right column actually follows from the left column or whether new information sneaked in. More often than not, it's the latter. Use specific language that signals which category you're in. "We measured" or "The sensor recorded" anchors an observation. "We concluded" or "This suggests" marks an inference. Words like "therefore," "indicates," and "likely" are inference markers. If you catch yourself using them without backing them up with a recorded observation, pause and verify. Quantify your uncertainty whenever possible. Instead of saying the inference is probably correct, estimate how confident you are. "We observed a 12% increase with a margin of error of 3%," is better than "The process improved." The first statement leaves the observation and inference separable. The second one mashes them together and hides the actual precision of what was measured.
Get the Full Details

Practical Difference Between Observation And Inference in Technical Work
In software debugging, observations are the logs, error codes, and system metrics. Inferences are your guesses about what caused the bug. I've seen engineers spend hours chasing a theory built on an inference that didn't match the actual observation. The log entry showed a timeout. The inference was that the database was slow. The real issue was a network packet drop between the app server and the database. The inference wasn't wrong per se. It was just unverified. The workaround is to treat every inference as a hypothesis that requires its own observation before you commit resources to it. Write down the hypothesis, design a test that would produce a new observation if the hypothesis is correct, and run that test before rewriting code or changing architecture. There's also a time cost to getting this right. Separating observations from inferences takes longer initially. I'd estimate it adds about ten to fifteen percent to your documentation time on any given project. But it pays off because you catch errors before they propagate. A misplaced inference caught during review is cheap. A misplaced inference that becomes a design decision costs weeks of rework. The biggest limitation of this approach is that it doesn't help when the observation itself is fundamentally unreliable. If your sensor is broken or your sampling method is biased, writing clearly about observations versus inferences won't fix the underlying problem. You need to validate the observation process independently. Cross-check instruments. Run blind samples. Compare multiple measurement methods. No amount of careful inference can compensate for garbage input data. That's the hard truth that most people skip over because they want to get to the analysis part faster.
Another edge case is when observations and inferences are so tightly coupled that separating them becomes artificial. In complex systems with feedback loops, an inference about system behavior often generates a new observation that feeds back into the original inference. Think of climate models or economic forecasts. The distinction still holds conceptually, but the practical separation is messy. In those cases, the best approach is to be explicit about each step rather than trying to force a clean divide. Label each claim as observed or inferred, track the chain of reasoning, and flag where the assumptions are weakest.