Why Most Scaled Agile Transformations Stall After Six Months
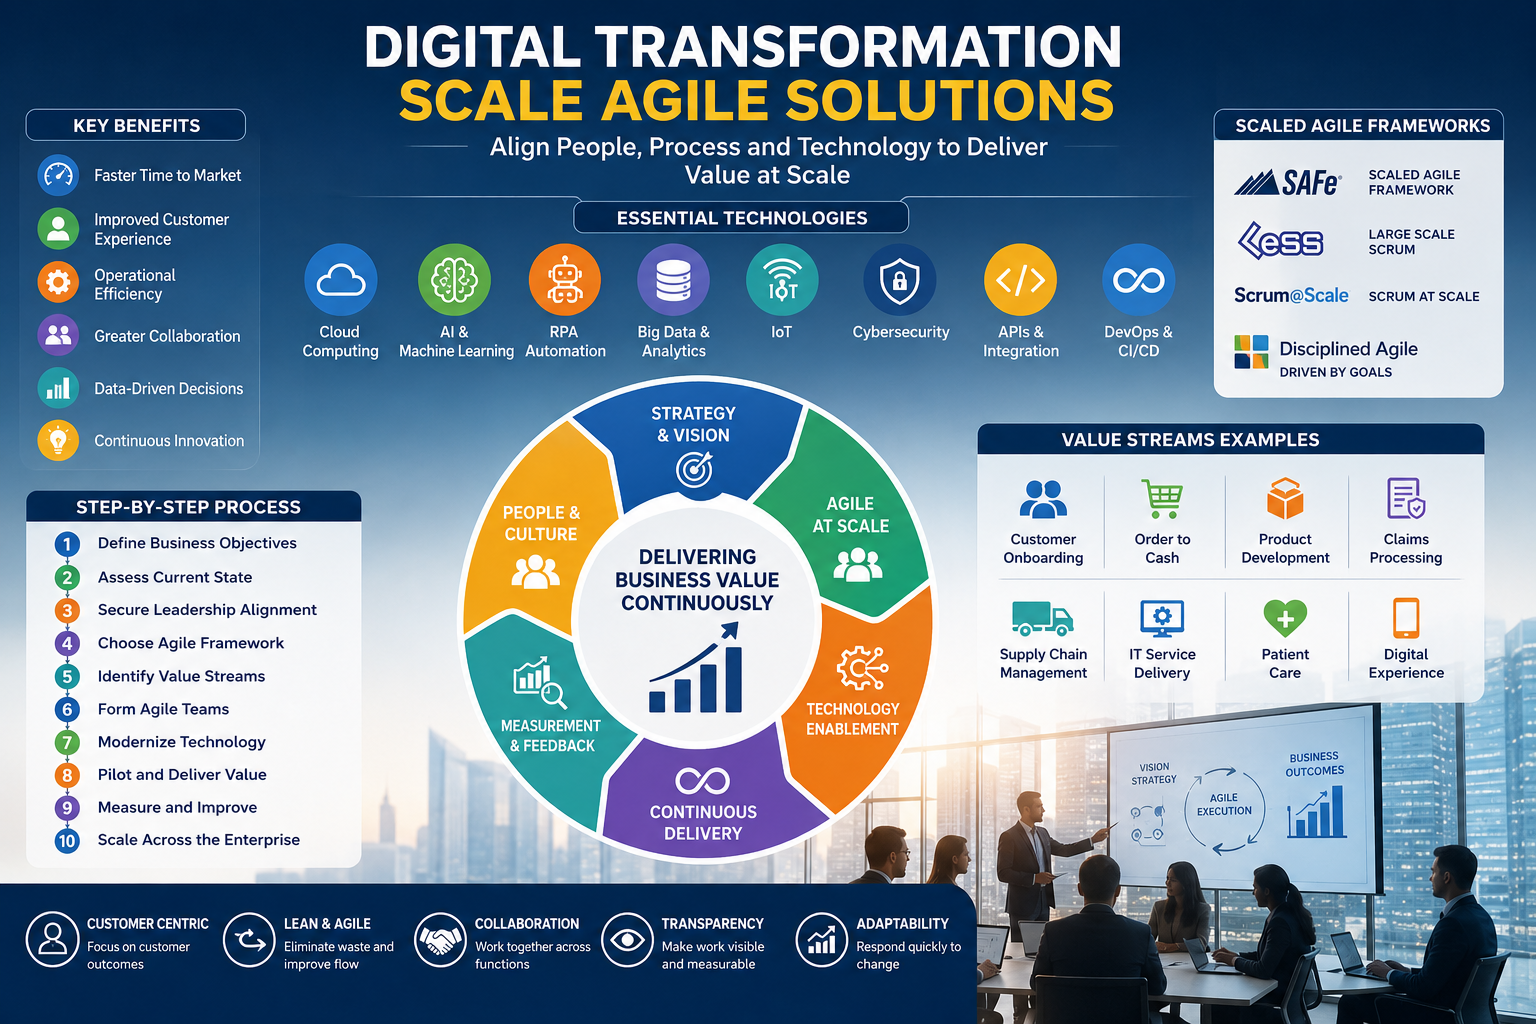
It starts with good intentions. A couple of teams adopt Scrum, they deliver on time, leadership decides to roll it out everywhere. That's when everything gets messy. The framework you're dealing with here isn't really a product you download. Digital Transformation Scale Agile Solutions is more of an umbrella term for the entire ecosystem of practices, tools, and structural changes organizations implement when they try to make agile work across dozens of teams simultaneously. The confusion mostly comes from people treating it like software you install rather than a fundamentally different operating system for how work gets organized. I spent roughly three years working on this kind of transformation for a mid-size logistics company. We went from eight Scrum teams operating independently to twenty-three teams across four business units trying to coordinate product releases. The first six months went smoothly because we had enough slack in the system that minor coordination problems just got absorbed. At month seven, a single dependency on a shared data platform between two teams created a cascade that delayed three separate release trains by six weeks. That's when I learned that the actual bottleneck in scaled agile isn't the ceremony or the documentation. It's dependency mapping across organizational boundaries that nobody wanted to own.
Implementing Digital Transformation Scale Agile Solutions in Practice
Let me skip the generic framework definitions and talk about what the actual mechanics look like. SAFe, LeSS, and Scrum@Scale all solve the same core problem differently. SAFe adds more structure and roles, which helps in complex enterprises but creates overhead that kills velocity in smaller orgs. LeSS strips things down but demands a level of team maturity most companies don't have yet. Scrum@Scale sits somewhere in the middle but its guidance on scaling beyond roughly ten teams is pretty thin. The practical implementation I found that actually worked involved three moves most companies skip because they seem too boring. First, you establish a single architectural runway. This means a dedicated platform team that maintains shared services, APIs, and infrastructure that all product teams depend on. Without this, every team rebuilds the same capabilities independently and you get version drift that causes integration nightmares later. Second, you run iterative planning at the portfolio level rather than waiting for an annual PI planning event. Portfolio-level decisions about what gets funded and prioritized need to happen on a cadence that matches how fast the market actually moves, which is usually monthly or quarterly, not once a year. Third, and this is the part everyone resists, you create a dependency board that is visible to every team lead and updated weekly. Not a Gantt chart. A live board showing which team owns which shared component and which other teams are blocked by it. When I implemented this at my previous organization, we used a simple confluence page with a matrix format rather than Jira because Jira dependencies at scale become impossible to keep accurate. Two or three teams would mark a dependency as resolved without telling the blocking team, and you'd find out during sprint review when the integration failed. The confluence board forced visibility because anyone could edit it and the format made gaps obvious.
The real counter-intuitive thing about scaling agile is that adding more ceremonies does not solve coordination problems. It usually makes them worse. What actually reduces coordination overhead is reducing inter-team dependency through modular architecture. You can run perfectly structured PI planning for eighteen months and if your architecture forces ten teams to touch the same codebase, you will still have constant integration friction. The fix is domain-driven design applied at the organizational level. Split your systems into bounded contexts where each team owns a complete vertical slice from database to API to frontend with minimal external dependencies. Another thing people get wrong is thinking that scaling agile means every team needs to follow the same framework. In practice, different teams serving different business functions operate at different tempos. A compliance reporting team might need a longer iteration cycle because their work involves regulatory review gates that an payments team doesn't have. Forcing both into identical two-week sprint cadences just creates artificial padding in one and chaos in the other. Let teams customize their cadence within a shared coordination layer. The coordination layer is where you keep the common conventions: definition of done, naming standards for branches and PRs, shared metrics dashboards. Everything else can be team-specific. Here's a specific edge case that nearly derailed our transformation. We had a team responsible for a legacy batch processing system that couldn't be modernized within any reasonable timeframe. They were stuck maintaining COBOL-based workflows while every other team was pushing containerized microservices. The cultural disconnect was brutal. Their timeline was measured in quarters. Everyone else's was measured in weeks. Standard agile metrics made them look like the slowest team in the company, which affected their funding priority in the next planning cycle. The workaround was to create a separate metric track for legacy maintenance teams. Things like mean time to restore, incident resolution rate, and technical debt reduction percentages instead of velocity or sprint burndown. It wasn't elegant but it prevented the transformation from actively punishing the teams keeping the lights on.
Get the Full Details
The tools people reach for when they hear Digital Transformation Scale Agile Solutions usually fall into a few categories. There are full platforms like Jira Align or Planview that promise end-to-end portfolio management but require significant configuration and licensing costs that scale poorly. Then there are lighter approaches using Confluence, Miro, and basic Jira projects with plugins. The lighter stack is easier to customize but requires more manual discipline to keep current. We ended up running Jira for individual team backlogs, Confluence for the dependency board and architectural decision records, and a quarterly planning offsite for the coordination meetings that no tool can replace. Tools manage information flow. They do not manage trust between teams. There are real limitations here that nobody in the consulting world talks about enough. Scaled agile assumes you have enough product demand to keep multiple teams continuously working. If your organization is in a maintenance phase with low incoming work, scaling agile just creates internal competition for tasks and lots of unused capacity. It also assumes a certain level of technical maturity. Teams that lack basic CI/CD practices, automated testing, or deployment automation will slow down dramatically at scale because every integration becomes a manual event. You cannot agile-scale a organization that deploys to production by opening a SSH terminal and running a script. If your organization has fewer than fifteen engineering teams, the answer is probably not to adopt a formal scaled framework at all. Most of the coordination overhead that scaling frameworks are designed to manage simply does not exist at that size. A good tech lead who knows what every team is working on can handle the coordination manually. The frameworks become necessary when the span of control exceeds what any single person can track, which typically happens around fifteen to twenty teams. Before you jump into SAFe or LeSS, ask whether the problem is really about scaling a framework or just about better communication patterns that don't require adding three new roles and eight new ceremonies.
For teams that do need to scale, start with the architectural piece before you touch the process piece. Figure out how your systems decompose into independent domains. Map the dependencies between those domains. Then apply lightweight coordination rituals on top of that structure. Doing it in reverse order means you spend months optimizing sprint planning ceremonies while your teams remain structurally dependent on each other in ways that no amount of refined backlog grooming can fix. The structure determines what's possible. The process just describes how you move within those constraints.