How DNA Profiling Actually Works Before You Touch a Worksheet
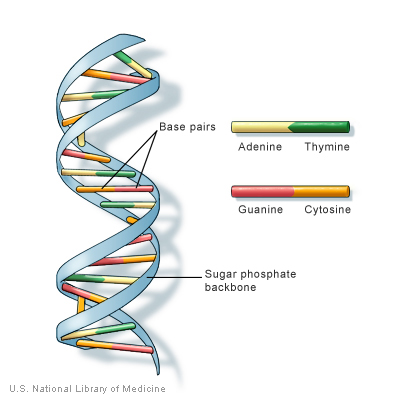
Most people assume paternity testing is about looking at a banding pattern and declaring a match. It's not that simple. You start with PCR amplification of short tandem repeat loci, usually 15 to 20 markers on a standard commercial kit like Identifiler or PowerPlex. Each person carries two alleles per locus, one inherited from each parent. The child must share one allele with the mother and one with the alleged father. That's the entire principle. Everything else is noise, contamination checks, and statistical weight. A Dna Fingerprinting And Paternity Worksheet is just a structured way to lay out those allele calls and do the exclusion or inclusion math. The chemistry happens first. The worksheet comes after.
Building a Dna Fingerprinting And Paternity Worksheet from Raw Electropherogram Data
Get your raw data from the capillary sequencer or gel imaging software. Extract the allele calls at each locus. Most labs use GeneMapper or similar for this. Hand-copying from a printout is where mistakes creep in. If you can export a CSV or tab-delimited file, do it. Even then, spot-check five random entries against the chromatogram. You'd be surprised how often the software mislabels a stutter peak as a true allele. Set up your columns. Mother, child, alleged father, then one column per locus. Add a final column for whether the alleged father contributes an obligate allele at that locus. If he doesn't at even one locus, you have an exclusion. Three exclusions across 15 loci is never a borderline case. It's a hard no.
The Calculation People Get Wrong
Include value alone doesn't prove paternity. It just means the man couldn't be excluded. The real number that matters is the paternity index, calculated per locus by dividing the probability of observing the child's genotype if the alleged father is the true father by the probability if a random man from the population is the father. Multiply those across all loci. Then convert to a probability of paternity using a prior, typically set at 0.5. I've seen worksheets where someone wrote the combined paternity index as 1 in 10,000 and then called that a 99.99 percent probability. It isn't. 1 in 10,000 is the reciprocal of the CPI. The actual probability of paternity works out to roughly 99.99 percent only if the CPI is around 10,000. You need to carry the CPI as a raw number and run the formula, not eyeball it.
Get the Full Details

A Real Problem I Ran Into
Last year I was reviewing a case where the mother's sample was degraded. Her electropherogram showed very low peak heights across multiple loci, and the child clearly carried an allele she shouldn't have been able to pass based on the visible peaks. The alleged father had one obligate allele mismatch at D8S1179. On paper, that's an exclusion. But the mother's peak at that locus was barely above the analytical threshold. When I re-extracted and amplified the sample with a lower input volume and ran it on a fresh capillary, the missing allele appeared. It was a stochastic drop-out, not a genuine exclusion. The alleged father passed. The initial worksheet had flagged him wrongly because I didn't check for degradation and low template effects before crossing him out. The workaround is straightforward but easy to skip. Check the internal size standard peak heights and the heterozygous peak balance ratio. If the balance falls below 0.6 or total peak height drops under a reasonable threshold, flag the profile as low-template and repeat with increased cycle numbers or more input DNA. Don't make a final call on the first read.
Common Pitfalls That Wreck These Worksheets
Stutter peaks get called as real alleles, especially at tetranucleotide repeats like D21S11. The NBS Genetics database and manufacturer guidelines list expected stutter percentages. Anything within the stutter window should not automatically count as a second allele. Another common error is allele dropout due to primer binding site mutations. This shows up as a consistent homozygous appearance across multiple loci in one parent when the child's genotype demands a second allele. The fix is to add a supplementary primer set or use a different commercial kit that targets different flanking regions. Known relatives as alleged fathers are another trap. Brothers share enough alleles that the CPI inflates artificially. The worksheet might show a CPI of 50,000 and a probability of 99.998 percent, but if the true father is the man's brother, the real probability could be far lower. In these situations, you need additional markers, ideally SNPs or full STR panels, and you should flag the possibility of a related alternative father explicitly.
When This Method Doesn't Help
A paternity worksheet based on STR profiling fails if the samples are too degraded or contaminated to produce reliable amplification. It also cannot resolve cases where the alleged father is deceased and only a buccal swab from a parent or sibling is available. In that scenario, you're doing kinship analysis, not direct paternity testing, and the statistical framework changes entirely. You'd need a likelihood ratio approach rather than a simple CPI. Mutation rates at STR loci are low but nonzero. A single-locus exclusion with no other errors can sometimes be a de novo mutation rather than non-paternity. The standard response is to test additional loci. If the rest of the profile supports paternity and only one locus shows a mismatch, calculate a mutation-adjusted paternity index rather than excluding outright. Skipping that step has cost people custody decisions and child support rulings I've seen reviewed.

Practical Workflow for a Clean Worksheet
Export allele calls from your analysis software. Verify against the raw chromatogram. Fill the worksheet locus by locus. Mark obligate allele contributions. Calculate the paternity index per locus. Multiply for the combined CPI. Convert to a probability. Add a notes section for any anomalies like stutter, drop-out, or low template. Keep the raw data files alongside the completed worksheet. Five years from now, when someone asks why a particular allele was called the way it was, you'll need that trail. This process usually takes a trained technician about 20 to 30 minutes per case once the amplification and electrophoresis are done. The analysis software handles most of the heavy lifting. The worksheet is where human judgment still matters, mostly because machines will label what they think they see without context. A competent review catches the cases where the machine is confidently wrong.