Understanding The Building Blocks Of Genetic Material
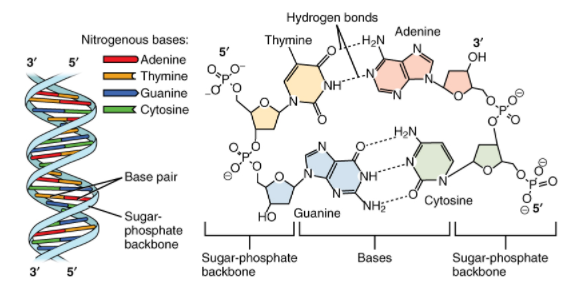
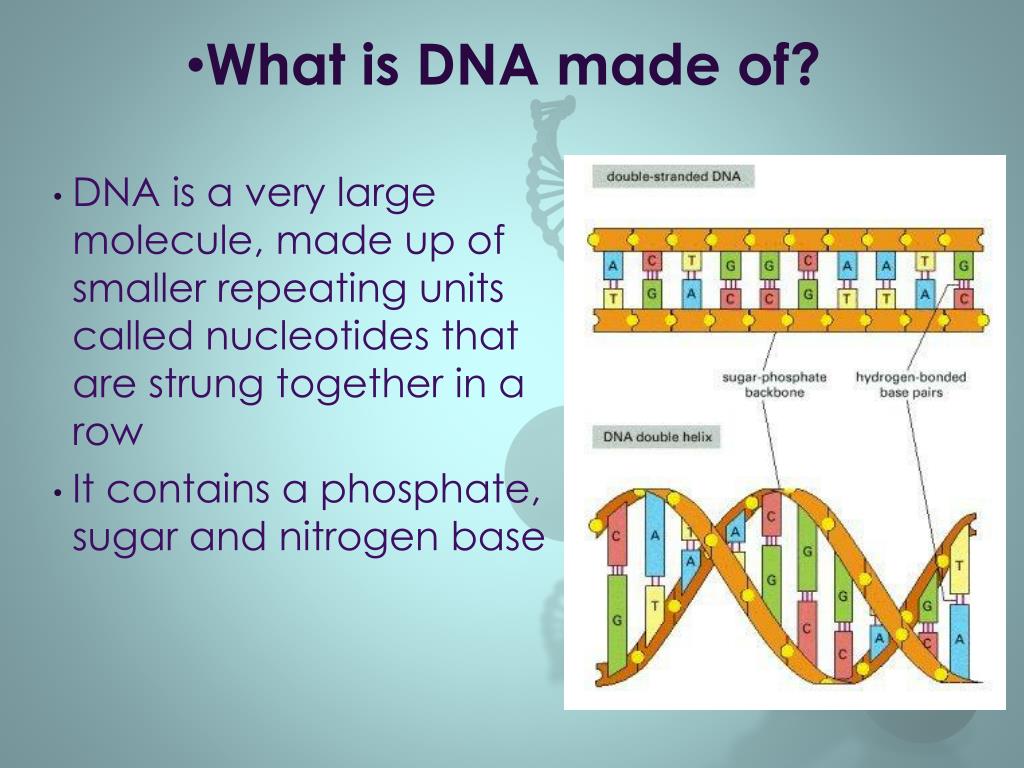
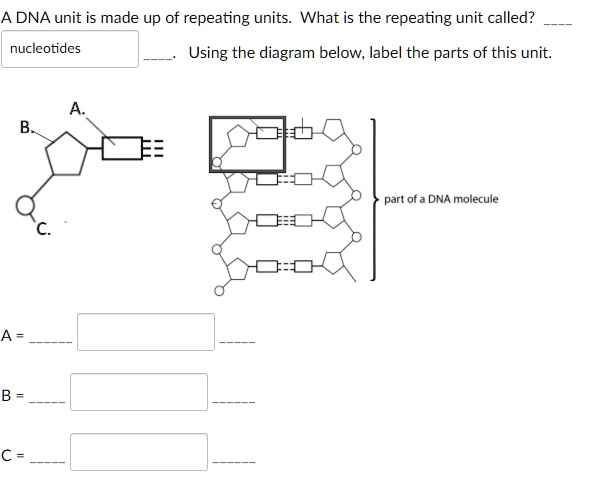
When you look at a DNA strand under a proper sequencer, what you're really seeing is a chain of repeating units. These units are called nucleotides. Each one is made of three components: a phosphate group, a sugar molecule (deoxyribose), and a nitrogenous base. There are four types of bases - adenine, thymine, guanine, and cytosine - and the sequence of these bases is what encodes genetic information. I spent years working in a molecular biology lab running PCR and sequencing work. The first time I actually had to explain this to a new grad student who kept mixing up nucleotides with nucleosides, I almost gave up on teaching altogether. A nucleoside is just the base plus the sugar. Add a phosphate and it becomes a nucleotide. That distinction matters when you're reading kit protocols or troubleshooting why your ligation reaction failed. The way these repeat is through phosphodiester bonds. The phosphate on one nucleotide connects to the 3' carbon of the sugar on the next nucleotide. This creates directionality - your strand runs 5' to 3'. This isn't just academic. If you're designing primers for amplification and you get the direction wrong, your reaction will sit there and do absolutely nothing. I learned that one the hard way during a thesis project where I wasted three days wondering why my gel came back blank. It turned out I'd synthesized the primer backwards. The sequence was perfect. The orientation was not.
One thing beginners consistently miss is that the repeating unit isn't just about structure. It's about how the chemistry works during replication and sequencing. When Sanger sequencing reads your sample, it's detecting which nucleotide gets incorporated at each position. The fluorescent labels attach to the nucleotides themselves, not to the bases in isolation. So if you're working with degraded samples where the phosphodiester backbone is already breaking down, your read quality drops significantly because the repeating chain is fragmenting before you can even load it on the machine. Here's a practical edge case I ran into recently. I was working with ancient DNA extracts - highly fragmented material from archaeological samples. The standard nucleotide repeat pattern breaks down because the fragments are so short that you're often looking at single-stranded pieces that barely contain a full repeating unit. The workaround was switching to single-stranded library prep protocols instead of the standard double-stranded approach. This increased our usable yield by about 40 percent compared to the old method, though it added roughly two extra hours to each batch processing time. Another thing worth noting: the nucleotide composition of your template directly affects how your sequencing runs perform. High GC content regions tend to form secondary structures that polymerase enzymes struggle to unwind. If your template has more than 65 percent GC, you should expect lower quality scores in those regions and plan accordingly. Some labs use specialized polymerases or add betaine to the reaction mix to compensate. It's not a perfect fix but it usually recovers enough data to make the run worthwhile.
Bottom line, the repeating nucleotide structure is simple on paper but doing actual work with it requires understanding how those repeats behave under different conditions. The theory doesn't always match what you see in the lab, and expecting it to is how you end up with wasted reagents and confused students.
Get the Full Details