The Basics You Already Know (But Probably Forget)
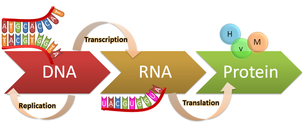
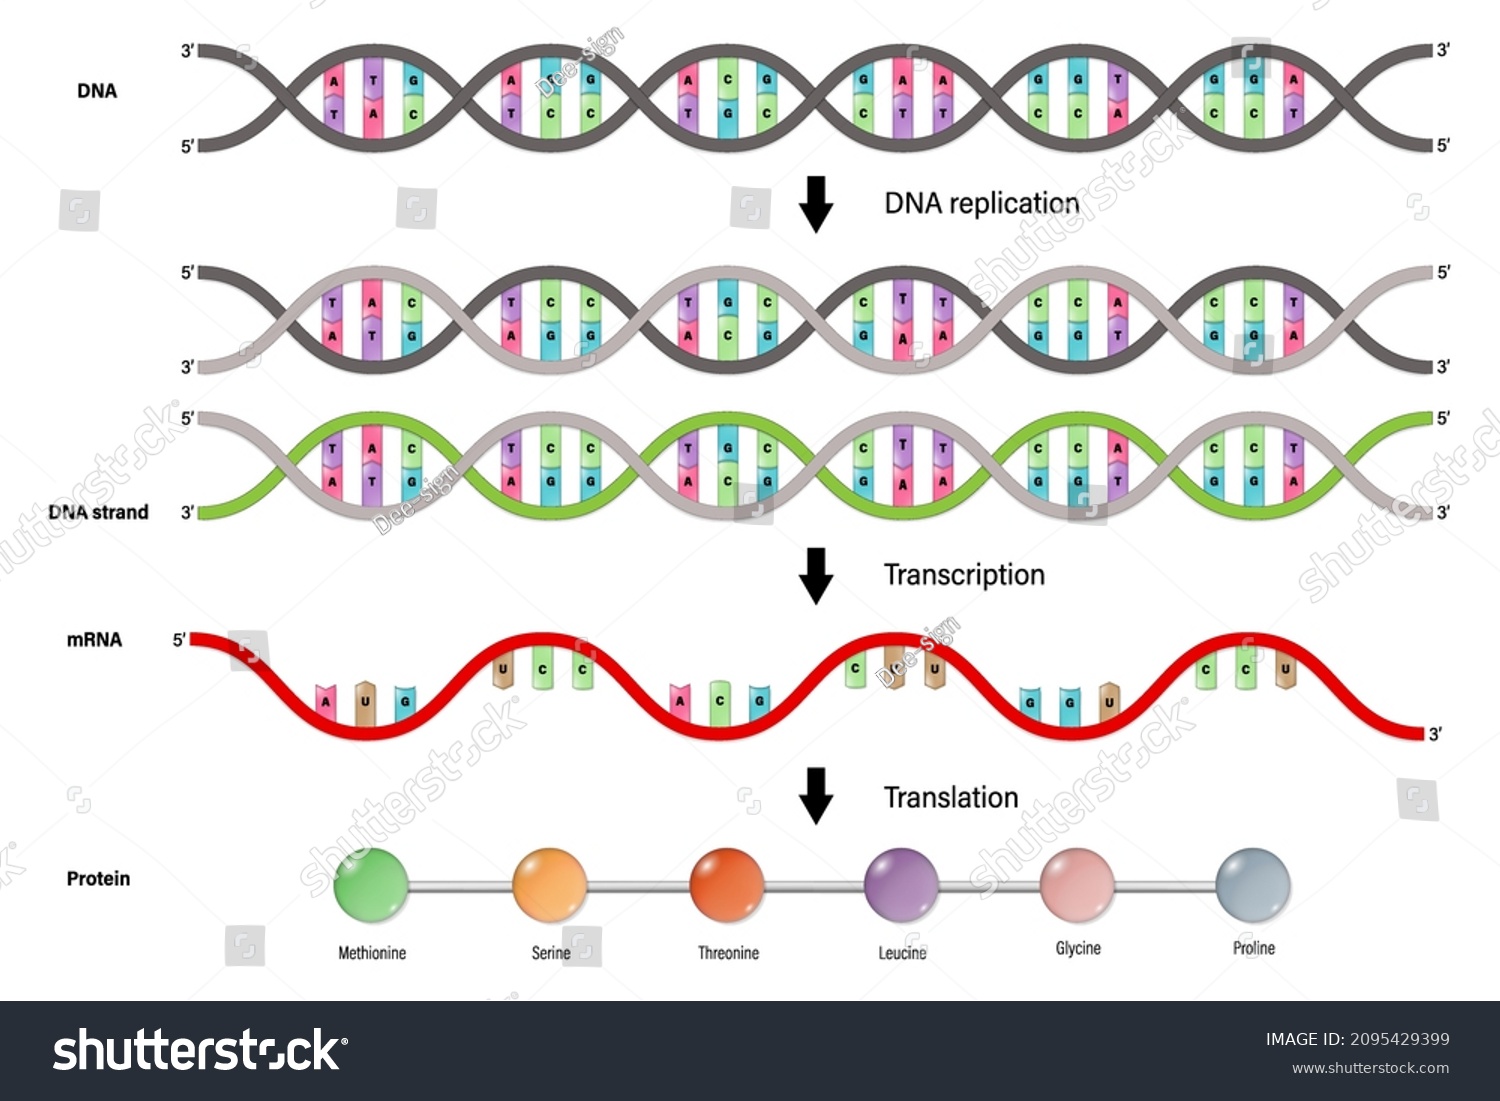
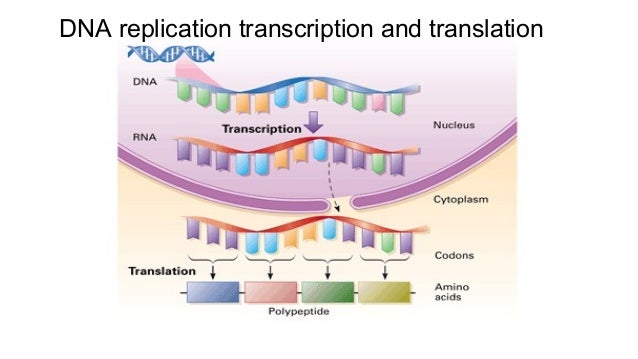
DNA replication copies the genome before cell division. Transcription makes RNA from a DNA template. Translation reads that RNA to build proteins. This is Dna Replication Transcription And Translation, the central dogma most undergrads memorize in a week and then never think about again until they hit a real problem in the lab. It sounds simple because the textbook version is clean. In practice, none of these processes are clean. They overlap, they mess up, and they require constant repair. The cell doesn't just run a script and move on.
Dna Replication Transcription And Translation
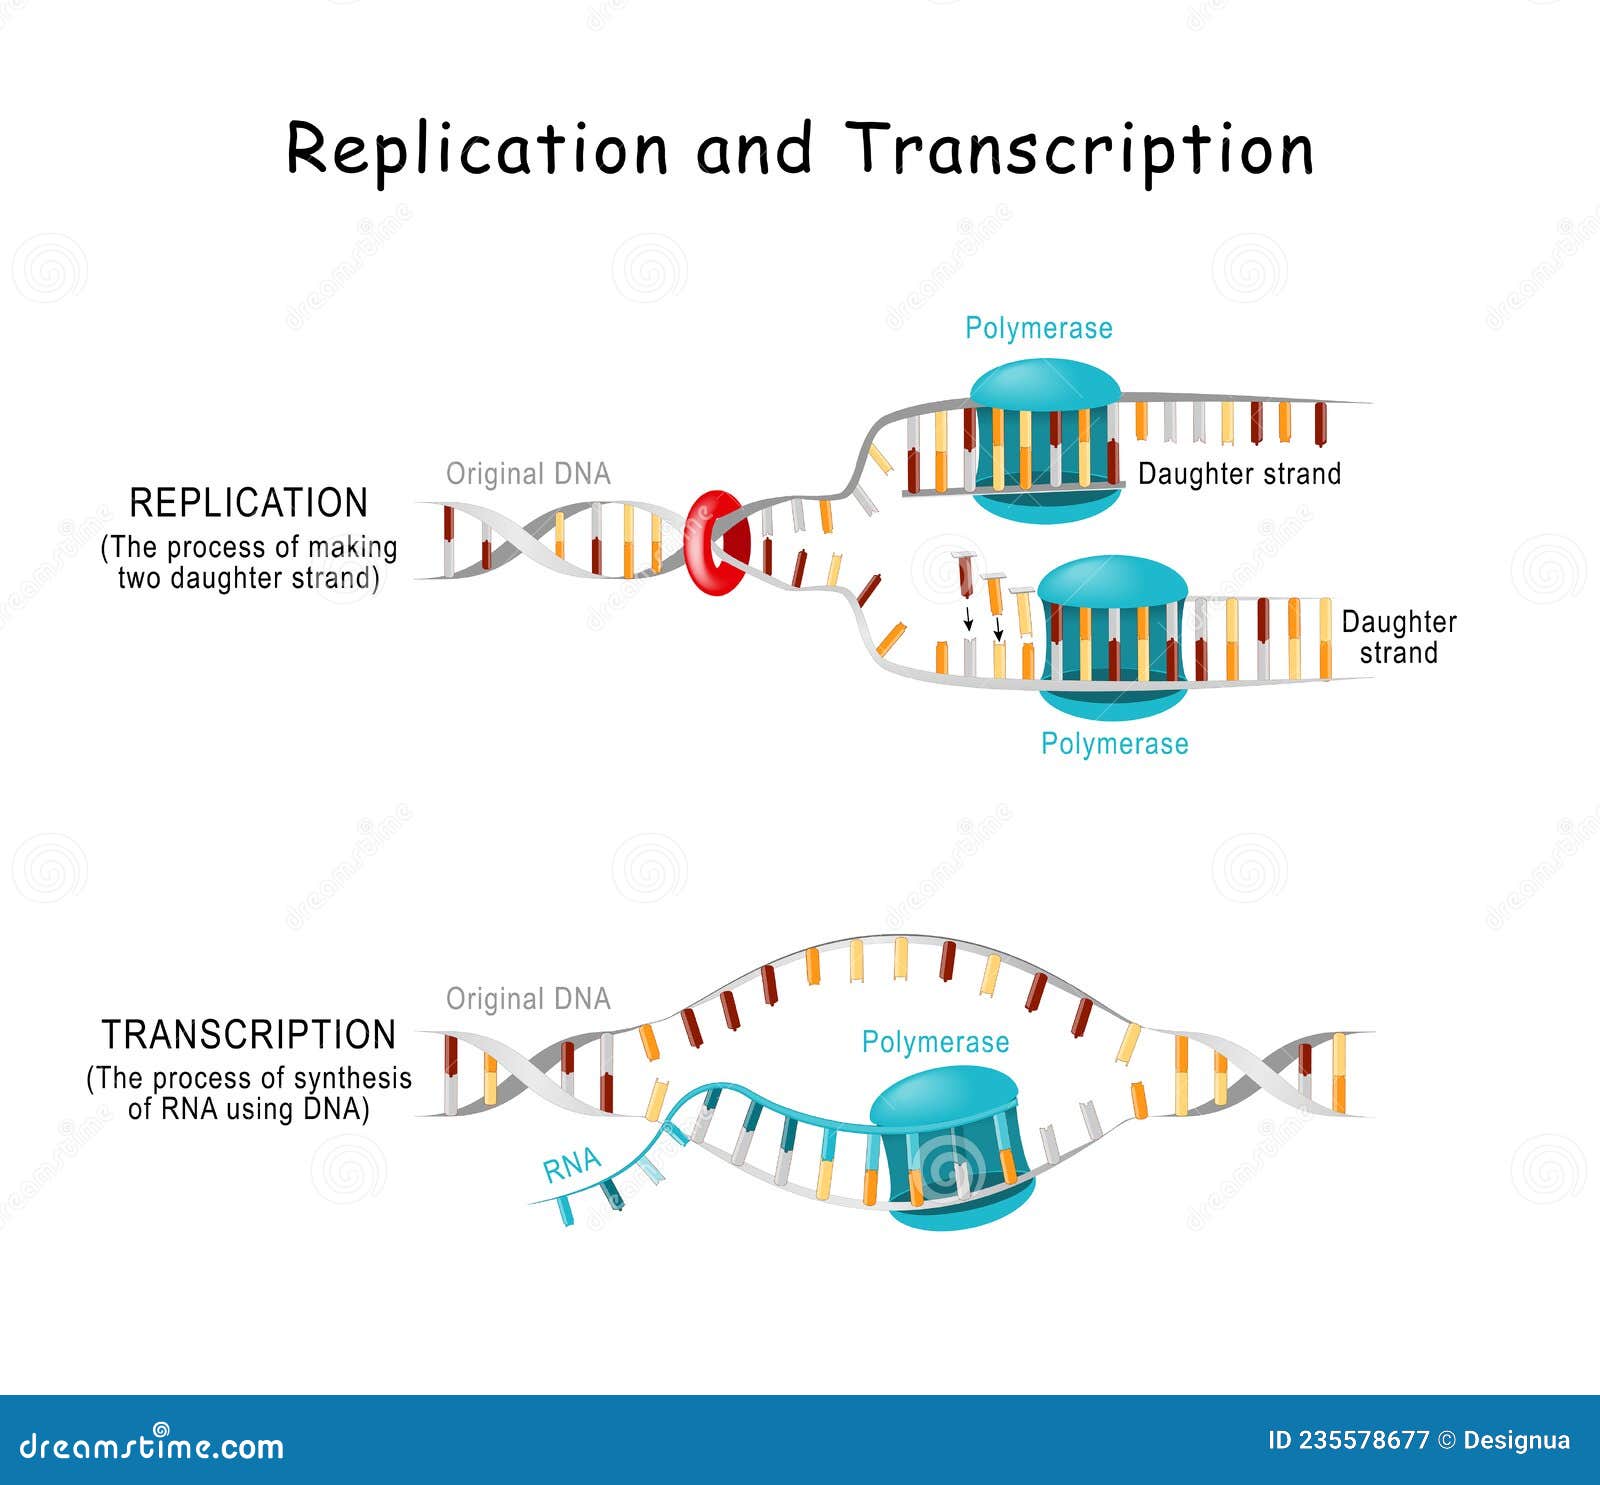
When I was running PCR-based cloning workflows, I learned pretty quickly that the textbook diagrams don't tell you where things actually break down. Let me walk through how this works in a real setting, not a lecture hall. Replication starts at origins of replication. In bacteria, there's usually one origin. In humans, there are tens of thousands. The replisome assembles there, and DNA polymerase begins synthesizing new strands. But here's the thing most people skip: DNA polymerase can only add nucleotides in the 5' to 3' direction. That means one strand is made continuously (the leading strand) and the other in short fragments called Okazaki fragments (the lagging strand). Those fragments have to be stitched together later by DNA ligase. If that doesn't happen cleanly, you get gaps or misjoins, and the cell pays for it during the next division. Replication is also where telomeres matter. Every time a linear chromosome replicates, the very end gets shorter because the RNA primer at the tip has nothing to replace it. Telomerase fixes this in stem cells and some cancer cells. Most normal somatic cells lose about 50 to 100 base pairs per division. That limits how many times a cell can divide before it shuts down. That's the Hayflick limit, and it's why your skin cells don't keep renewing forever.
Transcription uses RNA polymerase to read a gene and make a complementary RNA strand. In bacteria, one RNA polymerase handles everything. In eukaryotes, you've got RNA pol I making ribosomal RNA, RNA pol II making mRNA and most small nuclear RNAs, and RNA pol III handling transfer RNAs and other small RNAs. Each one has its own promoter architecture and regulatory logic. The RNA transcript isn't ready to use yet in eukaryotes. It needs a 5' cap added, a poly-A tail tacked onto the 3' end, and introns spliced out. Splicing is where things get complicated. A single gene can produce multiple different mRNA variants through alternative splicing. The TP53 gene alone has multiple splice isoforms, and they don't all do the same thing. That's one reason cancers that mess with splicing factors are so dangerous. Translation happens on ribosomes. The ribosome is essentially a ribozyme, meaning the catalytic activity comes from RNA, not protein. It reads the mRNA codon by codon, and each codon matches a specific tRNA carrying the corresponding amino acid. Peptide bonds form between adjacent amino acids, and the chain grows from the N-terminus to the C-terminus.
Get the Full Details
The genetic code is nearly universal, which is useful for everything from horizontal gene transfer studies to expressing human genes in bacterial systems. But it's not perfectly universal. Mitochondria use slightly different codon assignments. If you're expressing a mitochondrial gene in E. coli without adjusting the codons, translation will stall or produce the wrong protein. I learned that the hard way when my first attempt at expressing a human mitochondrial enzyme in a standard expression vector produced nothing but truncated peptides and a cloudy culture.
Where Things Actually Go Wrong
Here's a scenario I ran into a couple of years ago that didn't match any textbook explanation. We were doing a co-transcription-translation assay in reticulocyte lysate, trying to study how a particular mRNA with a long 5' untranslated region folds and affects translation efficiency. The UTR had potential G-quadruplex structures. Standard protocols assume linear mRNA, but G4 structures form under physiological salt conditions and they physically block the ribosome from scanning down the transcript. The result was near-zero protein production, and we spent weeks troubleshooting before we realized the issue wasn't with the lysate or the construct. The workaround was adding a G4-stabilizing ligand to confirm the hypothesis, then redesigning the UTR to remove the high-energy quadruplex-forming sequences. Protein output jumped to about 70 percent of the control. That experiment taught me that RNA secondary structure is a real variable in translation, not just a theoretical curiosity. Another common failure point is codon bias. Bacterial expression systems like E. coli don't have the same tRNA abundance profile as mammalian cells. If your gene has lots of arginine codons that E. coli rarely uses, translation will slow or stop at those points. The fix is usually codon optimization, which means rewriting the DNA sequence to match the host's preferred codons while keeping the same amino acid sequence. There are commercial tools that do this, but they don't always account for mRNA secondary structure, and sometimes the optimized sequence performs worse than the original. You have to check both the codon adaptation index and the predicted folding energy.
Replication Fidelity and Its Costs
DNA polymerase has a proofreading function. When it adds a wrong nucleotide, it backs up, cuts out the mistake, and tries again. This reduces the error rate from about one in ten thousand to roughly one in a million per base. Then mismatch repair proteins scan the newly synthesized strand, find the rare errors that slipped through, and fix them. The combined fidelity is about one error per billion bases copied. That sounds impressive, but the human genome is three billion bases long, and we divide cells constantly. You still get mutations. Most are neutral or repaired. Some accumulate. The ones that matter are the ones that hit oncogenes or tumor suppressors. Replication errors aren't random across the genome either. Replication timing matters. Late-replicating regions tend to have higher mutation rates, and heterochromatic regions are harder for repair machinery to access. If you're analyzing sequencing data from a tumor, don't treat the mutation spectrum as uniform. The biology of when and where replication happens shapes what you see. Transcription-coupled repair is another nuance. When RNA polymerase gets stuck on a DNA lesion, it recruits repair proteins to fix that specific spot. This means actively transcribed genes are protected better than silent regions. But there's a tradeoff. The polymerase itself can get damaged during this process, and if the lesion is too severe, the whole transcription complex can collapse and cause double-strand breaks. That's one mechanism linking high transcriptional activity to genomic instability in rapidly dividing cells.

Practical Takeaways
If you're working with these processes in a lab setting, stop thinking of them as separate steps. They're coupled. In bacteria, transcription and translation happen simultaneously because there's no nuclear membrane separating them. The ribosome latches onto the mRNA while it's still being made. This coupling actually protects the mRNA from degradation and speeds up protein production. When someone designing a synthetic biology circuit ignores this and puts a strong promoter driving a gene without considering ribosome binding site strength, the system usually fails because the mRNA gets degraded before meaningful protein accumulates. In eukaryotes, the separation gives you more regulation points but also more places for things to go wrong. Nuclear export is a checkpoint. mRNA has to pass quality control before it leaves the nucleus. Nonsense-mediated decay destroys transcripts with premature stop codons. This is useful, but it also means you can't just express any sequence you want and expect a protein. If your construct has an open reading frame that looks truncated to the surveillance machinery, it gets destroyed in the nucleus before translation even starts. Replication stress is another practical concern. Agents that slow down the replication fork, like hydroxyurea or certain chemotherapies, create single-stranded DNA regions that are vulnerable to damage. Cells respond by activating checkpoint pathways that pause the cell cycle. If the stress is too severe, the cell undergoes apoptosis. That's the basis of a lot of cancer treatments, but it also means your normal cells take damage too. There's no free lunch with interfering with replication.
When you're designing experiments around these processes, the biggest mistake I see is treating the central dogma as a one-way assembly line. It's not. There's reverse transcription in retroviruses and retrotransposons. RNA can influence chromatin structure. Proteins regulate their own expression through feedback loops. The system is full of feedback channels that textbooks leave out because they complicate the diagram. If you want a solid reference for the molecular mechanics, Alberts' Molecular Biology of the Cell is still the standard. For hands-on lab protocols, the methods sections of Nucleic Acids Research or Methods in Enzymology will give you specific conditions that actually work. Avoid relying solely on vendor protocol sheets. They're written for people who have never had a problem, and when you do, they won't help you fix it.