The Basic Math and Why It's Not Actually Useful
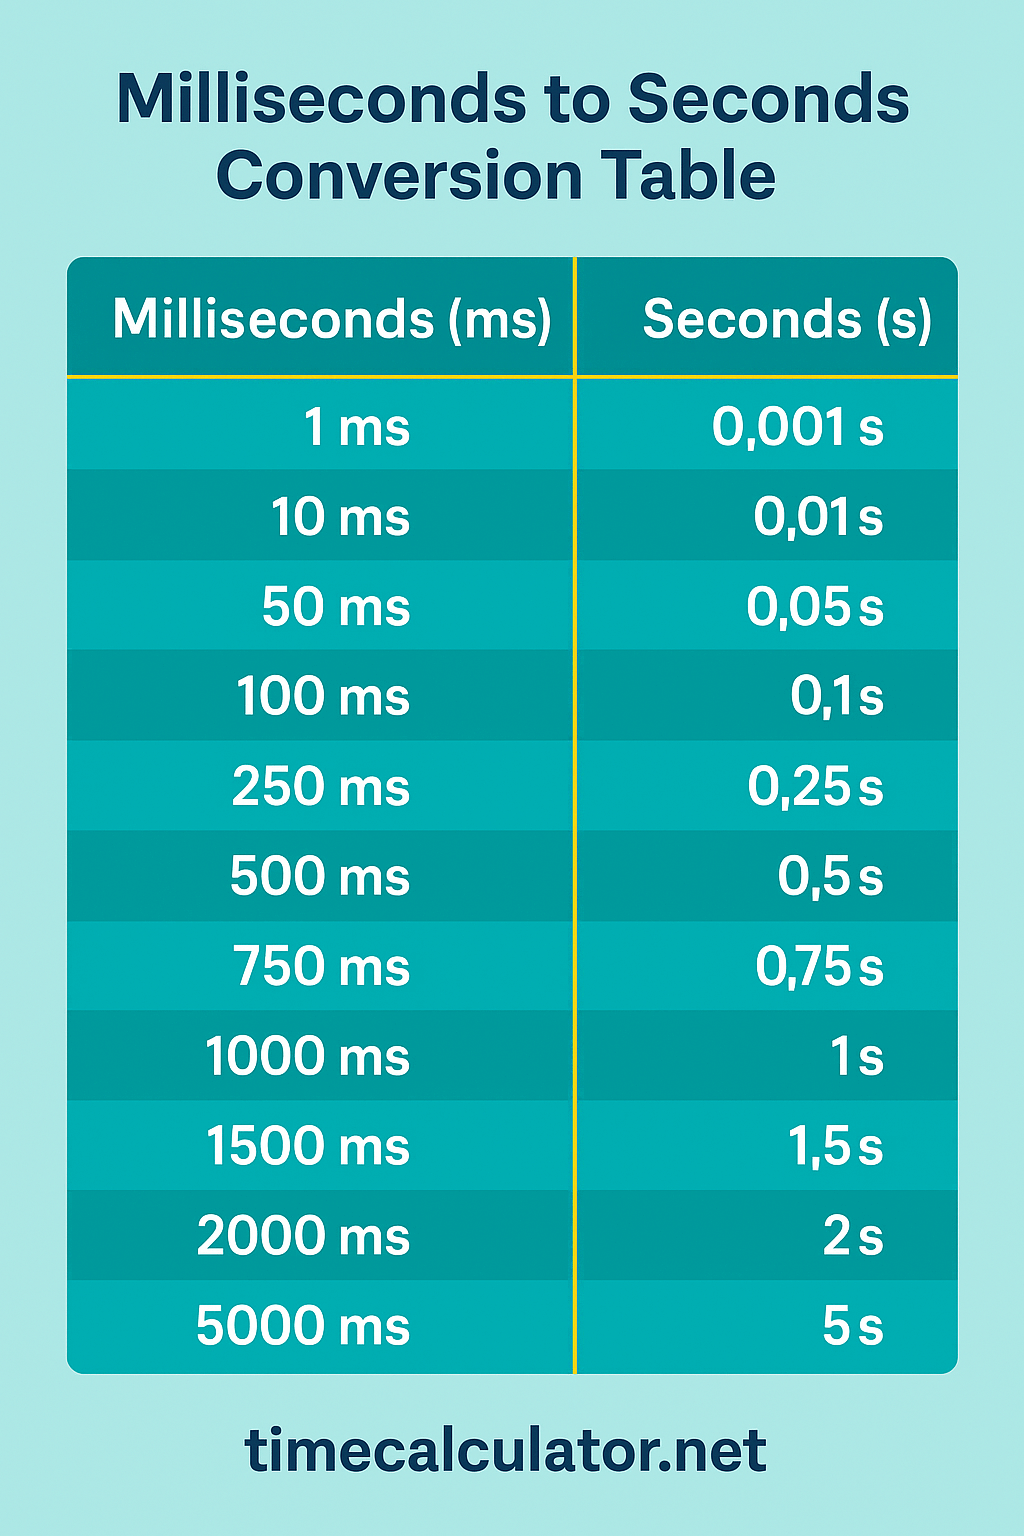
One second equals 1000 milliseconds. That's the definition. It's part of the International System of Units, established when the SI adopted the millisecond as exactly one-thousandth of a base SI unit second. The second itself is defined by the caesium-133 atom's hyperfine transition frequency, which is fixed at 9,192,631,770 Hz. So a millisecond is just that value divided by 1000, roughly 9,192,631.770 atomic oscillations. You don't really need any of that for daily work. What people actually need to know is how milliseconds behave in systems that aren't perfectly precise. Because they are never perfectly precise.
How Many Milliseconds In A Second?
Still 1000. The number doesn't change even when your CPU can't reliably measure it. I spent three weeks tracking down a race condition in a Go service that processed payment confirmations. The issue wasn't logic. The bug was that our validation function compared millisecond-precision timestamps from two different sources — one from our Postgres database using pg_sleep and one from an upstream API returning ISO 8601 strings parsed with a standard library clock. Both said they were tracking the same second. They weren't. The external API was reporting the time when the request arrived at their load balancer, not when it was processed. The difference came out to 3 milliseconds on average, sometimes 12. Over 40,000 transactions a day, that added up to about 200 false positives per week where our deduplication check incorrectly rejected legitimate duplicates. The workaround was straightforward but annoying. I stopped comparing raw timestamps against each other. Instead I built a small windowed cache keyed on the transaction ID with a 50-millisecond grace period on both sides. The deduplication logic became: if a new transaction arrives within 50ms of a previously seen transaction ID, treat it as a duplicate, otherwise process it. That gave enough breathing room for clock skew between services without creating a gap where legitimate concurrent requests could collide.
The Hidden Problem Nobody Talks About
Most developers think about milliseconds as a unit of measurement. They don't think about them as a unit of coordination. When you're working across multiple services, databases, or processes, millisecond-precision timestamps are essentially meaningless unless you've explicitly solved for clock skew between those systems. NTP can reduce that to sub-millisecond levels on a well-configured LAN, but cloud environments, containers, and VMs commonly drift by 10–50 milliseconds between syncs. Kubernetes pods on different nodes are a particular pain point. I've seen kubelet report node times that were off by 80 milliseconds because the host system had NTP disabled after a failed sync cycle. There's also the operating system side. Linux uses CLOCK_MONOTONIC for timing measurements that matter internally — like how long a syscall takes or how much wall time a process consumed. But application-level code often reads CLOCK_REALTIME, which is subject to NTP adjustments. Those adjustments can jump time backward or forward by seconds during a severe sync correction, which is why POSIX explicitly warns against using realtime clocks for duration measurement. Monotonic clocks don't have this problem because they only ever move forward from an arbitrary origin point. If you're writing time-sensitive code, check which clock your language's standard library uses by default. Python's time.time() returns realtime. Use time.monotonic() instead. JavaScript's Date.now() is realtime. Use performance.now() for anything measuring intervals. Go's time.Now() is realtime. There's no direct monotonic equivalent in the standard library, which is why Go's own runtime package has CpuProfile and other internals that manage monotonic reading internally. This distinction costs you nothing to make and saves you days of debugging later.
Get the Full Details
When Millisecond Precision Is Actually a Liability
I worked on an event-sourcing system where every domain event was timestamped at the millisecond. The schema enforced a uniqueness constraint on the combination of aggregate_id plus timestamp. When two events fired from different shards of the same aggregate within the same millisecond — which happened regularly under high throughput — the database rejected the second insert. We lost events. Not silently. The application caught the error and logged it, but the recovery path was broken because the original event had already been committed to memory before the insert failed. The fix was to drop the millisecond timestamp from the uniqueness constraint entirely and use a sequence number per aggregate instead. Sequence numbers are atomic, ordered, and completely independent of wall clock time. Every event stream got a monotonically increasing integer that had nothing to do with how many milliseconds had passed since epoch. We kept the millisecond timestamp for display purposes only. That cut our error rate from about 0.4% of writes down to zero. The broader lesson: if you're using millisecond timestamps as a structural component of your data model — not just for logging or display — you're building on sand. Clock accuracy varies by environment. NTP corrections happen unpredictably. Virtual machines drift. Container orchestration reshuffles nodes. A UTC timestamp accurate to the millisecond is a useful human-readable label. It is not a reliable ordering mechanism.
A Few Numbers That Matter
Here's what actual systems look like when you measure them properly, not what the textbooks say: Standard NTP sync on a good LAN: ±1 millisecond skew between nodes. Acceptable for most audit logging, useless for distributed consensus. Cloud VM without NTP or with large sync intervals: 10–100 milliseconds of skew. This is why AWS recommends using the Instance Metadata Service clock and why Google Cloud has its own internal clock synchronization layer that's separate from the guest OS's NTP stack.
Kubernetes with default settings: node clock skew of 50–200 milliseconds is common in production clusters. The Kubelet reports node conditions, but the container runtime sees the host clock, and different nodes may have been synced at different times depending on when they last contacted the NTP pool. Sub-millisecond timing in user-space code: typical context switch overhead on Linux is 1–10 microseconds. A single syscall to clock_gettime(CLOCK_MONOTONIC) takes about 50–150 nanoseconds on modern hardware. Reading a high-resolution timer isn't expensive, but doing it inside a hot loop on every request adds measurable latency. At 100,000 QPS, that's 5–15 milliseconds of pure overhead per second just from timestamp reads.
What I'd Do Different
When starting a new service today, I define three separate time abstractions from day one: Wall clock time (CLOCK_REALTIME) — only for displaying when things happened to humans. Never for logic. Monotonic duration — for measuring how long operations take, timeout calculations, and rate limiting. Always use the monotonic source available in your language.
Logical ordering — sequence numbers, vector clocks, or Lamport timestamps for establishing causality across services. Never rely on wall clock or monotonic time for ordering decisions in a distributed system. Keep them separate. Document which one each function uses. If a colleague asks why you're using monotonic time for a timeout but realtime for a log entry, the answer should be obvious from the type signature. If it isn't, your API is poorly designed. The number of milliseconds in a second hasn't changed since the SI system was formalized. What changes is how much you can actually trust the number your system gives you when you ask it.