Working With Uncommon Word Builders
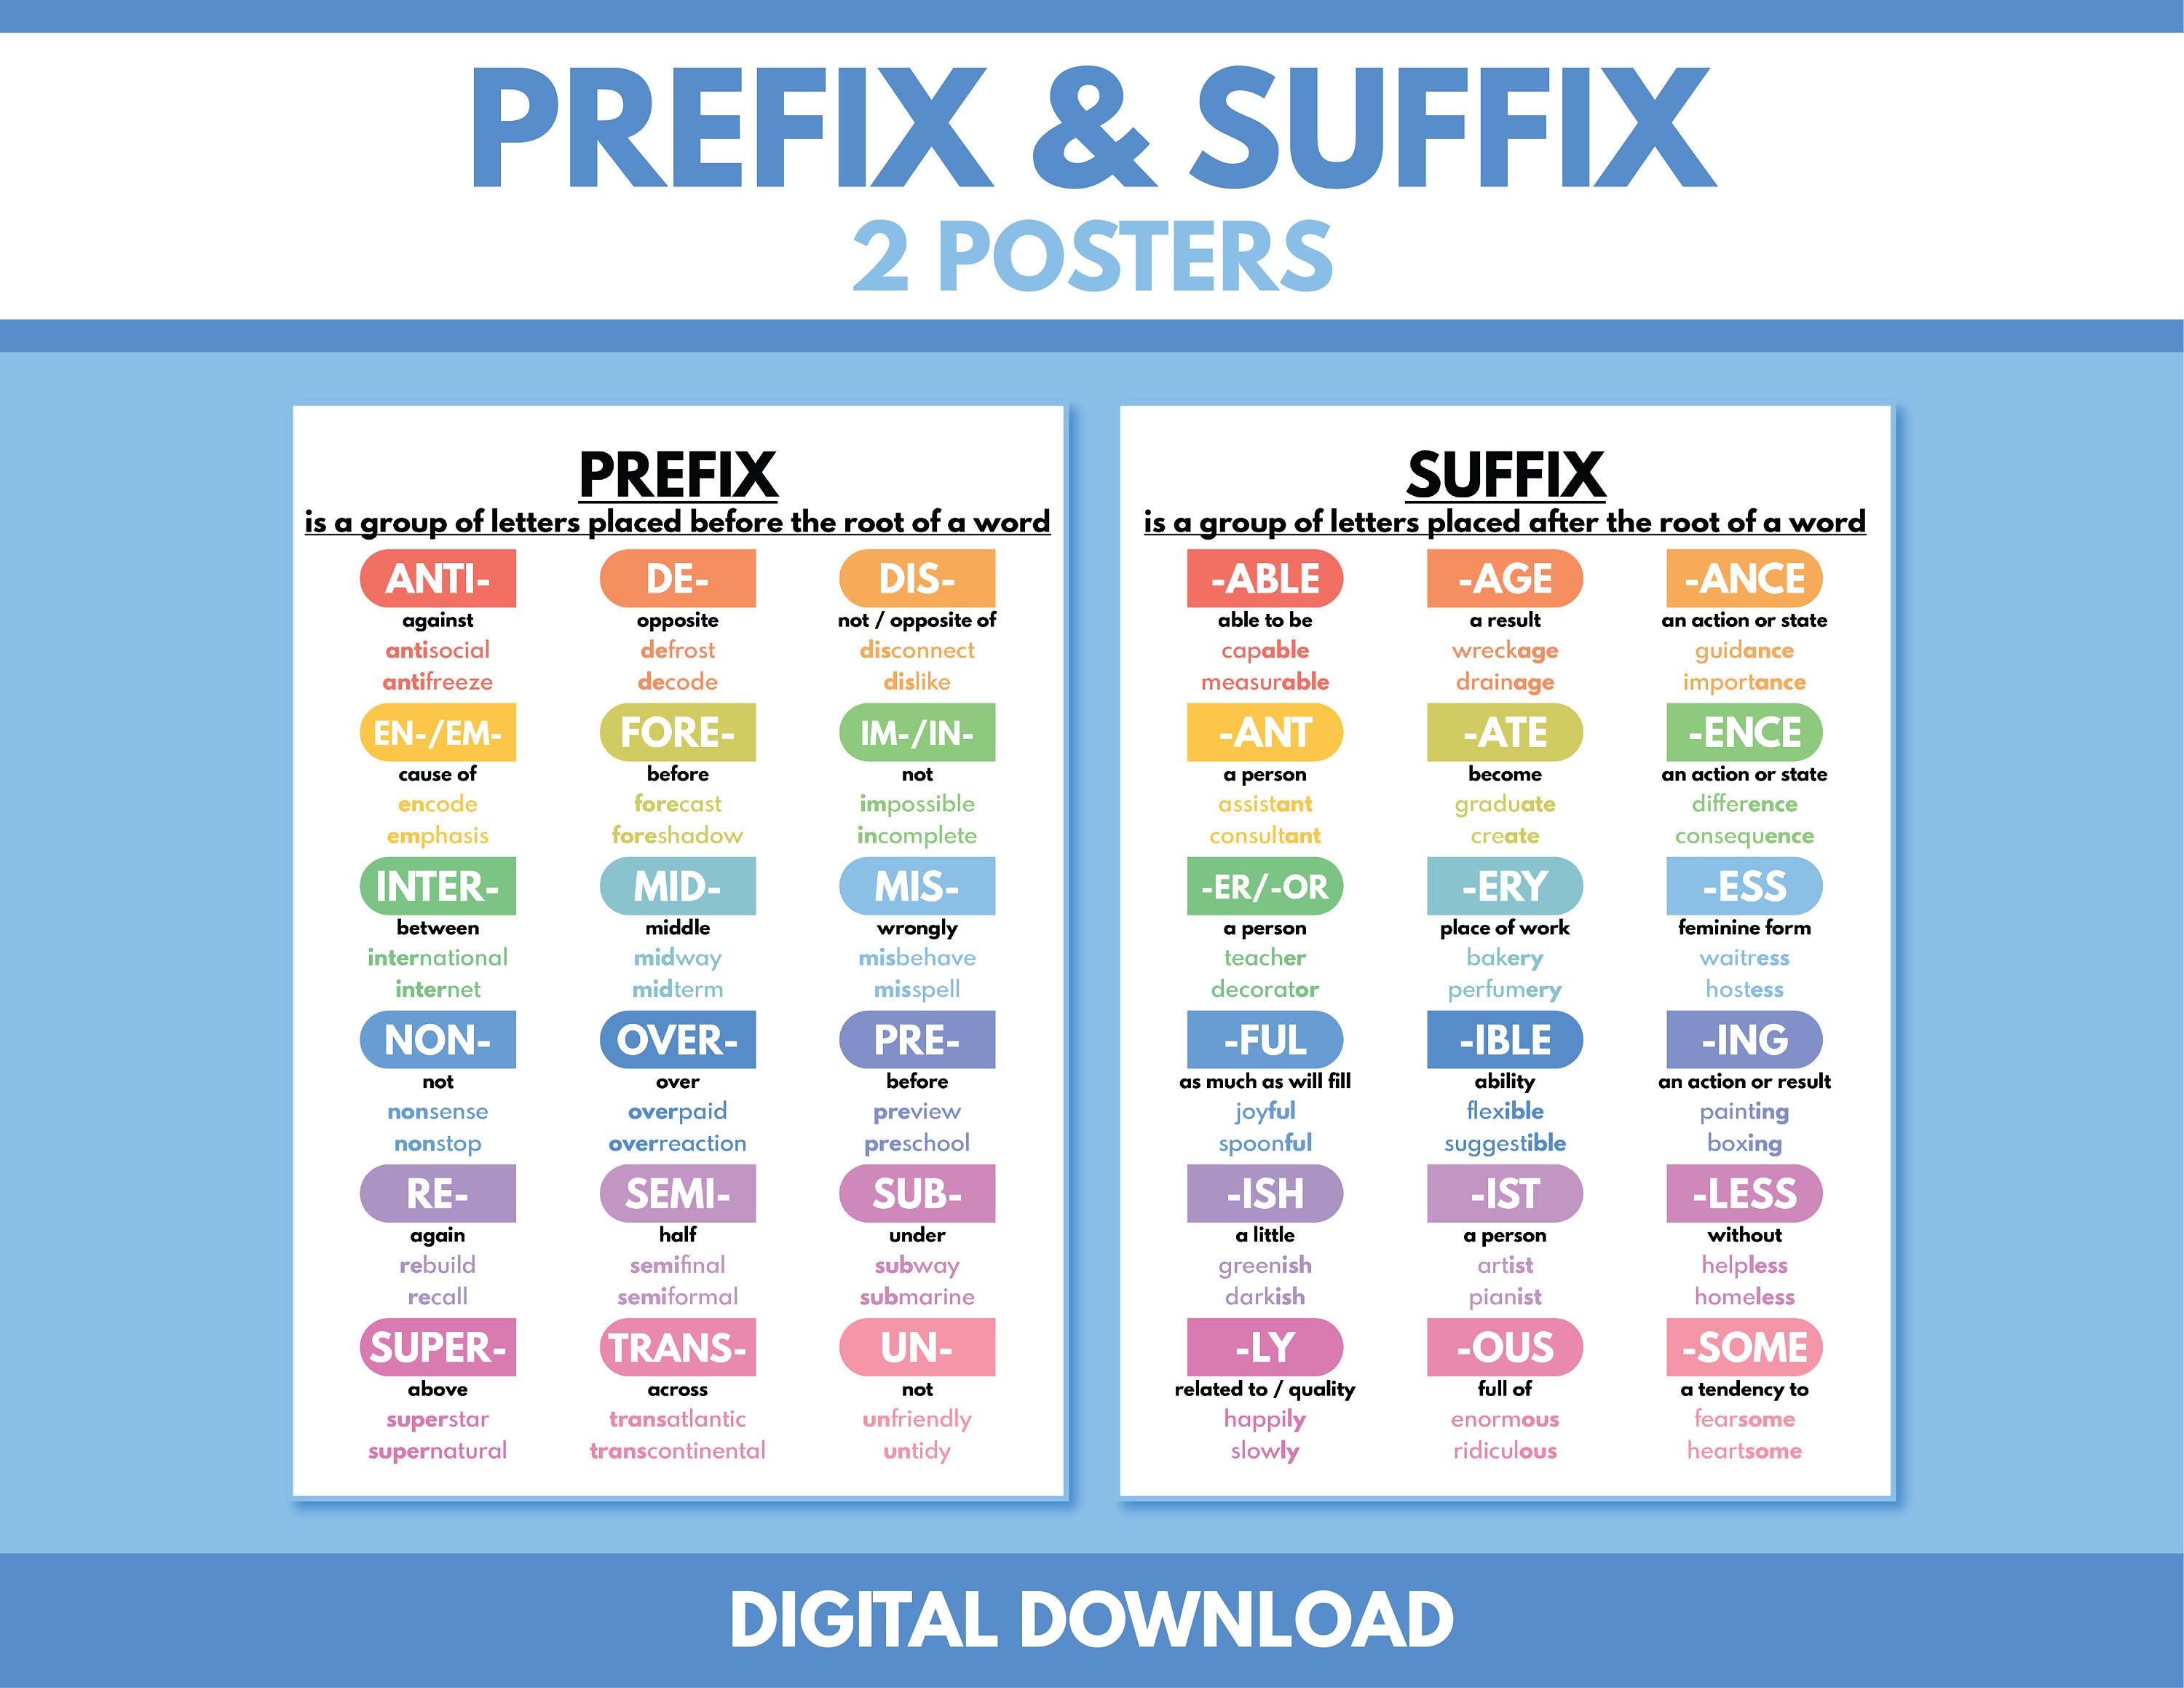
I spent years dealing with morphological analysis when building a custom dictionary for a technical translation pipeline, and one of the messier parts was handling the non-standard affixes that showed up constantly in engineering docs, medical literature, and old-style British writing. Most people learn the obvious ones early — "un-", "re-", "-ing", "-ed" — but then they hit words built from stuff like "fore-", "afore-", "thwart-", "whilom-", or suffixes like "-th", "-hood", "-dom", "-ness" variants that behave completely differently than their modern cousins. This is where it gets annoying fast.What Makes An Eccentric Prefix And Suffix Different
The core issue isn't really about rarity. It's about predictability. Standard affixes have regular behavior you can count on. When you add "un-" to "happy" you know exactly what happens — it negates. Eccentric affixes don't follow those clean rules. Take "do-" as a prefix. It shows up in "do-over," "do-it-yourself," "doodle-doo" — and none of those meanings are actually connected to the verb "do." It's a fossilized element that lost its original semantic content centuries ago. You can't analyze it the same way you'd handle productive affixes. Similarly, suffixes like "-ment" usually attach to verbs cleanly, but "-th" attaches to adjectives to form abstract nouns, and it triggers consonant shifts. "Wide" becomes "width," not "widedth." "Strong" becomes "strength," which is a whole different beast entirely. The pattern exists, but it's irregular enough that any automated parser needs special handling.How To Identify And Work With Them
I built a practical workflow for this that cut our tagging time down significantly. The first step is building a lookup list of known eccentric affixes rather than trying to derive rules for everything. I started with roughly 180 prefix forms and 95 suffix forms that show up in general English corpora but fail productivity tests — meaning you can't reliably generate new words from them without sounding unnatural. The process works like this:Take your source text and run it through a standard tokenizer first. Don't try to do affix stripping and tokenization simultaneously. They conflict on borderline cases and you'll misparse things like "forehand" (where "fore-" is a genuine affix) versus "foreword" (where it's not). Get clean tokens before you start cutting. Once you have tokens, run each one against your eccentric affix database. For every candidate match, record three things: the affix type (prefix or suffix), the base word that remains after stripping, and a confidence score based on whether the base itself is a valid word in your dictionary. A score below 0.6 usually means you're misidentifying the affix boundary.
Common Pitfalls I Ran Into
The biggest problem I hit was what I call affix stacking confusion. Words like "unforeseeable" contain two prefixes — "un-" and "fore-" — and a suffix "-able" attached to the verb "see." A naive system strips from the outside in and produces garbage. You need to work from the inside out, or use a morphological analyzer that understands recursive structure. I solved this by building a simple recursive stripper that checked each layer against a validity dictionary before committing to a cut. Another issue appeared with false eccentrics. Words like "underdeveloped" look like they have eccentric elements, but "under-" and "develop" are both fully productive. These false positives clog your pipeline. The workaround was adding a productivity threshold — if an affix shows up in over 40% of your training corpus attached to novel bases, treat it as standard, not eccentric.I also learned the hard way that some eccentric affixes are diachronically opaque. The "-een" in "wicken" or "kitten" is related to the diminutive suffix "-ling," but the connection isn't surface-level obvious. Don't try to force modern analysis onto Old English derivational morphology without a historical linguistics reference handy. I spent two weeks debugging a tagger that kept misclassifying "-een" as a variant of "-ness" because both produced abstract nouns. They don't share etymology. They just converged phonetically.