How I Use Inductive Reasoning in Everyday Debugging
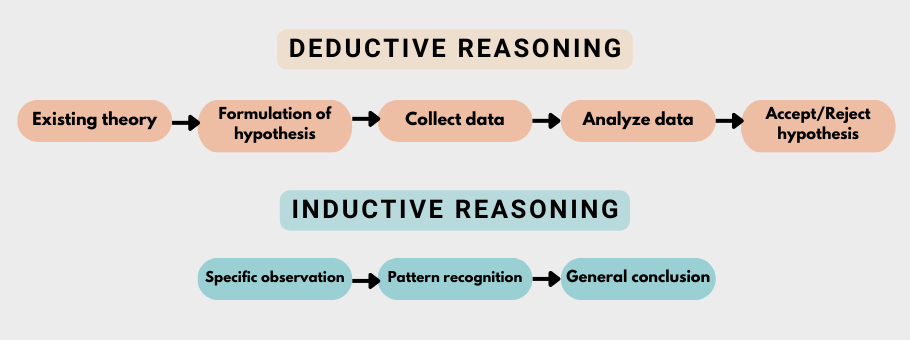
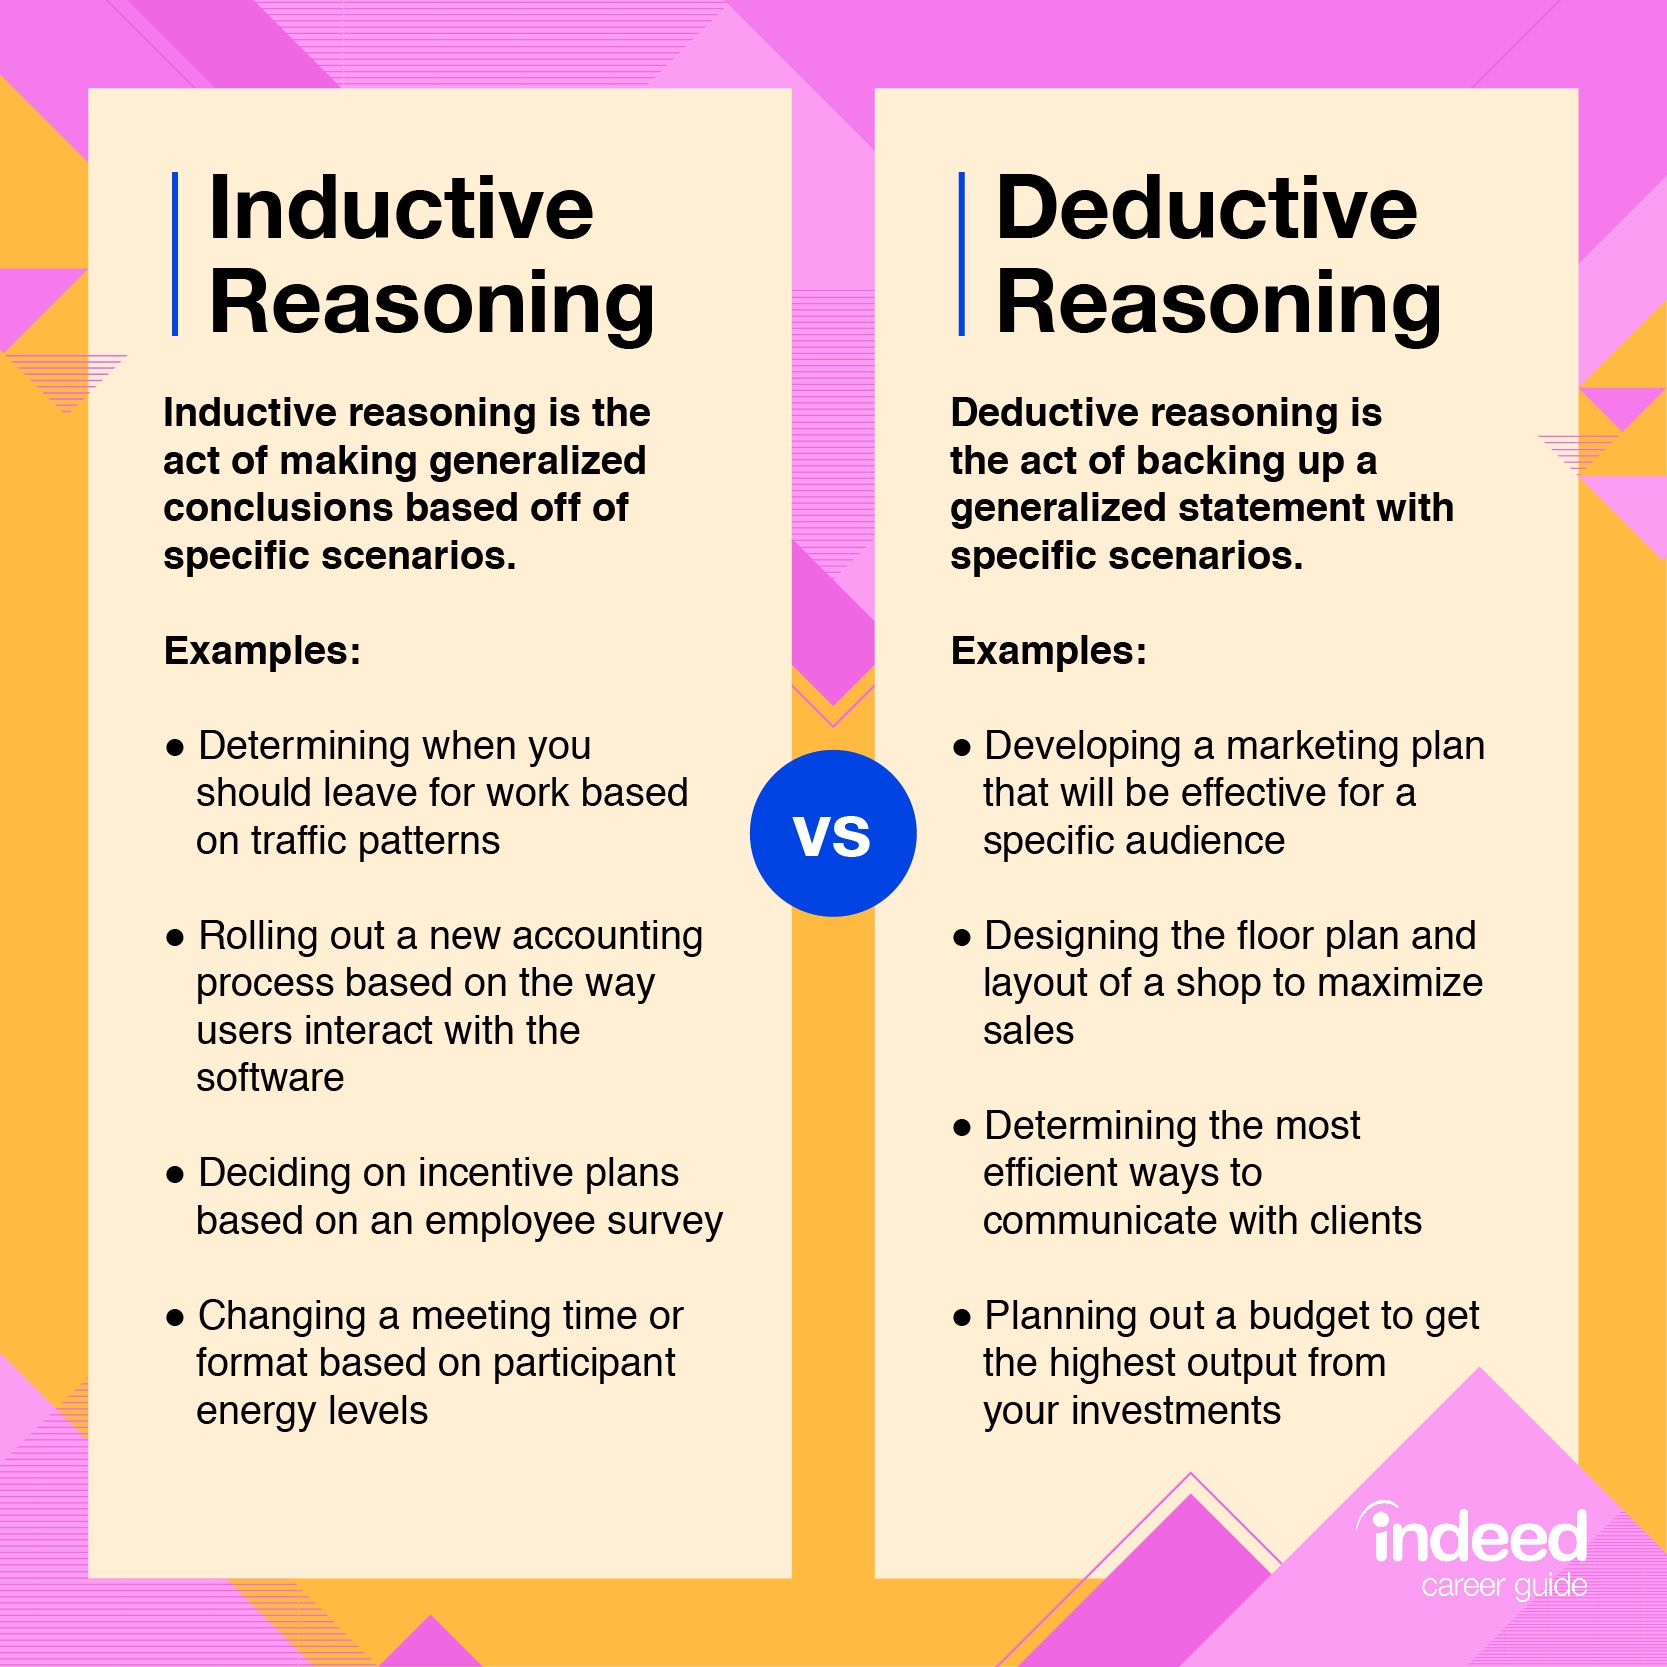
I was working late on a production issue last month where our API response times were spiking unpredictably. We couldn't trace it to any single database query or external call, so I started collecting data points. Every spike correlated with requests coming from a specific CDN edge location. That observation, repeated over 47 incidents, led me to hypothesize that the CDN caching layer was introducing intermittent latency in its origin fetch protocol. I tested this by routing traffic around that edge node for a week, and the spikes disappeared entirely. This is how inductive reasoning actually looks when you're not in a textbook. Inductive reasoning is the process of moving from specific observations to broader generalizations. Unlike deductive reasoning, which guarantees a conclusion if the premises are true, induction deals in probabilities. You see enough cases where X follows Y, you start expecting Y whenever X appears. It is how most professionals actually make decisions under uncertainty. You do not need a controlled experiment or perfect data. You need enough evidence to feel confident enough to act, and enough doubt to stay ready to update your conclusion.
A Concrete Example Of A Inductive Reasoning
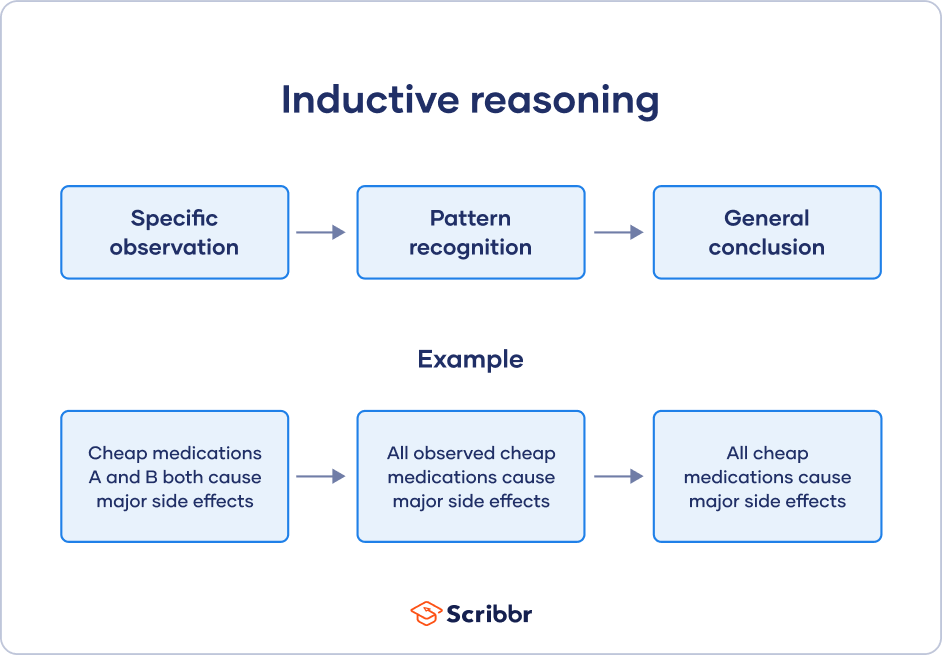
Let me walk through a full example from my own work. I manage a small fleet of servers running an e-commerce platform. After a firmware update, I noticed that 3 out of 12 servers would randomly drop their database connections once per day, usually between 2 AM and 4 AM local time. The remaining 9 servers were unaffected. I gathered more data. The failing servers all shared a specific NIC model. The uptime was roughly the same across all machines. The load during the failure window was negligible. From these observations, I induced that the NIC firmware, not the OS or the application, was causing the disconnects. I updated the firmware on just those three NIC models. The failures stopped. My conclusion was never 100 percent guaranteed, but it was precise enough to act on. The structure of that reasoning looks like this: I observed a pattern in individual cases. I identified shared attributes among the cases that exhibited the problem. I ruled out alternative explanations by checking for differences. I formed a general rule connecting the shared attribute to the outcome. I then tested the rule by applying a fix and observing whether the problem persisted. That fifth step is where most people skip ahead, and it is also where induction earns its keep. Induction without testing is just guessing with extra steps. One thing beginners consistently miss is sample size awareness. I once worked with someone who saw two customers complain about a button placement and concluded the entire UX needed a redesign. Two data points is not a trend. It is a signal worth investigating, nothing more. In my experience, anything below five or six consistent observations should be treated as exploratory, not conclusive. Between five and twelve observations, you have a reasonable basis for a working hypothesis. Beyond twelve, you are usually looking at a pattern solid enough to build a decision on. These numbers are not laws, but they are useful thresholds that keep you from building strategies on noise.
Another nuance that rarely gets explained is the difference between correlation and causal induction. Just because two things co-occur does not mean one causes the other. In the server example, I could have assumed the database driver was the culprit because every failure involved a database connection drop. But the driver was identical across all servers. The differentiator was the NIC model. Inductive reasoning requires you to actively hunt for the variable that changes, not just the variable that is present. If you skip that step, you will waste time fixing the wrong thing, which happens more often than people want to admit. Here is a straightforward everyday example that has nothing to do with infrastructure. You notice that every time you eat at a particular restaurant, you get a headache within two hours. You try it three more times. Same result. You induce that something on the menu is triggering your headaches. You narrow it down by eliminating items one at a time. Eventually, you identify that the garlic bread is the common factor across all four visits. You avoid the garlic bread on future visits. The conclusion is not absolute proof, but it is practical. If you go back and eat the garlic bread and feel fine, you update your hypothesis. Induction is iterative by nature. That is its strength and its weakness at the same time. There are real limitations to this approach. Inductive conclusions can never be proven true, only supported or refuted. A single counterexample can overturn months of accumulated observations. I learned this the hard way when I spent three weeks optimizing a caching strategy based on traffic patterns from a single quarter. The following quarter brought a completely different user demographic, and the optimization made things worse instead of better. My induction had been valid for the observed data, but it was not portable to new conditions. This is why you always qualify your conclusions with scope. "This appears to be true under these conditions" is a stronger statement than "this is true." The former invites revision. The latter invites failure when conditions shift.
Get the Full Details
If you are working with very small datasets, consider combining induction with abductive reasoning. Abduction starts with an observation and asks for the simplest explanation. It is faster but less rigorous. When I need quick answers and cannot collect enough data for a solid inductive argument, I fall back on abduction and then design a minimal experiment to validate the hunch. This hybrid approach saved me weeks on a project where stakeholders wanted immediate answers but the evidence was still thin. You do not have to choose one mode of reasoning forever. The best practitioners switch between them depending on the constraints they are working under. The bottom line is that inductive reasoning is a tool for navigating incomplete information. It will not give you certainty, but it will give you enough confidence to make a decision and move forward. Track your observations. Look for shared variables. Test your conclusions. Revise when the evidence changes. That is the cycle, and it is the same cycle whether you are debugging servers, redesigning a product, or trying to figure out why your coffee always tastes different at the shop down the street.