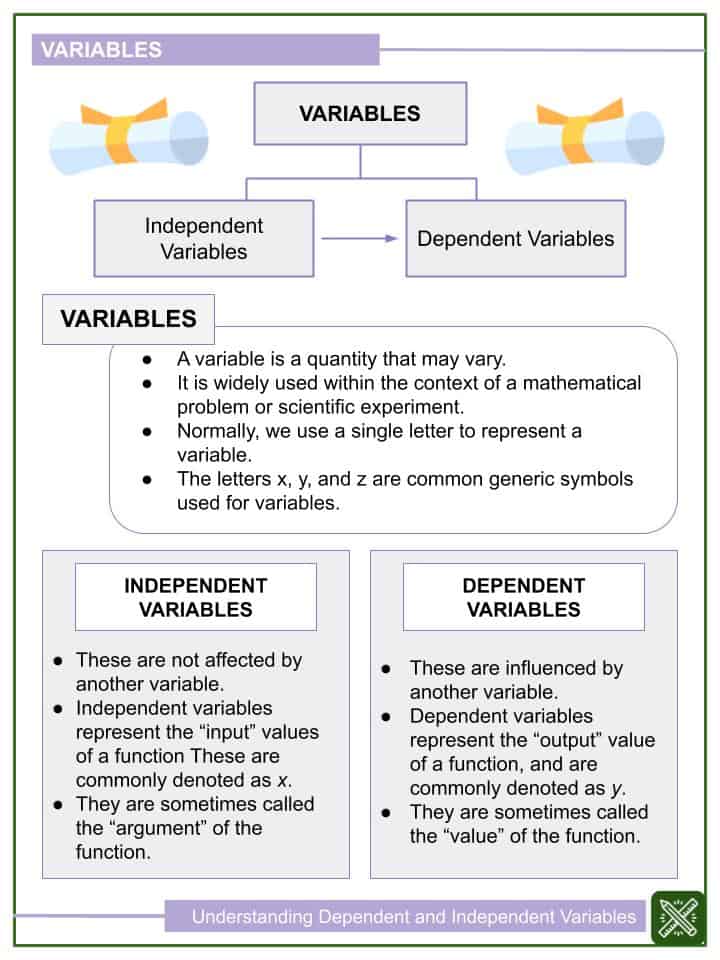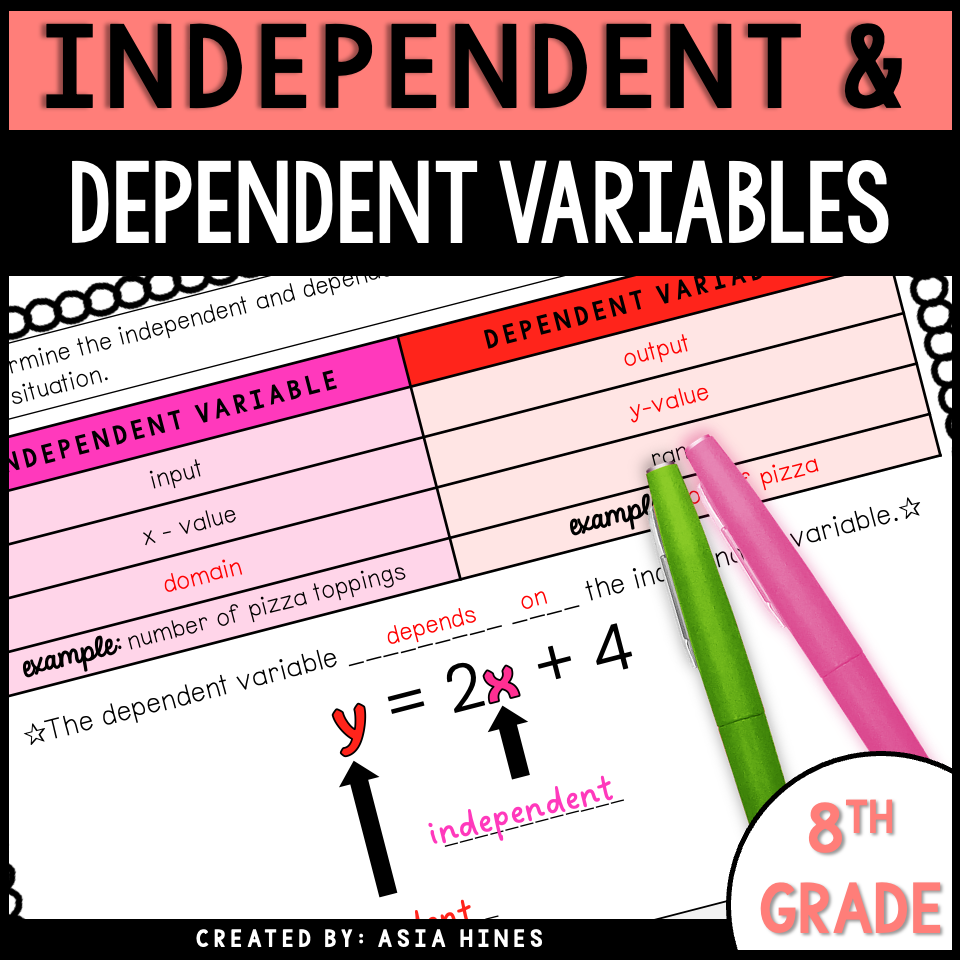
Dependent Variables Are Just The Output You Measure
You are probably seeing this because a homework assignment just threw it at you, or maybe you are trying to figure out what goes on the y-axis for a lab report. A dependent variable is the quantity whose value depends on another quantity. In math and science, you pick something to control or set, and then you measure what happens. The thing that changes as a result is your dependent variable. Here is a concrete one. You run a small freelance writing service. Your rate is fifty dollars per page. If you write five pages, the total charge comes out to two hundred fifty dollars. The number of pages is your independent variable. The total cost is your dependent variable. You can rewrite that as the equation C = 50p. Change p, and C follows. It is not guessing. It is a direct mathematical dependency. Another example people mess up constantly. You are measuring water heating over time. The clock ticks forward on its own, so time is independent. The temperature reading depends on how long the heater has been running, so temperature is dependent. The equation looks like T = 95 + 1.2t if you start at ninety-five degrees and climb at one point two degrees per minute. Plug in t, get T.
The reason I keep coming back to simple examples is that students tend to overcomplicate things once the variables stop being numbers and start being abstract concepts. Let me walk through a slightly messier case I see all the time in tutoring sessions. Suppose you are modeling the area of a rectangle where the length is always three units longer than the width. You could write A = w(w + 3). Here, width is the independent variable and area is the dependent variable. You pick a width, calculate the corresponding area, and plot those pairs. The dependent variable sits on the vertical axis. The independent variable sits on the horizontal axis. That convention exists for a reason, not as a random rule to memorize. I ran into a case last year involving a physics lab where students were supposed to identify the dependent variable for an experiment measuring the period of a pendulum against string length. The question seemed straightforward. The issue was that half the class wrote mass as the dependent variable because they had weighed the bob first. Mass was actually a controlled variable. They kept it constant. The period depended on length, not on the mass they happened to have hanging around. Once they realized that controlling something does not make it the output they are tracking, the whole graph made sense.
How To Identify The Dependent Variable Without Overthinking It
Start by asking what the problem is trying to find. If the prompt says something like calculate the cost, determine the distance, or predict the temperature, the thing you are solving for is almost certainly dependent. Then look for the phrase depends on. If the problem states that one quantity depends on another, the second quantity in that relationship is independent, and the first is dependent. When you are working with equations in standard form, the dependent variable is usually isolated on one side. If you see y = 3x minus two, y is dependent on x. If the equation is rearranged as 2x plus 5y equals ten, you need to solve for y first to see the dependency clearly. That step alone fixes about thirty percent of the confusion I see in introductory courses. Here is a practical workflow I use when students hand me word problems. Read the problem once. Circle every noun that represents a measurable quantity. Ask yourself which quantity you would change first if you were running the experiment or scenario. Ask yourself which quantity you would record afterward. The second answer is your dependent variable. It is that mechanical, but it catches more students off guard than it should.
Get the Full Details

I will share a counter-intuitive point that rarely gets covered in textbooks. Sometimes a variable that looks independent is actually dependent in a deeper model. Consider a supply chain problem where demand depends on price, but price depends on production cost, and production cost depends on raw material volume. If you only look at one link in that chain, you might mislabel price as independent when it is really dependent on cost. The fix is to draw the causal chain first. Maps like that expose which variables are truly exogenous and which are nested inside other relationships. Another nuance that trips people up is when both variables influence each other in a feedback loop. Population models with carrying capacity do this. Birth rate depends on population size, and population size changes based on the birth rate. In those cases, neither variable is cleanly dependent in a single direction. You move to systems of equations or differential equations, and the dependent variable designation becomes tied to the specific equation you are analyzing at that moment, not to the system as a whole.
Common Pitfalls That Waste Time
The biggest time sink I see is mixing up causation with correlation. Just because two variables move together in a dataset does not mean one is dependent on the other. If ice cream sales and shark attack counts both rise in summer, one is not causing the other. Temperature is a lurking variable driving both. Assigning dependency based purely on correlation without a causal model leads to garbage equations and worse, garbage conclusions drawn from them. A second pitfall is flipping axes without realizing it. When you plot data, putting the wrong variable on the y-axis makes the slope and intercept mean the opposite of what you think they mean. I spent an afternoon last semester untangling a regression output where a student had plotted fuel efficiency on the horizontal axis and engine size on the vertical axis. The coefficient looked fine numerically, but the interpretation was backwards. The fix is to decide on dependency before you open any graphing tool, not after. A third one is assuming linearity when the relationship is not linear. Many students default to linear models because those are what get taught first. Temperature conversion is linear. Distance equals rate times time is linear. But area grows with the square of side length. Population growth under ideal conditions is exponential. If you force a linear model onto a nonlinear dependency, your predictions will drift badly. The residuals will show it. If your model underestimates at the low end and overestimates at the high end, or vice versa, your functional form is wrong.
What This Approach Does Not Handle Well
I need to be blunt about where the dependent-variable framework breaks down. In multivariate settings with several interacting independent variables, labeling a single dependent variable can mask important interactions. Consider a model where sales depend on both advertising spend and seasonality. If you treat seasonality as a constant offset instead of a second independent variable, your estimate of the advertising effect will be biased. You need multiple regression, not a simple bivariate story. Another failure mode is when the dependent variable is not directly measurable. Structural equation modeling exists because researchers sometimes need to infer dependency among latent constructs like intelligence or satisfaction. Those are not quantities you can drop on a scale. You build composite indicators and estimate the dependency structure through covariance patterns. If you try to force that into a standard dependent-variable worksheet, you will produce numbers that look precise but are essentially meaningless. Time series data also exposes the limits of a clean dependent-independent split. In autoregressive models, a variable depends on its own past values. Is the past value independent or dependent? It is both, depending on the equation. Lags create a circular dependency that simple terminology cannot capture. You move to lagged dependent variable models or state-space representations instead.
Practical Steps To Work With Dependent Variables Confidently
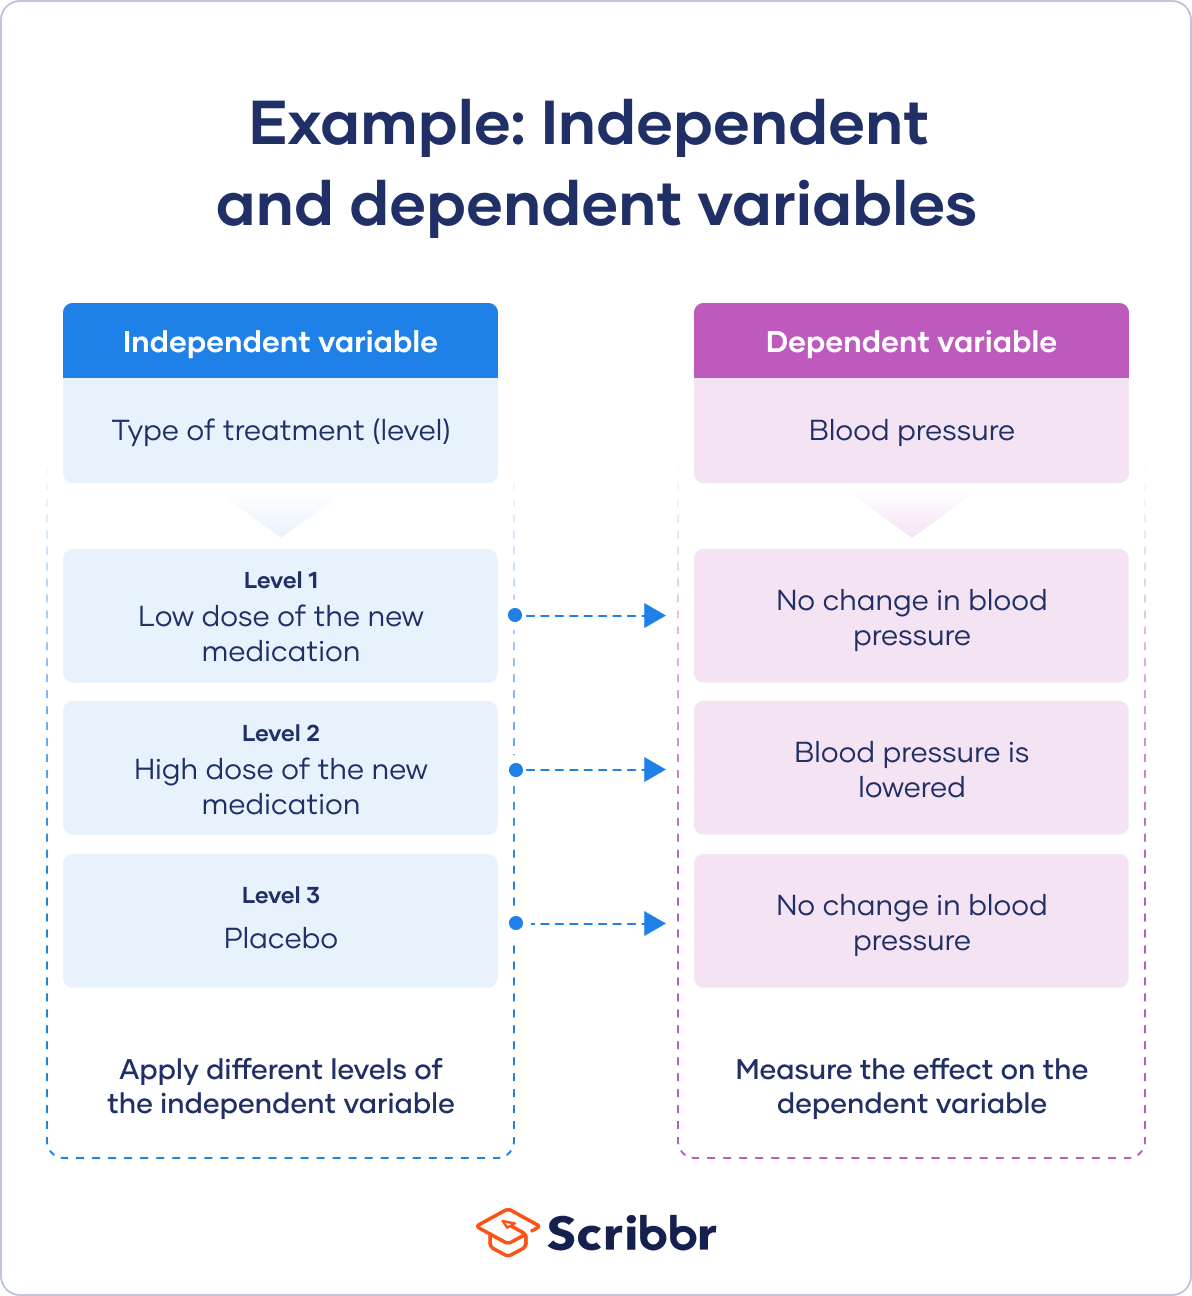
First, write down the full scenario in plain language before touching any symbols. Second, list every measurable quantity and label each one as something you control, something you observe, or something that is held constant. Third, pick the quantity whose value you want to predict or explain, and call that dependent. Fourth, build the equation or model, check the units, and verify that changing the independent input produces a reasonable change in the output. Fifth, test the model against at least one data point you already know to catch algebra mistakes early. When you are using software like Excel, Python, or a graphing calculator, put the independent variable in the leftmost column and the dependent variable in the next column. If you reverse them, most tools will still compute a fit, but the output labels will confuse you later. I have lost count of the spreadsheets I have inherited where the analyst swapped the columns and then presented a scatter plot with a backward-sloping trend line as if it were normal. It is not. If you are working with experimental data and the dependent variable has high measurement noise, consider whether your sampling frequency matters more than your model complexity. More observations at the right intervals often beat a fancy nonlinear fit on sparse data. I ran a quick audit on a dataset where someone had twenty points across a wide range and tried a fourth-degree polynomial. The curve passed through every point, which sounds good until you test it on new data, at which point it overshoots wildly. A simple linear fit on fifty well-placed points would have been far more useful.
A Note On Using This Concept In Real Projects
When I consult on projects that involve forecasting or optimization, the dependent-variable step is usually the shortest part of the process but also the part most likely to be rushed. Teams jump into curve fitting before they clarify what outcome they actually care about. If you are modeling customer churn, the dependent variable might be churn probability, but the business question might be retention revenue. Those are related but not identical. Define the outcome metric first. Then decide which inputs drive it. Then build. There is no shortcut around that ordering. I have watched groups spend weeks refining models only to realize later that the dependent variable they chose did not match the decision they needed to make. The fix is never to add more variables. The fix is to go back and restate the problem in one sentence before you touch the data again. Dependent variables are not a trick. They are just the labeled output of a relationship you are trying to describe. Pick the output. Find what drives it. Write the equation. Check it against known values. That sequence handles the vast majority of cases you will encounter in coursework and in practical work, and it prevents the expensive mistakes that happen when you reverse the logic.