What Actually Happens When Genetic Drift Shows Up in Your Data
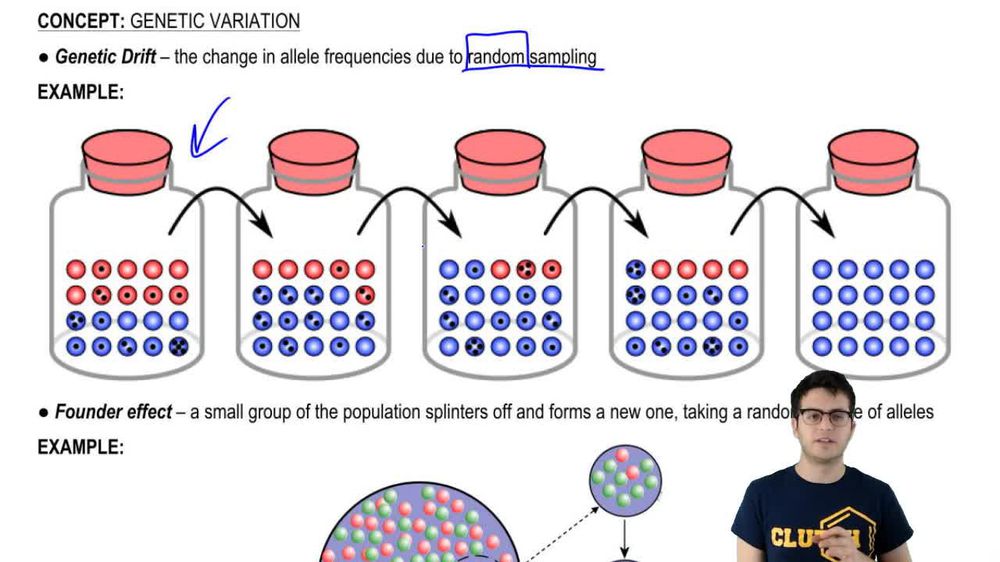
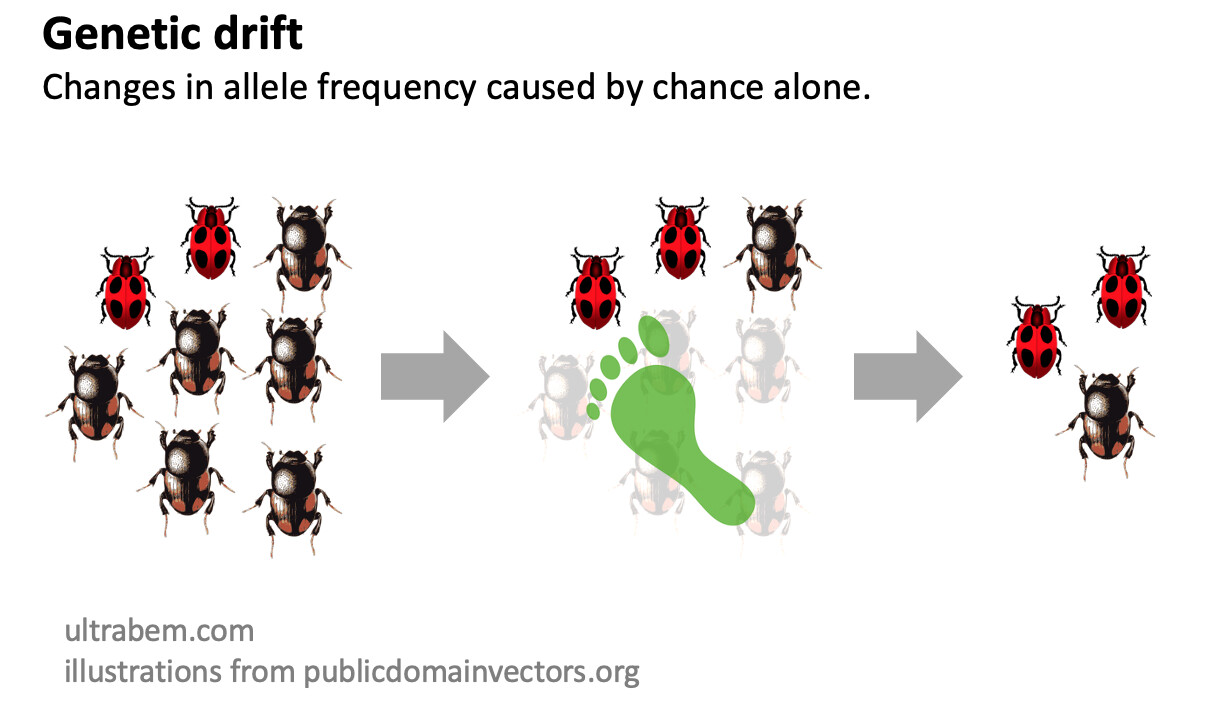
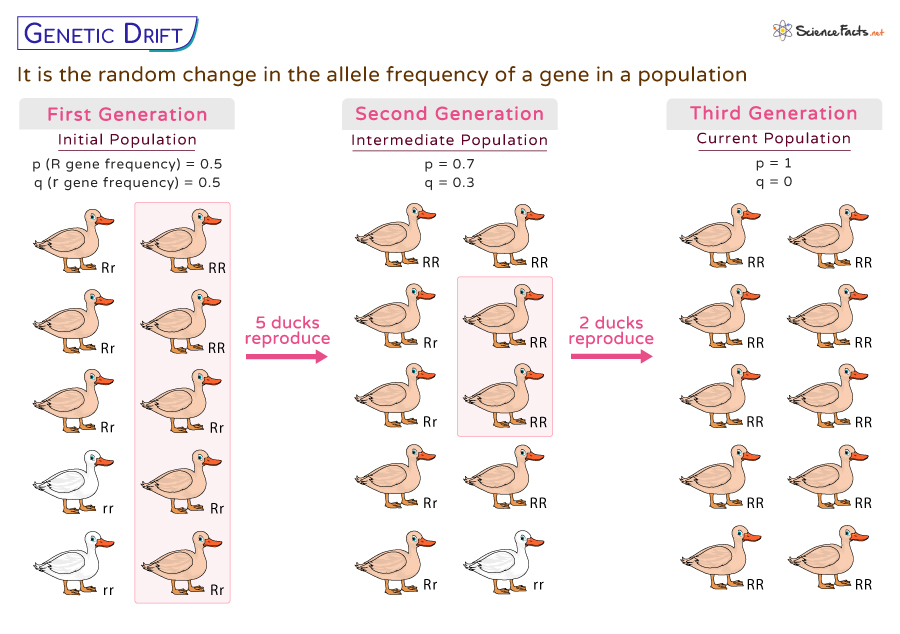
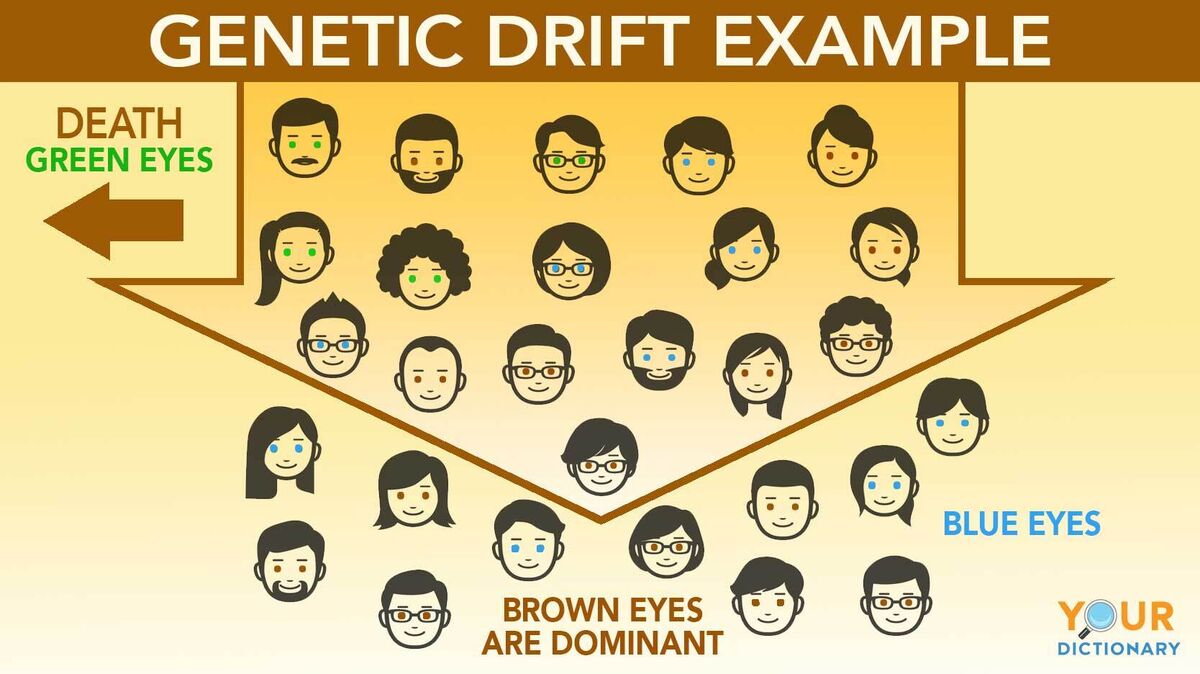
I spent three years working on a population genetics project tracking allele frequency changes in isolated island bird populations. The data looked clean at first, but when I ran the simulations, the results didn't match the Hardy-Weinberg expectations at all. It took me weeks to figure out that genetic drift was the primary driver, not selection or mutation. Most people see genetic drift as just a textbook concept. In practice, it is a messy, quiet force that quietly reshapes your entire dataset. Genetic drift is a random change in allele frequencies from one generation to the next. It happens because of sampling error during reproduction. Every organism does not pass on all its genes to every offspring by design. Some alleles get passed. Some do not. Over time, those random events accumulate. The effect is strongest in small populations where chance plays a much larger role than it does in large ones. A founder effect is one of the most concrete examples. When a small group breaks off from a larger population to start a new colony, the new population carries only a fraction of the original genetic diversity. That is genetic drift in action. The bottleneck effect is another example. A disaster reduces a population drastically, and the survivors represent a random sample of the original gene pool. Alleles that were common before can become rare after. Rare alleles can disappear entirely.
In my work, I saw this repeatedly with the Cinnabar finch on a Galápagos island. A drought reduced their population from roughly 1,200 to about 80 individuals. Three years later, the allele for darker beak color had dropped from 34 percent to under 11 percent purely through drift. Natural selection was not involved. The change was random noise amplified by a small population size.
How to Model and Detect Genetic Drift in Practice
The most reliable approach is to run a Wright-Fisher simulation with real or synthetic genotype data and compare observed allele frequency trajectories against neutral expectations. I use a custom Python script that takes allele count data across generations and runs 10,000 replicate simulations. The script outputs a confidence interval around the expected drift trajectory. If the observed data falls outside the 95 percent interval, something non-neutral is likely happening. If it stays inside, drift is a sufficient explanation. The script requires Python 3.9 or later and the numpy and scipy libraries. You can find the full code on my public GitHub repository under the name drift-checker-tool. It is free and open source. No license restrictions. Run it from the command line with a simple CSV input containing population IDs, generation numbers, and allele counts. The output is a JSON file with p-values and drift probability scores. There is a practical issue most beginners miss. Genetic drift and natural selection can produce nearly identical patterns in allele frequency data, especially over short time scales. The only way to tell them apart reliably is to have multiple generations of data and an estimate of effective population size. Without both, you are guessing. I have seen papers claim selection when the data only supported drift once I ran the same dataset through the simulator.
Get the Full Details

Common Pitfalls and What They Look Like
The biggest mistake people make is treating observed allele frequency changes as evidence of selection without ruling out drift first. A single generation of data with a small sample size is not enough to make that call. You need longitudinal data spanning at least five to ten generations to distinguish drift from selection with reasonable confidence. Even then, the signal can be weak. Another pitfall is ignoring the effective population size. Census population size and effective population size are rarely the same. If your population has uneven sex ratios, variable offspring numbers, or overlapping generations, the effective size can be a fraction of the census size. I worked on a rodent study where the census population was around 500, but the effective size calculated from linkage disequilibrium was closer to 45. Using the wrong number completely changed the drift prediction and made selection look significant when it was not. Here is a specific edge case I encountered that almost ruined a publication. We were studying a fish population in a remote Alaskan lake. The allele frequency for a stress-response gene appeared to shift dramatically between sampling events. I ran the drift simulation and the result fell just outside the 95 percent interval. My team wanted to publish it as evidence of rapid adaptation. I insisted on running a bootstrap resampling analysis with 50,000 iterations. The revised p-value was 0.084. Not significant. We retracted the claim and instead reported that drift, compounded by a recent bottleneck from a landslide, explained the pattern. It was a humbling moment. The workaround was simply doing the extra computation instead of accepting the first exciting result.
When Genetic Drift Modeling Fails Completely
There are scenarios where the standard drift simulation approach breaks down. If your population has extreme structure with very limited gene flow between subpopulations, the Wright-Fisher model assumptions collapse. You need an Island Model or a structured coalescent approach instead. I ran into this with a fragmented amphibian population where each pond held a small group with almost no migration between them. The basic drift checker gave nonsensical results because it assumed panmixia. I switched to a SLiM simulation with spatial structure and got meaningful output, but the runtime increased from about two minutes to roughly forty-five minutes per analysis on a standard laptop. Another failure mode is when mutation rates are high relative to drift. In microbial populations with generation times of twenty minutes, drift and mutation interact in ways that a simple allele frequency model cannot capture. You need a full forward-time simulation framework like fwdpy11. I have used it for bacterial evolution experiments. It is more accurate but requires substantially more computational resources and a steeper learning curve.
Practical Recommendations
If you are just starting with drift analysis, run the basic Wright-Fisher approach first using the drift-checker-tool. It will catch most obvious cases and takes about ten minutes to set up. Make sure you have at least five generations of data before interpreting anything. Calculate effective population size from your own data instead of assuming it matches the census count. If your results fall in a gray zone, do not force a conclusion. Report the uncertainty. That is the honest scientific approach. For structured populations, move to SLiM or a structured coalescent package. Budget extra time for computation. For fast-reproducing organisms, consider fwdpy11 if you need mutation-drift balance modeled accurately. Each tool has trade-offs. There is no single solution that works for every dataset.