Where Things Actually Go Wrong
Explain The Ethical Issues In The Use Of Information Technology
I got dragged into an ethics review last year for a data pipeline that was technically legal but practically ugly. We were aggregating user location pings from a mobile app to optimize routing for a logistics client. The privacy policy, as written, covered it. The terms of service signed away whatever rights the users had. But when I looked at the actual dataset, I saw we could reconstruct individual home addresses and daily routines for about twelve percent of our users. The client wanted to sell that inference layer to a third-party data broker. I flagged it. They pushed back hard because the law didn't explicitly forbid it. That's the thing nobody tells you about IT ethics. The real problems don't live in the gray areas where lawyers are comfortable. They live in the spaces between compliance checkboxes and what actually happens when people use your systems. I've spent more time debugging ethical failures than I have debugging code, and honestly, the debugging takes longer because you can't reproduce the same bug twice. Let me walk through how this works in practice rather than what the textbooks say.
Privacy Isn't Just Data Minimization
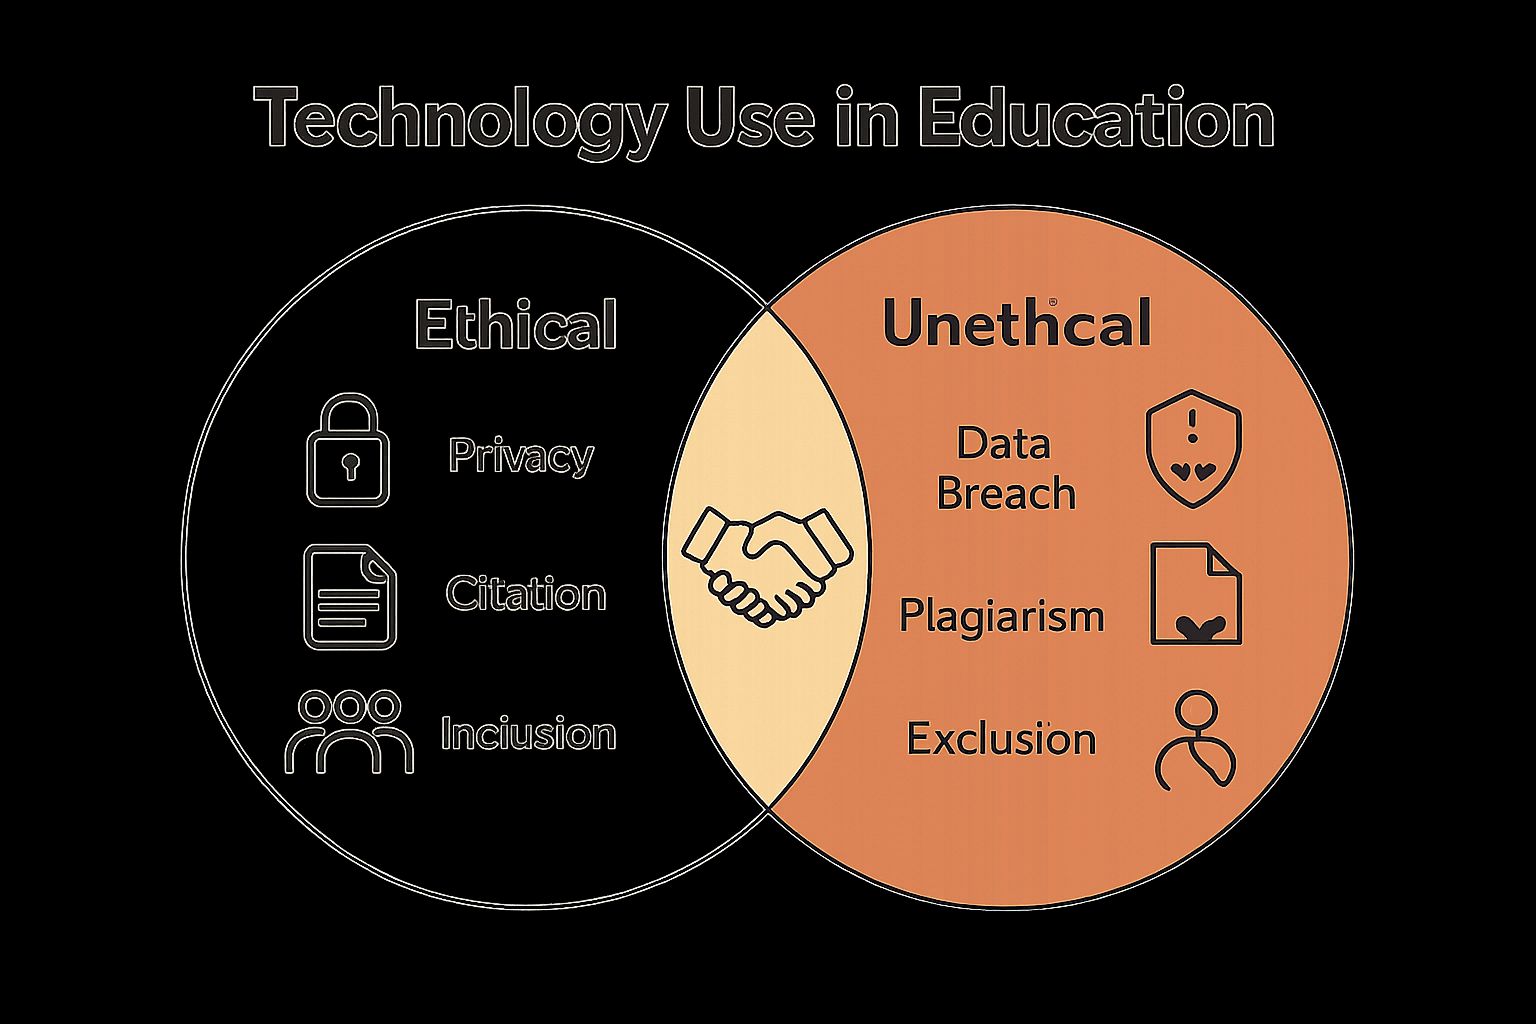
Most teams treat privacy as a checkbox exercise. Collect what you need, encrypt what you store, delete what's old. That's surface-level compliance. The actual ethical problem shows up in inference and aggregation. When you combine seemingly harmless datasets, you create new information that no single source contained. Location data plus purchase history plus device type becomes a behavioral profile that reveals health conditions, political leanings, and religious practices. GDPR calls this purpose limitation. In practice, it means the ethical obligation extends beyond what you directly collect to what your systems can deduce. I worked on a project where we were building a recommendation engine. The input features were benign: browsing history, click patterns, session duration. But the model started inferring socioeconomic status with about eighty-four percent accuracy by cross-referencing product preferences and time-of-day usage patterns. We had never asked users about their income. The inference came from behavioral signals alone. The engineering team wanted to feed that into ad targeting. We decided not to, but the technical capability was there from day one. This is the counter-intuitive part that most teams miss. Privacy isn't about hiding data. It's about understanding what can be reconstructed from your data and building guardrails around the inference layer, not just the storage layer. Most security audits check the storage layer. Almost none of them audit the inference layer.
Algorithmic Bias Is a Maintenance Problem
Bias in AI systems isn't a one-time training issue. It's something you inherit and compound every time you deploy a model and never re-audit it. I've seen hiring algorithms degrade silently over eighteen months because the training data became stale while the population being screened changed. The model wasn't racist or sexist in any intentional sense. It was just optimizing for patterns that existed in historical data that no longer reflected the candidate pool. The specific mechanism that gets overlooked is feedback loop contamination. When a biased model makes decisions, those decisions become new training data. A loan approval system that unfairly denies minority applicants will generate fewer approved loans for those demographics. The system then learns that those demographics are lower quality borrowers, which confirms the original bias. The loop tightens with every deployment cycle. Breaking it requires active counter-measures, not just periodic reviews. The workaround I settled on for a production system was implementing a demographic parity constraint during training and running a separate fairness auditor that compared outcomes across protected groups every thirty days. The cost was roughly twenty percent additional compute per training run and about four hours of engineering time per audit cycle. Worth it, because the alternative was deploying something that would quietly discriminate and we'd only find out after a lawsuit.
Get the Full Details
Surveillance Creep Is the Default Trajectory
Every monitoring tool you build for one purpose gets repurposed for another. I built an intrusion detection system for a healthcare provider. It was meant to flag unauthorized access to patient records. Within six months, management was using the same logs to track employee bathroom breaks by monitoring login and logout times. The system had the technical capacity to do this from the start. The original authorization didn't cover it. Nobody revisited the authorization when they started using it for something else. This is the surveillance creep problem. It's not dramatic. It happens incrementally. A tool approved for security gets used for productivity monitoring. Productivity monitoring gets combined with location tracking. Location tracking gets shared with a parent company. Each step is small. Each step has a plausible justification. By the time you're at the end of the chain, you've built something that would raise serious ethical flags if you evaluated it from a clean slate. The safeguard that actually works is a formal data use agreement that specifies not just what data can be collected but what questions it can answer. When someone wants to repurpose the system, they have to go through a review that asks whether the new use would have been permissible under the original agreement. It sounds bureaucratic. It prevents the slow drift that turns monitoring tools into surveillance tools.
The Consent Problem With Complex Systems
Users consent to things they don't understand. This isn't a new observation but the scale has changed. Modern IT systems involve data flows across dozens of vendors, processors, and subprocessors. A typical mobile app might share data with fifty different SDKs. The average user reads about twelve seconds of a privacy policy before scrolling past. The policy document itself is often contradictory, using different definitions for the same term in different sections. I encountered this directly when auditing a SaaS platform. The privacy policy stated that data was processed only in the United States. The infrastructure diagram showed failover clusters in Ireland and Singapore. The subprocessor list, updated three weeks earlier, added two data processors in Brazil that weren't mentioned anywhere in the policy. The system was designed so that the policy document, the technical implementation, and the operational reality were three different things. Nobody was intentionally lying. The complexity just made accurate representation impossible. Meaningful consent requires that the information a user receives matches what their data actually does. That's extremely difficult to achieve at scale. The practical fix isn't better privacy policies. It's layered notices that surface the most material information first, dynamic consent interfaces that let users adjust permissions in real time, and automated compliance checks that verify the technical implementation matches the documented policy. The last one is the one that matters most. Without it, the policy is just marketing copy.
Accountability Gaps in Automated Systems
When an automated system makes a harmful decision, the question of who is responsible is almost never clear. I was consulting for a company that deployed an automated claims denial system for insurance. It denied a claim that should have been approved. The claimant had a pre-existing condition that the system incorrectly classified as newly developed based on a data matching error. The error traced back to a vendor-provided medical coding update that was deployed without proper validation. The vendor said they weren't responsible because the integration was the client's duty. The client's engineering team said they followed the vendor's documentation. The product manager said the model was deployed within confidence thresholds. The compliance team said the model had passed all required tests. Everyone had done something reasonable. The person who got denied had done nothing wrong and was now stuck in a gap where no single party was accountable. This is the accountability hole that automated systems create. Each component of the system can be individually justified. The aggregate harm emerges from the interaction between components, and no single actor owns the interaction risk. The workaround I recommend is establishing a named accountability owner for every automated decision system before it goes to production. This person doesn't need to understand every technical detail. They need to own the responsibility for what the system does and have the authority to pull the plug. It sounds simple. Most systems I've reviewed don't have this.

Environmental Costs Are Externalized Ethics Problems
Training a large language model can emit as much carbon as five cars over their entire lifetimes. Most organizations that build or deploy these systems don't include the environmental cost in their decision-making. The metric that matters is carbon per inference, which varies wildly depending on model size, hardware efficiency, and whether the data center uses renewable energy. A model running on a coal-powered grid in one region produces roughly three times the emissions of the same model running on a hydro-powered grid elsewhere. I pushed for carbon-aware deployment scheduling at a company where I was working. The idea was to shift non-urgent model training to off-peak hours when the grid mix included more renewable energy. The result was a twelve to eighteen percent reduction in effective carbon emissions with no performance degradation. The pushback came from the finance team, which didn't track energy source composition, only total energy cost. From their perspective, the electric bill was unchanged, so there was no business case for the change. The ethical argument required translating carbon intensity into dollar terms that the existing financial models could process. It's a practical example of a broader pattern. Most IT ethical issues involve externalities that the current system design doesn't account for. Privacy violations, biased outcomes, surveillance creep, accountability gaps, environmental costs. These are all costs that get pushed outside the boundary of normal decision-making frameworks. Making them visible requires expanding what metrics count as relevant.
What Actually Works in Practice
After dealing with enough of these problems, I've settled on a set of practices that aren't glamorous but they catch more issues than theoretical frameworks ever have. Red team reviews before deployment. Not security red teams. Ethics red teams. People whose job is to try to break the system in ways that cause harm. They should include people outside the project, ideally from adjacent teams who don't share the same assumptions about why the system exists. Maintain a decision log. Every time you make a choice about data handling, model behavior, or system access, write down what you chose, why, and what the alternatives were. I know this sounds like overhead. It's not. When something goes wrong, and it will, that log becomes the difference between understanding what happened and spending three weeks trying to reconstruct a chain of reasoning that never existed on paper.
Set hard limits on data retention. Not policy-based retention. Technical enforcement. Data that passes its retention deadline gets deleted automatically. The default should be shortest practical retention, not longest permissible retention. Most organizations collect data assuming they might need it and then never use it. Audit inference, not just collection. Run fairness checks, accuracy parity tests, and re-identification risk assessments on a regular schedule. The schedule should be tied to model updates, not calendar dates, because drift happens on deployment cycles, not fiscal quarters. Give users real control, not just settings. Most privacy controls are useless. They're buried in menus, described in technical language, or set to defaults that maximize data collection. Effective controls are prominent, use plain language, and default to the most restrictive reasonable setting. The GDPR right to erasure is a step in the right direction, but most systems implement it incompletely because deleting from production databases is harder than deleting from the primary table.
The Limits of What You Can Do
None of this solves the fundamental tension. IT systems are designed to collect, process, and scale. Ethics requires restraint, context, and limits. Those goals are in conflict. You can narrow the gap. You can't eliminate it. There will always be situations where doing the right thing costs the company money, loses a customer, or slows down a product launch. The ethical issues in IT aren't bugs to be fixed. They're structural features of how the industry operates. The best you can do is build systems that make the tradeoffs visible and force them into the open where they can actually be debated. I've seen companies treat ethics reviews as roadblocks to work around. I've seen them treat them as genuine constraints that make the product better. The difference isn't philosophy. It's whether leadership is willing to say no when the data says yes. That's the part that can't be automated.