Getting from a Plot to a Formula
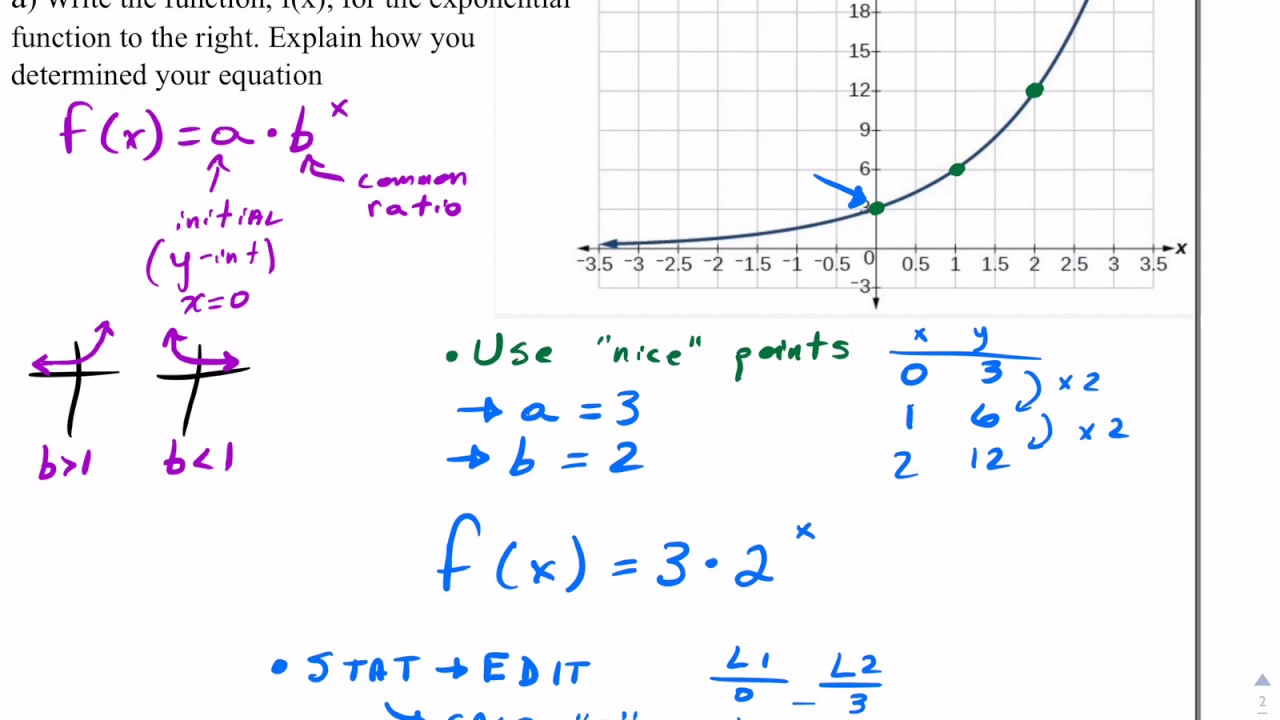
Most people try to eyeball it first. That never works unless the curve is perfectly aligned with your grid and you have a ruler. The actual process starts with recognizing which exponential family you are dealing with, then isolating the constants using two clean data points or the intercept and one other coordinate. An exponential relationship has the form f(x) = a * b^x where a is the initial value at x = 0 and b is the growth or decay factor. When b > 1 you have growth. When 0 < b
1 you have decay. Sometimes the base is e and the equation appears as a * e^(kx), which is mathematically identical with k = ln(b).
Exponential Graph To Equation Conversion Steps
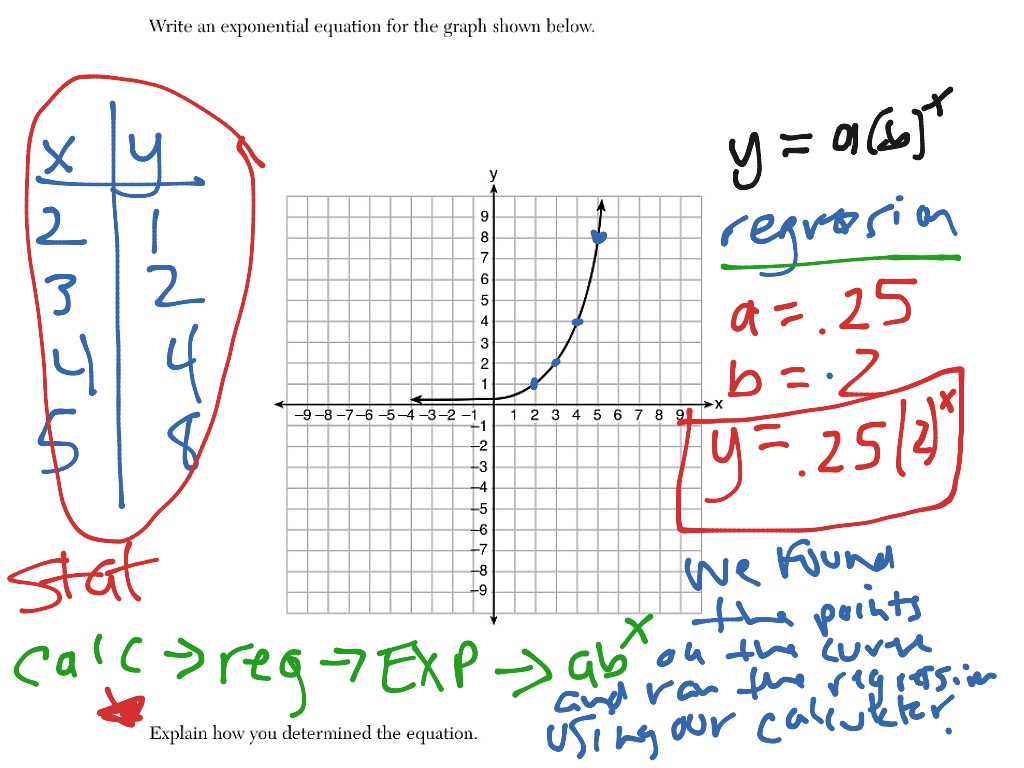
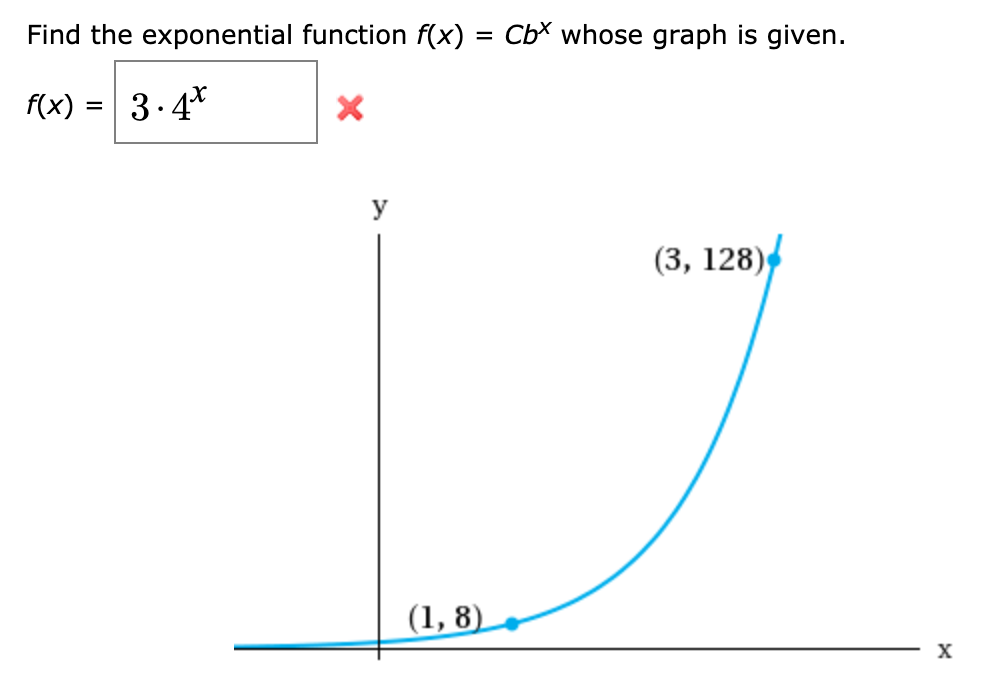
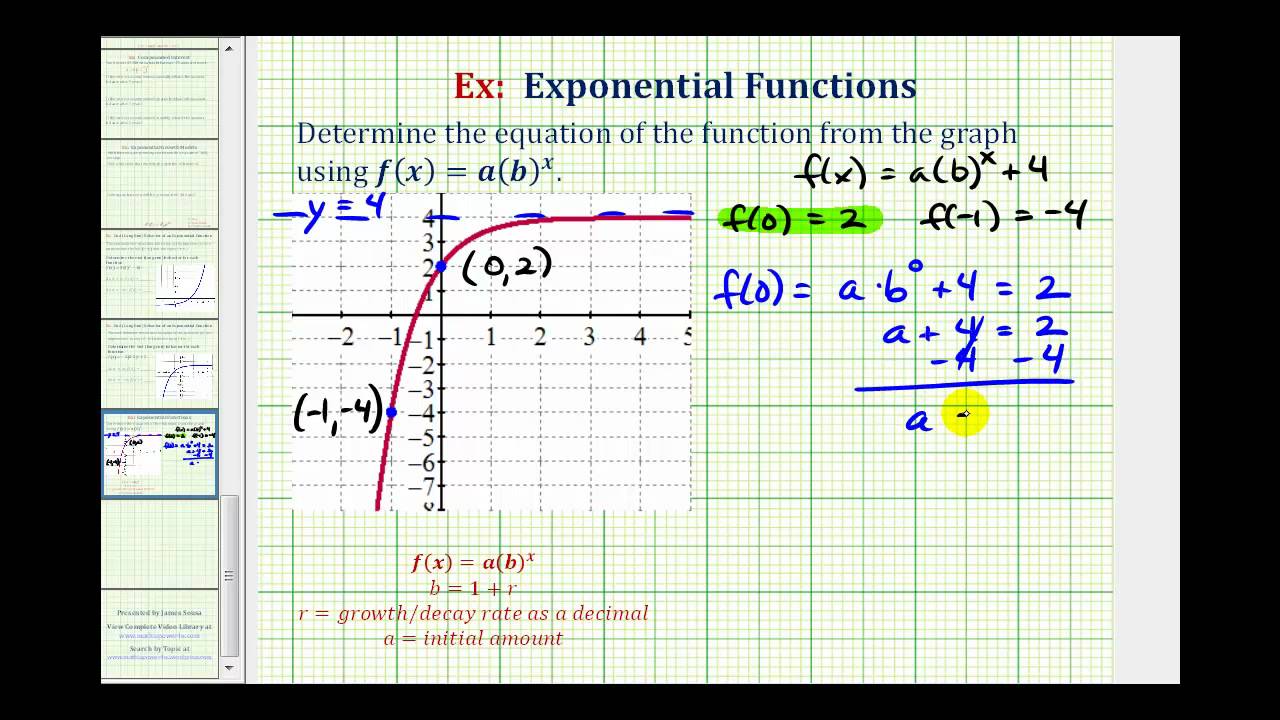
Here is the straightforward method I use in practice when I need to reverse-engineer a formula from plotted data. Step one: identify the y-intercept. If the graph crosses the y-axis at a specific point, that value is your constant a. Read it directly. If the curve does not cross at x = 0, you will need to work with the general form and solve for both constants simultaneously. Step two: pick a second point. Choose a coordinate where the grid lines make the values readable. Avoid points that fall between minor divisions. Write down the x and y values clearly.
Step three: substitute and solve. Plug both the intercept value and the second point into the equation. You get y = a * b^x, which rearranges to b^x = y/a. Take the x-th root of both sides, or use logarithms if the algebra feels messy. The result is b = (y/a)^(1/x). Step four: verify with a third point. This is the part beginners skip. Check another coordinate on the graph against your derived equation. If it does not match within acceptable tolerance, you either misread a point or the relationship is not purely exponential. Logarithmic scales can hide curvature that looks linear at a glance. I once spent two hours trying to force a dataset into an exponential model because the graph looked clean on paper. The residuals told a different story. The data was actually polynomial growth masquerading as exponential over a narrow range. Switching to a log-scale plot revealed the true curvature. Always validate before you commit to the formula.
Get the Full Details
When the Graph Is Already on Log Paper
If your data is plotted on semi-log graph paper, the exponential relationship becomes a straight line. The slope of that line is proportional to ln(b), and the intercept gives you a directly. This is why engineers and scientists prefer semi-log plots for exponential data. On regular Cartesian graph paper, exponential curves can look deceptively linear over short intervals. A curve that grows from 10 to 100 over five units might pass for linear if you do not extend the domain. The visual check alone is insufficient. You need mathematical verification. Another counter-intuitive point: exponential decay curves that approach zero asymptotically often get mistaken for rational functions or inverse relationships. The difference shows up when you take logarithms. If ln(y) versus x produces a straight line, the original relationship is exponential. If 1/y versus x is linear, you are dealing with a reciprocal relationship.
Common Pitfalls and Edge Cases
The most frequent error is assuming every J-shaped curve is exponential. Population growth, compound interest, and radioactive decay follow exponential laws, but so does the charging curve of a capacitor in an RC circuit, which is actually 1 - e^(-t/RC), not a pure exponential. The graph rises quickly then plateaus, which looks exponential to an untrained eye but is fundamentally different. Negative bases create complex outputs that do not appear on real-valued graphs. If your data comes from a physical measurement, b must be positive. Fractional bases are fine, but negative or zero bases indicate a different model entirely. When the y-intercept is not visible on the graph, you cannot read a directly. In that case, select two arbitrary points and set up a system of equations. Solve for both a and b simultaneously. The algebra is straightforward but error-prone if you rush.
Sometimes the data contains noise that makes any single formula inadequate. In those situations, least squares regression on the logarithm of the dependent variable gives a better fit than picking two points by hand. Most spreadsheet software can perform this calculation in seconds.
Software and Tools
Python with numpy and matplotlib handles this cleanly. The np.polyfit function on log-transformed data gives you the slope and intercept of the best-fit line on semi-log paper, which translates directly to b and a. R users can achieve the same result with lm(log(y) ~ x). Excel has built-in trendline options that export the equation automatically, though the precision depends on your sample size and data quality. For quick hand calculations, a graphing calculator in regression mode works adequately. Just remember that the displayed equation is only as good as the underlying data distribution.
Practical Example
Consider a culture of bacteria that starts at 500 cells and reaches 8,000 cells after 4 hours. The initial value a is 500. The point (4, 8000) gives 8000 = 500 * b^4. Dividing yields b^4 = 16. Taking the fourth root gives b = 2. The equation is f(t) = 500 * 2^t, where t is time in hours. Checking with t = 2: f(2) = 500 * 4 = 2000. If the observed value at 2 hours is close to 2000, the model holds. Large deviations suggest environmental constraints or measurement error. The same approach works for decay. Radioactive half-life problems use b = 0.5 per half-life period. The equation becomes N(t) = N0 * 0.5^(t/t_half), which is equivalent to N0 * e^(-kt) with k = ln(2)/t_half.
Limitations
Exponential models fail when resources become limiting, when feedback loops exist, or when the system transitions between regimes. Bacterial growth eventually plateaus due to nutrient depletion. Compound interest ignores inflation and taxes. None of these invalidate the mathematical form, but they limit the domain where the equation remains accurate. Always state the valid range when presenting an exponential equation derived from a graph. An equation that fits data from x = 0 to x = 5 may be useless outside that interval. Extrapolation beyond measured data is where exponential models most commonly mislead. If your graph shows oscillation, saturation, or inflection points, consider alternative models such as logistic growth, power functions, or piecewise definitions. Forcing an exponential fit onto non-exponential data produces equations that look plausible numerically but fail predictive tests.