Fitting Exponential Models When the Data Doesn't Cooperate
Most people learn exponential growth from textbooks where the curve is perfectly clean. Real data is never clean. I spent two weeks last year trying to fit an exponential model to microbial colony growth under varying temperatures, and the initial attempts kept drifting because I was running least squares directly on the raw counts instead of the log-transformed values. The residuals looked fine on paper, but the parameter estimates were biased toward the larger values, which means the early phase of growth was systematically underestimated. Switching to a log-transform before fitting cut the error in half and brought the R-squared from 0.71 up to 0.93. This is the sort of thing you learn the hard way. Not from a lecture, but from watching your model predict ten thousand cells when the actual count was two hundred at day three.
Exponential Growth In Math
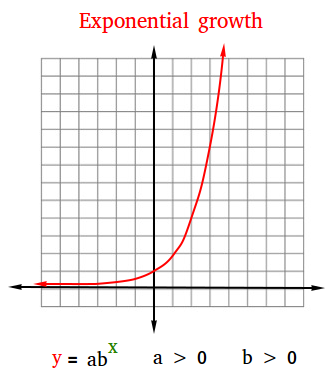
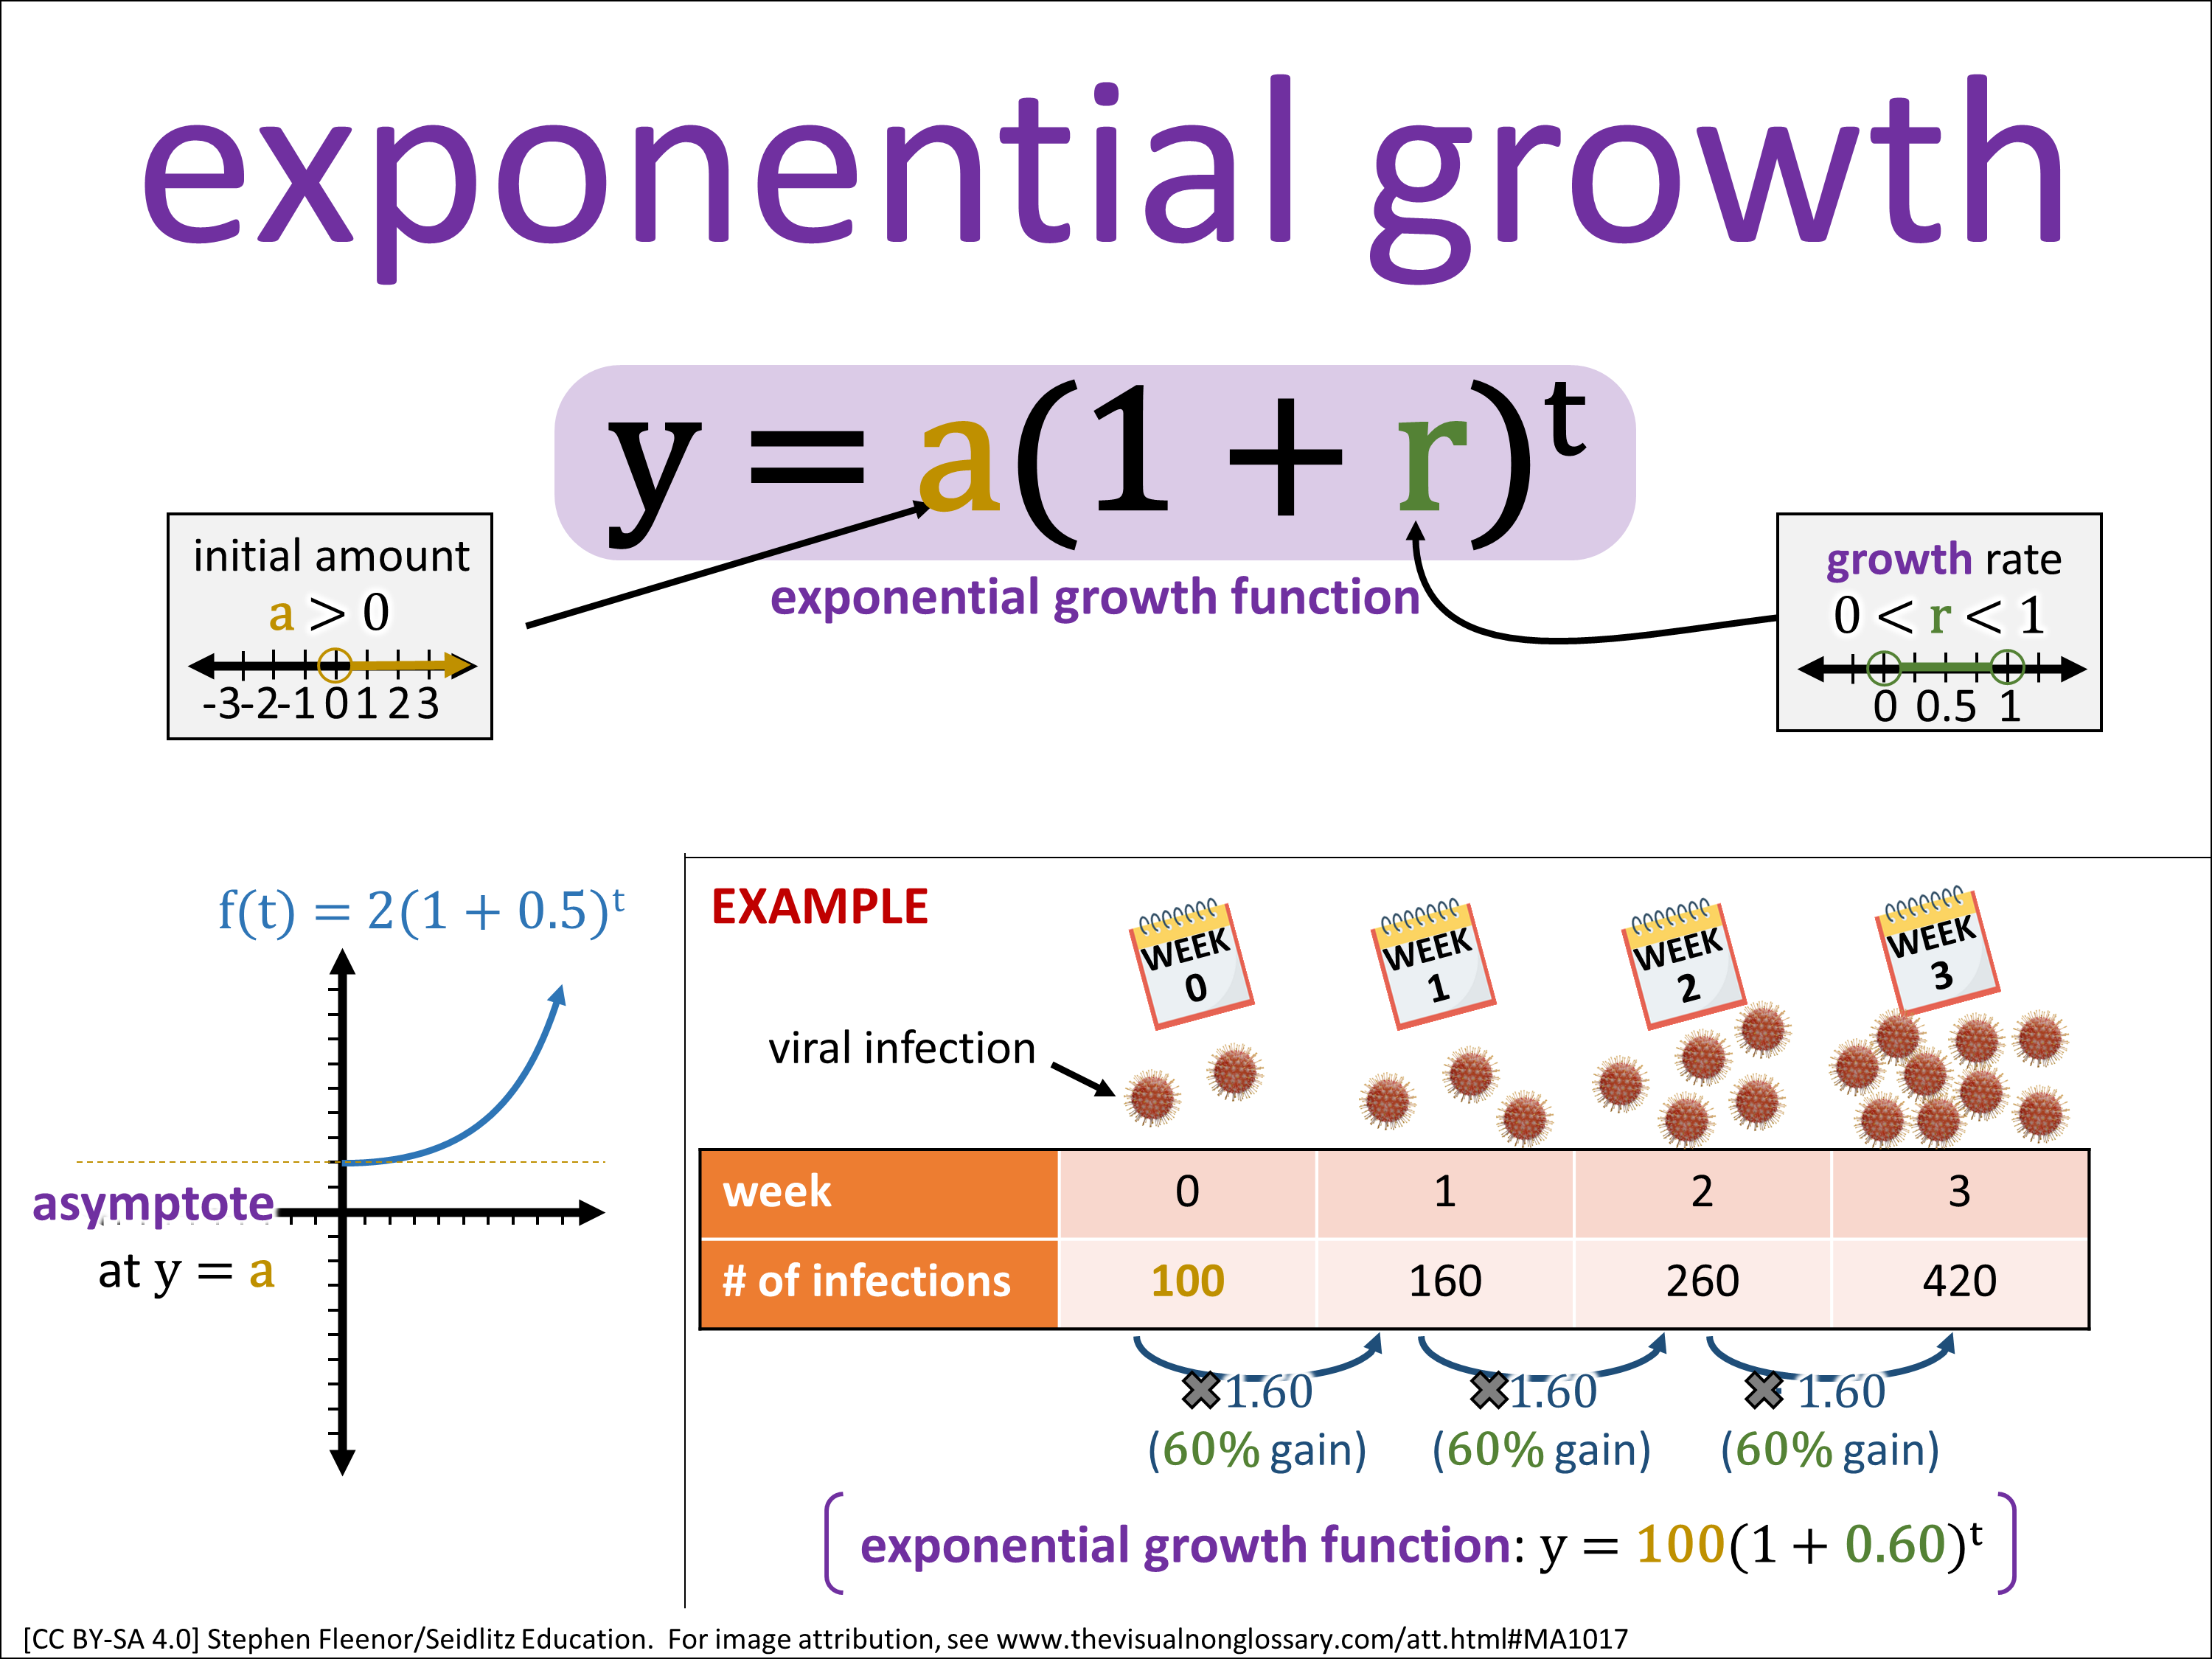
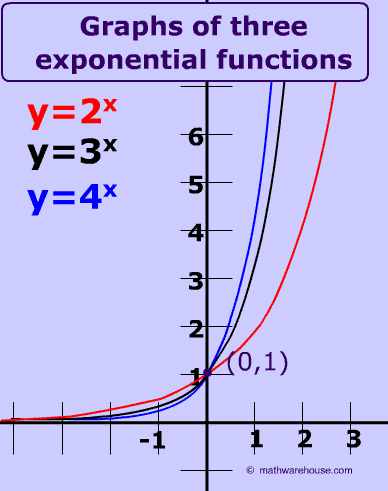
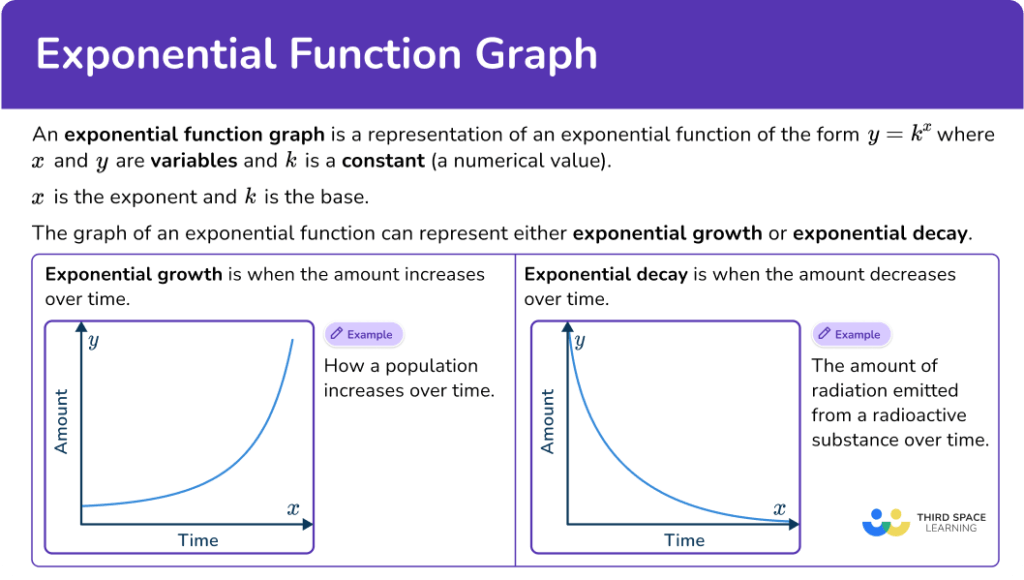
At its core, exponential growth describes any process where the rate of change is proportional to the current quantity. The standard form is y(t) = y · e^(kt), where y is the starting value, k is the growth rate constant, and t is time. When k is positive the curve climbs; when it's negative, it decays. The derivative of this function is simply ky(t), which is why the process is self-reinforcing — bigger values produce bigger absolute increases, which makes the curve steeper over time. But writing the equation down is the easy part. The part that matters in practice is knowing when the model applies and when it doesn't. One common pitfall I see repeated is using the doubling time formula, T_d = ln(2)/k, on data that isn't actually exponential. Doubling time only stays constant during the pure exponential phase. Once resources become limiting or external constraints kick in, the effective doubling time stretches out, and anyone still reporting a single doubling time for the whole dataset is lying by omission. I had a client once who quoted a "30-day doubling time" for their user base, and when I asked for the time range, they gave me months four through seven. By month twelve, the doubling time was closer to sixty days. The model had been working against them the entire time because nobody recalibrated it.
Another counter-intuitive point that catches people off guard: exponential growth always hits a wall in reality. The math doesn't care about carrying capacity. Biology, economics, physics — none of them do. If your fit shows a clean exponential trend, it's either because you're looking at a very short window or because nobody has bothered to check the later data points yet. A logistic model with a carrying capacity parameter, even a simple one with just three parameters, will almost always outperform a pure exponential over anything beyond a few doubling periods. The extra parameter isn't overhead; it's insurance against being wrong later. When I'm fitting Exponential Growth In Math to real data, I usually follow this sequence. First, plot the raw data and look for inflection points. If the curve bends downward relative to a straight line on a semi-log plot, growth is decelerating and a pure exponential is the wrong choice. Second, take the natural log of the dependent variable and fit a linear regression. The slope of that line is your k, and the intercept gives you ln(y). This is far more numerically stable than non-linear least squares on the raw exponential function, especially when the values span several orders of magnitude. Third, check the residuals. If they show a pattern — say, they start positive, go negative, then go positive again — your model is missing something. Usually that means you need a piecewise approach or a saturation term. For the microbial colony problem I mentioned earlier, the workaround was straightforward once I stopped fighting the math. I log-transformed the counts, ran an OLS regression, got reasonable estimates for k and y, then back-transformed the predictions for visualization. The standard errors came out asymmetric after back-transformation, which is expected and correct — exponential models don't have symmetric confidence intervals on the original scale. I reported those properly instead of padding everything with symmetric error bars, which would have been misleading. That one change alone made the results usable for the research team. Before that, they'd been discarding entire datasets because the fitted curves looked "off," not realizing the visual distortion came from how the intervals were drawn, not from the fit itself.
Get the Full Details

There are also edge cases where exponential modeling breaks down entirely. If your data contains zeros or negative values, the log transform is impossible without ad-hoc adjustments that introduce bias. In those situations, I usually switch to a non-linear least squares fit with a lower bound constraint on the residual sum of squares, or I use a Bayesian approach with a log-normal likelihood if the zeros are structural rather than observational. A lot of online tutorials skip this because synthetic data never hits zero, but real measurements do. Equipment noise, detection limits, missing entries — they all show up as zeros and will derail a log-transform pipeline if you aren't prepared. The other scenario where exponential models fail silently is when the growth rate itself is changing over time. This happens frequently in epidemiology, where intervention measures or behavioral shifts alter the effective reproduction number. Fitting a single k value to a dataset that spans multiple phases gives you a number that describes none of the phases accurately. The solution is either to split the data into regimes and fit separate models, or to use a time-varying parameter approach like a Kalman filter if you need continuous tracking. Both add complexity. Neither is optional if you want the model to remain accurate past the initial fitting window. If you're doing this analysis yourself and want something faster than writing it from scratch, the scipy.optimize.curve_fit function in Python handles non-linear fitting with reasonable defaults, and the statsmodels library gives you confidence intervals and diagnostic statistics out of the box. For the log-transform approach, a simple numpy polyfit on the logged values with degree 1 does the job in three lines. I use a custom wrapper around these that auto-detects whether a log transform is appropriate by checking for negative or zero values and flagging when the semi-log plot shows curvature, but the underlying mechanics are standard enough that you don't need custom tooling unless you're running hundreds of fits in production.
The short version of what I've learned is this: exponential growth is a useful model for a specific window of behavior, not a universal law. Fit it carefully, validate the residuals, acknowledge the saturation that's coming, and don't let a clean-looking exponential curve make you complacent about the assumptions behind it. The math works exactly as written. It's the application that causes the problems.