
Geospatial Data Analysis Is More Painful Than Most Tutorials Admit
You load your shapefile into QGIS, hit the buffer tool, and six hours later the process hasn't finished because your CRS is wrong, your coordinate system is reprojecting on the fly in the background, and your buffer radius is in degrees instead of meters. This happens every single day. It's the default experience, not the exception. I've been doing this work for over a decade, and I still get tripped up by projection issues on a weekly basis. The field has gotten better with tools like QGIS and ArcGIS Pro, but the fundamentals haven't changed. If you skip the setup properly, nothing downstream will work right.
Setting Up For Geospatial Data Analysis Without Losing Your Mind
Start by understanding what your data actually is before you touch a single tool. I once had a client send me a CSV with lat/lon coordinates that they claimed was in WGS84. It was. But the longitude values were formatted as negative numbers in one column and the absolute value in another, and the whole dataset was shifted about forty kilometers east because the source had used a local datum without documenting it. Took me three days to figure out where the offset was coming from. The first thing you need to do is identify your coordinate reference system. Not guess. Actually identify it. Check the metadata. If there's no metadata, run a quick check in your GIS software to see what projection it defaults to. Most modern tools will show you the EPSG code if you know where to look. In QGIS, right-click the layer, go to Properties, and under the Information tab you'll see the CRS. In ArcGIS, it's in the Source tab of the layer properties. If your data doesn't have a CRS assigned, don't just assume WGS84 and move on. That assumption will cost you. I've seen projects where the final output was completely unusable because someone assumed the data was in a projected coordinate system when it was actually geographic. The distances were off by a factor of roughly 111,000 meters per degree. That kind of error makes any spatial analysis meaningless.
The Tools You Actually Need
QGIS is free and covers most use cases. ArcGIS Pro is better if you have a budget and need enterprise-grade geoprocessing. For programmatic work, Python with GeoPandas and R with sf are the standard choices. gdal is your backend engine regardless of which interface you're using. I prefer Python because it gives me more control over what happens at each step. The learning curve is steeper than drag-and-drop GIS interfaces, but once you can write a script that handles reprojection, buffering, and spatial joins in one pipeline, you'll never want to go back to clicking buttons in a GUI. A typical spatial join that takes twenty minutes in QGIS might take forty seconds in a Python script after you've written it. Here's a concrete example that matters in practice. You have a point dataset of well locations and a polygon dataset of municipal boundaries. You need to assign each well to its municipality and calculate the average depth per municipality. The naive approach is to do a spatial join and then group by municipality. That works. But what if some wells fall exactly on boundary lines? What if the municipal boundaries have gaps or overlaps due to different survey dates?
Get the Full Details
In my experience, the spatial join will arbitrarily assign wells on boundaries to one municipality or another, and if there are topology errors in the polygon data, you'll get results that don't match reality. The workaround is to create a small buffer around the points, dissolve any overlapping buffers, and then rejoin. It sounds like overkill but it prevents the kind of errors that show up in final reports and make you look careless.
Common Pitfalls That Nobody Warns You About
Topology errors are the biggest time sink. Every real-world dataset has them. Lines that don't quite meet, polygons with gaps, self-intersecting rings. When you try to perform operations like union or intersection, the tools will either fail silently or produce garbage output. The fix isn't to just run the tool again. You need to explicitly validate topology first. QGIS has a built-in topology checker. In Python, you can use shapely's is_valid and MakeValid methods. Always check your geometries before you trust the results of any spatial operation. Another issue that people consistently miss is date handling. Many geospatial datasets include temporal attributes, and most GIS software treats dates as text strings rather than actual datetime objects. This means sorting by date won't work correctly if the format isn't consistent, and time-based spatial analysis becomes impossible without cleaning first. I spent an entire week fixing date parsing issues in a wildfire incident dataset where some entries used MM/DD/YYYY and others used YYYY-MM-DD. The software treated them all as strings and sorted them alphabetically, which completely messed up the temporal analysis. Performance is a third concern that gets glossed over in tutorials. Spatial operations scale poorly with data size. A spatial join on two datasets with a million features each will take significantly longer than a join on two datasets with ten thousand features. The difference isn't linear. I've seen joins that took hours on large datasets get down to minutes after filtering to the area of interest first. Always clip your data to the study area before running heavy geoprocessing operations. It's the single most effective optimization available.
When Standard Tools Fail You
Sometimes the tools you'd normally reach for simply cannot handle the problem. A few years ago I worked on a project involving aerial imagery analysis where I needed to classify land cover across a area spanning multiple UTM zones. The standard approach would be to reproject everything into a single projected coordinate system, but the distortion across such a large area would introduce significant accuracy loss in the classification boundaries. The solution was to process each UTM zone separately and then merge the results. I wrote a Python script that iterated through the zones, ran the classification in each one using the appropriate CRS, and then combined the outputs at the boundaries with a blending buffer to smooth the seams. It added maybe thirty minutes of setup time but saved what would have been hours of manual cleanup and the kind of positional inaccuracy that would have made the final product unusable for the client's purposes. There are also cases where the spatial operation you want doesn't exist in your tool of choice. PostGIS has capabilities that neither QGIS nor ArcGIS expose directly. If you're doing repeated analyses or working with very large datasets, learning basic SQL with PostGIS can be worth the effort. The initial investment is real but the payoff comes quickly once you need to run the same operation more than twice.
A Practical Workflow That Actually Works
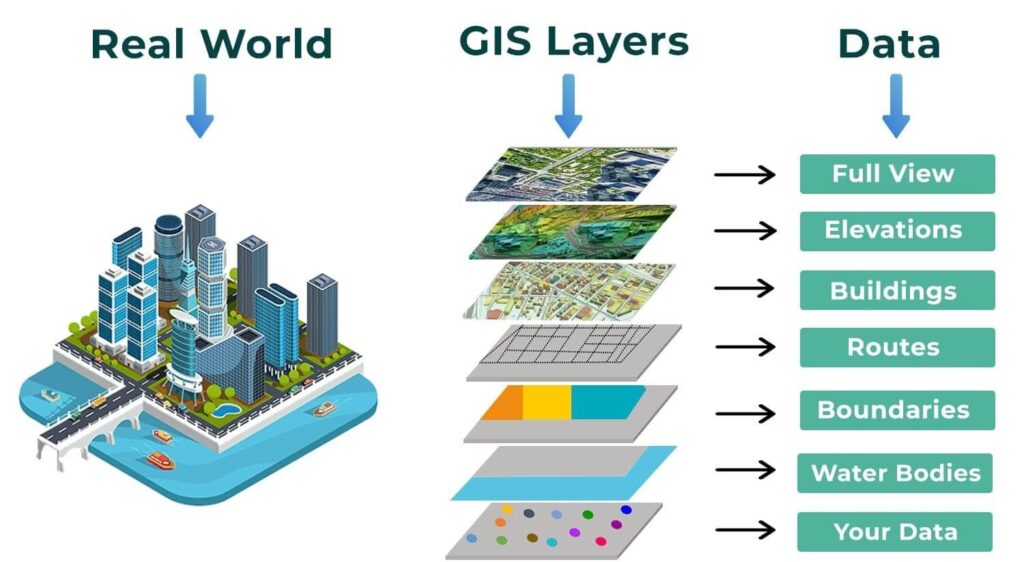
Here's the workflow I use now, and it's different from what I used to do because I learned through making mistakes. First, I get all my data in one place and identify the CRS for each layer. I verify that they're compatible. If not, I reproject them before doing anything else. This is non-negotiable. I've skipped this step too many times and paid for it later. Second, I validate topology on all vector data. I check for invalid geometries, overlaps where there shouldn't be any, and gaps. I fix what I can and document what I can't. The documentation matters because when someone later asks why a certain area wasn't included in the analysis, I need to be able to explain what happened. Third, I clip everything to the study area. This reduces data volume and improves performance for all subsequent operations. Fourth, I run the analysis. Fifth, I validate the results. I check the counts, I visualize the output, I compare against known values if available. I don't skip the validation step because it's easy to trust the tool and forget that garbage in means garbage out.
The entire process for a medium-complexity project typically takes me about two to three hours from raw data to validated output. That includes the time spent dealing with unexpected issues like the ones I described above. A beginner might take eight to twelve hours for the same project, and some of that time difference is just experience. The rest is knowing which steps to double-check and which steps you can safely skip. Geospatial data analysis isn't hard because the concepts are complicated. It's hard because the edge cases are everywhere and the tools don't always tell you when something has gone wrong. The best analysts I know aren't the ones who know the most functions. They're the ones who know where the failures hide.


