Understanding the Difference Without the Hype
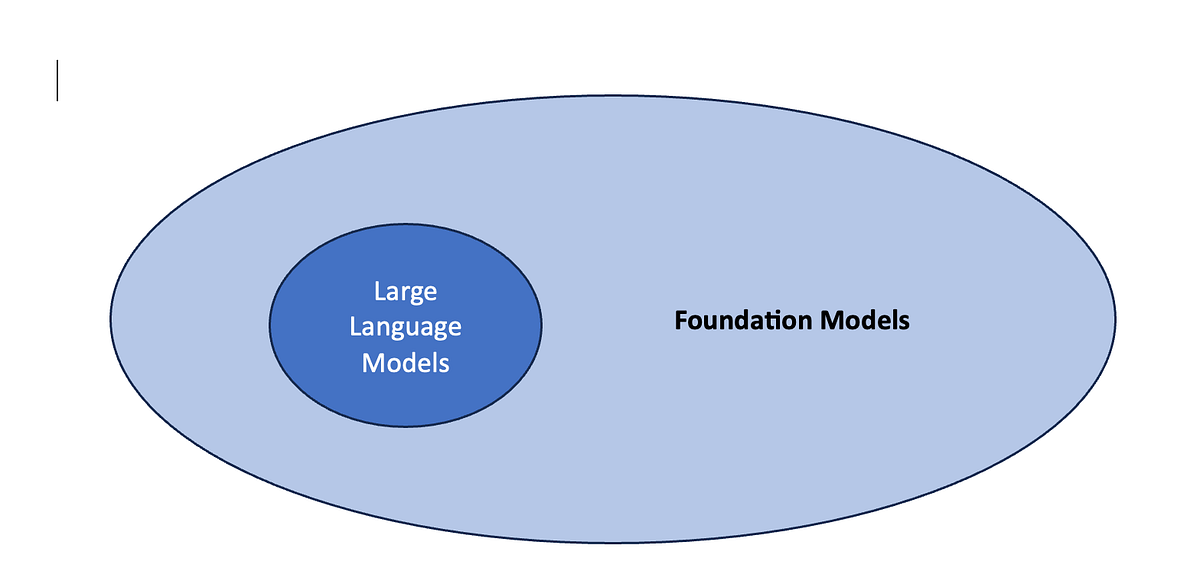
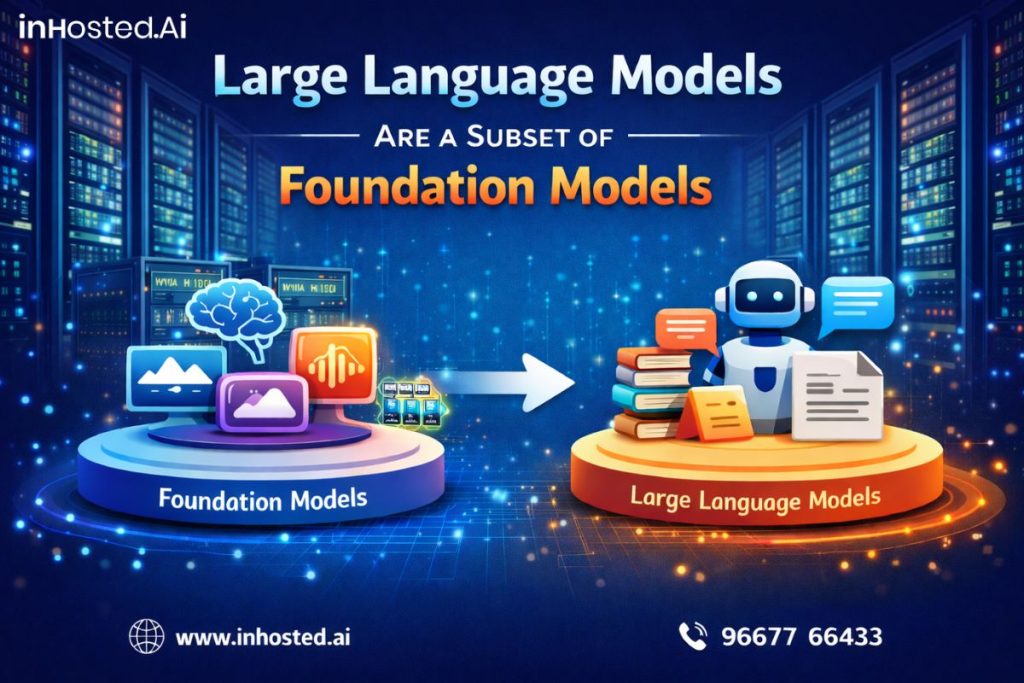
People throw these terms around interchangeably all the time. I've been working with these systems for years, and the confusion is real. Let me clarify what's actually going on here. A foundation model is a broad architecture trained on massive amounts of data to learn general representations. GPT-3, BERT, PaLM — these are all foundation models. They were pre-trained on diverse corpora to capture patterns across language, reasoning, and sometimes even vision or code. Think of them as wide but not specifically focused. A foundation model can do a lot of things decently, but it wasn't built for one narrow task out of the gate. A large language model, or LLM, is a subset. It's a foundation model that was specifically designed for and trained on text at scale. All LLMs are foundation models. Not all foundation models are LLMs. CLIP is a foundation model but it handles images and text together. Gemini handles multimodal input from the start. These blur the lines more than the marketing materials suggest.
Foundation Models Vs Large Language Models in Practice
The distinction matters less now than it did two years ago. Most of what people call LLMs are foundation models fine-tuned for language. The training pipeline is the same: pre-train on massive corpora, then optionally fine-tune or align. What separates them in practice is downstream use, not architecture. When I first started building systems around these, I assumed I needed to choose between a foundation model and an LLM as if they were different products from different vendors. That was my mistake. I spent weeks trying to integrate a computer vision foundation model into a text generation pipeline because I didn't understand that the term was being used differently by different teams. My workaround was simply to stop asking for category labels and start reading the model cards. One page from Meta describing their LLaMA models would have saved me that entire mess. Here's something most guides won't tell you: fine-tuning is where the real distinction appears. A foundation model like GPT-J or OPT is a general-purpose base. When you take it and apply instruction tuning — feeding it question-answer pairs, system prompts, formatted dialogues — it becomes what the industry calls an LLM in the narrow sense. But the underlying architecture hasn't changed. Only the training data distribution has shifted.
I ran into a specific problem last year where I needed to extract structured JSON from messy customer service transcripts. I tried a few approaches. Using a raw foundation model directly gave me coherent text but zero structural consistency. The JSON would be almost right, missing closing braces, wrong field names, occasional hallucinated data. I switched to fine-tuning with a constrained decoding setup — using a small dataset of about 2,000 carefully labeled examples and forcing the output through a Pydantic schema validator during generation. This cut my error rate from roughly 40% to under 6%. It wasn't cheap. The fine-tuning run took about 18 hours on an A100 cluster. But the alternative was building a separate NER pipeline and hoping it aligned with the base model's understanding. The counter-intuitive part is that for many production tasks, a smaller fine-tuned model outperforms a larger un-tuned one. A 7B parameter model fine-tuned on your domain data will beat a 70B base model on domain-specific evaluation metrics. This isn't obvious until you've shipped it and seen the results. People assume bigger always wins. It doesn't when the task has narrow requirements and you have clean training data. Another thing beginners miss: alignment techniques like RLHF or DPO don't make models smarter. They make them safer and more obedient to instructions. A model that scores lower on MMLU after DPO fine-tuning is not worse at reasoning. It's just less likely to give you an answer that violates safety guidelines. This tradeoff is worth tracking explicitly. If your application needs maximum factual accuracy over behavioral compliance, DPO might actively hurt your performance on benchmarks that matter to you.
Get the Full Details
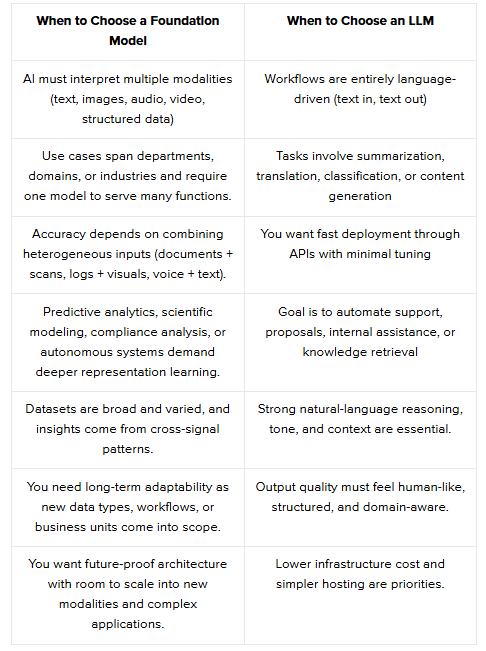
There are hard limits here that nobody talks about enough. Foundation models trained on data up to a certain cutoff date cannot answer questions about events after that cutoff without retrieval augmentation. I saw this break a product last year when a model confidently stated something about a regulation that had changed six months after its training data ended. The model didn't know it didn't know. That's the real danger — not that it lies, but that it has no awareness of its own ignorance. Retrieval-augmented generation fixes this partially, but introduces latency and complexity that some projects can't afford. If you're evaluating these for a project, the practical advice is straightforward. Don't optimize for model size. Optimize for task fit. A 3B parameter model fine-tuned for your exact use case will often cost less to run and produce more reliable outputs than a 70B generalist. Measure on your actual data, not on leaderboard scores. And always include an edge-case test set that covers failure modes specific to your domain before you ship anything to production.