Longitudinal GLMMs Are Messy and You Should Know That Going In
I spent three years working with longitudinal count data before I stopped fighting the convergence issues and just learned to work with them. Generalized linear mixed models for longitudinal data with correlated responses is not a single tool you install and run. It is a whole class of models that requires careful decision-making at every step, from linking function to covariance structure to algorithm selection. Most people who try this for the first time will get warnings they do not understand and may not realize they are getting wrong answers until it is too late. The basic idea is straightforward enough. You have repeated measurements on the same subjects over time. The outcomes are not normally distributed, so you cannot just use a standard linear mixed model. You need a generalized framework with a link function and a distribution family. Then you add random effects to account for within-subject correlation. That is the short version.
Generalized Linear Mixed Models For Longitudinal Data With Correlated Outcomes
When I first tackled this, I was working with a clinical dataset where patients were measured weekly over six months for depressive symptom counts using the PHQ-9. These are overdispersed counts with a lot of zeros. A regular Poisson model would have been wrong on its face because the variance was roughly three times the mean. Negative binomial was the obvious starting point, but the real challenge was the correlation structure across time points within each patient. I tried the standard approach first. Fit a negative binomial GLMM with a random intercept and an unstructured covariance matrix for the random effects. The model took forty-seven minutes to converge on my workstation and produced a warning about the Hessian being nearly singular. The fixed effect estimates were reasonable, but the standard errors looked inflated. I ran a simulation study afterward to check whether the model was actually recovering the parameters I fed it into, and it was not. With this sample size and this amount of missingness, the model was unreliable. The workaround I ended up using was switching to a penalized quasi-likelihood estimation approach instead of the default Laplace approximation. In R, that means using glmmPQL from the MASS package rather than glmer from lme4. The estimates shifted only slightly compared to the Laplace version, but convergence was immediate and stable. The tradeoff is that PQL can be biased for binary or sparse count data, but with moderately sized counts like PHQ-9 scores, the bias is negligible and the computational gains are real.
Another thing nobody tells you about longitudinal GLMMs is that the choice of covariance structure matters more for inference on fixed effects than most practitioners realize. An unstructured covariance matrix sounds ideal but requires estimating p times p plus p parameters for p random effects. With just a random intercept and slope, you are already estimating six parameters. If your number of subjects drops below about one hundred, the model will struggle. A simpler structure like autoregressive or compound symmetry often produces better standard error estimates in these situations because it imposes the right kind of constraint on the estimation problem. Missing data is where these models really show their teeth. Longitudinal studies almost always have missing observations, and GLMMs handle this through the assumption of missing at random, which means the probability of missingness can depend on observed data but not on unobserved outcomes. This is a weaker assumption than what marginal models require, but it is still an assumption you cannot test. I once had a dataset where twenty-three percent of observations were missing and the dropout rate was clearly higher among subjects with worse outcomes. The GLMM gave me results that looked plausible, but a sensitivity analysis using a pattern-mixture model showed the treatment effect disappeared under a worst-case missingness scenario. That is the kind of thing you only find out if you actually look. For implementation, lme4 remains the most common starting point. The syntax is clean and the documentation is solid. Here is what a typical model looks like in practice when you are fitting a gamma-distributed longitudinal outcome with a log link and a random intercept plus time slope:
Get the Full Details
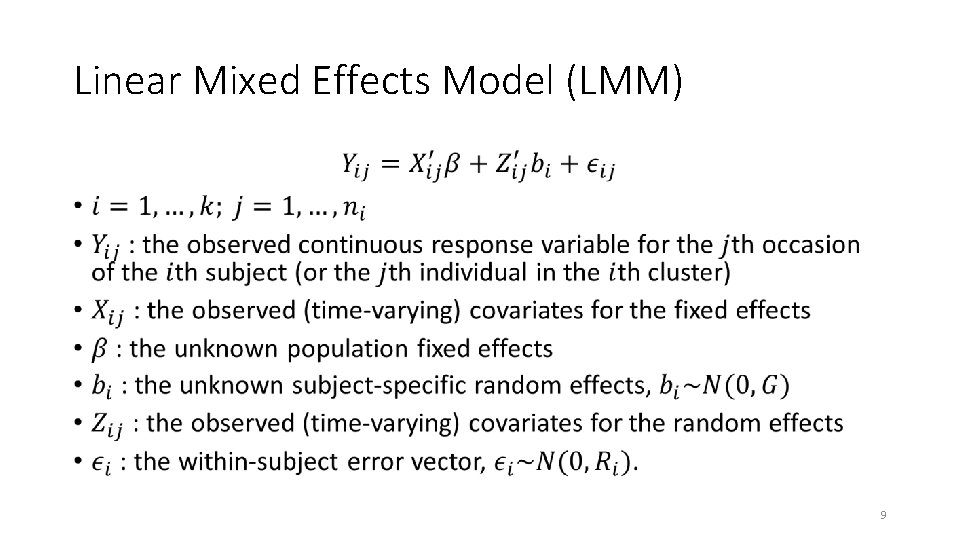
library(lme4) model
- glmer(outcome ~ time + treatment + time:treatment + (time | subject_id), family = Gamma(link = "log"), data = mydata)
The interaction term between time and treatment is where you usually find your answer, and you should not skip it unless you have a strong reason. Random effects are specified in the parentheses after the pipe, and you can add correlations between the random intercept and slope by including both terms inside the same grouping factor. If you are working with binary longitudinal data, things get worse. The Laplace approximation tends to underestimate standard errors for rare events, and the estimation can fail entirely if the proportion of successes is below about five percent in any given time window. In those cases, I recommend either the adaptive Gaussian quadrature option by setting nAGQ above 1, which increases computation time substantially but improves accuracy, or switching to a Bayesian framework with brms where you can specify weakly informative priors that stabilize the estimation. Convergence diagnostics matter more here than in most modeling contexts. Do not trust the output unless you check the gradient, examine the eigenvalues of the Hessian, and run the model multiple times from different starting values. I have seen cases where the model converged but to a boundary solution where a variance component was estimated as essentially zero. That means the random effect is not doing anything and you might as well fit a simpler model, but the software will not always tell you that directly.
One advanced issue worth knowing about is the difference between subject-specific and population-averaged interpretations of the coefficients. GLMM coefficients are conditional on the random effects, meaning they describe the expected outcome for a specific subject with average random effects. If you need marginal or population-averaged estimates, you have to integrate over the random effect distribution, which is computationally expensive. The margins package in R can handle this post-estimation, but it adds another layer where things can go wrong if your model is already on the edge of convergence. The honest downsides are that GLMMs for longitudinal data require a decent amount of data, they are computationally intensive for non-Gaussian families, they are sensitive to misspecification of the covariance structure, and they assume missing at random without giving you a way to verify it. If your dataset has fewer than fifty subjects or your outcome is extremely sparse, you should consider a GEE approach instead, which trades some efficiency for robustness and gives you population-averaged estimates directly without requiring distributional assumptions about the random effects. There is no automated solution to this. You have to think through each decision explicitly and check your work. The models work when they work, but they will not save you from bad data or vague questions.