Understanding Group By in Relational Algebra
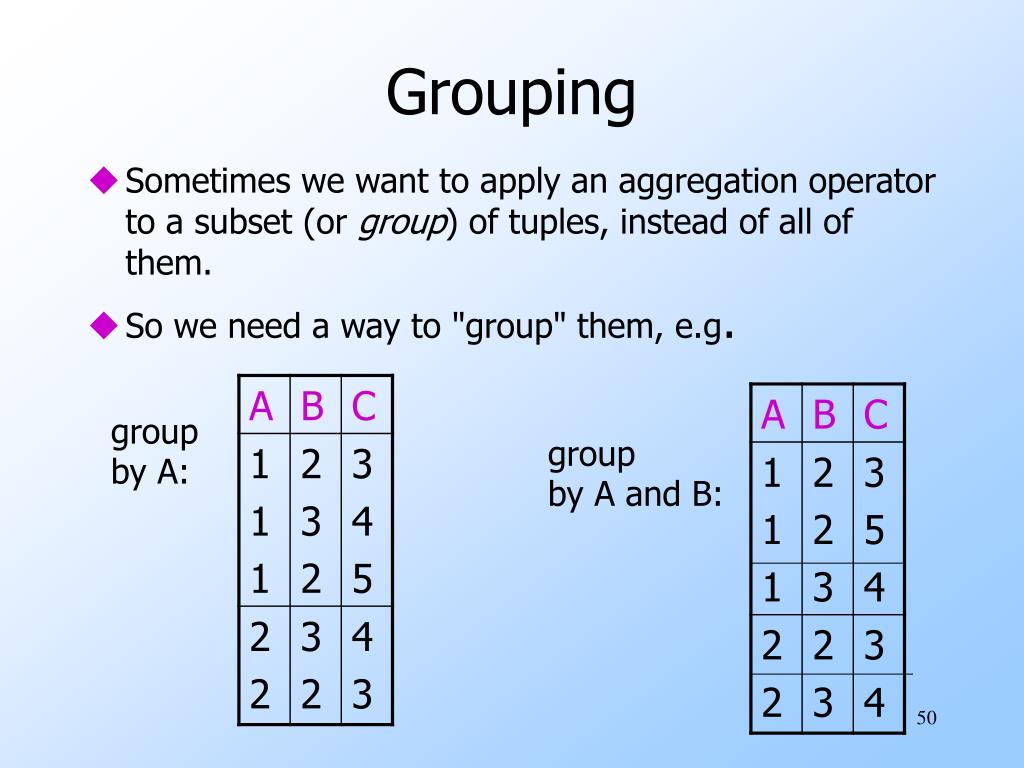
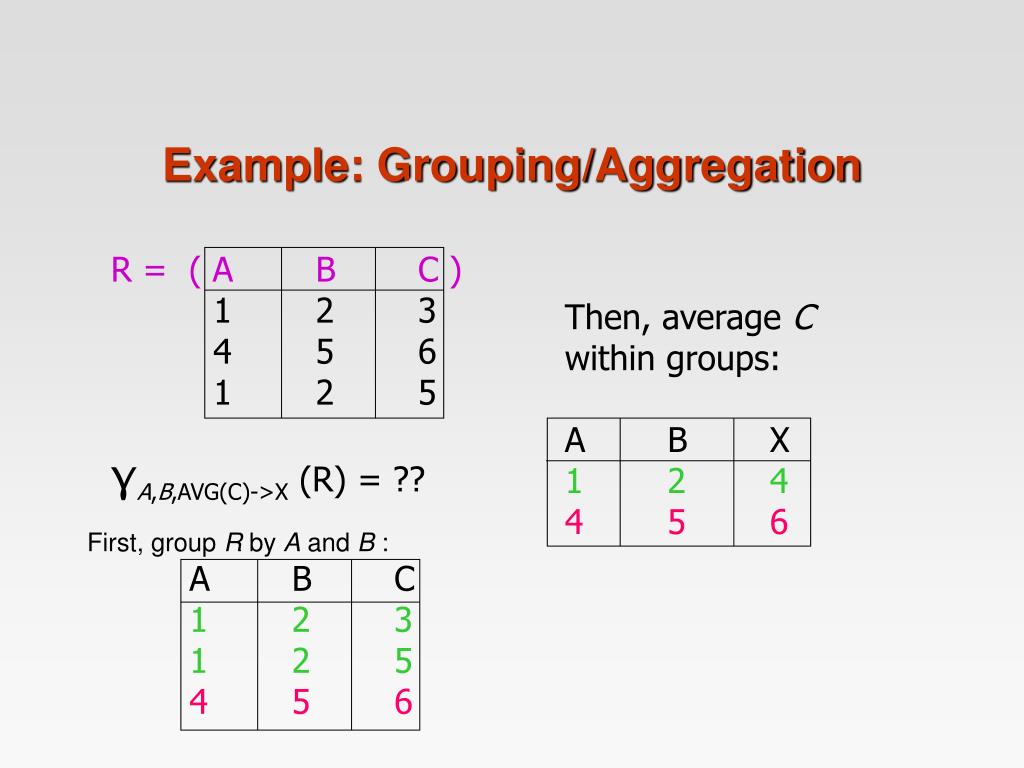
Group by is one of those operations that every database student learns but almost nobody actually understands from the formal side. You memorize the symbol, you pass the exam, and then when you get to writing actual queries or optimizing them, you realize the gap between the textbook notation and what's happening at runtime is enormous. This piece tries to bridge that gap. The Group By relational algebra operation takes a relation and reorganizes its tuples into partitions based on one or more grouping attributes. Each partition contains all tuples that share the same value (or combination of values) across those attributes. Then, for each partition, you apply an aggregate function like SUM, COUNT, MAX, MIN, or AVG to compute a single output value per group. The result is a new relation with fewer rows but different structure.
Group By Relational Algebra
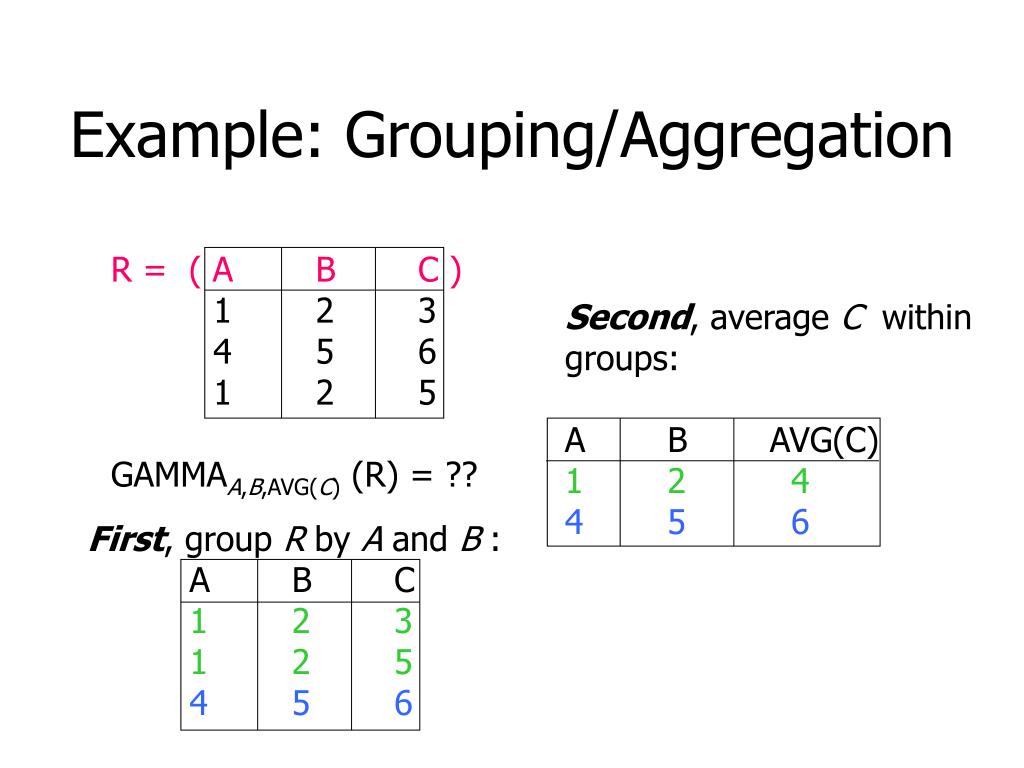
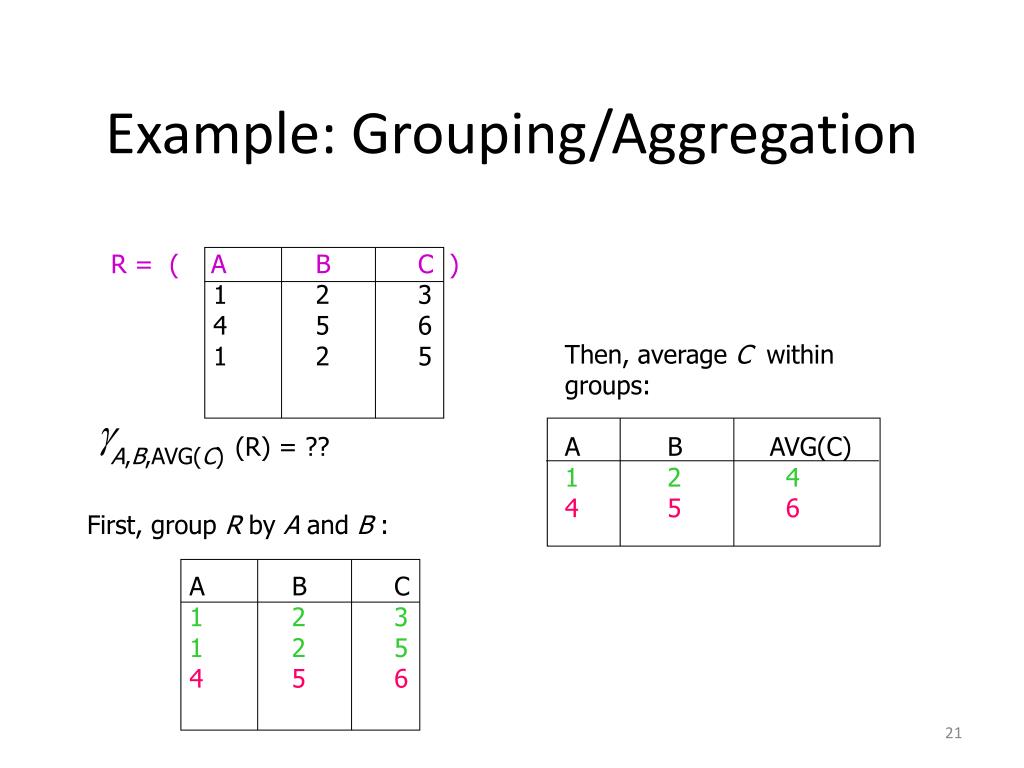
Formally, the operation is written as (gamma) followed by the grouping attributes and the aggregate expressions. If you have a relation Enrollment with attributes (StudentID, CourseID, Grade) and you want the average grade per student, you write: StudentID, AVG(Grade)(Enrollment) This partitions Enrollment by StudentID, then computes the average Grade within each partition. The result has two attributes: StudentID and a derived attribute holding the average. Simple enough on paper. The notation collapses a lot of messy detail, which is both its beauty and its problem.
Here is the practical reality that textbooks skip. When you use GROUP BY in a real query optimizer, the operation is not a single atomic step. It decomposes into a sequence of physically executable operations: a sort or hash partitioning phase, followed by a streaming aggregation pass. The choice between sort-based and hash-based execution depends entirely on your data distribution, available memory, and whether there is an existing index or sorted order you can exploit. I spent three months debugging a report that ran in 4 seconds on one environment and 47 minutes on another. The queries were identical. The difference was that the slower environment had a corrupted statistics profile that caused the optimizer to choose a sort-based grouping strategy on a nearly random dataset instead of a hash partition, and the disk spill from the sort was catastrophic. Fixing the statistics brought it back to 4 seconds. One thing beginners consistently miss is that GROUP BY is not just an SQL convenience. It is a primitive relational algebra operator that exists independently of any particular query language. The original relational model by Codd included aggregation as part of the formal framework. Every modern SQL engine implements it because it maps directly to the algebra. Understanding this helps when you are reading execution plans or trying to reason about query transformations, because the optimizer is essentially translating your SQL GROUP BY into a sequence of algebraic operations and then deciding how to execute them physically. Another counter-intuitive point: the output schema of a GROUP BY operation is not deterministic without explicit naming of aggregate expressions. In the formal algebra, each aggregate produces an unnamed derived attribute, and collisions are possible when you have multiple aggregates on the same input attribute. Different systems handle this differently. Some assign generated names like "AVG(Grade)", others use positional indices. This matters when you are composing multiple GROUP BY operations in a single algebraic expression or when you are writing a query transformer that needs to track attribute provenance through transformations.
Get the Full Details

Let me give you a more complete example with multiple aggregations and a join before grouping. Say you have two relations: Department(DepartmentID, DepartmentName, Location) Employee(EmployeeID, Name, DepartmentID, Salary, HireDate)
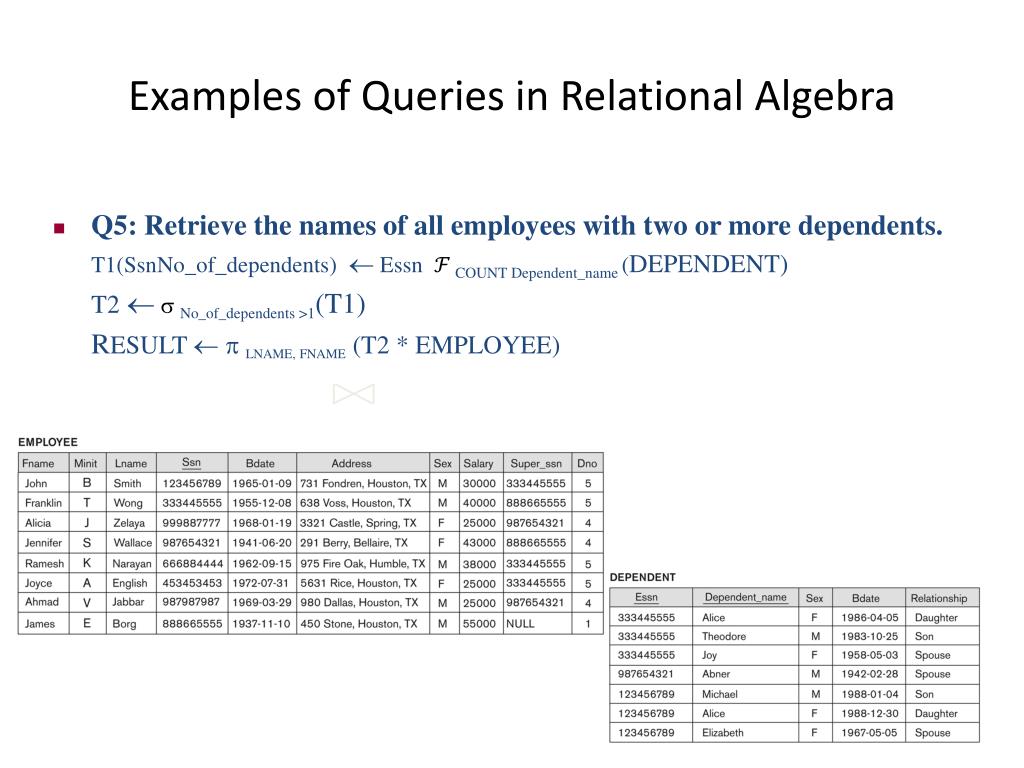
You want the department name, location, total salary budget, average salary, and employee count for departments with more than five employees. In relational algebra: DepartmentID, DepartmentName, Location, SUM(Salary), AVG(Salary), COUNT(EmployeeID)(Department Employee) Then you would apply a selection COUNT(EmployeeID) > 5 to filter the groups. Note that the selection on the aggregated result is technically a secondary operation in the formal model. In SQL this is HAVING, but in pure relational algebra you express it as a composition of the group operation followed by a selection on the grouped relation. This distinction matters for query optimization because the order of operations determines whether you can push the selection down before the grouping, which can dramatically reduce the number of tuples entering the aggregation phase.
In practice, I once encountered a query where a predicate on Employee.HireDate was being applied after the GROUP BY instead of before it, causing the aggregation to process thousands of extra rows that would have been eliminated by the date filter. The fix was rewriting the query so the selection appeared earlier in the logical plan. On a 200-million-row table, this reduced execution time from about 11 minutes to roughly 90 seconds. The algebra tells you the correct semantic result, but the physical execution order is where performance lives or dies. There are also limitations you need to be aware of. Group by does not handle NULLs intuitively in all contexts. A NULL grouping key creates its own partition. If every tuple in a group has NULL for the aggregate attribute, SUM returns NULL, not zero. COUNT on a NULL attribute excludes that tuple entirely, but COUNT(*) counts it. These behaviors are standardized but they trip people up constantly when they write queries assuming SQL semantics will carry over from one database engine to another. Another hard limitation: standard GROUP BY in relational algebra does not support window functions or analytic groupings in its basic form. If you need both a grouped aggregate and the individual row details, you cannot express that with a single operator. You need either a join-back to the original relation or a more advanced extension to the algebra. This is why SQL added the OVER clause and why some research systems introduced additional operators. It is a genuine expressiveness gap in the pure relational model.
There is also a computational complexity consideration. Group by is inherently a many-to-one reduction. The worst-case complexity is O(n log n) for sort-based grouping or O(n) for hash-based grouping with sufficient memory. But when you go parallel or distributed, the cost model changes entirely. Data shuffling across nodes to bring matching keys together becomes the dominant factor, and the overhead can exceed the actual computation by orders of magnitude. Systems like Spark and Hive add a shuffle phase that has nothing to do with the algebra itself but everything to do with the physical implementation. The algebra describes what you want. It says nothing about how expensive it is to get there. If you are studying this for an exam, focus on the gamma notation, the decomposition into partition plus aggregate, and the composition with selection and join. If you are working with it in production, focus on the execution strategy, the statistics that drive the optimizer's choice, and the placement of selections relative to the grouping operation. The algebra gives you the contract. The engine gives you the bill.