Geospatial Technology Is Just How We Measure The Earth, Really
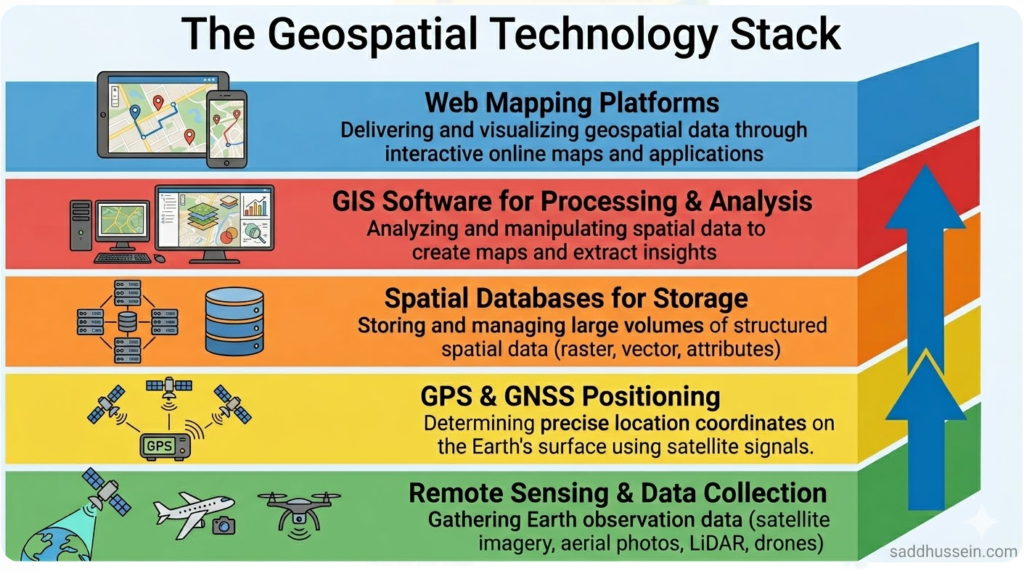
It sounds like a lot more than it is, but it really comes down to figuring out where something is and then using that location to understand patterns. Satellites, drones, ground sensors, and mobile devices all feed into the same basic workflow. You capture spatial data, you organize it, and you look for connections that aren't obvious from just looking at a map alone. The core pipeline is straightforward: acquire, process, analyze, and visualize. But the reality of running these systems day to day is far messier than any textbook will tell you. I spent years dealing with coordinate drift in high-precision LiDAR surveys, where a single misaligned laser return could shift a building footprint by nearly a meter over a kilometer of flight line. What I learned was that ground control points matter less than you think if your sensor is well-calibrated, and they matter enormously if it isn't. I started cross-referencing my GPS readings against existing cadastral data instead of relying on the equipment alone, and that changed everything about how reliable my output became.
How Are Geospatial Technologies Used To Learn About The World
At the surface level, people use geospatial tools to track deforestation, monitor urban growth, predict flood zones, manage agriculture, and navigate infrastructure projects. But the actual utility goes deeper. When you layer satellite imagery over soil composition data and weather patterns, you can model crop yields before the plants are even planted. When you combine traffic sensor data with transit ridership records, you can redesign bus routes in a way that actually moves people instead of just covering more miles. There are a few platforms worth knowing. ArcGIS is the industry workhorse and it is expensive. QGIS is free, open source, and completely capable if you know what you are doing. Google Earth Engine handles massive satellite datasets without requiring you to download them, which matters when you are processing MODIS or Landsat data across multiple years. For drone work, Pix4D and Agisoft Metashape are standard, though Pix4D generally runs smoother for large-scale surveys while Metashape gives you more control over the reconstruction parameters. One thing most beginners miss is that resolution is not the same thing as accuracy. A 30 centimeter per pixel image looks sharper than a 1 meter one, but that does not mean it is more accurate for mapping purposes. Accuracy depends on georeferencing quality, sensor calibration, and processing methodology. I once had a client who wanted 10 centimeter accuracy from drone footage that was taken in heavy wind. The gusts caused camera shake that no amount of processing could fully correct, so the final product was visually clean but measurably off by about 15 centimeters on key structural features. I recommended a second pass with a different flight pattern and tighter overlap settings, which brought it within tolerance. The first run wasted money but taught me something valuable about weather constraints that I never forget now.
The Data Layer Problem
The hardest part of any geospatial project is not the analysis, it is the data. You will spend far more time cleaning coordinate systems, merging shapefiles that do not align, and dealing with missing metadata than you will on actual model building. A common pitfall is assuming all your layers share the same projection. They rarely do, and reprojecting on the fly in software can introduce subtle distortions that compound across your analysis. Always define your project CRS upfront and reproject everything to match before you do anything else. Another issue is temporal inconsistency. Satellite images used in a three year study might come from different sensors, taken under different atmospheric conditions, processed by different algorithms. Comparing NDVI values from Sentinel 2 against Landsat 8 requires normalization, not just direct comparison. I have seen analysts skip this step and then wonder why their change detection results looked nonsensical. The solution is to use surface reflectance products where available, and always document your data sources with processing chains that are reproducible.
Get the Full Details
Practical Techniques That Actually Matter
Beyond the standard supervised and unsupervised classification workflows, there are a few techniques that routinely save time. Object based image analysis, or OBIA, is far more useful than pixel-based classification for high resolution imagery. Instead of classifying individual pixels, you group neighboring pixels into meaningful objects based on texture, shape, and spectral similarity, then classify those objects. This reduces the salt and pepper noise that plagues traditional methods and produces cleaner results, especially for urban and agricultural mapping. Machine learning is now standard in most geospatial workflows, but it is not a magic bullet. Random forests and gradient boosting handle tabular derived features well, but convolutional neural networks require substantial labeled data and computational resources. If you only have a few hundred training samples, a random forest with handcrafted features will outperform a deep learning model every time. The rule of thumb I follow is: start simple, add complexity only when the simpler model hits a ceiling that the data supports crossing. For terrain analysis, digital elevation models are foundational, but not all DEMs are created equal. SRTM has a 30 meter resolution and is freely available, but it struggles in dense forest canopy areas where the surface is obscured. ALOS World 3D data offers better coverage in forested regions, and airborne LiDAR is the gold standard when you need sub meter accuracy. The trade off is cost and data volume. I worked on a landslide susceptibility study where the difference between SRTM derived slope values and LiDAR derived ones changed the classification from moderate risk to high risk in several zones. The SRTM data had underestimated slope angles because the canopy was damping the terrain surface representation.
When Geospatial Technology Falls Short
It does not work everywhere. Cloud cover ruins optical satellite imagery over large swaths of the tropics for significant portions of the year. In those cases, SAR, or synthetic aperture radar, is your only reliable option since it penetrates clouds. But SAR data is harder to interpret, requires specialized processing, and the results are not as intuitively understandable as color imagery. I once tried to map wetland boundaries in the Amazon using optical data and ended up wasting two weeks on cloud-masked scenes before switching to Sentinel 1 SAR. The SAR approach worked, but it took me longer to learn the processing pipeline than I would have spent if I had switched sooner. Urban environments also present unique challenges. The urban canyon effect, where tall buildings block or multipath GPS signals, can degrade positioning accuracy to several meters. For precise indoor or dense urban navigation, RTK or PPP positioning is necessary, but those require network infrastructure or specialized post-processing services that are not universally available. I have found that combining GNSS with inertial measurement units from smartphones or dedicated hardware helps, but it adds cost and complexity that many projects cannot justify. There is also the question of scale. Geospatial models trained on one region often fail when applied elsewhere without retraining. A land cover classification model built on European agricultural patterns will not transfer well to Sub-Saharan farming systems without significant adaptation. This is one reason why open data initiatives like the Global Land Cover Facility and open-source modeling frameworks matter so much. They allow someone in Nairobi to build on work from Zurich instead of starting from scratch, which is how most small teams operate anyway.
Getting Started Without Overcomplicating It
If you want to begin, start with QGIS and Sentinel 2 data from Copernicus. Download the data through the SciHub interface or use the Sen2Cor processor to generate surface reflectance products. Build a simple NDVI layer, classify it using the maximum likelihood classifier, and validate the results with ground truth points you source from Google Earth or OpenStreetMap. It is a basic workflow, but it teaches you the full chain from raw data to analysis output without requiring expensive software or infrastructure. From there, move into OBIA using the eCognition trial version or the GRASS GIS segmentation tools. Then experiment with Google Earth Engine for larger scale analysis where processing time and data storage become real constraints. The platform's JavaScript or Python API lets you run computations on Google's servers instead of your own machine, which is a massive advantage when you are working with years of daily imagery over an entire country. The field moves fast, but the fundamentals do not change. Spatial data is messy, sensors have limitations, and no model is better than the data it is built on. The people who get good at this are not the ones who know every tool, they are the ones who understand when a tool is the wrong choice and know how to work around its weaknesses.