
The middle fifty of any dataset lives between two points, and the distance between them is what you're after.
IQR stands for Interquartile Range. It tells you how spread out the middle half of your data is. Outliers don't matter as much here because you are looking at the 25th percentile through the 75th percentile. That gives you a cleaner picture than standard deviation when your data has weird spikes at the edges. I have spent years cleaning messy operational datasets where the mean was lying to everyone. Standard deviation looked massive because three warehouse entries recorded negative weights by accident. The IQR stayed sane. That was the first thing that made me pay attention to it instead of skipping ahead.
How Do You Calculate Iqr Step by Step
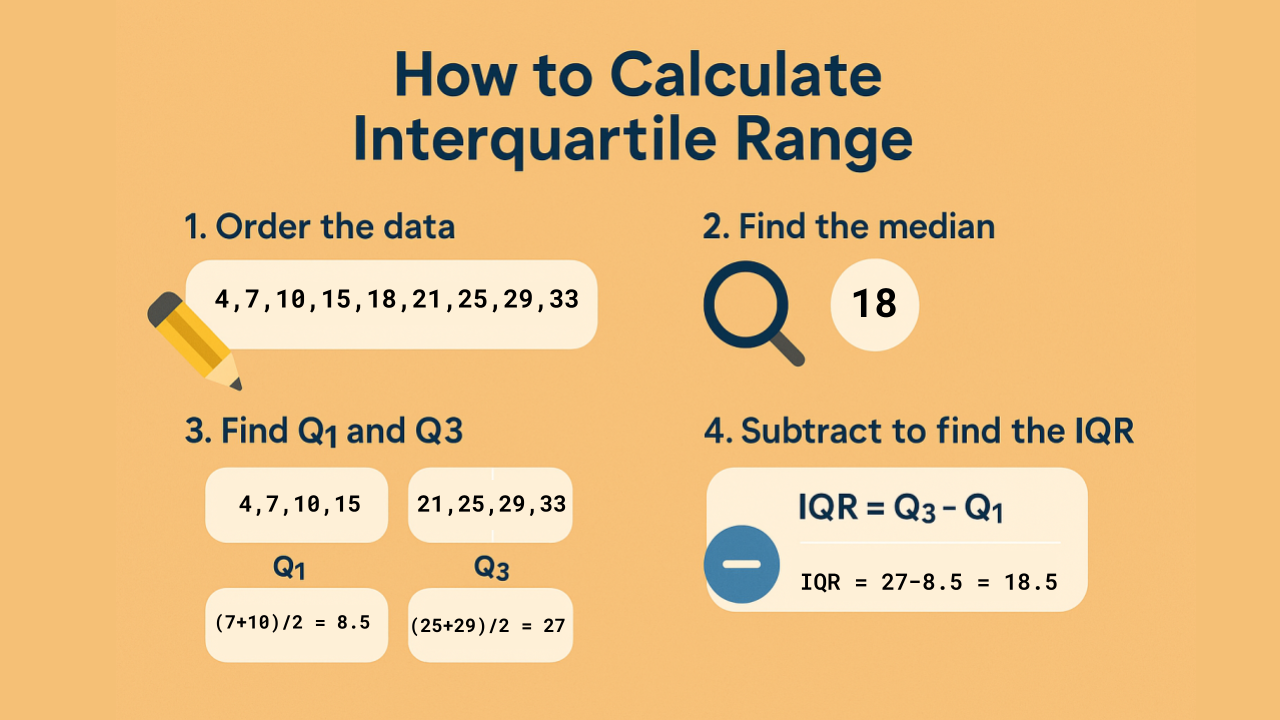
Write down all your numbers. Sort them from smallest to largest. Find the median, which splits the dataset in half. If the count is odd, drop the middle number and work with the lower and upper halves separately. If the count is even, split the list right down the middle and treat both sides as their own group. Take the lower half and find its median. That value is Q1, the 25th percentile. Take the upper half and find its median. That value is Q3, the 75th percentile. Subtract Q1 from Q3 and you have your IQR. Here is a concrete example. Let me walk through a real set of numbers I used recently. The dataset was support ticket resolution times in minutes: 4, 7, 9, 12, 15, 18, 22, 25, 31, 40, 95. Eleven values, so the median is the sixth number, which is 18. Drop that middle number. The lower half is 4, 7, 9, 12, 15. The median of that is 9. So Q1 equals 9. The upper half is 22, 25, 31, 40, 95. The median there is 31. So Q3 equals 31. IQR is 31 minus 9, which gives you 22 minutes.
When the dataset had an even count, like twelve numbers instead of eleven, the method changes slightly. You do not drop the middle. You just split the list and take the median of each half. With twelve sorted values, the lower six form Q1's group and the upper six form Q3's group. If either half has an even count inside it, you average the two middle values to get that quartile. This is where people make mistakes and get slightly wrong answers without noticing.
Get the Full Details
The edge case that cost me a morning
I was working with a logistics dataset that had exactly 48 observations. The lower half had 24 values and the upper half also had 24. When I calculated the median of each half manually, I got one result. When I ran the same numbers through Excel's QUARTILE function, the output differed by about 3.5 percent. It was subtle but enough to throw off my outlier fences. The issue is that Excel and many calculators use interpolation methods to estimate quartile positions rather than the strict split-half median method. Excel's older QUARTILE function uses a different algorithm than the newer QUARTILE.EXC version. The older one can include the overall median in both halves, which double-counts it and shifts Q1 and Q3 slightly. The newer EXC version excludes the median entirely and interpolates between the two nearest data points. Both are valid, but they are not interchangeable. My workaround was simple. I decided on the method upfront and stuck with it. For most operational work I use the strict split-half method because it is transparent and auditable. If someone asks where the numbers came from, I can show them the list and point to the middle. I document which method I am using in the analysis notes. If I ever need Excel-style interpolation, I switch to QUARTILE.EXC and note that explicitly. Never mix the two in the same report.
What most people miss about IQR
IQR does not tell you anything about the shape of your distribution. Two datasets can have identical IQR values and look completely different. One could be symmetric and tight. The other could be heavily skewed with a long tail. The IQR alone cannot distinguish between them. Always look at Q1, Q3, and the median together, and check a boxplot or histogram before drawing conclusions. Another thing beginners routinely overlook is how sample size affects stability. With fewer than twenty data points, IQR is unreliable. A single change in one extreme value can swing Q1 or Q3 by a large percentage. I would not trust an IQR calculation on a dataset smaller than about thirty observations unless you are doing exploratory work and flagging the result as preliminary. Beyond that threshold, the quartile positions stabilize enough for most practical purposes.
Using IQR to detect outliers
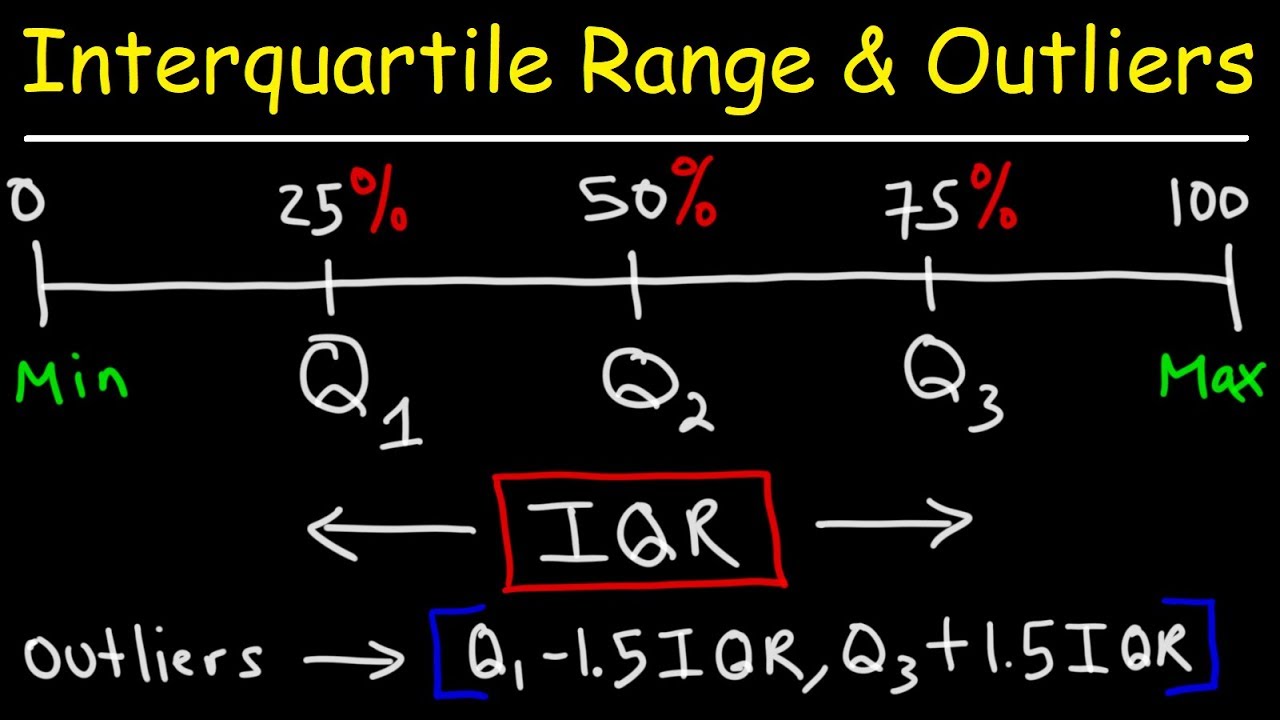
The most common application is outlier detection. Multiply the IQR by 1.5. Any value below Q1 minus that product or above Q3 plus that product is considered a mild outlier. Multiply the IQR by 3 for extreme outliers. This is the standard Tukey fence method and it works well for roughly symmetric data. In practice, I found this approach flagged about 4 to 8 percent of clean operational data as outliers depending on the domain. That matched expectations. But I also learned that it is not universal. For heavily skewed distributions like response times or transaction amounts, the fences can be absurdly wide on one side and useless on the other. In those cases, a log transform before calculating IQR often produces more meaningful fences. I do this regularly with server latency data where raw values span orders of magnitude.
Limitations you need to accept
IQR ignores everything outside the middle fifty. If your analysis depends on understanding the tails, this method will blind you to important patterns. It also does not incorporate all data points into a single summary number, which means it can feel unsatisfying when stakeholders want one metric that represents the whole dataset. Standard deviation stays popular for that reason, even though it is more sensitive to noise. For bimodal or multimodal distributions, IQR can be misleading. The middle fifty might sit in a valley between two peaks, making the range look narrow when the data is actually split into distinct groups. I encountered this once with a customer satisfaction score dataset that had two clear clusters. The IQR suggested low variability. The reality was two very different customer experiences. In situations like that, IQR is the wrong tool and you should use segmentation or mixture modeling instead. If you need a robust measure of spread that accounts for all data points, consider the median absolute deviation. It is less commonly known but often more informative alongside IQR. I usually report both in technical summaries and let the reader decide which metric fits their context better.
Quick reference for common tools
Python: Use numpy.percentile or scipy.stats.iqr. The scipy version has an interpolation parameter you can adjust if you need consistency with a specific quartile definition. R: The IQR function is built in. It uses type 7 quantile estimation by default, which is the same as Excel's older QUARTILE behavior. Excel: Use QUARTILE.EXC for the exclusive method or QUARTILE.INC for the inclusive method. Make sure both people comparing results are using the same function.
Google Sheets: QUARTILE function follows the inclusive method, equivalent to Excel's INC variant. Pick your tool, pick your method, document both, and move on. The math itself is straightforward. The difficulty is usually in knowing which definition your software is using and making sure it matches what your audience expects.

 in Math"")

