The Actual Process of Transcribing DNA to mRNA
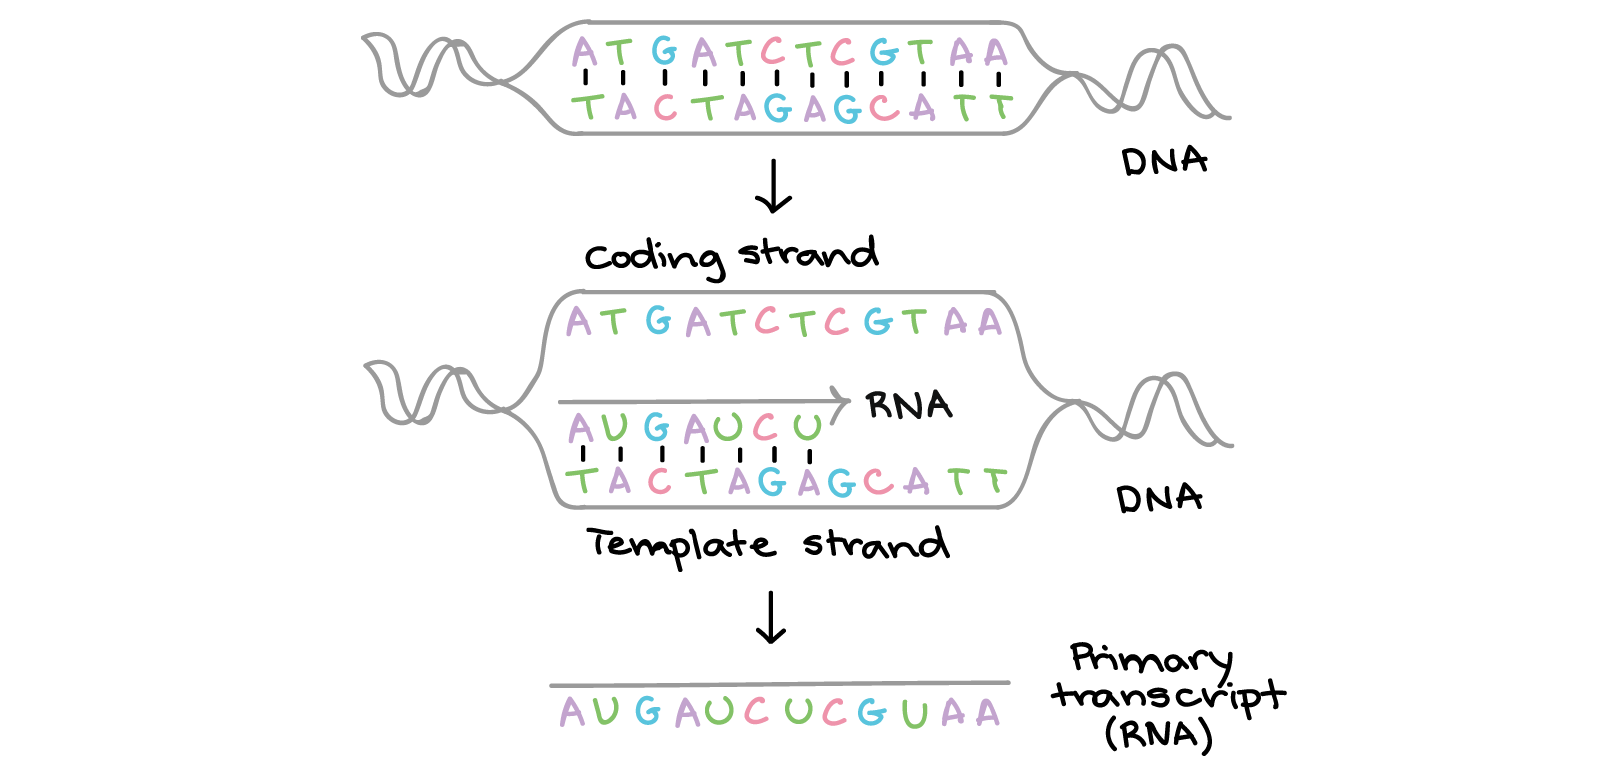
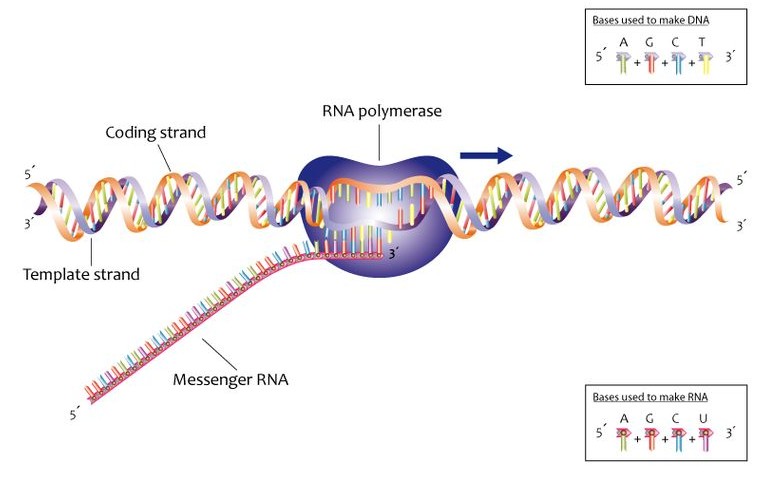
I spent a few semesters in an undergraduate molecular biology lab where we did exactly this by hand on paper worksheets. The professor would hand us a snippet of a gene sequence and demand the complementary mRNA strand. Most students got tripped up on the same two things: which DNA strand to read, and what to do about uracil. Once those clicks into place, the actual mechanics are straightforward base pairing. First, you need to identify the template strand. DNA is double-stranded and antiparallel. The template strand runs 3 prime to 5 prime, and RNA polymerase reads it in that direction while synthesizing mRNA 5 prime to 3 prime. The other strand, the coding strand, has the same sequence as the resulting mRNA except it still carries thymine instead of uracil. A lot of people mistakenly transcribe from the coding strand directly and end up with the reverse complement when they actually needed the normal sense sequence. I still see this in first-year exam papers. Here is the actual step-by-step of what happens inside a cell and what you do on paper:
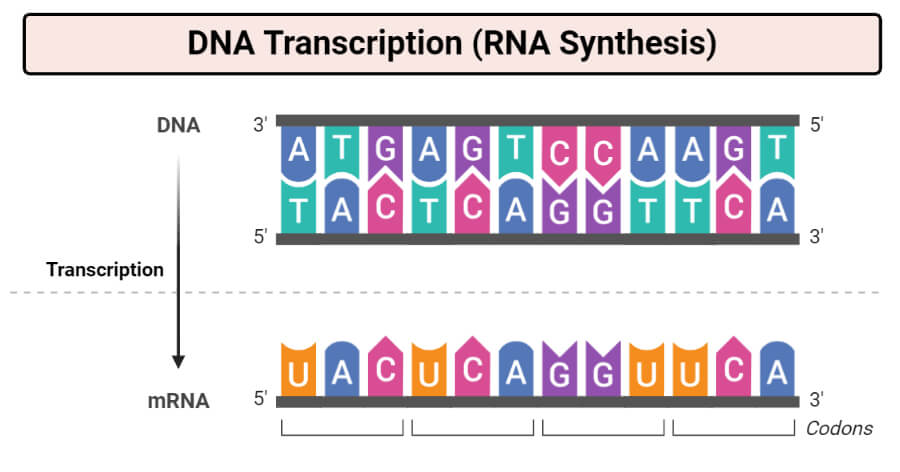
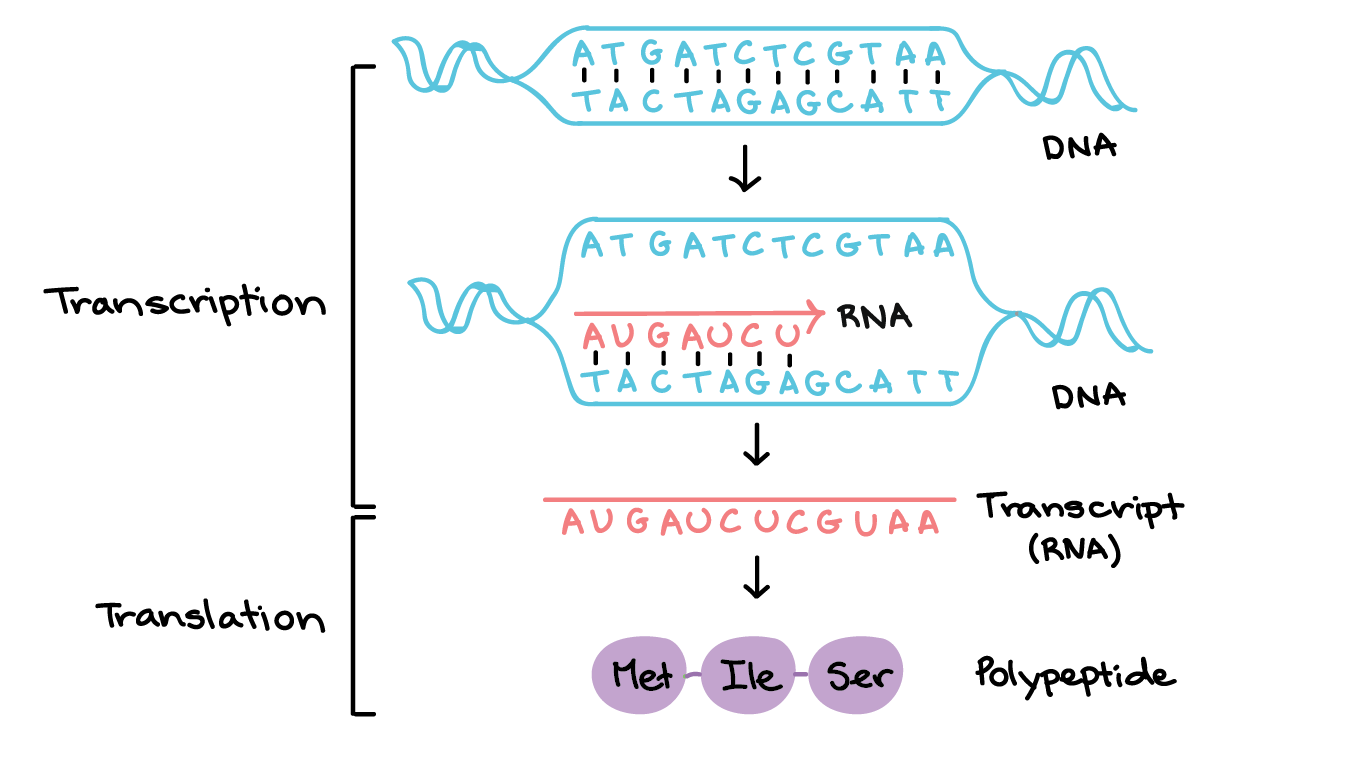
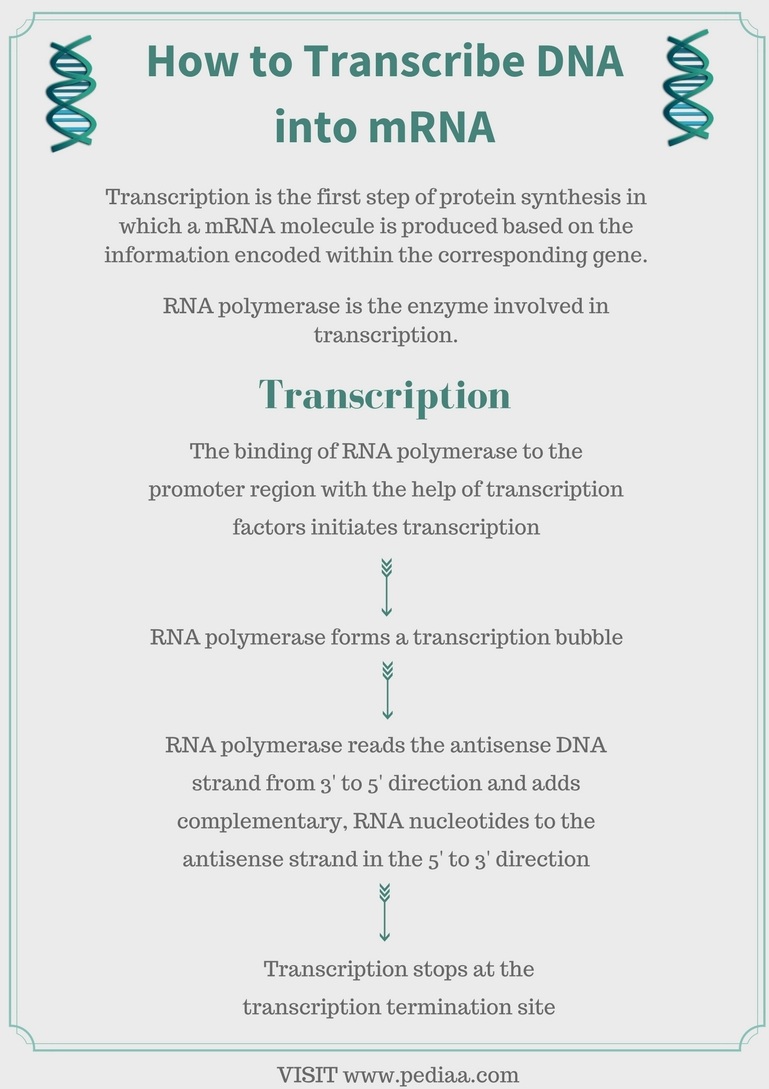
Step one is locating the promoter region. This is a specific DNA sequence upstream of the gene that signals where transcription should begin. In bacteria you might see a TATAAT box, known as the Pribnow box. In eukaryotes it is more complex with TATA boxes and various enhancer elements. RNA polymerase, along with transcription factors, binds here to form the transcription initiation complex. This part matters because if you are looking at a genomic context and trying to figure out which strand is actually the template, the promoter orientation tells you the direction of transcription. Step two is unwinding the DNA double helix. The enzyme opens up roughly 14 base pairs at a time to expose the template strand. This forms what is called the transcription bubble. You do not need to memorize the exact number for most introductory purposes, but it helps to know that only a small section is single-stranded at any given moment, not the entire gene. Step three is elongation. RNA polymerase reads the template strand and adds complementary RNA nucleotides one by one. Adenine on the DNA pairs with uracil on the RNA. Thymine on the DNA pairs with adenine on the RNA. Guanine pairs with cytosine and cytosine pairs with guanine. The RNA chain grows in the 5 prime to 3 prime direction. This means you write the mRNA sequence starting from the 5 prime end, reading the template strand from 3 prime to 5 prime.
Step four is termination. In bacteria, this often involves a hairpin loop structure forming in the newly synthesized RNA, which causes the polymerase to detach. In eukaryotes, the process is more involved and typically involves cleavage of the transcript and addition of a poly-A signal sequence. The polymerase continues transcribing past the actual end point before falling off. Step five in eukaryotes involves RNA processing. The initial transcript, called pre-mRNA, undergoes several modifications before it becomes mature mRNA. A 7-methylguanosine cap is added to the 5 prime end. This cap protects the mRNA from degradation and is recognized by the ribosome during translation. A poly-A tail consisting of roughly 200 adenine residues is added to the 3 prime end. This also provides stability and aids in nuclear export. Then there is splicing, where introns, the non-coding intervening sequences, are removed and exons, the coding regions, are joined together. This is done by a complex called the spliceosome, which recognizes specific consensus sequences at the intron boundaries. Alternative splicing means a single gene can produce multiple different mRNA variants, which is why the human genome with roughly 20,000 protein-coding genes can produce far more than 20,000 distinct proteins. I ran into a real problem a few years ago when I was working with cloned gene sequences and trying to predict the mRNA product from a genomic DNA fragment. The sequence I had included what looked like a partial intron near the 5 prime end. My initial manual transcription produced a reading frame that made no biological sense. The issue was that I was treating the entire inserted sequence as if it were all exon. I had to go back and identify the canonical GT-AG splice site pairs, remove the intronic region, and then transcribe only the spliced exonic sequence. It took me about an hour to figure out what went wrong instead of the five minutes it should have taken. The workaround was simply running a preliminary splice site prediction using standard consensus motifs before doing the actual transcription, and cross-referencing with known isoform databases when available.
Get the Full Details
Common Pitfalls and Things That Break
One thing that beginners consistently mess up is the directionality. If you are given the non-template coding strand written 5 prime to 3 prime, you do not just swap T for U and call it done. That actually gives you the correct mRNA sequence in most textbook problems, but only because the coding strand is already the sense sequence. The conceptual confusion comes when you are given the template strand and need to produce the mRNA, or when you are working with actual research data where you only have one strand sequenced and need to figure out orientation. I would recommend always drawing out the antiparallel strands with explicit 5 prime and 3 prime labels rather than trying to do this in your head. Another issue is promiscuous transcription. In eukaryotic genomes, RNA polymerase II can initiate at low levels from many sites that resemble promoters but are not true promoters. This produces what are called pervasive transcripts, many of which are rapidly degraded and never translated. If you are analyzing RNA sequencing data and seeing transcription across regions you would not expect to be transcribed, this is often what is happening. It is a real bottleneck when you are trying to identify genuine transcriptional units from noisy data. Filtering requires combining strand-specific RNA-seq with careful annotation against known gene models and often Ribo-seq data to confirm which transcripts are actually being translated. The other limitation worth noting is that in vitro transcription systems, which you might use if you need to produce mRNA in the lab for something like a vaccine or a functional assay, do not perform splicing. If your gene contains introns, you must start with cDNA, not genomic DNA. I have seen people waste days on this. They clone the genomic version into a transcription vector, run the reaction, and get a full-length transcript that still contains intronic sequence, then wonder why the protein does not express correctly in their downstream system. Always verify your template is intron-free before setting up an in vitro transcription.
For practical transcription from a DNA sequence on paper or in a basic bioinformatics tool, you do not need anything fancy. A simple script that identifies the template strand, reads it in the 3 prime to 5 prime direction, and substitutes uracil for thymine will handle the core task in under a second. The harder part is always knowing which strand is the template and whether post-transcriptional modifications like splicing are relevant to your particular question.