Working with Eigenvectors in Practice
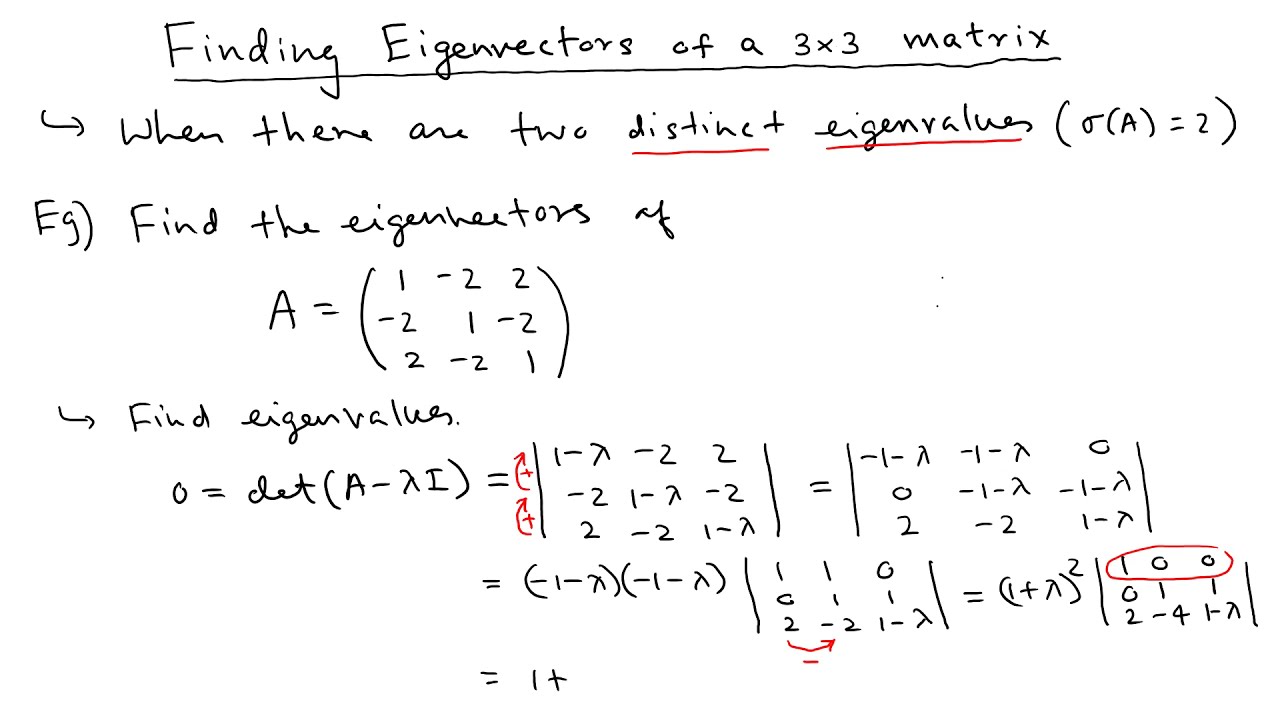
You set up the eigenvalue problem and then spend the next hour making sure your arithmetic didn't break somewhere. That's the real work. The math itself is straightforward linear algebra. Finding the actual vectors is where people usually lose track of what's happening.The process starts with the characteristic equation. You take your matrix A, subtract lambda times the identity matrix, and set the determinant equal to zero. This gives you the eigenvalues first. Once you have those, you plug each one back into (A - I)x = 0 and solve the resulting homogeneous system. The non-zero solutions are your eigenvectors. For a 2x2 matrix, the determinant calculation is manual and you need to be careful with the signs. Take A = [[4, 1], [2, 3]]. You compute det(A - I) = (4-)(3-) - 2. Expand that to get ² - 7 + 10 = 0. Factor it: (-5)(-2) = 0. Eigenvalues are 5 and 2. Now for = 5. You substitute back into A - 5I, which gives [[-1, 1], [2, -2]]. Row reduce that. The second row is just -2 times the first row, so you really have one equation: -x + y = 0, meaning x = y. Your eigenvector is any scalar multiple of [1, 1]. For = 2, you get A - 2I = [[2, 1], [2, 1]], which reduces to 2x + y = 0, so y = -2x. The eigenvector is any multiple of [1, -2].
For larger matrices, this gets expensive fast. A 4x4 matrix means solving a quartic equation, and the roots might not be nice integers. That's when you switch tactics and use numerical methods. The QR algorithm is the standard approach. It iteratively transforms the matrix into upper triangular form while preserving eigenvalues. Most implementations in numpy, MATLAB, or scipy handle this without you writing any of the numerics yourself. I ran into a case recently where I was diagonalizing a covariance matrix for a dataset with nearly collinear features. The eigenvalues came out as something like 10.0001 and 9.9998, which looked fine until I computed the condition number. The eigenvectors were wildly sensitive to tiny perturbations in the input. A single bit of floating point noise changed the direction significantly. I ended up thresholding the smaller eigenvalue and treating those dimensions as numerically zero rather than trying to work with the unstable eigenvectors directly. That saved me from chasing garbage directions in downstream calculations.
What People Get Wrong About Eigenvectors
The first issue is normalization. Textbooks often present eigenvectors as unit vectors, but that's a convention, not a requirement. Any non-zero scalar multiple works. When you're coding this up, just be consistent about whether you're returning normalized vectors or raw ones, because mixing the two silently produces wrong results downstream. Another thing that trips people up is the assumption that every matrix has real eigenvectors. Complex eigenvalues exist, and the corresponding eigenvectors live in complex space. If you're working with a rotation matrix in 2D, you'll find eigenvalues like cos() ± i sin(). The eigenvectors have complex entries. For many engineering applications, you don't actually need to compute these explicitly because the real canonical form handles them just fine. Defective matrices are another edge case. Not every matrix is diagonalizable. A Jordan block like [[0, 1], [0, 0]] has only one eigenvector for its single eigenvalue. The geometric multiplicity is less than the algebraic multiplicity. If you're building a system that assumes full diagonalization, it will silently fail or produce incomplete results on these cases. Check the rank of (A - I) before proceeding. If the nullity doesn't match the multiplicity of the eigenvalue, you're dealing with a defect.
Get the Full Details

In practice, the big bottleneck isn't the theory, it's the scaling. When your matrix is 1000x1000 or larger, computing all eigenvalues and eigenvectors takes noticeable time and memory. The LAPACK routines behind scipy.linalg.eigh or numpy.linalg.eig are well optimized, but you still pay O(n³) for a full decomposition. If you only need a few dominant eigenvectors, use an iterative method like Lanczos or ARPACK through scipy.sparse.linalg.eigsh. That brings it down to something more manageable, often completing in minutes instead of hours depending on your matrix structure and available memory.
When the Standard Approach Fails
Symmetric matrices are the easiest case. They always have real eigenvalues and orthogonal eigenvectors. The eigensystem is well-behaved. Non-symmetric matrices are less predictable. You can get complex conjugate pairs, defective structures, and sensitivity issues. If you're doing this for a physics simulation or a structural mechanics problem, your matrix is probably symmetric or at least structured in a way you can exploit. For a general data science application, you might not have that luxury. If your matrix is sparse and you need only the largest or smallest eigenvalues, the power iteration method is worth knowing about. You pick a random vector, repeatedly multiply it by your matrix, and normalize. The vector converges to the eigenvector associated with the dominant eigenvalue. It's simple enough to implement from scratch in under fifty lines, and it scales well for sparse matrices where dense decomposition would be wasteful. The downside is that it only gives you one eigenvector per run, and convergence can be slow if the gap between the largest and second-largest eigenvalue is small. There's also the case where your matrix changes over time, like in a Kalman filter or an online PCA setup. Recomputing the full eigensystem from scratch at every step is overkill. You can use eigenvector perturbation theory to update the decomposition incrementally. The first-order correction to an eigenvector when the matrix shifts by a small amount A is a weighted sum involving the other eigenvectors and the inverse differences of eigenvalues. This breaks down when eigenvalues are close together, which circles back to the sensitivity problem I mentioned earlier. In those situations, a full recompute is sometimes the safer choice even if it costs more.
The practical takeaway is to match your method to the structure of your problem. Small dense matrix with exact arithmetic needed? Go analytical or use a direct solver. Large sparse matrix where you only need a handful of eigenvectors? Iterative methods. Nearly singular or ill-conditioned? Expect numerical instability and plan around it. I've seen projects fail because someone ran a full eigendecomposition on a 5000x5000 matrix and then wondered why their pipeline took forty-five minutes per batch when a targeted sparse solver would have completed in under three.