The Mode Isn't Complicated, But People Make It More Complicated Than It Needs To Be
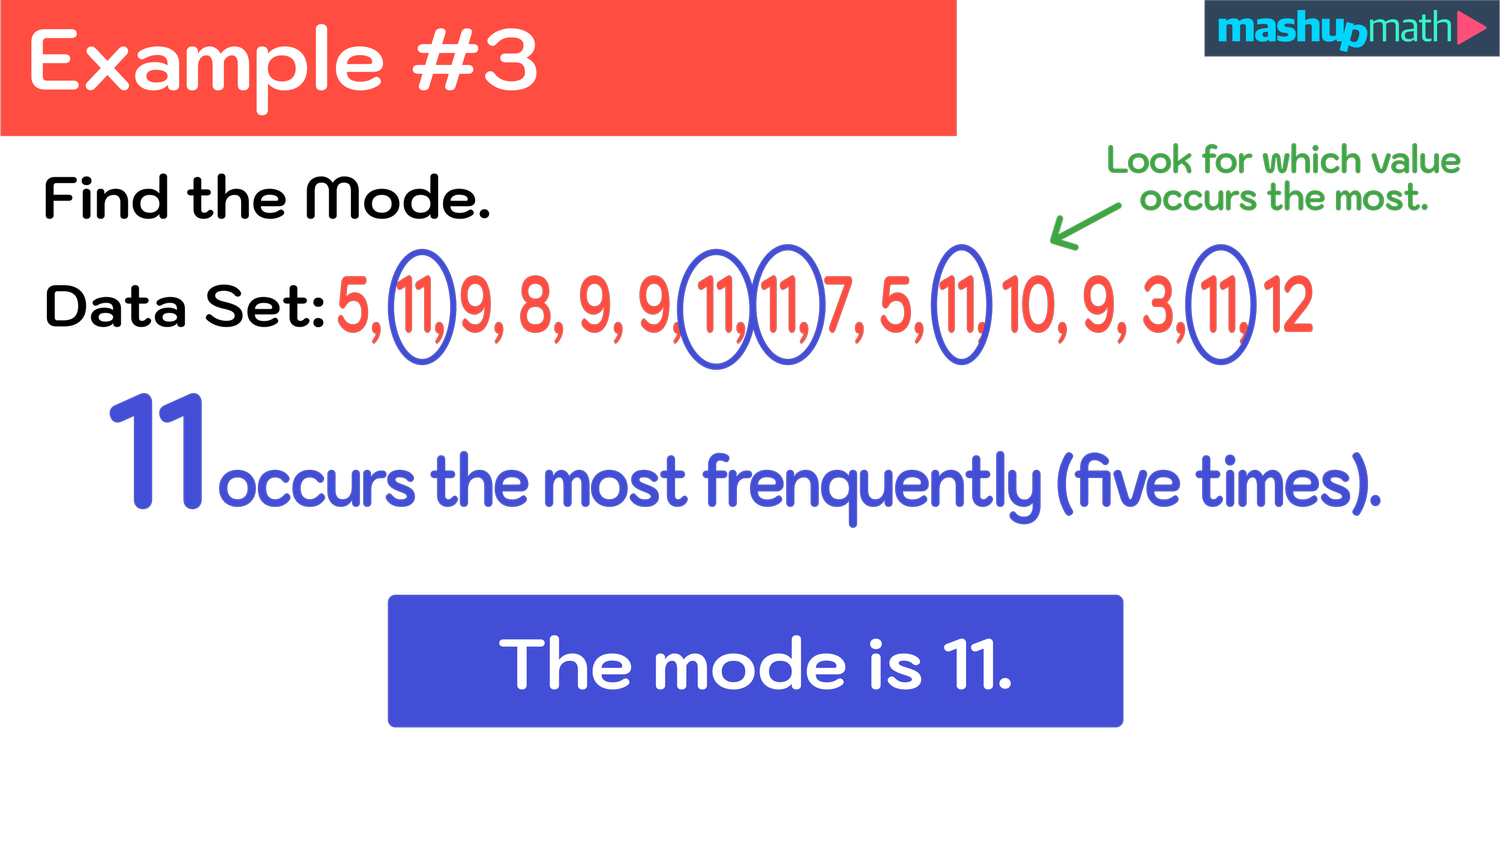
Mode is the value that appears most frequently in a dataset. That's the textbook definition, and it's accurate enough for most purposes, but the reality of working with actual data makes it less cut-and-dry than a middle school worksheet would suggest. Here's the quick version: you count how many times each number shows up, and whichever number has the highest count is your mode. That's it. But there are enough edge cases that if you're only thinking about clean, single-mode datasets, you're going to run into problems.
How To Find Mode In Math
The standard procedure is straightforward. Take your dataset. Tally the frequency of each distinct value. Identify the value or values with the highest frequency. Done. For a dataset like {2, 3, 3, 5, 7, 7, 7, 9}, you'd see that 7 appears three times, which is more than any other value, so 7 is the mode. For {1, 1, 4, 4, 4, 6, 8}, 4 is the mode with a frequency of 3. Simple enough. Where people actually get tripped up is with multimodal distributions. A dataset can have more than one mode. If you have {2, 2, 5, 5, 9}, both 2 and 5 appear twice and neither appears more frequently than the other. That's bimodal. Some people call this "no mode," which is wrong. The dataset has two modes. There are also trimodal and multimodal datasets, though those are relatively rare in practice outside of artificially constructed examples.
Then there's the uniform case. If every value in your dataset appears exactly once, like {1, 2, 3, 4, 5}, then there is no mode. This isn't a failure of the method. It's a valid result. A dataset without repeated values simply doesn't have one. I remember working with survey data a while back where we were analyzing Likert-scale responses from roughly 2,000 participants. The question was about satisfaction levels on a scale from 1 to 5. When I calculated the mode, I got a bimodal distribution with peaks at both 1 and 5, and a flat middle section. The obvious interpretation was a polarized response pattern, but that initial reading was misleading. When I went back and cross-referenced by department, I found that the bimodality was entirely driven by two departments with opposite tendencies. Pooled together, they created a false impression of division across the entire organization. The mode itself was correct, but the contextual story it told was wrong because I wasn't segmenting the data before analysis. I ended up presenting the modes by department rather than the aggregate, which was the actually useful finding. That's the kind of thing that doesn't show up in textbooks. The mechanics of finding a mode are trivial. Interpreting what it means in context is where the work actually is.
Get the Full Details

One counter-intuitive point that beginners consistently miss: the mode is the only measure of central tendency that works for nominal data. You can't calculate a meaningful mean or median for categories like "red, blue, red, green, blue, blue" unless you assign them numerical values, which introduces assumptions you may not want to make. The mode is just "blue" because it appears most often. It requires zero assumptions about ordering or distance between values. That's not a minor detail, it's the reason the mode survives in datasets where the mean and median are meaningless. Another thing that doesn't get enough attention: the mode is sensitive to binning when you're working with continuous data. If you're trying to find the mode of a distribution of heights measured in centimeters, the answer changes depending on whether you group the data into 1-centimeter bins or 5-centimeter bins. With fine enough binning, you might get a spurious single mode; with coarse binning, modes can merge or disappear. This is why kernel density estimation exists as an alternative approach for continuous data. It smooths out the binning dependency rather than eliminating it entirely. Here's a practical method I use when working with larger datasets, say 100 or more values: I sort the data first, then scan through it once, counting consecutive runs of identical values. This avoids the overhead of building a frequency dictionary or hash map in your head, which gets error-prone past a certain dataset size. With sorted data, repeated values cluster together and you can count runs by eye or with a simple spreadsheet formula.
In a spreadsheet environment, the MODE.SNGL function returns the single most frequent value, and MODE.MULT returns all modal values as an array. The older MODE function still exists for backward compatibility but it's been superseded. If you're using Python, scipy.stats.mode gives you both the mode value and its frequency count, which is useful because knowing the frequency matters just as much as the mode itself. A mode of 42 appearing twice in a dataset of 500 values carries very different weight than a mode of 42 appearing 150 times. The main limitation of the mode as a statistical tool is that it ignores the distribution shape entirely. Two completely different datasets can share the same mode while being nothing alike otherwise. Consider {1, 1, 1, 1, 100} and {1, 1, 1, 50, 50}. Both have a mode of 1, but the second dataset is clearly more spread out and the single mode tells you almost nothing about the overall structure. Relying on the mode alone for decision-making is where people go wrong, not in understanding how to calculate it. For small datasets under 20 values, doing it by hand is fast and reliable. Above that, I'd recommend using a tool. The cognitive load of tracking frequencies manually increases linearly with dataset size, and the error rate becomes non-trivial. A five-minute spreadsheet operation replaces about fifteen minutes of manual tallying with near-zero error probability.
The mode is also the least stable measure of central tendency across samples. Draw two random samples from the same population and their modes can differ significantly, especially with small sample sizes or discrete data with few distinct values. The mean converges to the population mean much more reliably as sample size increases. This stability problem is why the mode gets less emphasis in introductory statistics courses, even though it's the simplest concept to grasp. If you're dealing with categorical data where the mean and median don't apply, the mode is your only option for a central tendency measure. If you're dealing with continuous data, it's worth calculating alongside the mean and median, but don't treat it as a replacement for them. And if you're working with grouped or binned continuous data, be honest about the binning dependency when you report your findings.