The Mechanics Behind Finding a P-Value
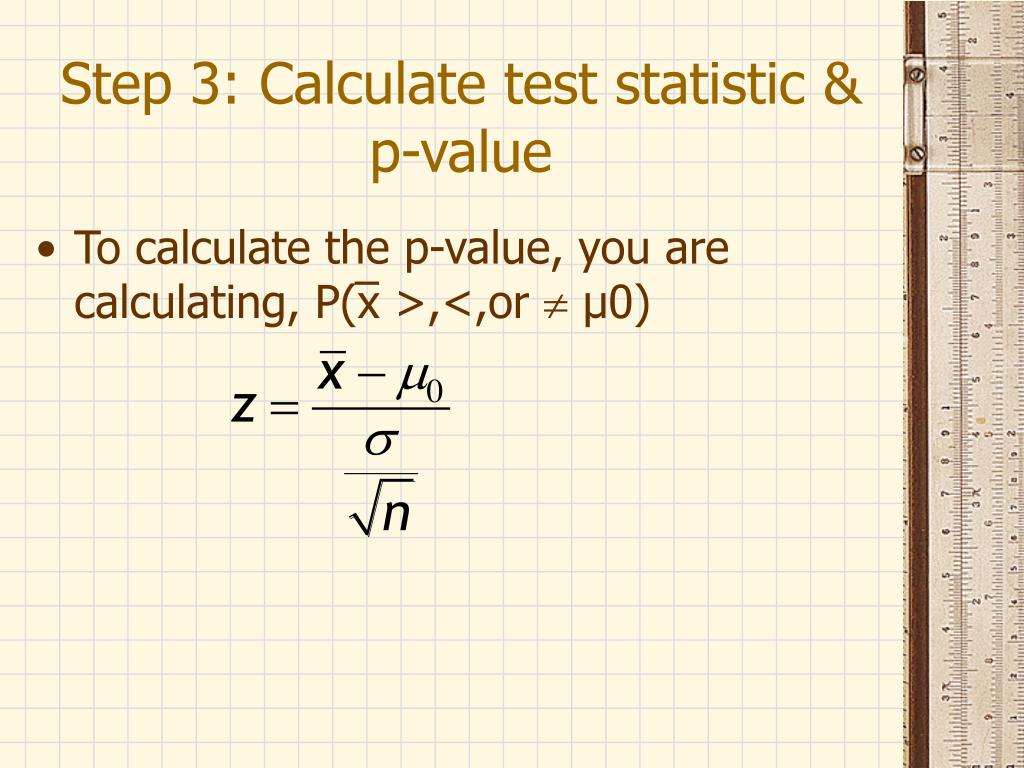
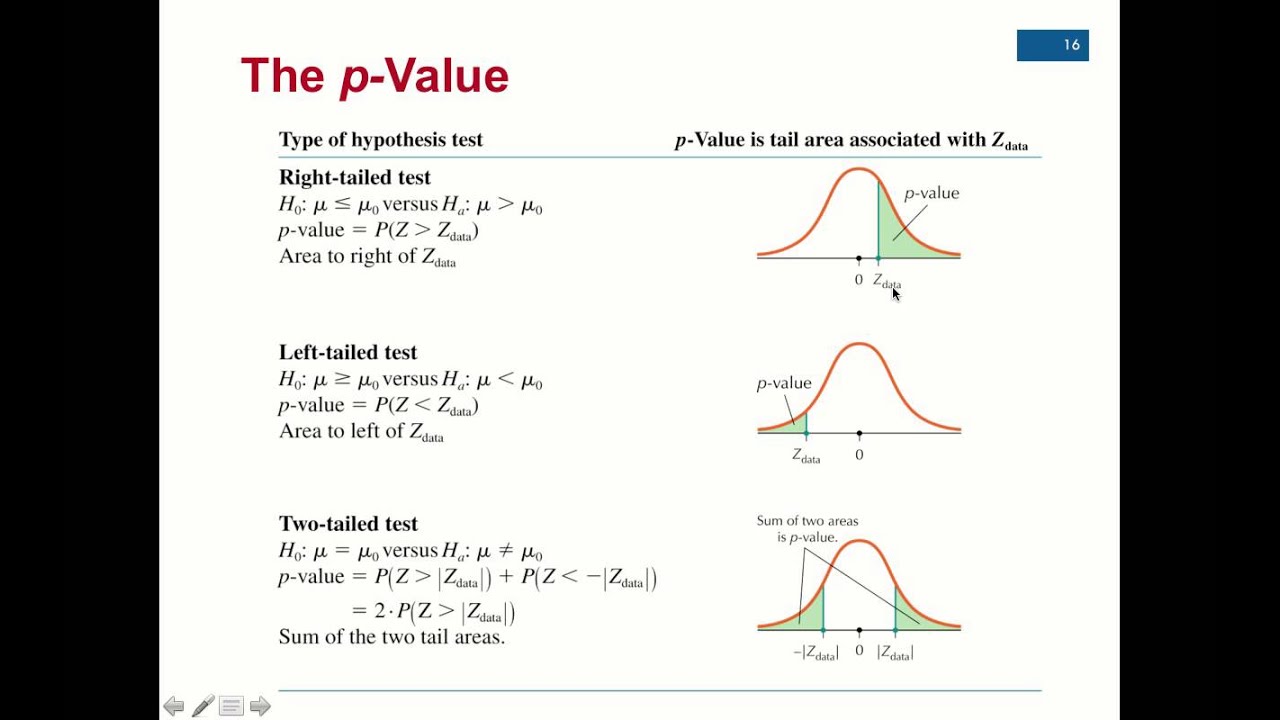
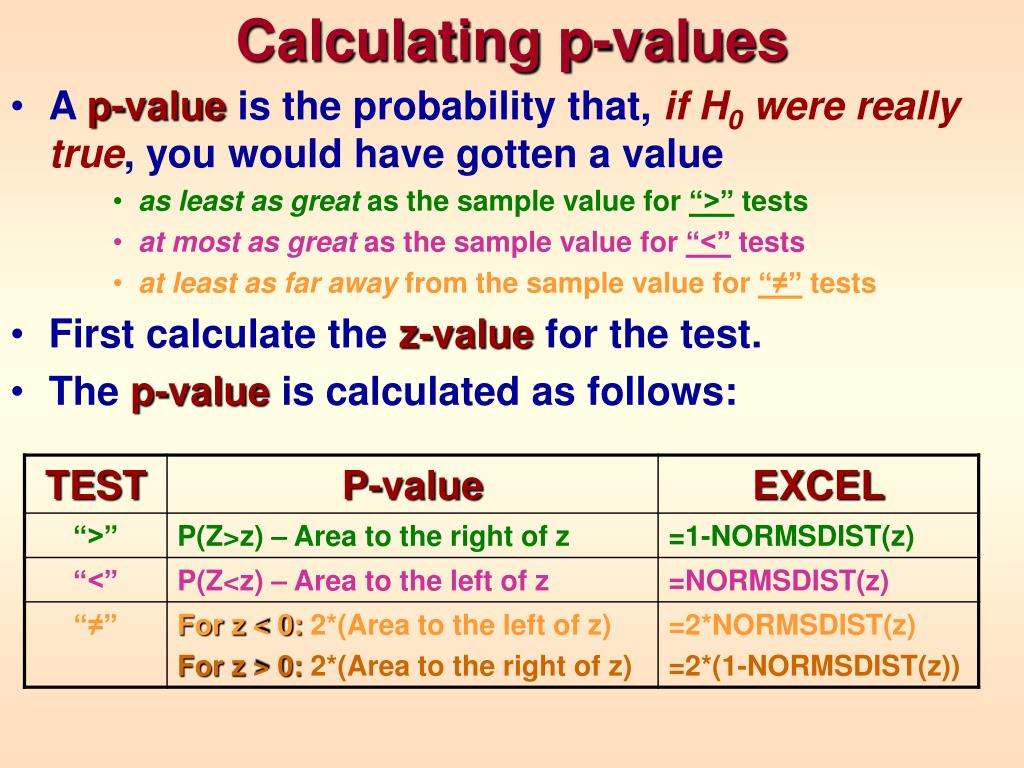
A p-value tells you the probability of observing your test statistic—or something more extreme—if the null hypothesis is actually true. That's it. It does not tell you the probability that your hypothesis is correct, which is a misunderstanding I see constantly. To calculate it by hand, you need three things: your test statistic, the appropriate probability distribution, and the degrees of freedom. From there, you locate your statistic on that distribution's cumulative table and read off the area in the tail.
How To Find P Value in Practice
Most people I work with just run their data through a calculator or software package, which handles the integration numerically. The real question is whether the right test was chosen upfront, because the output is only as meaningful as the assumptions baked into it. You need to specify whether you are looking for a one-tailed or two-tailed result depending on your hypothesis, which gets handled automatically in most tools, but it's important to pick the right one upfront. The output gives you both the test statistic and the p-value, which is what you actually need. Most people stop there, but I've seen plenty of cases where that's not enough. If your data is non-normal or your sample size is really small, parametric tests can give misleading results. That's when you might need to fall back on a permutation test or bootstrap approach instead. I had a situation a few years back where I was analyzing survival data with a lot of tied event times using a log-rank test, and the p-value came out borderline. Looking at the raw data, I realized the proportional hazards assumption was seriously violated between the two groups, so the standard test was not actually valid for what I was trying to measure. I switched to a weighted log-rank test—specifically a Fleming-Harrington weight—and the adjusted p-value told a completely different story than the unweighted version.
Using Tables When Software Is Not Available
Statistical tables are the traditional way to approximate a p-value by hand. They give you ranges rather than exact numbers. If your t-statistic is 2.14 with 15 degrees of freedom, the table shows it falls between 2.131 and 2.145. That means the one-tailed p-value is between 0.05 and 0.025. You do not get an exact figure unless you interpolate or switch to software. Tables are still useful when you need a quick sanity check before running a full model, or when you are in an environment where computing resources are restricted. The downside is that interpolation introduces error, and most published tables only go to two decimal places for critical values, which limits precision to around the third decimal place for the p-value itself.
Get the Full Details
Common Mistakes That Wreck Your Result
The biggest issue I encounter is testing the wrong distribution. People will plug a mean comparison into a z-test when the sample is small and the population variance is unknown, which inflates the test statistic and deflates the p-value artificially. Use a t-distribution with the correct degrees of freedom when the population variance is estimated from the sample. Another frequent problem is ignoring multiple comparisons. If you run ten independent tests at alpha equals 0.05, the chance of at least one false positive climbs to about 40 percent. Applying a Bonferroni correction brings the per-test threshold down to 0.005, but it also reduces power, so the trade-off needs to be explicit in your design. P-hacking is the other side of that same coin. When researchers test dozens of variations and report only the significant ones, the published p-values are no longer trustworthy. Pre-registration and analysis plans help, but they do not fix the fundamental problem of data dredging after the fact.
Interpreting the Number Without Overcommitting
A p-value below 0.05 is often treated as a hard boundary for significance, but it is a convention, not a law. The actual threshold depends on your field, the cost of a false positive, and the power of your study. Reporting a p-value of 0.049 and a p-value of 0.051 as categorically different results is a mistake I see in peer review all the time. Pair every p-value with an effect size and its confidence interval. The interval tells you the range of plausible values for the true effect, which is usually more useful for decision-making than a binary reject-or-fail-to-reject outcome. A small effect that reaches p less than 0.001 with a massive sample is rarely more important than a moderate effect that barely misses significance with a small sample. There is also a persistent confusion between the p-value and the probability that the null hypothesis is true. They are not the same thing. The p-value is computed under the assumption that the null is true. It does not update the probability of the null itself. Bayesian methods handle that direction of inference directly, but they require a prior, which is a separate layer of assumptions you need to justify.
What Happens When the Method Breaks
No test works well under every condition. Standard parametric tests assume independence, specific distributional shapes, and homogeneity of variance. Violate those assumptions and the p-value loses its stated meaning. Nonparametric alternatives exist, but they have lower power when the parametric assumptions hold, so you need to weigh that trade-off explicitly. Large sample sizes expose another limitation. With thousands of observations, even trivial deviations from the null produce small p-values. The test becomes sensitive to noise rather than to meaningful effects. In those cases, focus on the magnitude of the effect and its practical relevance instead of treating the p-value as the primary result. If you need exact p-values for small or sparse datasets, consider Fisher's exact test for contingency tables or exact permutation methods for continuous data. They are computationally more intensive, but they do not rely on the asymptotic approximations that break down in those scenarios.