The Math Behind The Numbers Nobody Talks About
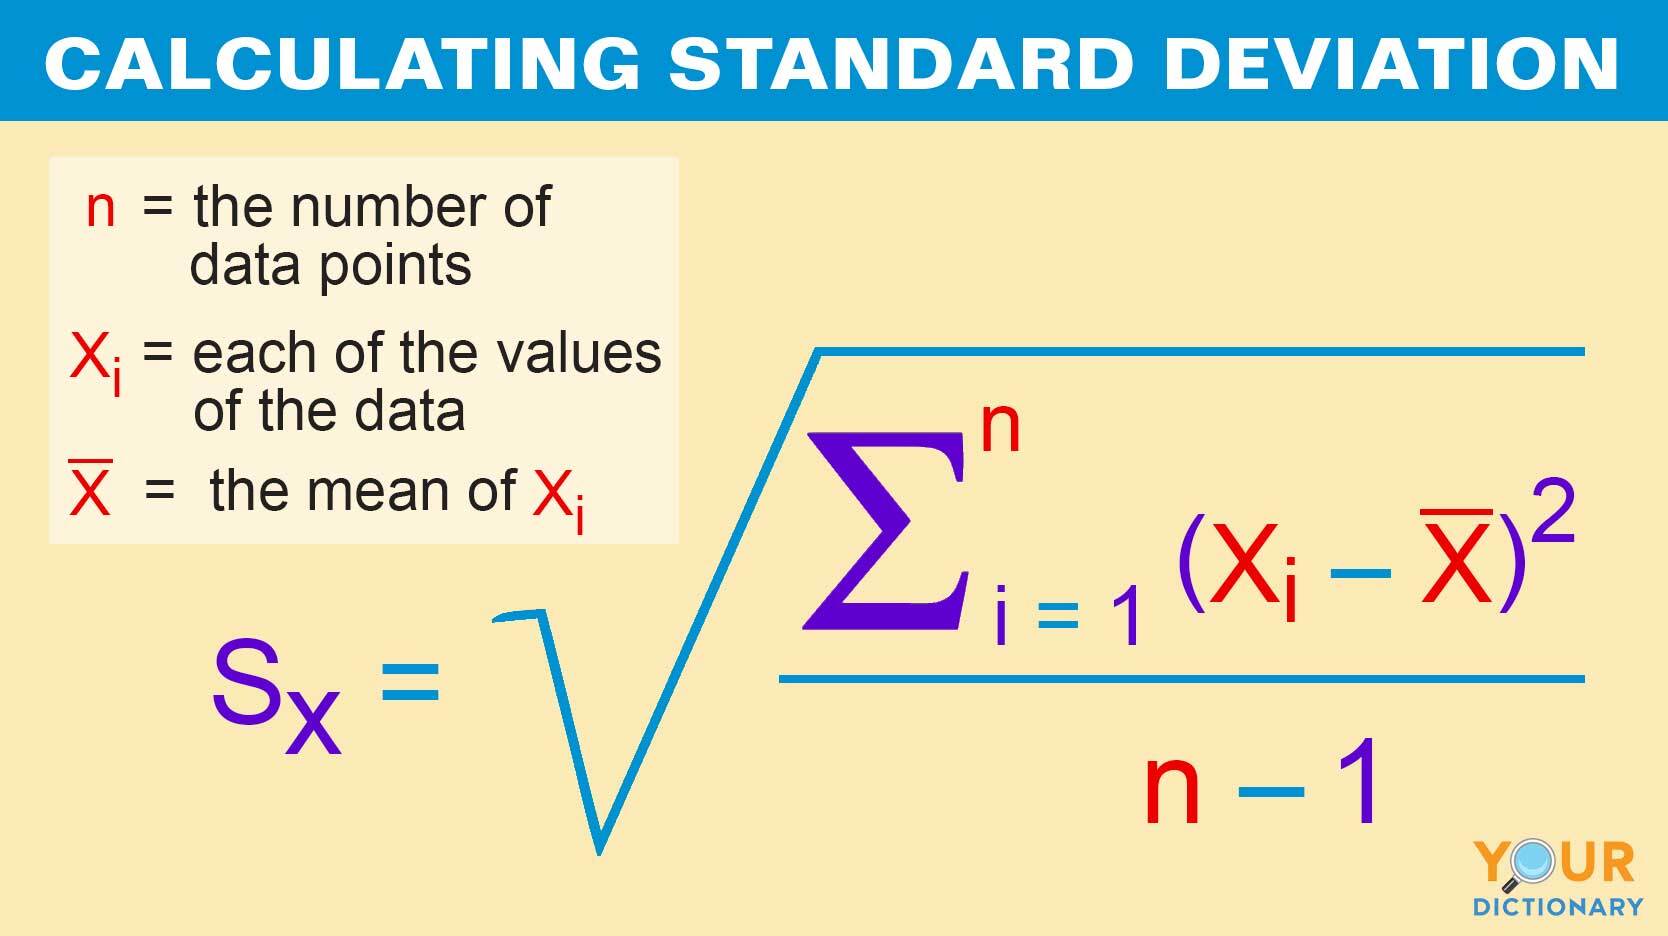
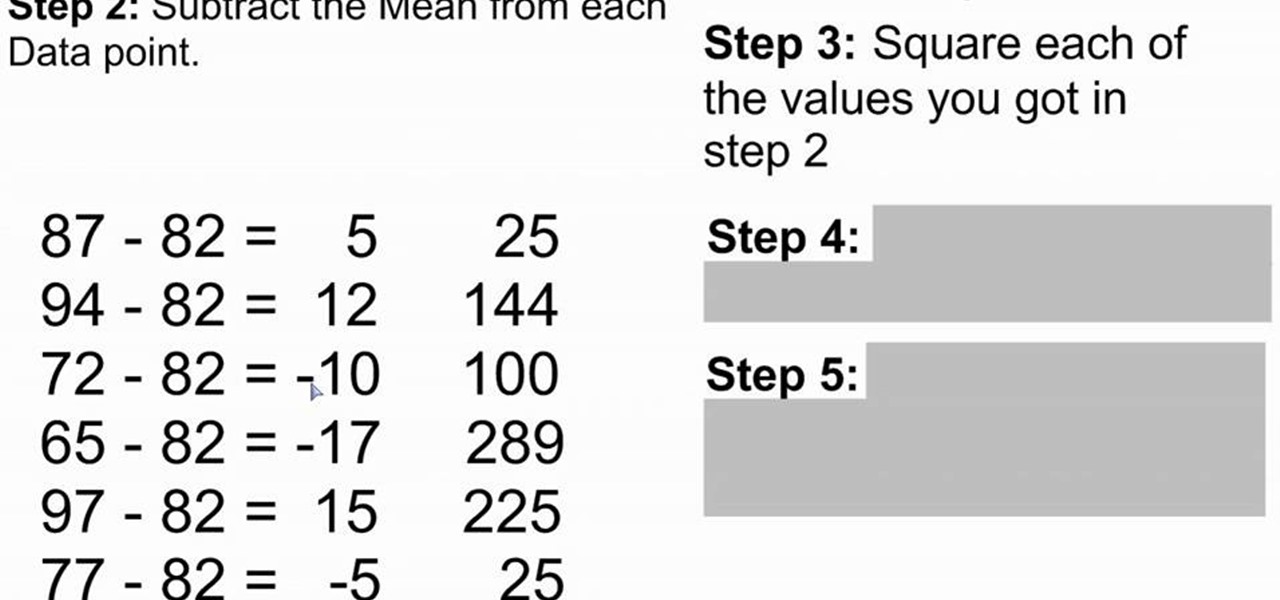
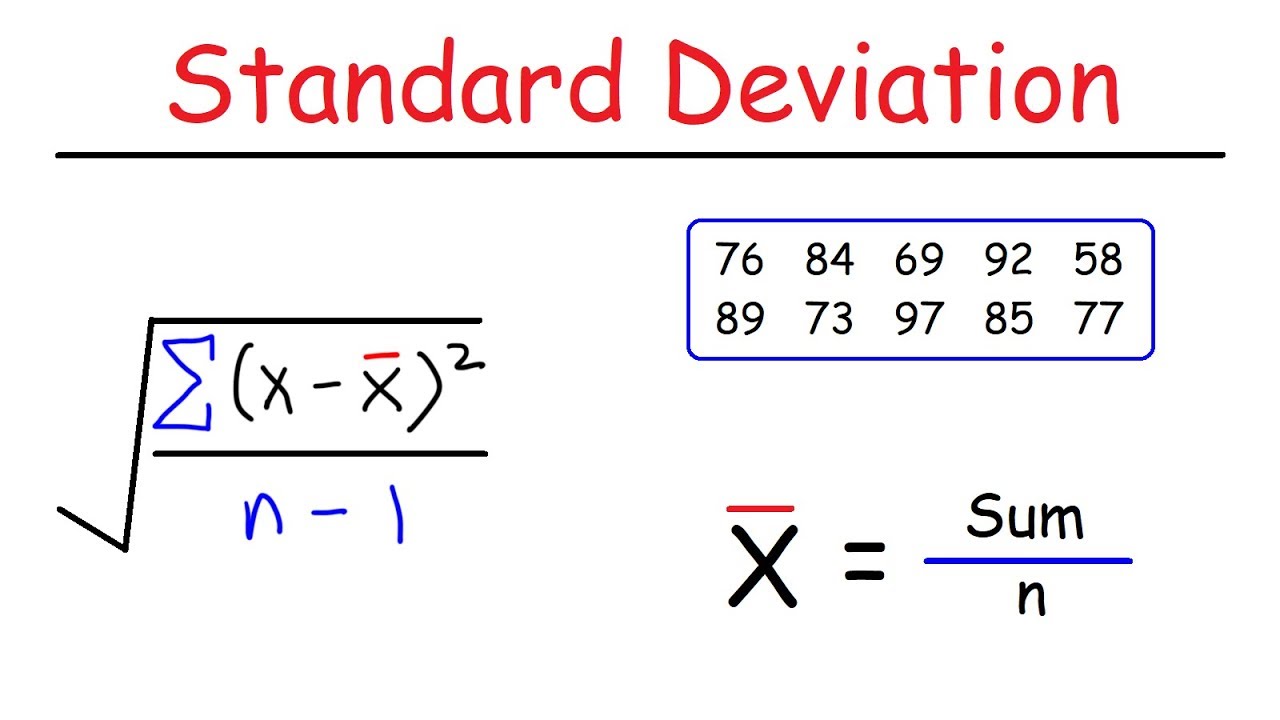
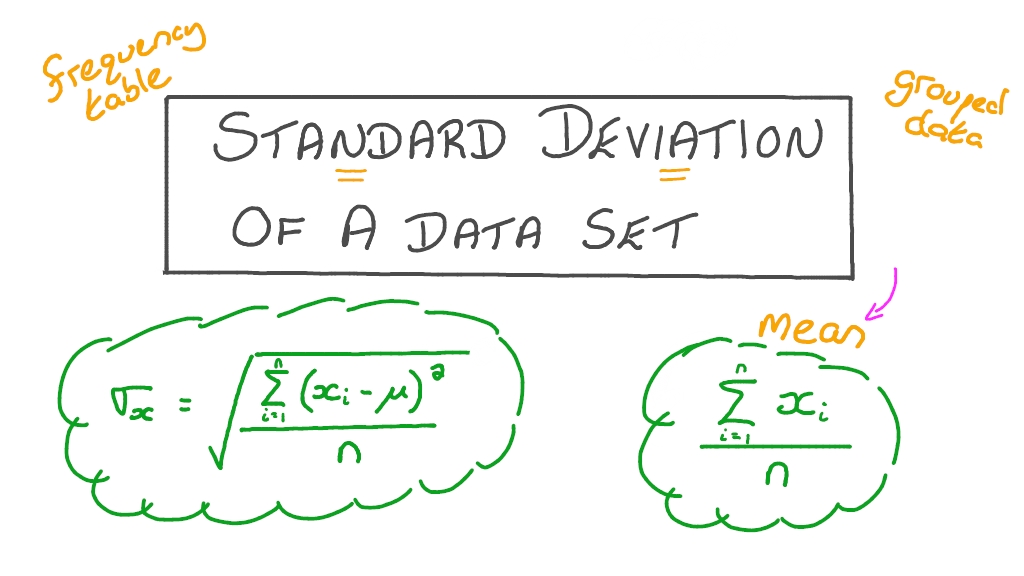
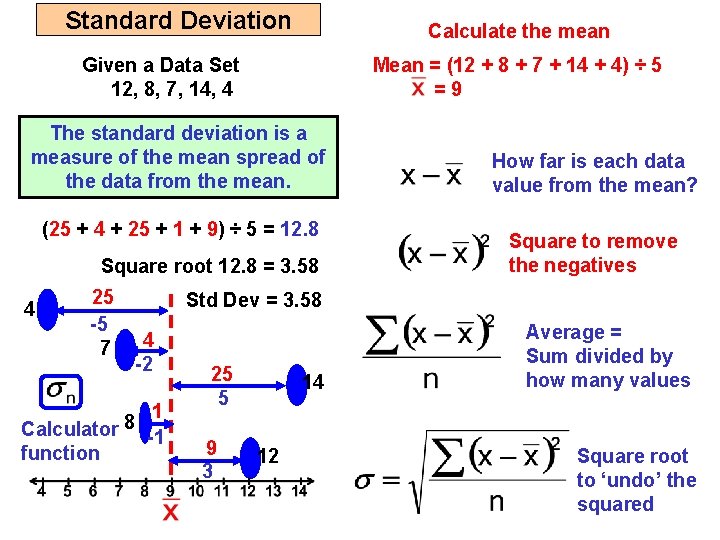
Standard deviation tells you how spread out your data actually is. It sounds simple enough, but most people who need to calculate it are coming from spreadsheets or basic stats classes and they have no idea what's happening under the hood until something goes wrong. I spent three years cleaning messy operational data before I learned to do this by hand without second-guessing myself. The actual process is straightforward once you've seen it done correctly. You start with a data set—could be daily server response times, could be defect counts across production batches, doesn't matter. You need the mean first. Add every value together, divide by how many values you have. That gives you the central point. From there, each individual data point gets subtracted from that mean. You square each of those differences so negative and positive deviations don't cancel each other out. Add up all those squared values. Divide by the count—if you're working with a full population—by N minus one if it's a sample. Take the square root. That's your standard deviation.
How To Find Standard Deviation Of Data Set
Here's what that looks like in practice. Say you have these five numbers: 12, 15, 14, 10, 17. The mean is 13.6. The differences are negative 1.6, positive 1.4, positive 0.4, negative 3.6, and positive 3.4. Squared, those become 2.56, 1.96, 0.16, 12.96, and 11.56. Summed, that's 29.2. Divide by five for a population and you get 5.84. Square root of 5.84 comes out to about 2.42. That's your standard deviation. If this were a sample instead, you'd divide by four and the result would be roughly 2.41. The difference is tiny here but it compounds fast with larger data sets. I ran into a specific problem a while back where I was calculating standard deviation on a data set that looked normal at first glance—about two hundred temperature readings from a manufacturing line. The numbers seemed clustered nicely around the mean. When I computed the standard deviation by hand, I got a value that felt way too low for the spread I was seeing in the raw data. I double-checked my arithmetic three times. The mean was correct. The squaring was correct. Then I realized the issue: I had accidentally included some outlier calibration records in the data set that were over three hundred degrees, which was throwing off the mean enough to make the rest of the cluster look artificially tight. The fix was straightforward—I filtered out anything beyond three standard deviations from the mean after an initial pass, recalculated, and got a result that matched what the distribution actually looked like. The key thing most people miss is understanding when to use population standard deviation versus sample standard deviation. This isn't just academic. If you're analyzing an entire year of sensor readings from a machine, that's a population. If you're looking at forty-eight hours of readings and treating them as a representative slice of the machine's total behavior, that's a sample. The formula changes by exactly one divisor. Using the wrong one can shift your result enough to affect decisions about whether a process is in control or not.
Working Through A Real Example
Let me walk through a slightly bigger example because the small one makes it look easier than it actually is. Take this data set of customer service wait times in minutes: 3, 7, 5, 12, 8, 4, 9, 6. The mean is six. The squared differences are nine, one, one, thirty-six, four, four, nine, zero. Sum is sixty-four. Population standard deviation is the square root of eight, which is approximately 2.83 minutes. Sample standard deviation is the square root of eight pointfive, approximately 2.92 minutes. What matters more than the calculation itself is what the number tells you. With a mean of six and a standard deviation of roughly three, you know most of your wait times fall between three and nine minutes. Any individual call outside that range is worth investigating. Standard deviation gives you a practical boundary without needing to look at every single data point. There's a common pitfall that catches people regularly, especially in business contexts where data is messy. If your data set has extreme outliers, standard deviation becomes less useful because it squares the deviations, which amplifies the influence of outliers. A single garbage value can inflate your standard deviation so much that it becomes meaningless for practical decision-making. In those cases, the interquartile range or median absolute deviation gives you a more stable measure of spread. I've seen teams rely on standard deviation to claim a process was stable when the reality was that one bad week was masking consistent variation the rest of the time.
Get the Full Details
Another nuance people don't usually consider is that standard deviation assumes your data follows an approximately normal distribution to be fully interpretable. If your data is heavily skewed—say, income data or website bounce rates with a long tail—standard deviation alone doesn't tell the whole story. You should pair it with a histogram or box plot before making any conclusions. The number itself is still mathematically valid, but interpreting it requires knowing the shape of the distribution behind it. For anyone doing this repeatedly, Excel or Google Sheets will compute it in a fraction of a second. The formula is either STDEV.P for population or STDEV.S for sample. You select the range and you're done. But relying solely on the tool without understanding the calculation means you won't catch errors when they happen. I've seen the same outlier problem I described earlier go unnoticed for months because someone trusted the spreadsheet output without sanity-checking the result against the raw numbers.
When Standard Deviation Falls Short
The honest limitation is that standard deviation measures linear spread. It works well for symmetric distributions but struggles with anything bimodal or heavily skewed. If you have two distinct groups in your data that standard deviation will smooth over and give you a number that doesn't represent either group accurately. In those situations, you need to segment the data first or switch to a different dispersion metric entirely. Also worth noting: standard deviation is in the same units as your original data, which is convenient for interpretation but doesn't help when you need to compare variability across data sets measured in different units. For that, you'd use the coefficient of variation, which divides the standard deviation by the mean and gives you a dimensionless ratio. The calculation itself isn't hard. What takes experience is knowing when the result is trustworthy and when something else is needed instead. Most of the mistakes I've seen aren't arithmetic errors—they're using standard deviation in situations where it doesn't apply or ignoring the distribution shape that the number depends on.