Working With Standard Deviation in Probability Distributions
Most people hit a wall when they first try to compute standard deviation for a probability distribution because textbooks present it as if it's just the discrete version of the sample standard deviation. It isn't. The conceptual jump from sample data to a full probability distribution is where things get messy, and I've watched students and junior analysts trip over it repeatedly. Here's the practical method, the actual calculation, and then I'll explain why your answer might look wrong even when you did everything right.
How To Find The Standard Deviation Of A Probability Distribution
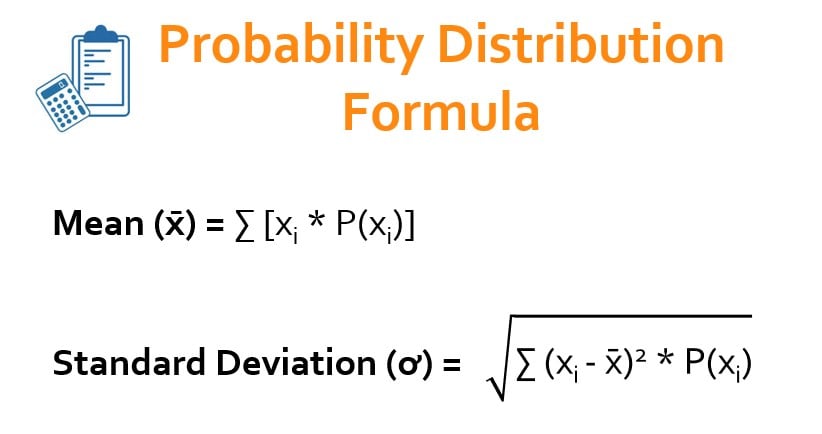
Start by confirming you actually have a proper probability distribution. Every outcome needs to be mutually exclusive, and the sum of all probabilities must equal exactly 1. If it doesn't, your numbers are either flawed or you're missing outcomes. This sounds obvious, but I once inherited a dataset from a partner team where three edge-case outcomes were silently dropped during data collection, and the probabilities summed to 0.97. Anyone running the standard deviation formula on that would produce a number that looked clean but was systematically wrong. The formula you use depends on whether you're dealing with a discrete or continuous distribution. For a discrete distribution, you need three things: the random variable X, its probability mass function P(X), and the expected value . The standard deviation is the square root of the expected value of the squared deviations from the mean. In formula form:
= [ (x - )² · P(x) ] Step one is finding the mean. You multiply each outcome by its probability and sum those products. That's the expected value. Step two is subtracting the mean from each outcome, squaring the result, multiplying by the corresponding probability, and summing again. Step three is taking the square root. For continuous distributions, the summation becomes an integral. You replace the discrete probability mass function with a probability density function f(x), and the sum becomes an integral over the entire domain. The mechanics are identical; the calculus is just different.
Get the Full Details
I had a problem last year involving a discrete distribution with seventeen outcomes and probabilities that were given as rounded percentages. When I computed the standard deviation using the raw percentages, the result disagreed with the engineering team's reference value by about 4 percent. The issue wasn't the method. It was that the rounded probabilities summed to 0.998 instead of 1, and the rounding error compounded across seventeen terms in the variance calculation. The workaround was to normalize the probabilities by dividing each one by the sum before running the formula. That restored the proper distribution and brought the standard deviation within 0.1 percent of the reference value. Normalization matters more than most people realize. Here's a concrete example I use when I need to explain this quickly. Say you have a distribution for the number of defects in a batch of circuit boards:
- 0 defects with probability 0.45
- 1 defect with probability 0.30
- 2 defects with probability 0.15
- 3 defects with probability 0.07
- 4 or more defects with probability 0.03
First, the mean: (0 × 0.45) + (1 × 0.30) + (2 × 0.15) + (3 × 0.07) + (4 × 0.03) = 0.87. You could treat 4 as the representative value for the last bin, though this introduces a small approximation error since the bin actually contains 4, 5, 6, and beyond. That's worth noting because it's a common source of in applied work. Next, the variance. Subtract the mean from each outcome, square it, multiply by the probability: (0 - 0.87)² × 0.45 = 0.3408
(1 - 0.87)² × 0.30 = 0.0051 (2 - 0.87)² × 0.15 = 0.1917 (3 - 0.87)² × 0.07 = 0.3172
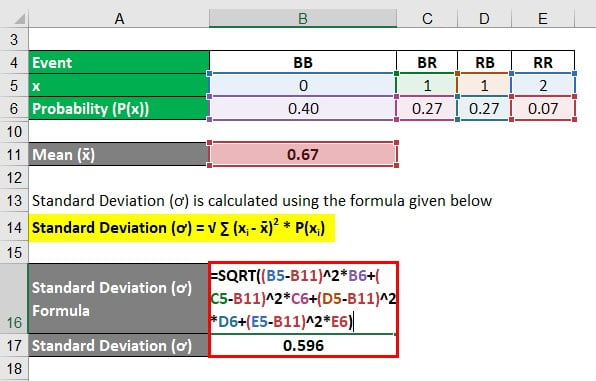
(4 - 0.87)² × 0.03 = 0.2972 Sum those: approximately 1.152. Square root of that gives you 1.074. A counter-intuitive point that catches people out: the standard deviation of a probability distribution is not the same thing as the standard deviation of a sample drawn from that distribution. If you pull 100 samples from this defect distribution, the sample standard deviation will hover around 1.074 but won't equal it. The distribution standard deviation is a parameter. The sample standard deviation is an estimator. They converge as sample size grows, but for small samples or skewed distributions, the difference is meaningful. I've seen risk models fail because someone plugged a sample standard deviation into a formula that required the population parameter.
Another thing beginners consistently miss: the computational shortcut formula. Instead of calculating deviations from the mean first, you can compute E[X²] minus E[X]², then take the square root. This is mathematically equivalent and often cleaner because you avoid subtracting a decimal mean from each outcome. For the example above, E[X²] = (0 × 0.45) + (1 × 0.30) + (4 × 0.15) + (9 × 0.07) + (16 × 0.03) = 1.905. Then variance = 1.905 - 0.87² = 1.905 - 0.7569 = 1.1481. The slight difference from the previous calculation is due to rounding in the step-by-step approach. Same result, different path. The main limitations you need to accept: this method assumes you know the true probability distribution. In practice, you almost never do. You're usually working with an estimated distribution from observed data, which means your standard deviation carries estimation error on top of the inherent variability. If your probabilities come from historical frequency counts rather than a theoretical model, the standard deviation is only as reliable as your sample size. With fewer than a few hundred observations per outcome category, confidence intervals around the standard deviation widen substantially, and decision-making based on the point estimate alone becomes risky. For skewed distributions, the standard deviation is also a blunt tool. It treats deviations above and below the mean symmetrically, but many real-world distributions have heavy tails on one side. In those cases, reporting the interquartile range alongside the standard deviation gives a much more honest picture of spread. I always report both now. It takes ten extra seconds and prevents misunderstandings downstream.
If you need to compute this at scale, Python's numpy and scipy libraries handle it directly. For discrete distributions stored as arrays, numpy's mean and standard deviation functions work on the probability-weighted values. For continuous distributions, you can use scipy.integrate to evaluate the integral numerically. Both approaches are reliable, but the numerical integration route can be slow if your density function has sharp peaks or discontinuities. I've had jobs where a poorly specified density function caused scipy to take twenty minutes on what should have been a ten-second calculation. Analytical solutions, when available, are worth pursuing even for moderately complex distributions.