The Inverse of a Matrix Doesn't Need to Be a Mystery
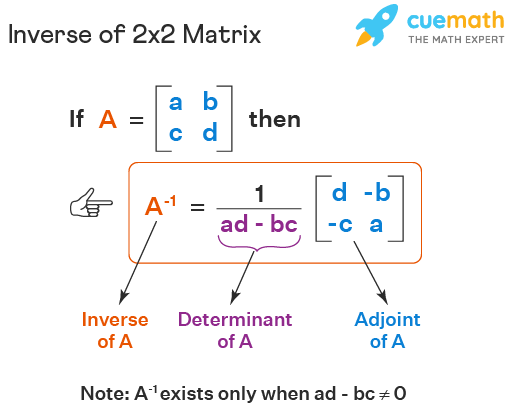
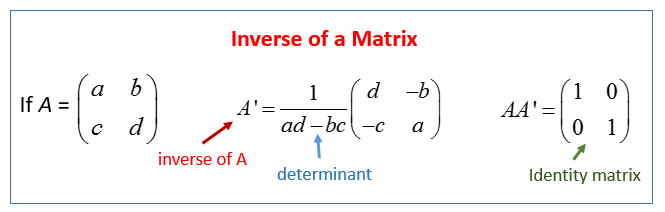
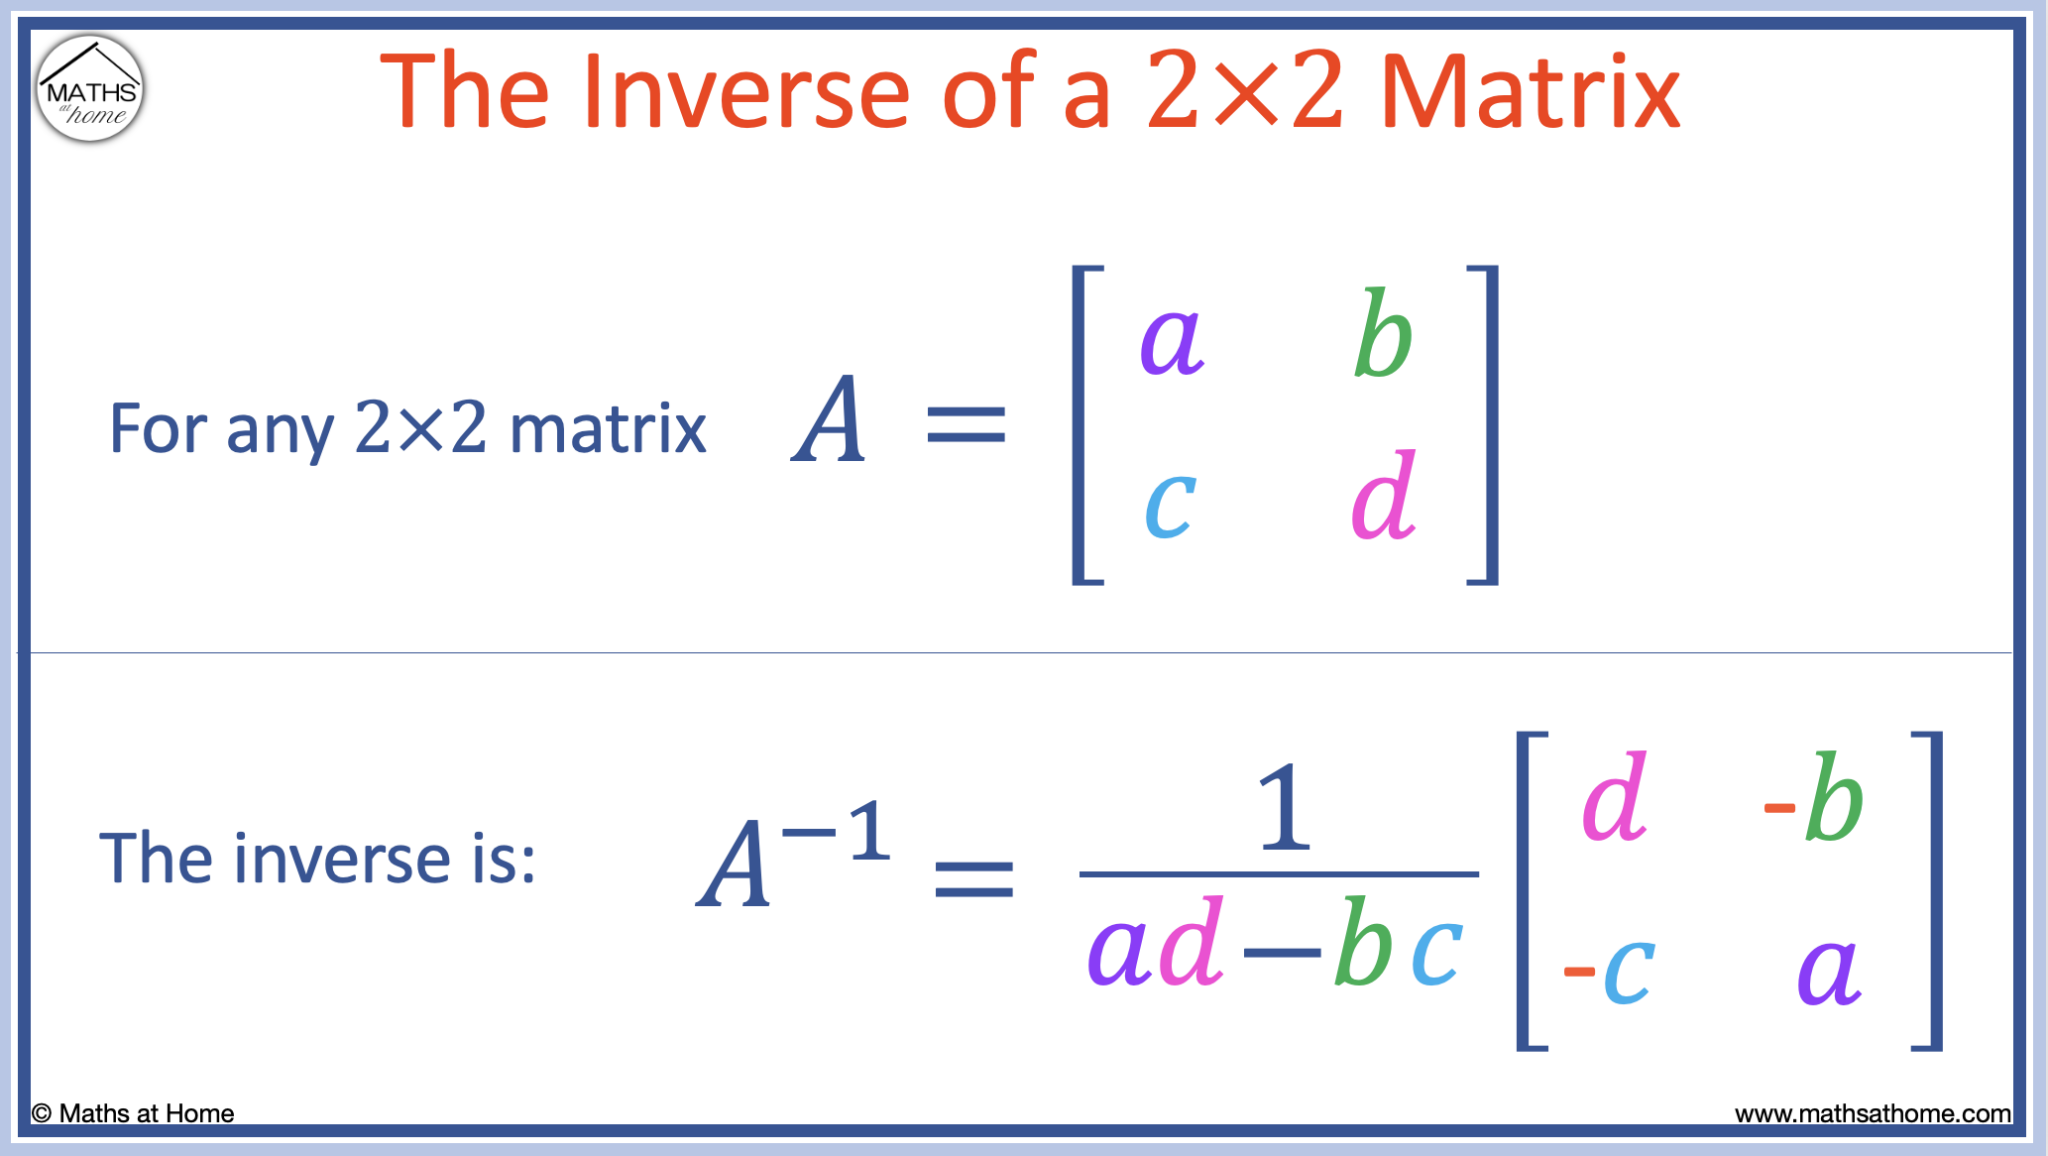
Most people learn matrix inversion through the adjugate-over-determinant formula, which looks elegant until you actually try to use it on anything bigger than a 2x2. I ran into that wall early in my career when someone asked me to invert a 6x6 transformation matrix by hand during a coordinate geometry project. I spent about 90 minutes with cofactor expansions and then realized I'd already made two arithmetic mistakes. I just switched to row reduction and finished in twenty minutes. There are essentially three practical approaches you will encounter in real work, and they each have a different failure mode. The first is Gauss-Jordan elimination. You set up an augmented matrix with your original matrix on the left and the identity matrix on the right, then row reduce the left side until it becomes the identity. Whatever ends up on the right side is your inverse. It is O(n^3) in computational cost, which is the same order as most useful matrix operations, so it is not a magic bullet but it is reliable for moderate sizes. The second approach is the adjugate method, which involves computing the determinant and the cofactor matrix. It works fine for 2x2 and 3x3 systems, and occasionally for symbolic calculations where you need a closed-form expression. For anything 4x4 and larger it becomes exponentially tedious, and the determinant calculation itself is numerically unstable if your matrix entries span several orders of magnitude. I almost never use this in practice except as a sanity check on paper.
The third is the LU decomposition route, which is what most numerical libraries actually use under the hood. You factor your matrix into a lower triangular matrix and an upper triangular matrix, then solve two triangular systems instead of inverting directly. This is the standard approach in production code because it is faster, more numerically stable, and it avoids computing an explicit inverse when you only need to solve linear systems anyway. Which leads to the point most tutorials miss. Explicitly forming the inverse is usually the wrong thing to do. If your actual goal is to solve Ax = b, you should use a solver that works with the factorization rather than computing A^-1 first. Multiplying the inverse by b introduces additional roundoff error and costs more operations than a direct solve. I have seen engineers waste hours debugging precision issues in finite element meshes because someone computed an inverse explicitly before multiplying by a load vector. The fix was switching to a LAPACK routine and re-running the pipeline with conditional scaling enabled.
Edge Cases That Will Break Your Code
A singular matrix has no inverse, obviously, but detecting singularity numerically is not as simple as checking whether the determinant equals zero. Consider a matrix where the condition number is around 10^15. The determinant might be nonzero and your software will happily return an inverse, but that inverse will be dominated by numerical noise. I worked on a robotics calibration task last year where the sensor fusion matrix was technically invertible but produced wildly different joint corrections depending on floating-point precision settings. The workaround was checking the condition number with a singular value decomposition before proceeding, and falling back to a least-squares pseudoinverse when the condition number exceeded 1e12. Another issue that comes up constantly is that your matrix might not be square. Non-square matrices do not have inverses in the traditional sense, but they do have left or right pseudoinverses. The Moore-Penrose pseudoinverse handles this cleanly through SVD and it degrades gracefully when the matrix is rank-deficient. I once inherited a signal processing pipeline that crashed whenever a microphone array had one dead channel because the covariance matrix dropped rank and the old code tried to invert it directly. Rewriting that section with a pseudoinverse computed via truncated SVD eliminated the crash and actually improved the output quality since it implicitly filtered out the noise subspace.
Get the Full Details
What the Textbooks Leave Out
Block matrix inversion is something you will use if you ever work with large structured systems, and it saves enormous time compared to inverting the full matrix from scratch. If you can partition your matrix into blocks where one of those blocks is already factored or known to be well-conditioned, the Schur complement formula lets you invert the whole thing by only inverting the smaller blocks. I use this routinely in model predictive control code where the KKT system has a sparse block structure. A full invert would be cubic in the horizon length, but the block approach reduces it to something closer to quadratic for typical horizons. There is also the Woodbury matrix identity, which is basically the block inversion formula dressed up for updates. If you have an existing inverse and your matrix changes by a low-rank update, Woodbury lets you refresh the inverse without recomputing from scratch. It costs O(n^2 k) where k is the rank of the update, compared to O(n^3) for a full recomputation. I use this in Kalman filter implementations where the measurement update is a rank-one modification to the information matrix. Going from an hour-long batch computation to a few milliseconds per update step was the difference between real-time operation and a prototype that only worked offline. If you need to implement this yourself, start with a basic Gauss-Jordan for small educational cases, then move to an LU-based solver for production work. Python users can call numpy.linalg.solve instead of numpy.linalg.inv whenever possible. MATLAB has the same advice baked into its documentation, though they also ship the backslash operator which picks the best factorization automatically based on matrix properties. For anything that needs to run on constrained hardware, consider whether a fixed-point iterative method like the Schulz iteration might be more appropriate, though convergence is not guaranteed without careful preconditioning.