Learning Data Science: What I Wish I Knew Before Wasting Two Years
I spent 2019 trying to learn data science the way everyone said you should. Watched three Python courses, bought the O'Reilly books, set up Jupyter notebooks on my laptop that crashed whenever I loaded anything bigger than a CSV. By month four I had a GitHub full of unpolished projects nobody would hire me for. The actual path is uglier and more boring than the Medium articles make it look. You don't need another TensorFlow tutorial. You need to understand what happens when your training data doesn't match your production data, which is something nobody tells you until you've deployed a model that performed 94% accuracy in testing and 61% in the wild.
How To Learn Data Science Reddit
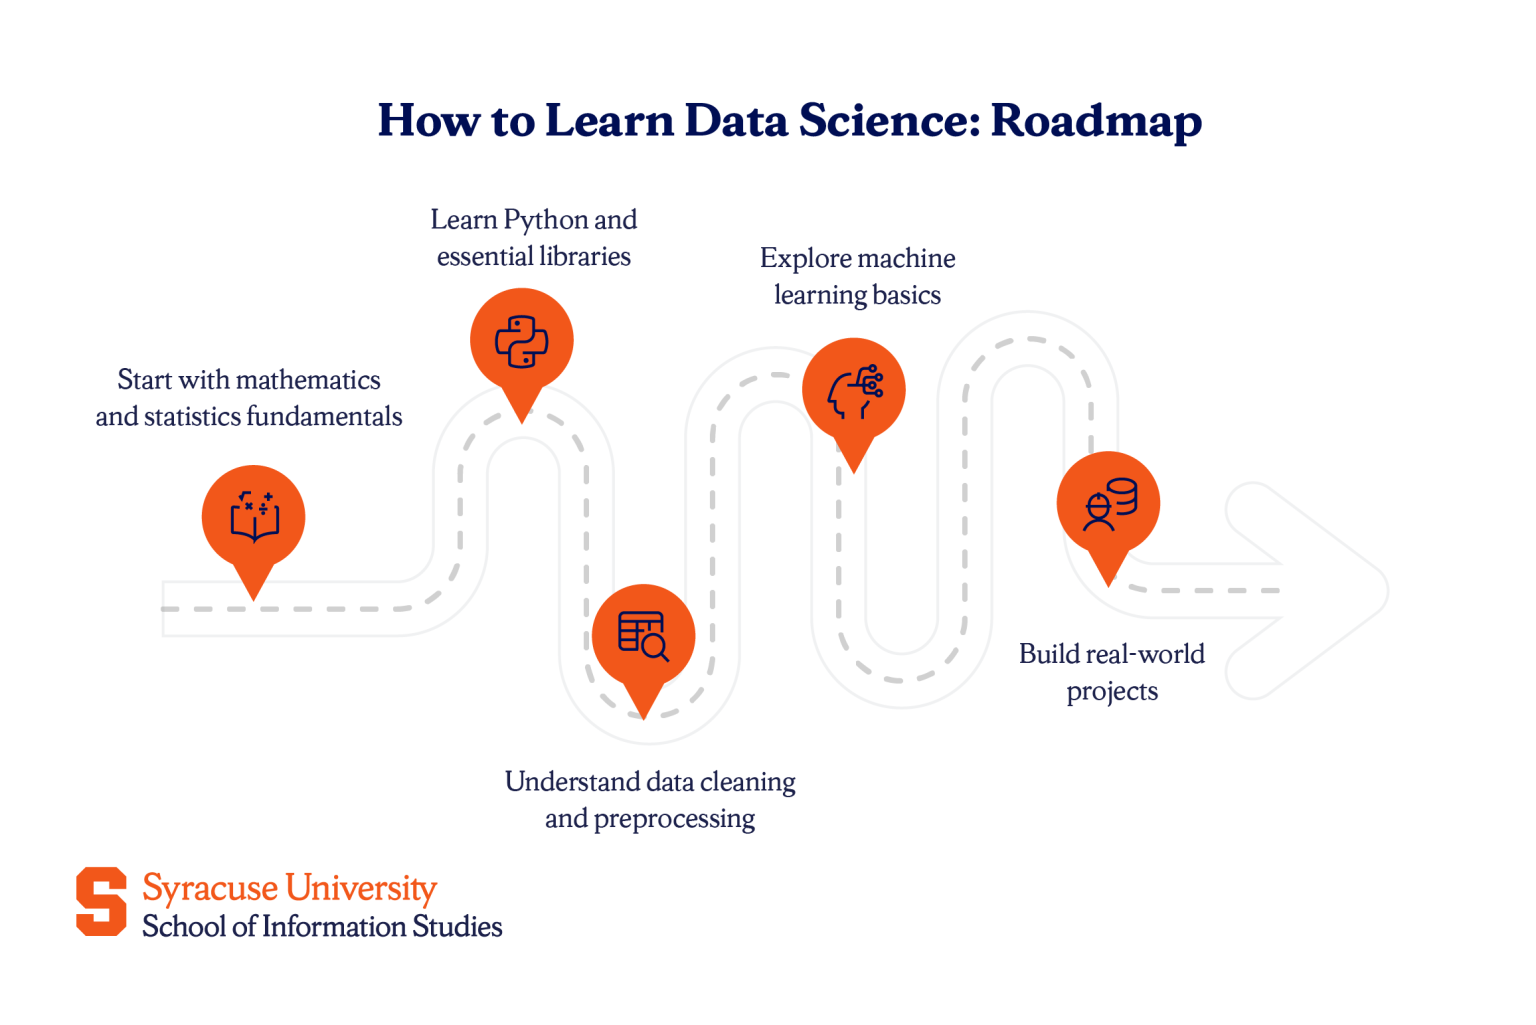
If you search How To Learn Data Science Reddit, you'll find the usual advice: Python, SQL, statistics, then pick a library and build a portfolio. The comments will tell you Kaggle competitions matter more than degrees, that you should contribute to open source, that machine learning engineering is just software engineering with math attached. Most of it is correct. None of it is complete. Here's what the top posts won't tell you. The mathematical foundations matter less than you think until you're debugging why your gradient descent isn't converging, and then suddenly you care about learning rate schedules and whether your loss landscape is convex. The coding skills matter less than you think until you're spending three days fixing an off-by-one error in your data pipeline that nobody else can find because they don't understand the domain. I learned this the hard way. In 2021 I built a customer churn model that took six weeks to develop. Feature engineering alone ate two of those weeks. The model hit 89% AUC on the validation set. We deployed it to production on a Tuesday. By Wednesday morning the business team called because the predictions were backwards. Not wrong. Backwards. Turns out I'd trained on customers who left and called them "1", but the API expected the opposite encoding. Two hours. Two weeks wasted. I learned to validate every assumption about label encoding before connecting any upstream systems.
That's the actual work. Not the theory. The assumptions you make when nobody's watching.
Get the Full Details
The Skills That Actually Matter
Python is table stakes. Everyone knows Python. What separates people who get hired from people who don't is whether they can take a messy business requirement and translate it into a data pipeline that doesn't break when the schema changes. This usually means SQL, not because SQL is magical, but because the data lives in a relational database and your model runs in production where the data engineers have already made their choices about normalization and partitioning. Statistics matters more than most bootcamps teach it. Not the hypothesis testing stuff from your introductory course, but the practical understanding of bias-variance tradeoffs, confidence intervals, and when "statistically significant" actually means something in your context versus when it's just noise that happened to pass your p-value threshold. I can't count how many models I've seen ship because someone ran a t-test and got p
0.05 without checking whether the effect size was practically meaningful. Machine learning libraries are tools, not skills. Scikit-learn, XGBoost, PyTorch — these change every eighteen months. The underlying concepts don't. Understanding what a random forest actually does at the ensemble level matters more than knowing the exact syntax for GridSearchCV. When your hyperparameter tuning takes six hours and gives you 0.3% improvement over the baseline, you'll wish you'd spent that time understanding the feature interactions instead.
The Portfolio Problem
Kaggle competitions look good on resumes until you realize they optimize for leaderboard performance, not business impact. The winner of a recent fraud detection competition had 99% precision on the test set, but when they deployed to production the false positive rate destroyed the operations team's workflow because the threshold was calibrated for maximum F1 score, not for the cost of investigating legitimate transactions. Your portfolio should show you can handle the messiness of real data. Not clean CSV files from a competition. Real data with missing values that aren't missing at random, timestamps that cross timezone boundaries, categorical features that change encoding between environments. I've hired people who could recite the architecture of a Transformer but couldn't write a SQL query that joins three tables without duplicates. Don't be that person. The projects that actually impressed my last hiring committee weren't the fancy deep learning models. They were the ones where someone took a broken Excel spreadsheet, wrote a pipeline to extract and transform the data, and deployed a simple logistic regression that saved the team forty hours a week. Not sexy. Effective.
What Nobody Tells You About the Job
Data science is 80% data engineering and 20% modeling. The 80% isn't glamorous. It's writing scripts to clean data that was entered by humans who don't understand your schema, dealing with legacy systems that export CSV files with inconsistent delimiters, arguing with stakeholders about whether "urgent" really means "before lunch" or whether it can wait until Friday. I learned this in my first role at a fintech startup. My job title was "Data Scientist." My actual work was writing Python scripts to extract transaction data from four different databases, cleaning it, and building dashboards so the risk team could spot suspicious patterns. No deep learning. No NLP. Just SQL and pandas and a lot of meetings about what "suspicious" actually meant in business terms versus what the rules engine had been configured to flag. The modeling comes later, if at all. Sometimes the best model is no model. Sometimes a rule-based system that a business analyst can explain to their boss in five minutes is worth more than a black-box neural network that requires a PhD to justify. I've seen teams ship gradient boosting classifiers that added marginal improvement over a simple threshold rule while burning three sprints on feature engineering nobody could interpret.

The Math You Actually Need
Linear algebra matters when you're implementing your own matrix operations or debugging why your neural network isn't converging. You don't need to derive the backpropagation algorithm by hand, but you should understand what a Jacobian represents and why numerical stability matters when your gradients vanish or explode. I once spent two days tracking down NaN losses in a custom implementation only to discover my learning rate was too high for the weight initialization I'd chosen. Simple fix. Expensive lesson. Probability and statistics matter more than calculus for most day-to-day work. Bayesian reasoning helps you update your beliefs as new data arrives, which is something frequentist hypothesis testing doesn't do elegantly. Understanding distributions matters when you're choosing between a Gaussian likelihood and a Poisson likelihood for your count data. I've seen people fit linear regression to count data and wonder why their predictions went negative, which shouldn't surprise anyone who's seen the support of a Poisson distribution. The math that matters most is the kind you use when you're debugging, not the kind you use when you're building. Knowing how to read a confusion matrix matters more than knowing how to derive the cross-entropy loss. Understanding what precision-recall tradeoffs mean for your specific business case matters more than knowing the exact formula for F-beta score.
Tools and Setup
You don't need a GPU cluster. I trained my first production models on a 2017 MacBook Pro with 16GB RAM. The bottleneck wasn't compute. It was data loading. When your pandas dataframe doesn't fit in memory, you'll discover the value of Dask, Vaex, or just writing your data to disk in chunks. I spent three weeks debugging memory issues only to realize I was loading the entire dataset into a single dataframe when I could have processed it in batches. Your toolchain should be simple. Python, SQL, a version control system, a notebook environment for exploration, and a deployment strategy that doesn't require a DevOps team. I've seen teams spend more time configuring Kubernetes clusters for model serving than they did on the actual modeling. Sometimes a REST API that calls a pickle file is good enough. Often it is. Cloud platforms offer convenience but add complexity. AWS SageMaker, GCP AI Platform, Azure ML — these abstract away infrastructure but introduce their own abstractions that you need to learn. I've found it faster to containerize my models with Docker and deploy them anywhere than to learn each platform's proprietary serving stack. YMMV, depending on your team's expertise and your organization's existing cloud investment.
Common Mistakes
Overfitting to your validation set is the most common mistake I see. Not the technical kind where your model memorizes the test data, but the organizational kind where you optimize for the metric your stakeholders care about without understanding whether that metric actually correlates with business value. I've seen teams hit 99% accuracy on a fraud detection task where fraud was 0.1% of transactions, which meant they were right almost all the time by predicting everything as legitimate. Data leakage is the second most common. Not the obvious kind where your test set leaks into your training set, but the subtle kind where features correlate with your target through a common cause that doesn't exist in production. I spent a week debugging why my model's feature importance ranked "transaction timestamp" as the most predictive feature, only to realize the timestamp correlated with a seasonal pattern that wouldn't exist for new customers. The model was learning history, not causation. Certificate programs and bootcamps promise job placement but deliver diluted curriculum. I've hired bootcamp graduates who could build a neural network but couldn't write a SQL query that handles NULLs correctly. The foundation matters more than the framework. Learn to clean data, write tests, and communicate with stakeholders before you learn to tune hyperparameters.

The Reality of the Work
Data science is applied statistics with a software engineering problem. The statistics part is the hard part. The software engineering part is the tedious part. Both are necessary. I've seen teams ship models that were statistically sound but couldn't be deployed because the code quality didn't meet their engineering standards. I've also seen teams ship maintainable code that was statistically naive because nobody on the team understood basic experimental design. The job varies by company. Startups need generalists who can build pipelines, train models, and present to stakeholders. Large companies have specialized roles: data engineers build the infrastructure, ML engineers deploy the models, data scientists do the analysis. Both structures work. Both have tradeoffs. In startups you'll touch everything and master nothing. In large companies you'll master one thing and barely understand the others. I prefer the startup model, personally. Understanding the full pipeline from data collection to deployment makes you a better data scientist because you know where your assumptions break. When your model fails in production, you want to know whether it's because the training data was biased, the feature engineering introduced leakage, the deployment pipeline corrupted the features, or the stakeholders misinterpreted the predictions. Each failure mode requires different debugging.
Learning Resources That Actually Help
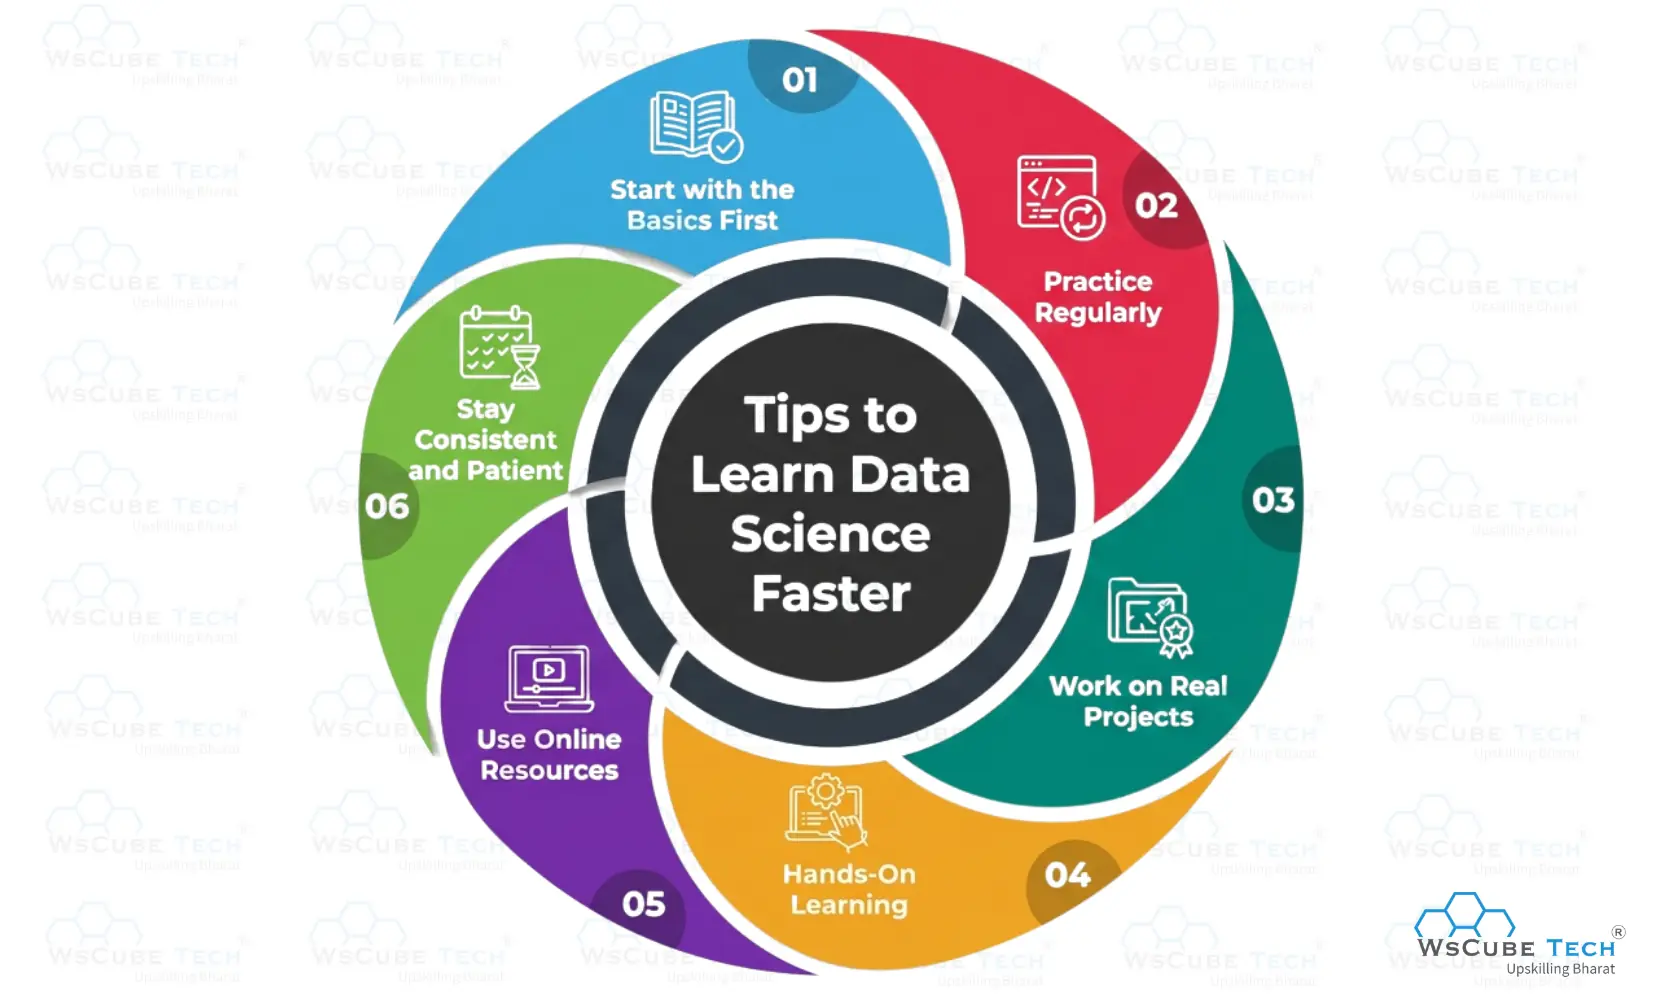
Books matter more than videos. "Elements of Statistical Learning" by Hastie and Tibshirani is dense but definitive. "Pattern Recognition and Machine Learning" by Bishop is mathematically rigorous but accessible if you know the prerequisites. "Python for Data Analysis" by McKinney is practical and current. I've recommended these to junior data scientists for years. The video courses are fine for introduction, but the depth comes from reading and doing, not watching. Practice matters more than certificates. Build projects that solve real problems, not tutorial clones. Clean a messy dataset from your industry. Write a blog post explaining a concept you learned. Contribute to open source. I hired someone once because they fixed a bug in a data processing library and wrote a clear issue report. Not because of their Kaggle rank or their certificate collection. Mentorship matters more than curriculum. Find someone who's done the work you want to do and ask them specific questions. Not "how do I learn data science," but "how did you handle data leakage in your last project?" or "what's your process for validating model performance before deployment?" The answers will be more valuable than any course because they'll be specific to your context, not generic best practices.
When Data Science Isn't the Answer
Sometimes the best solution is no model. A dashboard, a rule-based system, a simple threshold. I've seen teams spend months building gradient boosting classifiers when a SQL query would have solved the problem. Not because the model was wrong, but because the stakeholder didn't need a prediction. They needed visibility into existing data. Other times the problem isn't data science. It's product design, or business strategy, or organizational incentives. I worked on a project where the "churn prediction model" was actually a retention problem caused by poor onboarding. No algorithm could fix that. The data was noisy because the signal was weak, and the weak signal was a product problem, not a modeling problem. Learn to say no. Learn to identify when data science is the right tool versus when it's a solution in search of a problem. This skill matters more than any framework because it saves your team time and preserves your credibility. I've lost respect for data scientists who said yes to every modeling request without questioning whether the problem was actually solvable with data.

The Field Is Changing
LLMs are changing the baseline. Tasks that required custom pipelines five years ago can now be solved with prompt engineering and RAG architectures. This doesn't replace data science. It replaces the tedious parts. Feature extraction, text cleaning, basic classification — these are getting commoditized. The hard parts remain: understanding causality, designing experiments, interpreting results, communicating with stakeholders. I'm not bullish on LLMs replacing data scientists. I am bullish on data scientists who use LLMs being more productive than those who don't. The tool is powerful but narrow. It excels at pattern matching in text, not at causal inference from observational data, not at designing controlled experiments, not at understanding business context. The future belongs to generalists who understand the full stack, not specialists who know one framework deeply. The framework changes every few years. The fundamentals don't. Learn SQL, learn Python, learn statistics, learn to communicate. The rest is tooling.

