Setting Up the Character Matrix
Most people overcomplicate this from the start. The actual work begins long before you open any software. You need a character matrix first, and that means deciding what traits matter and which organisms you're comparing. Pick your taxa carefully. Three to eight species usually keeps things manageable. More than that and you're looking at real data-cleaning time rather than a clean tutorial exercise. Characters are the columns, taxa are the rows. Each cell gets a state value—usually 0 for absent, 1 for present, and sometimes 2 for intermediate. The trick is picking characters that actually vary across your group. If every species has a backbone, that character won't help distinguish anything and you should drop it. I spent two days once trying to resolve relationships between four lichen species using morphological characters. Everything converged on a polytomy because I had only five characters and three of them were synapomorphies shared by all four. Dropped the shared ones, added some spore size measurements, and got a usable tree. Took about forty minutes instead.How To Make A Cladogram: The Practical Steps
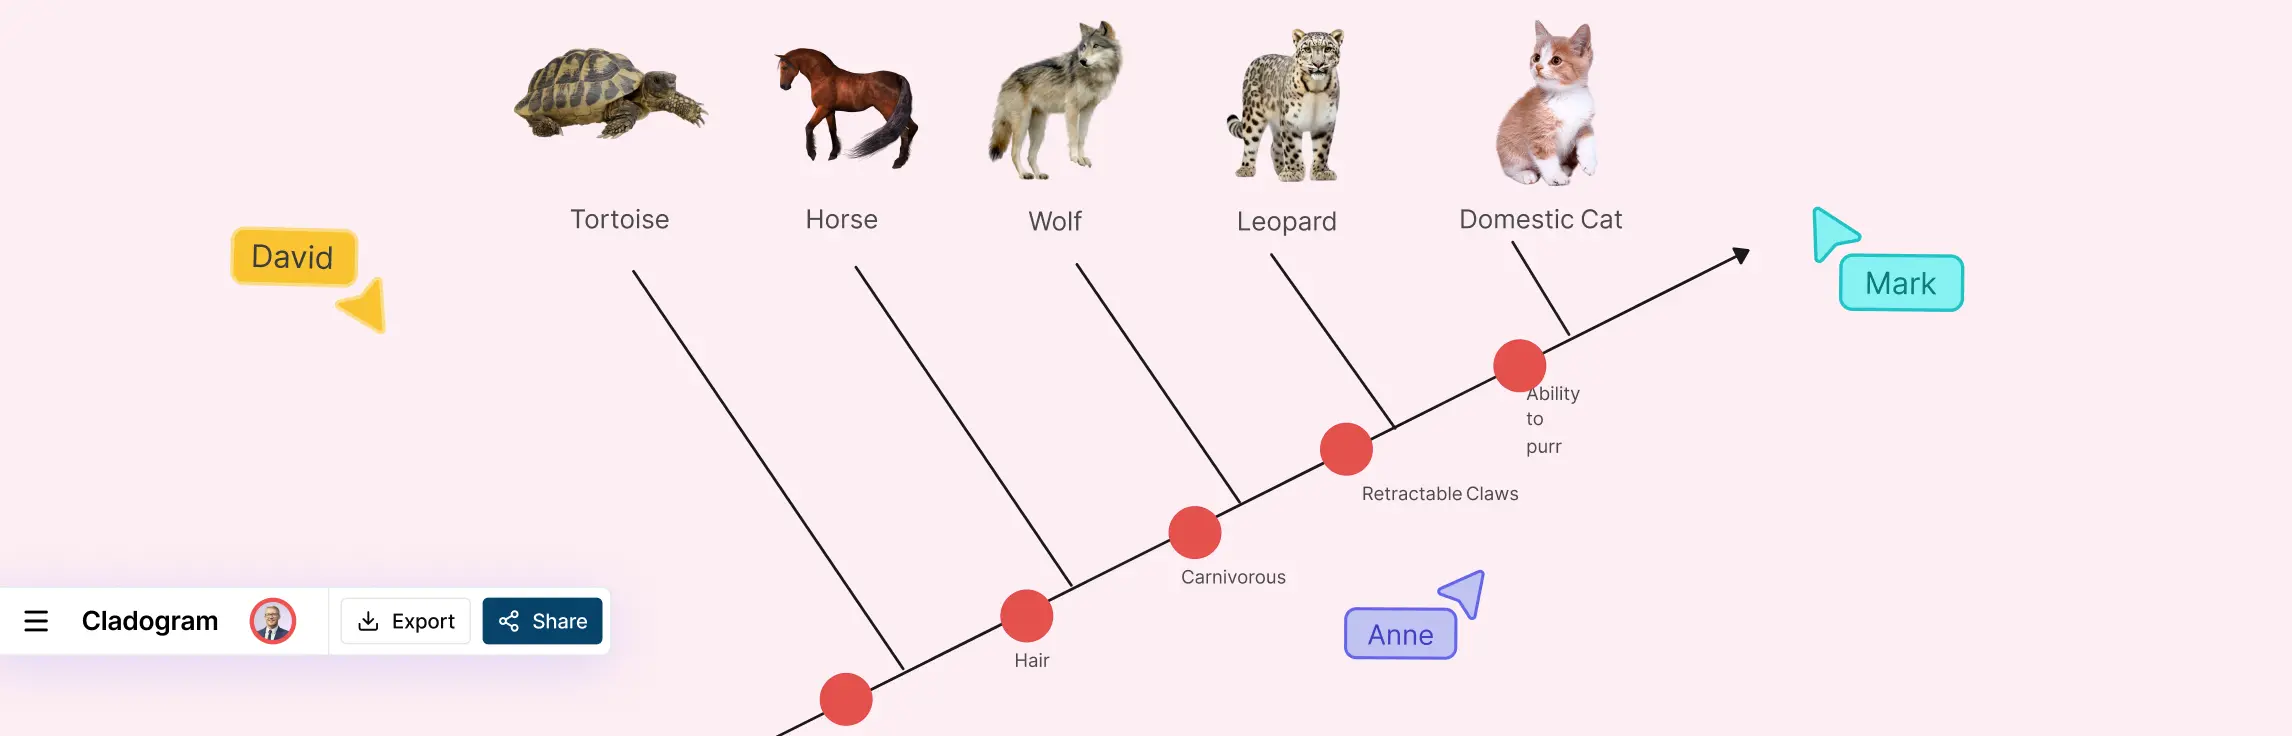
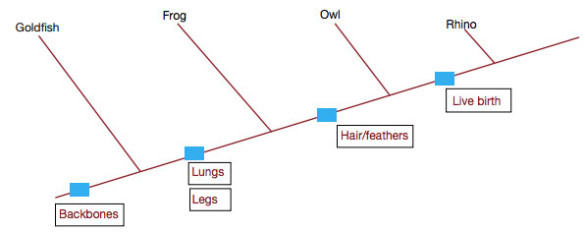
Start by grouping taxa based on shared derived characters, not just shared similarities. That distinction matters more than most introductory courses make it sound. Work through each character one at a time. Look at which species share the same derived state and note where those groupings overlap. The most nested overlaps become your branches. You're essentially building a hierarchy from the ground up. When you have your groupings mapped out, draw the tree. Root it using an outgroup—a species you know falls outside the group you're studying. Without a root, you're just drawing a network, not a cladogram. I see people skip this step constantly. It makes the whole diagram ambiguous about direction of change.
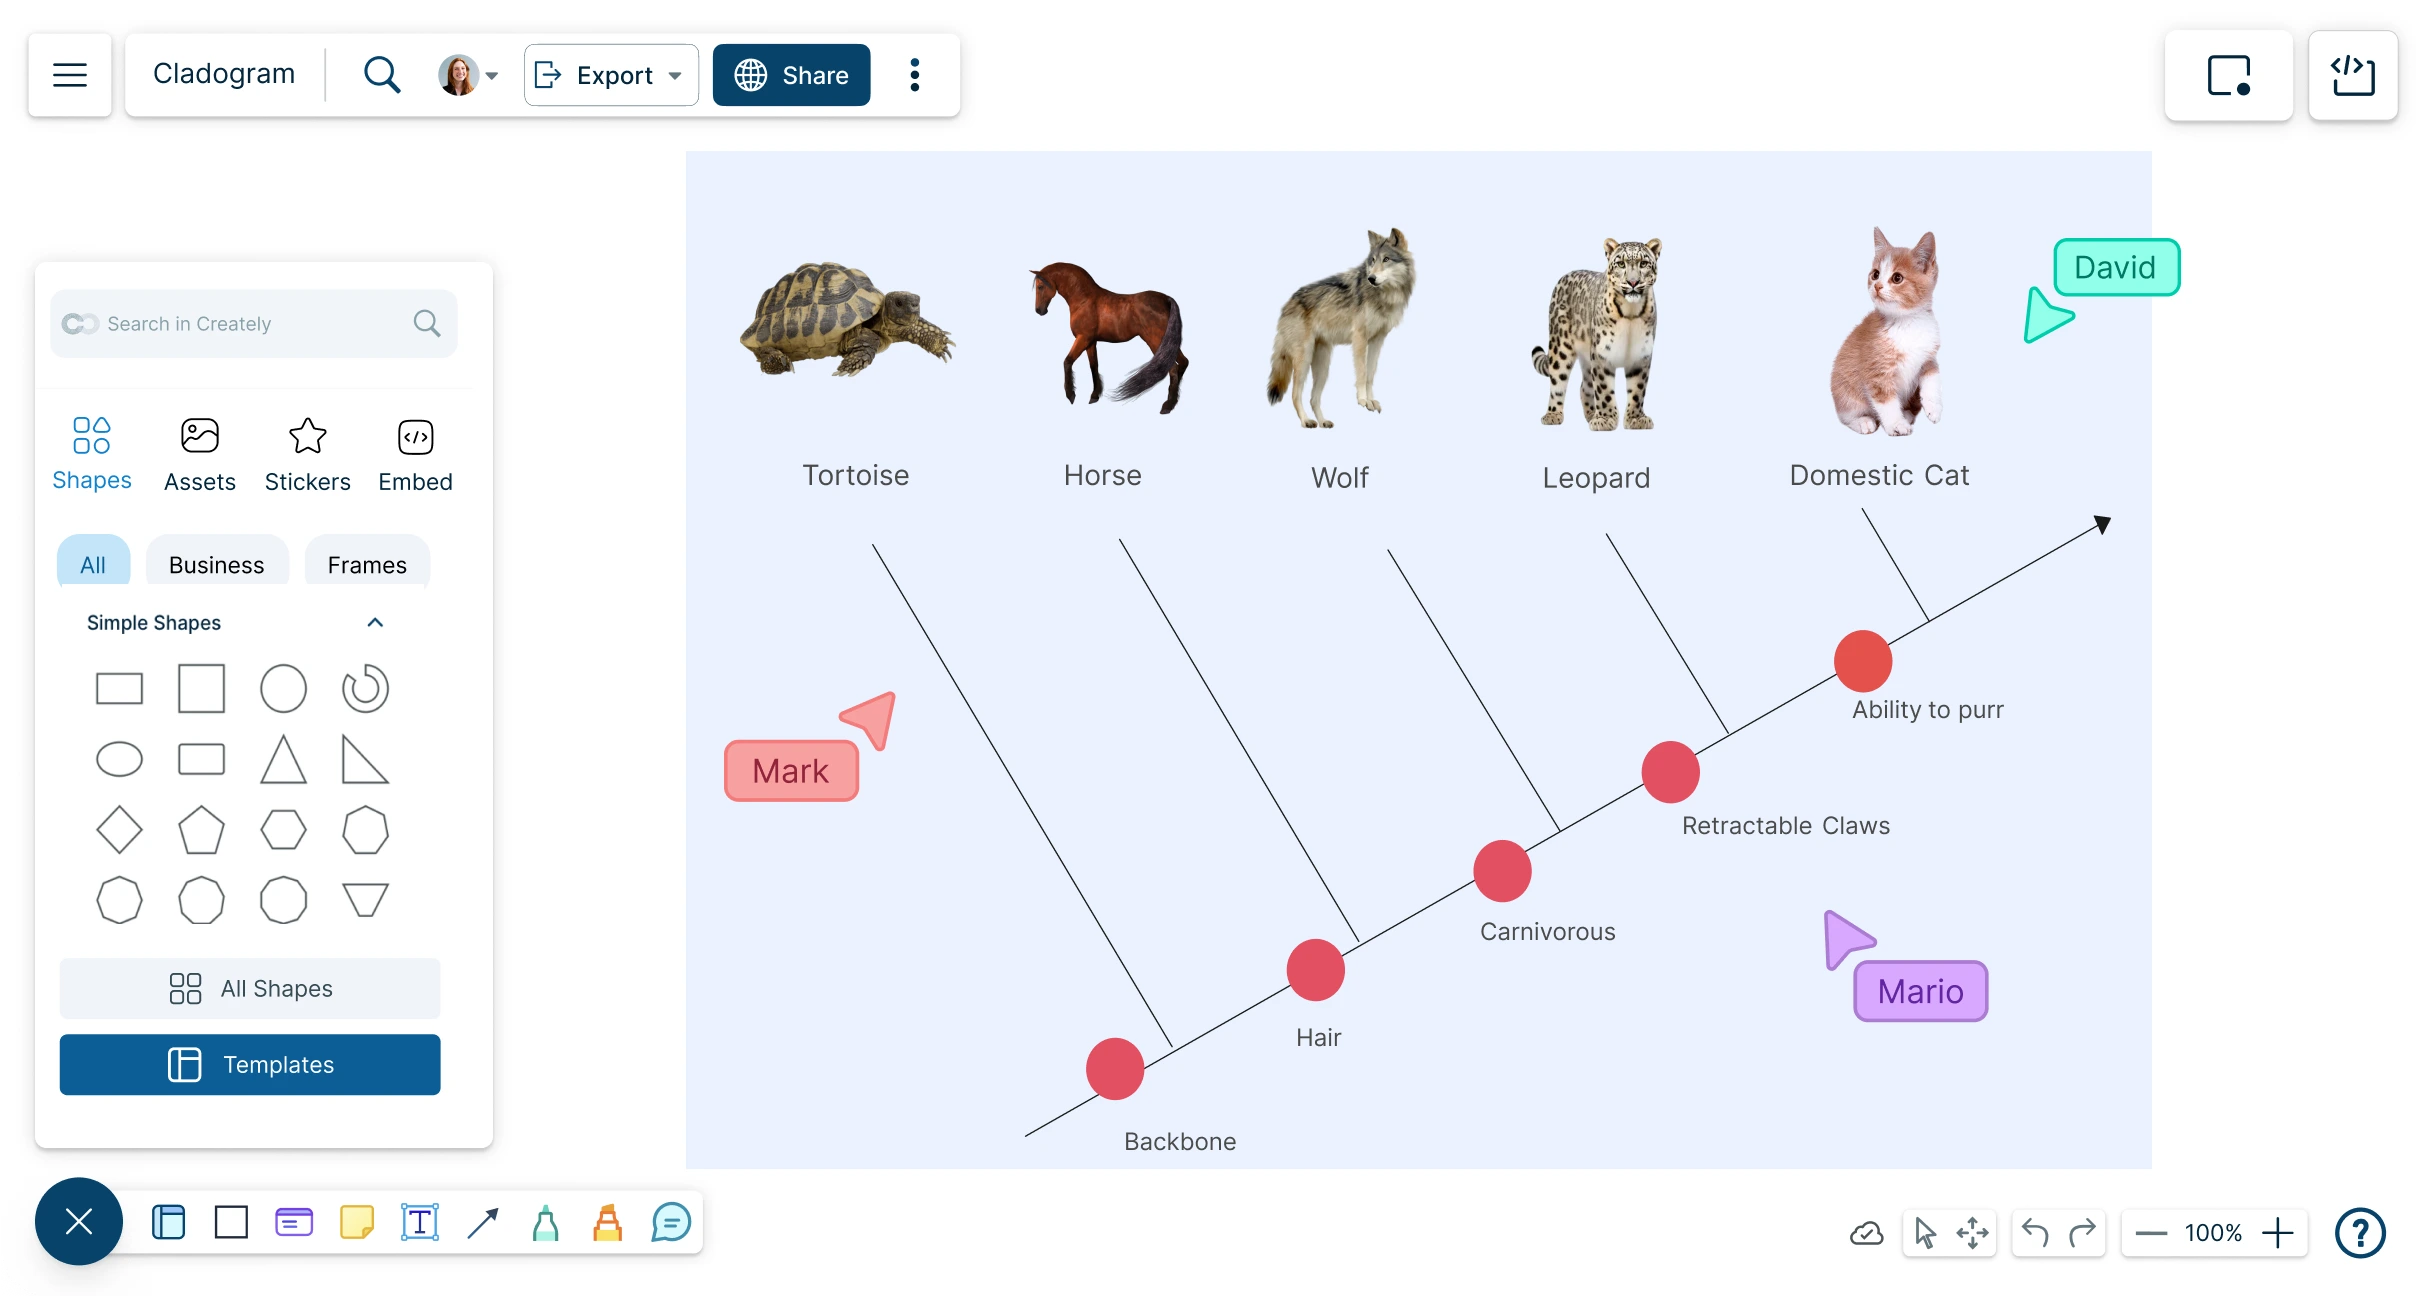
The last part is labeling nodes with the characters that support them. This is where you show your work. Every branch should correspond to at least one synapomorphy. If a node has no character backing it, question whether it belongs there.
Software Options and When to Use Them
For small datasets, a spreadsheet and a piece of paper will get you where you need to go. I still do rough work like this manually because it forces you to understand what you're doing rather than letting software handle the logic for you. When you move past about ten taxa or twenty characters, manual drawing becomes error-prone. Free programs like Mesquite and TNT handle parsimony analysis properly and give you branch support values. They also save you from having to recalculate everything when you discover a character coding error—something that happens more often than you'd think. PAUP* is the industry standard for anything involving bootstrap values or model-based methods, but it's commercial software. If you don't have access through a university license, TNT gets you most of the way there for free.
Get the Full Details

A common pitfall I keep running into with beginners is treating the software output as definitive without checking the input matrix. I had a student once run a cladogram on a dataset where every character was coded as "1" for every species except one. The software produced a perfectly resolved tree. It was completely meaningless. Always inspect your matrix before running any analysis.
Common Problems and How to Handle Them
Parsimony doesn't always give you a single tree. Homoplasy—characters that evolved independently in different lineages—can create multiple equally parsimonious solutions. When this happens, you look at the consensus tree to find the groupings all solutions agree on. Anything unresolved in the consensus is just that your data doesn't have enough signal. Long branch attraction is another issue worth knowing about. It's when fast-evolving lineages appear artificially grouped together because they accumulated similar changes by chance rather than shared descent. This tends to show up when your outgroup is very distantly related to your ingroup. Switching to a closer outgroup or using model-based methods instead of pure parsimony usually helps. Character dependency is something most people miss. If two characters are actually portions of the same biological structure, treating them as independent data points inflates their weight in the analysis. A vertebral column and individual vertebrae aren't independent observations. Code them as a single composite character or justify why they're independent in your methodology section.
I once analyzed a dataset where what I thought were three separate morphological characters turned out to be developmentally linked. The tree topology shifted noticeably once I recoded them. Worth catching early rather than after peer review.
What This Method Can't Do
A cladogram shows hypothetical relationships based on the characters you provide. It does not prove anything. Different character sets can produce different trees from the same species. This is a feature, not a bug—it means you're testing hypotheses rather than stating facts. But it also means you need to be transparent about which characters you included and why. Quantitative characters can be tricky to code consistently. Continuous measurements like skull length don't fit neatly into 0/1 states without some kind of thresholding, and different thresholds can change your results. Document your decisions clearly. If your dataset is large and purely molecular, parsimony might not be the best approach. Maximum likelihood and Bayesian methods often handle sequence data more accurately, though they require more computational resources and a better understanding of substitution models. Cladistics in the strict sense—manual character-by-character analysis—is really suited to morphology-heavy studies or small molecular datasets where you want full transparency about how each character influences the result.